maps: introduce generic_maps_open()
Subsystems (4)
A message that is not in the archive (sent off-list or not yet received): [email protected]
PATCH 1/4 maps: PSS(proportional set size) accounting in smaps
The "proportional set size" (PSS) of a process is the count of pages it has in memory, where each page is divided by the number of processes sharing it. So if a process has 1000 pages all to itself, and 1000 shared with one other process, its PSS will be 1500.
- lwn.net: "ELC: How much memory are applications really using?"
The PSS proposed by Matt Mackall is a very nice metic for measuring an process's memory footprint. So collect and export it via /proc/<pid>/smaps.
Matt Mackall's pagemap/kpagemap and John Berthels's exmap can also do the job. They are comprehensive tools. But for PSS, let's do it in the simple way.
---
 fs/proc/task_mmu.c |   29 ++++++++++++++++++++++++++++-
 1 file changed, 28 insertions(+), 1 deletion(-)
fs/proc/task_mmu.c +28 -1
@@ -324,6 +324,27 @@ struct mem_size_statsunsigned long private_clean;unsigned long private_dirty;unsigned long referenced; + +/* +* Proportional Set Size(PSS): my share of RSS. +* +* PSS of a process is the count of pages it has in memory, where each +* page is divided by the number of processes sharing it. So if a +* process has 1000 pages all to itself, and 1000 shared with one other +* process, its PSS will be 1500. (lwn.net) +*/ +u64 pss; +/* +* To keep (accumulated) division errors low, we adopt 64bit pss and +* use some low bits for division errors. So (pss >> PSS_ERROR_BITS) +* would be the real byte count. +* +* A shift of 12 before division means(assuming 4K page size): +* - 1M 3-user-pages add up to 8KB errors; +* - supports mapcount up to 2^24, or 16M; +* - supports PSS up to 2^52 bytes, or 4PB. +*/ +#define PSS_ERROR_BITS 12 };struct smaps_arg
@@ -341,6 +362,7 @@ static int smaps_pte_range(pmd_t *pmd, upte_t *pte, ptent;spinlock_t *ptl;struct page *page; +int mapcount; pte =pte_offset_map_lock (vma->vm_mm, pmd, addr, &ptl);for (; addr != end; pte++, addr +=PAGE_SIZE ) {
@@ -357,16 +379,19 @@ static int smaps_pte_range(pmd_t *pmd, u/* Accumulate the size in pages that have been accessed. */ if (pte_young (ptent) ||PageReferenced (page)) mss->referenced +=PAGE_SIZE ; -if (page_mapcount (page) >=2 ) { + mapcount =page_mapcount (page); +if (mapcount >=2 ) {if (pte_dirty (ptent)) mss->shared_dirty +=PAGE_SIZE ;else mss->shared_clean +=PAGE_SIZE ; + mss->pss += (PAGE_SIZE <<PSS_ERROR_BITS ) / mapcount; }else {if (pte_dirty (ptent)) mss->private_dirty +=PAGE_SIZE ;else mss->private_clean +=PAGE_SIZE ; + mss->pss += (PAGE_SIZE <<PSS_ERROR_BITS ); } }pte_unmap_unlock (pte -1 , ptl);
@@ -395,6 +420,7 @@ static int show_smap(struct seq_file *m,seq_printf (m,"Size: %8lu kB\n" "Rss: %8lu kB\n" +"Pss: %8lu kB\n" "Shared_Clean: %8lu kB\n" "Shared_Dirty: %8lu kB\n" "Private_Clean: %8lu kB\n"
@@ -402,6 +428,7 @@ static int show_smap(struct seq_file *m,"Referenced: %8lu kB\n" , (vma->vm_end - vma->vm_start) >>10 , sarg.mss.resident >>10 , + (unsigned long )(sarg.mss.pss >> (10 +PSS_ERROR_BITS )), sarg.mss.shared_clean >>10 , sarg.mss.shared_dirty >>10 , sarg.mss.private_clean >> 10,
PATCH 2/4 maps: address based vma walking
In reply to a message not in the archiveSplit large vmas into page groups of proc_maps_private.batch_size bytes, and iterate them one by one for seqfile->show. This allows us to export large scale process address space information via the seqfile interface. The old behavior of walking one vma at a time can be achieved by setting the batching size to ~0UL.
---
 fs/proc/task_mmu.c      |  105 ++++++++++++--------------------------
 include/linux/proc_fs.h |    6 +-
 mm/mempolicy.c          |    2
 3 files changed, 38 insertions(+), 75 deletions(-)
include/linux/proc_fs.h +3 -3
@@ -283,9 +283,9 @@ static inline struct proc_dir_entry *PDEstruct proc_maps_private {struct pid *pid;struct task_struct *task; -#ifdef CONFIG_MMU -struct vm_area_struct *tail_vma; -#endif +struct mm_struct *mm; +/* walk min(batch_size, remaining_size_of(vma)) bytes at a time */ +unsigned long batch_size; };#endif /* _LINUX_PROC_FS_H */
mm/mempolicy.c +0 -2
@@ -1937,7 +1937,5 @@ out:seq_putc (m,'\n' );kfree (md); -if (m->count < m->size) - m->version = (vma != priv->tail_vma) ? vma->vm_start :0 ;return 0 ; }
fs/proc/task_mmu.c +35 -70
148 lines not on this page · raw message
PATCH 3/4 maps: introduce generic_maps_open()
In reply to a message not in the archiveIntroduce generic_maps_open(). It is an extended version of do_maps_open(). The new function supports batch_size and custom sized seqfile/private buffers. This function will be reused by pmaps.
---
 fs/proc/task_mmu.c |   51 ++++++++++++++++++++++++++++++-------------
 1 file changed, 36 insertions(+), 15 deletions(-)
fs/proc/task_mmu.c +36 -15
@@ -178,24 +178,45 @@ static void m_stop(struct seq_file *m, vput_task_struct (priv->task); } +static int generic_maps_open (struct inode *inode,struct file *file, +struct seq_operations *ops,unsigned long batch_size, +int bufsize,int privsize) +{ +struct seq_file *m; +struct proc_maps_private *priv =NULL ; +char *buf =NULL ; +int ret = -ENOMEM ; + + priv =kzalloc (privsize,GFP_KERNEL ); +if (!priv) + goto out; + + buf =kmalloc (bufsize,GFP_KERNEL ); +if (!buf) + goto out; + + ret =seq_open (file, ops); +if (ret) + goto out; + + m = file->private_data; + m->private = priv; + m->buf = buf; + m->size = bufsize; + priv->pid =proc_pid (inode); + priv->batch_size = batch_size; +return 0 ; +out: +kfree (priv); +kfree (buf); +return ret; +} +static int do_maps_open (struct inode *inode,struct file *file,struct seq_operations *ops) { -struct proc_maps_private *priv; -int ret = -ENOMEM ; - priv =kzalloc (sizeof (*priv),GFP_KERNEL ); -if (priv) { - priv->pid =proc_pid (inode); - priv->batch_size = ~0 ; - ret =seq_open (file, ops); -if (!ret) { -struct seq_file *m = file->private_data; - m->private = priv; - }else { -kfree (priv); - } - } -return ret; +return generic_maps_open (inode, file, ops, ~0 ,2 *PAGE_SIZE , +sizeof (struct proc_maps_private )); }static int show_map (struct seq_file *m,void *v)
PATCH 4/4 maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
In reply to a message not in the archiveShow a process's page-by-page address space infomation in /proc/<pid>/pmaps. It helps to analyze applications' memory footprints in a comprehensive way.
Pages share the same states are grouped into a page range. For each page range, the following fields are exported:
- first page index
- number of pages in the range
- well known page/pte flags
- number of mmap users
Only page flags not expected to disappear in the near future are exported:
Y:young R:referenced A:active U:uptodate P:ptedirty D:dirty W:writeback
Here is a sample output:
# cat /proc/$$/pmaps
08048000-080c9000 r-xp 08048000 00:00 0
8048    81      Y_A_P__ 1
080c9000-080f8000 rwxp 080c9000 00:00 0                                  [heap]
80c9    2f      Y_A_P__ 1
f7e1c000-f7e25000 r-xp 00000000 03:00 176633                             /lib/libnss_files-2.3.6.so
0       1       Y_AU___ 1
1       1       YR_U___ 1
5       1       YR_U___ 1
8       1       YR_U___ 1
f7e25000-f7e27000 rwxp 00008000 03:00 176633                             /lib/libnss_files-2.3.6.so
8       2       Y_A_P__ 1
f7e27000-f7e2f000 r-xp 00000000 03:00 176635                             /lib/libnss_nis-2.3.6.so
0       1       Y_AU___ 1
1       1       YR_U___ 1
4       1       YR_U___ 1
7       1       Y_AU___ 1
f7e2f000-f7e31000 rwxp 00007000 03:00 176635                             /lib/libnss_nis-2.3.6.so
7       2       Y_A_P__ 1
f7e31000-f7e43000 r-xp 00000000 03:00 176630                             /lib/libnsl-2.3.6.so
0       1       Y_AU___ 1
1       3       YR_U___ 1
10      1       YR_U___ 1
f7e43000-f7e45000 rwxp 00011000 03:00 176630                             /lib/libnsl-2.3.6.so
11      2       Y_A_P__ 1
f7e45000-f7e47000 rwxp f7e45000 00:00 0
f7e47000-f7e4f000 r-xp 00000000 03:00 176631                             /lib/libnss_compat-2.3.6.so
0       1       Y_AU___ 1
1       3       YR_U___ 1
7       1       Y_AU___ 1
f7e4f000-f7e51000 rwxp 00007000 03:00 176631                             /lib/libnss_compat-2.3.6.so
7       2       Y_A_P__ 1
f7e51000-f7f79000 r-xp 00000000 03:00 176359                             /lib/libc-2.3.6.so
0       16      YRAU___ 2
19      1       YR_U___ 1
1f      1       YRAU___ 2
21      1       YRAU___ 1
22      2       YRAU___ 2
24      1       YRAU___ 1
26      1       YRAU___ 2
[...]
Matt Mackall's pagemap/kpagemap and John Berthels's exmap can achieve the same goals, and probably more. But this text based pmaps interface should be more easy to use.
The concern of dataset size is taken care of by working in a sparse way:
1) It will only generate output for resident pages, that normally is much smaller than the mapped size. Take my shell for example, the (size:rss) ratio is (7:1)!
wfg ~% cat /proc/$$/smaps |grep Size|sum
sum 50552.000
avg 777.723
wfg ~% cat /proc/$$/smaps |grep Rss|sum
sum 7604.000
avg 116.985
2) The page range trick suppresses more output.
It's interesting to see that the seq_file interface demands some more programming efforts, and provides such flexibility as well.
---
 fs/proc/base.c     |    7 +
 fs/proc/internal.h |    1
 fs/proc/task_mmu.c |  171 +++++++++++++++++++++++++++++++++++++++++++
 3 files changed, 179 insertions(+)
fs/proc/task_mmu.c +171 -0
@@ -754,3 +754,174 @@ const struct file_operations proc_numa_m .release = seq_release_private, };#endif /* CONFIG_NUMA */ + +struct pmaps_private { +struct proc_maps_private pmp; +struct vm_area_struct *vma; +struct seq_file *m; +/* page range attrs */ +unsigned long offset; +unsigned long len; +unsigned long flags; +int mapcount; +}; + +#define PMAPS_BUF_SIZE (64<<10)/* 64K */ +#define PMAPS_BATCH_SIZE (16<<20)/* 16M */ + +#define PG_YOUNG PG_readahead/* reuse any non-relevant flag */ +#define PG_DIRTY PG_lru/* ditto */ + +static unsigned long page_mask; + +static struct { +unsigned long mask; +const char *name; +bool faked; +} page_flags [] = { + {1 <<PG_YOUNG ,"Y:pteyoung" ,1 }, + {1 << PG_referenced,"R:referenced" ,0 }, + {1 << PG_active,"A:active" ,0 }, + + {1 << PG_uptodate,"U:uptodate" ,0 }, + {1 <<PG_DIRTY ,"P:ptedirty" ,1 }, + {1 << PG_dirty,"D:dirty" ,0 }, + {1 << PG_writeback,"W:writeback" ,0 }, +}; + +static unsigned long pte_page_flags (pte_t ptent,struct page * page) +{ +unsigned long flags; + + flags = page->flags & page_mask; + +if (pte_young (ptent)) + flags |= (1 <<PG_YOUNG ); + +if (pte_dirty (ptent)) + flags |= (1 <<PG_DIRTY ); + +return flags; +} + +static int pmaps_show_range (struct pmaps_private *pp) +{ +int i; + +if (!pp->len) +return 0 ; + +seq_printf (pp->m,"%lx\t%lx\t" , pp->offset, pp->len); + +for (i =0 ; i <ARRAY_SIZE (page_flags); i++) +seq_putc (pp->m, (pp->flags & page_flags[i].mask) ? + page_flags[i].name[0 ] :'_' ); + +return seq_printf (pp->m,"\t%x\n" , pp->mapcount); +} + +static int pmaps_pte_range (pmd_t *pmd,unsigned long addr,unsigned long end, +void *private) +{ +struct pmaps_private *pp = private; +struct vm_area_struct *vma = pp->vma; +pte_t *pte, *apte, ptent; +spinlock_t *ptl; +struct page *page; +unsigned long offset; +unsigned long flags; +int mapcount; +int ret =0 ; + + apte = pte =pte_offset_map_lock (vma->vm_mm, pmd, addr, &ptl); +for (; addr != end; pte++, addr +=PAGE_SIZE ) { + ptent = *pte; +if (!pte_present (ptent)) +continue ; + + page =vm_normal_page (vma, addr, ptent); +if (!page) +continue ; + +/* test page similarity, then grow the range or show it */ + offset =page_index (page); + mapcount =page_mapcount (page); + flags =pte_page_flags (ptent, page); +if (offset == pp->offset + pp->len && + mapcount == pp->mapcount && + flags == pp->flags) { + pp->len++; + }else { + ret =pmaps_show_range (pp); +if (ret) +break ; + pp->offset = offset; + pp->len =1 ; + pp->mapcount = mapcount; + pp->flags = flags; + } + } +pte_unmap_unlock (apte, ptl); +cond_resched (); +return ret; +} + +static struct mm_walk pmaps_walk = { .pmd_entry = pmaps_pte_range }; +static int show_pmaps (struct seq_file *m,void *v) +{ +struct vm_area_struct *vma = v; +struct pmaps_private *pp = m->private; +unsigned long addr = m->version; +unsigned long end; +int ret; + +if (addr == vma->vm_start) { + ret =show_map (m, vma); +if (ret) +return ret; + } + + end = vma->vm_end; +if (end - addr >PMAPS_BATCH_SIZE ) + end = addr +PMAPS_BATCH_SIZE ; + + pp->m = m; + pp->vma = vma; + pp->len =0 ; +walk_page_range (vma->vm_mm, addr, end, &pmaps_walk, pp); +pmaps_show_range (pp); + +return 0 ; +} + +static struct seq_operations proc_pid_pmaps_op = { + .start = m_start, + .next = m_next, + .stop = m_stop, + .show = show_pmaps +}; + +static int pmaps_open (struct inode *inode,struct file *file) +{ +return generic_maps_open (inode, file, &proc_pid_pmaps_op, +PMAPS_BATCH_SIZE ,PMAPS_BUF_SIZE , +sizeof (struct pmaps_private )); +} + +const struct file_operations proc_pmaps_operations = { + .open = pmaps_open, + .read = seq_read, + .llseek = seq_lseek, + .release = seq_release_private, +}; + +static __init int task_mmu_init (void ) +{ +int i; +for (page_mask =0 , i =0 ; i <ARRAY_SIZE (page_flags); i++) +if (!page_flags[i].faked) + page_mask |= page_flags[i].mask; +return 0 ; +} + +pure_initcall (task_mmu_init);
fs/proc/base.c +7 -0
@@ -45,6 +45,11 @@* * Paul Mundt <[email protected]>: * Overall revision about smaps. +* +* ChangeLog: +* 15-Aug-2007 +* Fengguang Wu <[email protected]>: +* Page granularity mapping info in pmaps. */ #include <asm/uaccess.h>
@@ -2044,6 +2049,7 @@ static const struct pid_entry tgid_base_
 #ifdef CONFIG_PROC_PAGE_MONITOR
 	REG("clear_refs", S_IWUSR, clear_refs),
 	REG("smaps",      S_IRUGO, smaps),
+	REG("pmaps",      S_IRUSR, pmaps),
 	REG("pagemap",    S_IRUSR, pagemap),
 #endif
 #endif
@@ -2336,6 +2342,7 @@ static const struct pid_entry tid_base_s
 #ifdef CONFIG_PROC_PAGE_MONITOR
 	REG("clear_refs", S_IWUSR, clear_refs),
 	REG("smaps",     S_IRUGO, smaps),
+	REG("pmaps",     S_IRUSR, pmaps),
 	REG("pagemap",    S_IRUSR, pagemap),
 #endif
 #endif
fs/proc/internal.h +1 -0
@@ -50,6 +50,7 @@ extern loff_t mem_lseek(struct file * fiextern const struct file_operations proc_maps_operations;extern const struct file_operations proc_numa_maps_operations;extern const struct file_operations proc_smaps_operations; +extern const struct file_operations proc_pmaps_operations;extern const struct file_operations proc_clear_refs_operations;extern const struct file_operations proc_pagemap_operations;
A message that is not in the archive (sent off-list or not yet received): [email protected]
Matt Mackall
Acked-byRe: [PATCH 1/4] maps: PSS(proportional set size) accounting in smaps
Quoted 11 lines · Fengguang Wu
The "proportional set size" (PSS) of a process is the count of pages it has in memory, where each page is divided by the number of processes sharing it. So if a process has 1000 pages all to itself, and 1000 shared with one other process, its PSS will be 1500.
- lwn.net: "ELC: How much memory are applications really using?"The PSS proposed by Matt Mackall is a very nice metic for measuring an process's memory footprint. So collect and export it via /proc/<pid>/smaps.
Matt Mackall's pagemap/kpagemap and John Berthels's exmap can also do the job. They are comprehensive tools. But for PSS, let's do it in the simple way.
It's a bit odd that you attribute the description of PSS to LWN rather than me. But anyway:
Signature · 1 line
Mathematics is the supreme nostalgia of our time.
Re: [PATCH 1/4] maps: PSS(proportional set size) accounting in smaps
Quoted 10 lines · Matt Mackall
Quoted 9 lines · Fengguang Wu
The "proportional set size" (PSS) of a process is the count of pages it has in memory, where each page is divided by the number of processes sharing it. So if a process has 1000 pages all to itself, and 1000 shared with one other process, its PSS will be 1500.
- lwn.net: "ELC: How much memory are applications really using?"The PSS proposed by Matt Mackall is a very nice metic for measuring an process's memory footprint. So collect and export it via /proc/<pid>/smaps.
Quoted 7 lines
Quoted 2 lines
Matt Mackall's pagemap/kpagemap and John Berthels's exmap can also do the job. They are comprehensive tools. But for PSS, let's do it in the simple way.
It's a bit odd that you attribute the description of PSS to LWN rather than me. But anyway:
Acked-by Matt Mackall <[email protected]>
Sorry and thank you!
I'll change it in the next take.
A message that is not in the archive (sent off-list or not yet received): [email protected]
Re: [PATCH 2/4] maps: address based vma walking
Quoted 33 lines · Fengguang Wu
Split large vmas into page groups of proc_maps_private.batch_size bytes, and iterate them one by one for
seqfile->show. This allows us to export large scale process address space information via the seqfile interface. The old behavior of walking one vma at a time can be achieved by setting the batching size to ~0UL.Cc Matt Mackall <[email protected]>Cc Al Viro <[email protected]>Signed-off-by Fengguang Wu <[email protected]>--- fs/proc/task_mmu.c | 105 ++++++++++++-------------------------- include/linux/proc_fs.h | 6 +- mm/mempolicy.c | 2 3 files changed, 38 insertions(+), 75 deletions(-)include/linux/proc_fs.h +3
-3@@ -283,9 +283,9 @@ static inline struct proc_dir_entry *PDEstruct proc_maps_private {struct pid *pid;struct task_struct *task; -#ifdef CONFIG_MMU -struct vm_area_struct *tail_vma; -#endif +struct mm_struct *mm; +/* walk min(batch_size, remaining_size_of(vma)) bytes at a time */ +unsigned long batch_size; };#endif /* _LINUX_PROC_FS_H */
mm/mempolicy.c out: · line 1941
Quoted 7 lines
mm/mempolicy.c +0
-2@@ -1937,7 +1937,5 @@ out:seq_putc (m,'\n' );kfree (md); -if (m->count < m->size) - m->version = (vma != priv->tail_vma) ? vma->vm_start :0 ;return 0 ; }
What's this bit for?
Quoted 152 lines
fs/proc/task_mmu.c +35
-70@@ -115,99 +115,65 @@ static void pad_len_spaces(struct seq_fiseq_printf (m,"%*c" , len,' ' ); } -static void vma_stop (struct proc_maps_private *priv,struct vm_area_struct *vma) +static void *seek_vma_addr (struct seq_file *m, +struct vm_area_struct *vma,loff_t *pos) { -if (vma && vma != priv->tail_vma) { -struct mm_struct *mm = vma->vm_mm; -up_read (&mm->mmap_sem); -mmput (mm); - } +struct proc_maps_private *priv = m->private; +unsigned long addr = *pos; + +if (addr & ~PAGE_MASK ) {/* time for next batch */ +if (vma->vm_end - addr < priv->batch_size) { + vma = vma->vm_next; +if (!vma || vma ==get_gate_vma (priv->task)) + goto done; + }else + addr = (addr + priv->batch_size) &PAGE_MASK ; + } +if (addr < vma->vm_start) + addr = vma->vm_start; + + m->version = *pos = addr; +return vma; +done: +return NULL ; }static void *m_start (struct seq_file *m,loff_t *pos) {struct proc_maps_private *priv = m->private; -unsigned long last_addr = m->version; -struct mm_struct *mm; -struct vm_area_struct *vma, *tail_vma =NULL ; -loff_t l = *pos; - -/* Clear the per syscall fields in priv */ - priv->task =NULL ; - priv->tail_vma =NULL ; - -/* -* We remember last_addr rather than next_addr to hit with -* mmap_cache most of the time. We have zero last_addr at -* the beginning and also after lseek. We will have -1 last_addr -* after the end of the vmas. -*/ - -if (last_addr ==-1UL ) -return NULL ; +struct vm_area_struct *vma; + priv->mm =NULL ; priv->task =get_pid_task (priv->pid,PIDTYPE_PID );if (!priv->task)return NULL ; - mm =get_task_mm (priv->task); -if (!mm) + priv->mm =get_task_mm (priv->task); +if (!priv->mm)return NULL ; - priv->tail_vma = tail_vma =get_gate_vma (priv->task); -down_read (&mm->mmap_sem); +down_read (&priv->mm->mmap_sem); -/* Start with last addr hint */ -if (last_addr && (vma =find_vma (mm, last_addr))) { - vma = vma->vm_next; - goto out; - } - -/* -* Check the vma index is within the range and do -* sequential scan until m_index. -*/ - vma =NULL ; -if ((unsigned long )l < mm->map_count) { - vma = mm->mmap; -while (l-- && vma) - vma = vma->vm_next; - goto out; - } - -if (l != mm->map_count) - tail_vma =NULL ;/* After gate vma */ - -out: -if (vma) -return vma; + vma =find_vma (priv->mm, *pos); +if (!vma || vma ==get_gate_vma (priv->task)) +return NULL ; -/* End of vmas has been reached */ - m->version = (tail_vma !=NULL )?0 :-1UL ; -up_read (&mm->mmap_sem); -mmput (mm); -return tail_vma; +return seek_vma_addr (m, vma, pos); }static void *m_next (struct seq_file *m,void *v,loff_t *pos) { -struct proc_maps_private *priv = m->private; -struct vm_area_struct *vma = v; -struct vm_area_struct *tail_vma = priv->tail_vma; - (*pos)++; -if (vma && (vma != tail_vma) && vma->vm_next) -return vma->vm_next; -vma_stop (priv, vma); -return (vma != tail_vma)? tail_vma:NULL ; +return seek_vma_addr (m, v, pos); }static void m_stop (struct seq_file *m,void *v) {struct proc_maps_private *priv = m->private; -struct vm_area_struct *vma = v; - -vma_stop (priv, vma); +if (priv->mm) { +up_read (&priv->mm->mmap_sem); +mmput (priv->mm); + }if (priv->task)put_task_struct (priv->task); }@@ -220,6 +186,7 @@ static int do_maps_open(struct inode *in priv =kzalloc (sizeof (*priv),GFP_KERNEL );if (priv) { priv->pid =proc_pid (inode); + priv->batch_size = ~0 ; ret =seq_open (file, ops);if (!ret) {struct seq_file *m = file->private_data;@@ -291,8 +258,6 @@ static int show_map(struct seq_file *m, }seq_putc (m,'\n' ); -if (m->count < m->size)/* vma is copied successfully */ - m->version = (vma !=get_gate_vma (task))? vma->vm_start:0 ;return 0 ; }
Signature · 1 line
Mathematics is the supreme nostalgia of our time.
Re: [PATCH 2/4] maps: address based vma walking
Quoted 37 lines · Matt Mackall
Quoted 36 lines · Fengguang Wu
Split large vmas into page groups of proc_maps_private.batch_size bytes, and iterate them one by one for
seqfile->show. This allows us to export large scale process address space information via the seqfile interface. The old behavior of walking one vma at a time can be achieved by setting the batching size to ~0UL.Cc Matt Mackall <[email protected]>Cc Al Viro <[email protected]>Signed-off-by Fengguang Wu <[email protected]>--- fs/proc/task_mmu.c | 105 ++++++++++++-------------------------- include/linux/proc_fs.h | 6 +- mm/mempolicy.c | 2 3 files changed, 38 insertions(+), 75 deletions(-)include/linux/proc_fs.h +3
-3@@ -283,9 +283,9 @@ static inline struct proc_dir_entry *PDEstruct proc_maps_private {struct pid *pid;struct task_struct *task; -#ifdef CONFIG_MMU -struct vm_area_struct *tail_vma; -#endif +struct mm_struct *mm; +/* walk min(batch_size, remaining_size_of(vma)) bytes at a time */ +unsigned long batch_size; };#endif /* _LINUX_PROC_FS_H */ mm/mempolicy.c +0
-0@@ -1937,7 +1937,5 @@ out:seq_putc (m,'\n' );kfree (md);
Quoted 6 lines
mm/mempolicy.c out: · line 1941
Quoted 4 lines
mm/mempolicy.c +0
-2-if (m->count < m->size) - m->version = (vma != priv->tail_vma) ? vma->vm_start :0 ;return 0 ; }What's this bit for?
This function is called by show_numa_map_checked(), which in turn also uses m_start/m_next/m_stop. m->version used to store start address of vmas, but now may also point to the middle of a vma.
A message that is not in the archive (sent off-list or not yet received): [email protected]
Re: [PATCH 4/4] maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
Quoted 13 lines · Fengguang Wu
Show a process's page-by-page address space infomation in /proc/<pid>/pmaps. It helps to analyze applications' memory footprints in a comprehensive way.
Pages share the same states are grouped into a page range. For each page range, the following fields are exported:
- first page index
- number of pages in the range
- well known page/pte flags
- number of mmap usersOnly page flags not expected to disappear in the near future are exported:
Y:young R:referenced A:active U:uptodate P:ptedirty D:dirty W:writeback
...
Quoted 10 lines
The concern of dataset size is taken care of by working in a sparse way:
1) It will only generate output for resident pages, that normally is much smaller than the mapped size. Take my shell for example, the (size:rss) ratio is (7:1)!
wfg ~% cat
/proc/$$/smaps|grep Size|sum
sum 50552.000
avg 777.723
Quoted 8 lines
wfg ~% cat
/proc/$$/smaps|grep Rss|sum
sum 7604.000
avg 116.9852) The page range trick suppresses more output.
It's interesting to see that the
seq_fileinterface demands some more programming efforts, and provides such flexibility as well.
I'm so-so on this.
On the downside:
- requires lots of parsing
- isn't random-access
- probably significantly slower than pagemap
Signature · 1 line
Mathematics is the supreme nostalgia of our time.
Re: [PATCH 4/4] maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
Quoted 30 lines · Matt Mackall
Quoted 13 lines · Fengguang Wu
Show a process's page-by-page address space infomation in /proc/<pid>/pmaps. It helps to analyze applications' memory footprints in a comprehensive way.
Pages share the same states are grouped into a page range. For each page range, the following fields are exported:
- first page index
- number of pages in the range
- well known page/pte flags
- number of mmap usersOnly page flags not expected to disappear in the near future are exported:
Y:young R:referenced A:active U:uptodate P:ptedirty D:dirty W:writeback
...
Quoted 14 lines
The concern of dataset size is taken care of by working in a sparse way:
1) It will only generate output for resident pages, that normally is much smaller than the mapped size. Take my shell for example, the (size:rss) ratio is (7:1)!
wfg ~% cat
/proc/$$/smaps|grep Size|sum
sum 50552.000
avg 777.723wfg ~% cat
/proc/$$/smaps|grep Rss|sum
sum 7604.000
avg 116.985
Quoted 6 lines
Quoted 4 lines
2) The page range trick suppresses more output.
It's interesting to see that the
seq_fileinterface demands some more programming efforts, and provides such flexibility as well.I'm so-so on this.
Not that way! It's a good thing that people have different experiences and hence viewpoints. Maybe the concept of PFN sharing are straightforward to you, while I have been playing with seq_file a lot.
Quoted 5 lines
On the downside:
- requires lots of parsing
- isn't random-access
- probably significantly slower than pagemap
That could be true. Maybe some user with huge datasets will give us some idea about the performance. I don't know, maybe it's application dependent.
Anyway I don't think it's fair to merge a binary interface without the challenge from a textual one ;)
Thank you,
Fengguang
A message that is not in the archive (sent off-list or not yet received): [email protected]
Re: [PATCH 4/4] maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
Quoted 12 lines · Fengguang Wu
Quoted 1 line
I'm so-so on this.
Not that way! It's a good thing that people have different experiences and hence viewpoints. Maybe the concept of PFN sharing are straightforward to you, while I have been playing with
seq_filea lot.Quoted 5 lines
On the downside:
- requires lots of parsing
- isn't random-access
- probably significantly slower than pagemap
Quoted 6 lines
That could be true. Maybe some user with huge datasets will give us some idea about the performance. I don't know, maybe it's application dependent.
Anyway I don't think it's fair to merge a binary interface without the challenge from a textual one ;)
Yes, that's why I didn't say I hated it.
Signature · 1 line
Mathematics is the supreme nostalgia of our time.
Re: [PATCH 4/4] maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
In reply to Matt MackallMatt,
It's not easy to do direct performance comparisons between pmaps and pagemap/kpagemap. However some close analyzes are still possible :)
1) code size
pmaps ~200 LOC
pagemap/kpagemap ~300 LOC
2) dataset size
take for example my running firefox on Intel Core 2:
VSZ 400 MB
RSS 64 MB, or 16k pages
pmaps 64 KB, wc shows 2k lines, or so much page ranges
pagemap 800 KB, could be heavily optimized by returning partial data
kpagemap 256 KB
3) runtime overheads
pmaps 2k lines of string processing(encode/decode)
kpagemap 16k seek()/read()s, and context switches (could be
optimized somehow by doing a PFN sort first, but that's also non-trivial overheads)
So pmaps seems to be a clear winner :)
Thank you,
Fengguang
A message that is not in the archive (sent off-list or not yet received): [email protected]
Re: [PATCH 4/4] maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
Quoted 9 lines · Fengguang Wu
Matt,
It's not easy to do direct performance comparisons between pmaps and pagemap/kpagemap. However some close analyzes are still possible :)
1) code size
pmaps ~200 LOC
pagemap/kpagemap ~300 LOC
Quoted 6 lines
2) dataset size
take for example my running firefox on Intel Core 2:
VSZ 400 MB
RSS 64 MB, or 16k pages
pmaps 64 KB, wc shows 2k lines, or so much page ranges
pagemap 800 KB, could be heavily optimized by returning partial data
I take it you're in 64-bit mode?
You're right, this data compresses well in many circumstances. I suspect it will suffer under memory pressure though. That will fragment the ranges in-memory and also fragment the active bits. The worst case here is huge, of course, but realistically I'd expect something like 2x-4x.
But there are still the downsides I have mentioned:
- you don't get page frame numbers
- you can't do random access
And how long does it take to pull the data out? My benchmarks show greater than 50MB/s (and that's with the version in -mm that's doing double buffering), so that 800K would take < .016s.
Quoted 7 lines
kpagemap 256 KB
3) runtime overheads
pmaps 2k lines of string processing(encode/decode)
kpagemap 16k seek()/read()s, and context switches (could be
optimized somehow by doing a PFN sort first, but that's also non-trivial overheads)
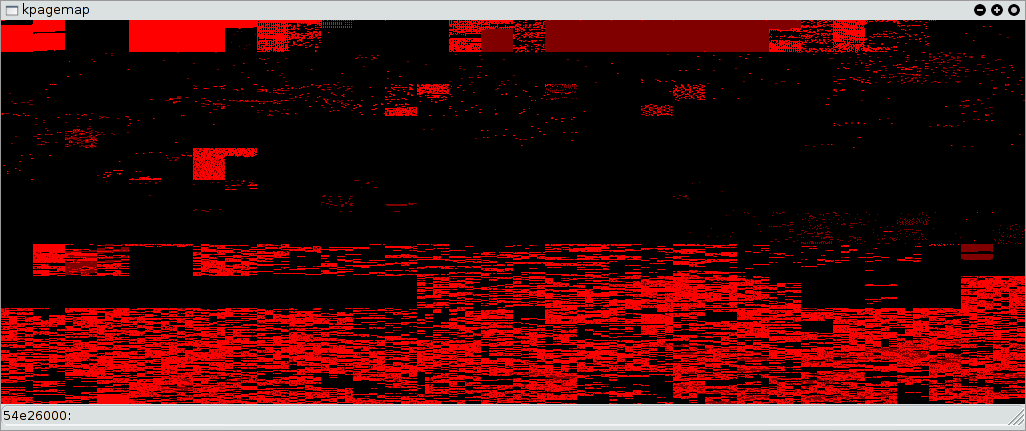
You can do anywhere between 16k small reads or 1 large read. Depends what data you're trying to get. Right now, kpagemap is fast enough that I can do realtime displays of the whole of memory in my desktop in a GUI written in Python. And Python is fairly horrible for drawing bitmaps and such.
http://www.selenic.com/Screenshot-kpagemap.png
Quoted 1 line
So pmaps seems to be a clear winner :)
Except that it's only providing a subset of the data.
Signature · 1 line
Mathematics is the supreme nostalgia of our time.
Re: [PATCH 4/4] maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
Matt,
Quoted 8 lines · Matt Mackall
Quoted 7 lines · Fengguang Wu
It's not easy to do direct performance comparisons between pmaps and pagemap/kpagemap. However some close analyzes are still possible :)
1) code size
pmaps ~200 LOC
pagemap/kpagemap ~300 LOC
Quoted 8 lines
Quoted 6 lines
2) dataset size
take for example my running firefox on Intel Core 2:
VSZ 400 MB
RSS 64 MB, or 16k pages
pmaps 64 KB, wc shows 2k lines, or so much page ranges
pagemap 800 KB, could be heavily optimized by returning partial dataI take it you're in 64-bit mode?
Yes. That will be the common case.
Quoted 5 lines
You're right, this data compresses well in many circumstances. I suspect it will suffer under memory pressure though. That will fragment the ranges in-memory and also fragment the active bits. The worst case here is huge, of course, but realistically I'd expect something like 2x-4x.
Not likely to degrade even under memory pressure ;)
The compress_ratio = (VSZ:RSS) * (RSS:page_ranges).
- On fresh startup and no memory pressure,
- the VSZ:RSS ratio of ALL processes are 4516796KB:457048KB ~= 10:1.
- the firefox case shows a (RSS:page_ranges) of 16k:2k ~= 8:1.
- On memory pressure,
- as VSZ goes up, RSS will be bounded by physical memory. So VSZ:RSS ratio actually goes up with memory pressure.
- page range is a good unit of locality. They are more likely to be reclaimed as a whole. So (RSS:page_ranges) wouldn't degrade as much.
Quoted 3 lines
But there are still the downsides I have mentioned:
- you don't get page frame numbers
True. I guess PFNs are meaningless to a normal user?
Quoted 1 line
- you can't do random access
Not for now.
It would be trivial to support seek-by-address semantic: the seqfile operations already iterate by addresses. Only that we cannot do it via the regular read/pread/seek interfaces. They have different semantic on fpos. However, tricks like ioctl(begin_addr, end_addr) can be employed if necessary.
Quoted 3 lines
And how long does it take to pull the data out? My benchmarks show greater than 50MB/s (and that's with the version in -mm that's doing double buffering), so that 800K would take < .016s.
You are right :)
Quoted 9 lines
Quoted 7 lines
kpagemap 256 KB
3) runtime overheads
pmaps 2k lines of string processing(encode/decode)
kpagemap 16k seek()/read()s, and context switches (could be
optimized somehow by doing a PFN sort first, but that's also non-trivial overheads)You can do anywhere between 16k small reads or 1 large read. Depends
No way to avoid the seeks if PFNs are discontinuous. Too bad the memory get fragmented with uptime, at least for the current kernel.
But sure, sequential reads are viable when doing whole system memory analysis, or for memory hog processes.
Quoted 10 lines
what data you're trying to get. Right now, kpagemap is fast enough that I can do realtime displays of the whole of memory in my desktop in a GUI written in Python. And Python is fairly horrible for drawing bitmaps and such.
http://www.selenic.com/Screenshot-kpagemap.png
Quoted 1 line
So pmaps seems to be a clear winner :)
Except that it's only providing a subset of the data.
Yes, and it's a nice graph :)
A message that is not in the archive (sent off-list or not yet received): [email protected]
Re: [PATCH 4/4] maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
Quoted 28 lines · Fengguang Wu
Matt,
Quoted 8 lines · Matt Mackall
Quoted 7 lines · Fengguang Wu
It's not easy to do direct performance comparisons between pmaps and pagemap/kpagemap. However some close analyzes are still possible :)
1) code size
pmaps ~200 LOC
pagemap/kpagemap ~300 LOCQuoted 8 lines
Quoted 6 lines
2) dataset size
take for example my running firefox on Intel Core 2:
VSZ 400 MB
RSS 64 MB, or 16k pages
pmaps 64 KB, wc shows 2k lines, or so much page ranges
pagemap 800 KB, could be heavily optimized by returning partial dataI take it you're in 64-bit mode?
Yes. That will be the common case.
Quoted 5 lines
You're right, this data compresses well in many circumstances. I suspect it will suffer under memory pressure though. That will fragment the ranges in-memory and also fragment the active bits. The worst case here is huge, of course, but realistically I'd expect something like 2x-4x.
Quoted 6 lines
Not likely to degrade even under memory pressure ;)
The
compress_ratio= (VSZ:RSS) * (RSS:page_ranges).
- On fresh startup and no memory pressure,
- the VSZ:RSS ratio of ALL processes are 4516796KB:457048KB ~= 10:1.
- the firefox case shows a (RSS:page_ranges) of 16k:2k ~= 8:1.
Yes.
Quoted 3 lines
- On memory pressure,
- as VSZ goes up, RSS will be bounded by physical memory. So VSZ:RSS ratio actually goes up with memory pressure.
And yes.
But that's not what I'm talking about. You're likely to have more holes in your ranges with memory pressure as things that aren't active get paged or swapped out and back in. And because we're walking the LRU more rapidly, we'll flip over a lot of the active bits more often which will mean more output.
Quoted 2 lines
- page range is a good unit of locality. They are more likely to be reclaimed as a whole. So (RSS:page_ranges) wouldn't degrade as much.
There is that. The relative magnitude of the different effects is unclear. But it is clear that the worst case for pmap is much worse than pagemap (two lines per page of RSS?).
Quoted 5 lines
Quoted 3 lines
But there are still the downsides I have mentioned:
- you don't get page frame numbers
True. I guess PFNs are meaningless to a normal user?
They're useful for anyone who's trying to look at the system as a whole.
Quoted 9 lines
Quoted 1 line
- you can't do random access
Not for now.
It would be trivial to support seek-by-address semantic: the seqfile operations already iterate by addresses. Only that we cannot do it via the regular read/pread/seek interfaces. They have different semantic on fpos. However, tricks like
ioctl(begin_addr, end_addr)can be employed if necessary.
I suppose. But if you're willing to stomach that sort of thing, you might as well use a simple binary interface.
Signature · 1 line
Mathematics is the supreme nostalgia of our time.
Re: [PATCH 4/4] maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
Matt,
Quoted 12 lines · Matt Mackall
Quoted 3 lines
- On memory pressure,
- as VSZ goes up, RSS will be bounded by physical memory. So VSZ:RSS ratio actually goes up with memory pressure.And yes.
But that's not what I'm talking about. You're likely to have more holes in your ranges with memory pressure as things that aren't active get paged or swapped out and back in. And because we're walking the LRU more rapidly, we'll flip over a lot of the active bits more often which will mean more output.
Quoted 7 lines
Quoted 2 lines
- page range is a good unit of locality. They are more likely to be reclaimed as a whole. So (RSS:page_ranges) wouldn't degrade as much.
There is that. The relative magnitude of the different effects is unclear. But it is clear that the worst case for pmap is much worse
than pagemap (two lines per page of RSS?).
It's one line per page. No sane app will make vmas proliferate.
So let's talk about the worst case.
pagemap's data set size is determined by VSZ.
4GB VSZ means 1M PFNs, hence 8MB pagemap data.
pmaps's data set size is bounded by RSS hence physical memory. 4GB RSS means up to 1M page ranges, hence ~20M pmaps data. Not too bad :)
Quoted 13 lines
Quoted 5 lines
Quoted 3 lines
But there are still the downsides I have mentioned:
- you don't get page frame numbers
True. I guess PFNs are meaningless to a normal user?
They're useful for anyone who's trying to look at the system as a whole.
Quoted 4 lines
Quoted 1 line
- you can't do random access
Not for now.
Quoted 8 lines
Quoted 5 lines
It would be trivial to support seek-by-address semantic: the seqfile operations already iterate by addresses. Only that we cannot do it via the regular read/pread/seek interfaces. They have different semantic on fpos. However, tricks like
ioctl(begin_addr, end_addr)can be employed if necessary.I suppose. But if you're willing to stomach that sort of thing, you might as well use a simple binary interface.
Python can do ioctl() :)
Anyway it's already a special interface.
Re: [PATCH 4/4] maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
In reply to Matt MackallQuoted 6 lines · Matt Mackall
Quoted 3 lines
Quoted 1 line
- you don't get page frame numbers
True. I guess PFNs are meaningless to a normal user?
They're useful for anyone who's trying to look at the system as a whole.
To answer the question: "who are sharing this page with me"? PFNs are not the only option. The tuple dev/ino/offset can also uniquely identify the shared page :)
A message that is not in the archive (sent off-list or not yet received): [email protected]
Re: [PATCH 4/4] maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
Quoted 15 lines · Fengguang Wu
Matt,
Quoted 12 lines · Matt Mackall
Quoted 3 lines
- On memory pressure,
- as VSZ goes up, RSS will be bounded by physical memory. So VSZ:RSS ratio actually goes up with memory pressure.And yes.
But that's not what I'm talking about. You're likely to have more holes in your ranges with memory pressure as things that aren't active get paged or swapped out and back in. And because we're walking the LRU more rapidly, we'll flip over a lot of the active bits more often which will mean more output.
Quoted 8 lines
Quoted 7 lines
Quoted 2 lines
- page range is a good unit of locality. They are more likely to be reclaimed as a whole. So (RSS:page_ranges) wouldn't degrade as much.
There is that. The relative magnitude of the different effects is unclear. But it is clear that the worst case for pmap is much worse
than pagemap (two lines per page of RSS?).
It's one line per page. No sane app will make vmas proliferate.
Sane apps are few and far between.
Quoted 8 lines
So let's talk about the worst case.
pagemap's data set size is determined by VSZ.
4GB VSZ means 1M PFNs, hence 8MB pagemap data.pmaps's data set size is bounded by RSS hence physical memory. 4GB RSS means up to 1M page ranges, hence ~20M pmaps data. Not too bad :)
Hmmm, I've been misreading the output.
What does it do with nonlinear VMAs?
Signature · 1 line
Mathematics is the supreme nostalgia of our time.
Re: [PATCH 4/4] maps: /proc/<pid>/pmaps interface - memory maps in granularity of pages
Quoted 13 lines · Matt Mackall
Quoted 13 lines
Quoted 13 lines
Quoted 1 line
So VSZ:RSS ratio actually goes up with memory pressure.
And yes.
But that's not what I'm talking about. You're likely to have more holes in your ranges with memory pressure as things that aren't active get paged or swapped out and back in. And because we're walking the LRU more rapidly, we'll flip over a lot of the active bits more often which will mean more output.
Quoted 2 lines
- page range is a good unit of locality. They are more likely to be reclaimed as a whole. So (RSS:page_ranges) wouldn't degrade as much.
Quoted 7 lines
Quoted 5 lines
Quoted 4 lines
There is that. The relative magnitude of the different effects is unclear. But it is clear that the worst case for pmap is much worse
than pagemap (two lines per page of RSS?).
It's one line per page. No sane app will make vmas proliferate.
Sane apps are few and far between.
Very likely, and they will bloat maps/smaps/pmaps alike :(
Quoted 5 lines
Quoted 5 lines
So let's talk about the worst case.
pagemap's data set size is determined by VSZ.
4GB VSZ means 1M PFNs, hence 8MB pagemap data.
Quoted 7 lines
Quoted 3 lines
pmaps's data set size is bounded by RSS hence physical memory. 4GB RSS means up to 1M page ranges, hence ~20M pmaps data. Not too bad :)
Hmmm, I've been misreading the output.
What does it do with nonlinear VMAs?
The implementation gets offset from page_index(page), so will work the same way in linear/nonlinear VMAs. Depending how one does the remap_file_ranges() calls, the output lines may be not strictly ordered by offset, or overlap, or have small page ranges.