3.4.20-stable review
Subsystems (49)
Greg Kroah-Hartman
maintainercover 3.4.20-stable review
This is the start of the stable review cycle for the 3.4.20 release. There are 171 patches in this series, all will be posted as a response to this one. If anyone has any issues with these being applied, please let me know.
Responses should be made by Sat Nov 24 00:36:21 UTC 2012. Anything received after that time might be too late.
The whole patch series can be found in one patch at:
kernel.org/pub/linux/kernel/v3.0/stable-review/patch-3.4.20-rc1.gz
and the diffstat can be found below.
thanks,
greg k-h
-------------
Pseudo-Shortlog of commits:
Greg Kroah-Hartman <[email protected]>
Linux 3.4.20-rc1
Felipe Balbi <[email protected]>
Revert "serial: omap: fix software flow control"
Igor Murzov <[email protected]>
ACPI video: Ignore errors after _DOD evaluation.
Alex Elder <[email protected]>
ceph: avoid 32-bit page index overflow
Sage Weil <[email protected]>
libceph: check for invalid mapping
Yan, Zheng <[email protected]>
ceph: Fix oops when handling mdsmap that decreases max_mds
Sage Weil <[email protected]>
libceph: avoid NULL kref_put when osd reset races with alloc_msg
Alex Elder <[email protected]>
rbd: reset BACKOFF if unable to re-queue
Alex Elder <[email protected]>
libceph: only kunmap kmapped pages
Jim Schutt <[email protected]>
libceph: avoid truncation due to racing banners
Sage Weil <[email protected]>
libceph: delay debugfs initialization until we learn global_id
Sylvain Munaut <[email protected]>
libceph: fix crypto key null deref, memory leak
Sage Weil <[email protected]>
libceph: recheck con state after allocating incoming message
Sage Weil <[email protected]>
libceph: change ceph_con_in_msg_alloc convention to be less weird
Sage Weil <[email protected]>
libceph: avoid dropping con mutex before fault
Sage Weil <[email protected]>
libceph: verify state after retaking con lock after dispatch
Sage Weil <[email protected]>
libceph: revoke mon_client messages on session restart
Sage Weil <[email protected]>
libceph: fix handling of immediate socket connect failure
Sage Weil <[email protected]>
libceph: clear all flags on con_close
Sage Weil <[email protected]>
libceph: clean up con flags
Sage Weil <[email protected]>
libceph: replace connection state bits with states
Sage Weil <[email protected]>
libceph: drop unnecessary CLOSED check in socket state change callback
Sage Weil <[email protected]>
libceph: close socket directly from ceph_con_close()
Sage Weil <[email protected]>
libceph: drop gratuitous socket close calls in con_work
Sage Weil <[email protected]>
libceph: move ceph_con_send() closed check under the con mutex
Sage Weil <[email protected]>
libceph: move msgr clear_standby under con mutex protection
Sage Weil <[email protected]>
libceph: fix fault locking; close socket on lossy fault
Sage Weil <[email protected]>
libceph: reset connection retry on successfully negotiation
Sage Weil <[email protected]>
libceph: protect ceph_con_open() with mutex
Sage Weil <[email protected]>
libceph: (re)initialize bio_iter on start of message receive
Sage Weil <[email protected]>
libceph: resubmit linger ops when pg mapping changes
Sage Weil <[email protected]>
libceph: fix mutex coverage for ceph_con_close
Sage Weil <[email protected]>
libceph: report socket read/write error message
Guanjun He <[email protected]>
libceph: prevent the race of incoming work during teardown
Sage Weil <[email protected]>
libceph: initialize msgpool message types
Sage Weil <[email protected]>
libceph: allow sock transition from CONNECTING to CLOSED
Sage Weil <[email protected]>
libceph: initialize mon_client con only once
Sage Weil <[email protected]>
libceph: set peer name on con_open, not init
Alex Elder <[email protected]>
libceph: add some fine ASCII art
Alex Elder <[email protected]>
libceph: small changes to messenger.c
Alex Elder <[email protected]>
libceph: distinguish two phases of connect sequence
Alex Elder <[email protected]>
libceph: separate banner and connect writes
Alex Elder <[email protected]>
libceph: define and use an explicit CONNECTED state
Alex Elder <[email protected]>
libceph: clear NEGOTIATING when done
Alex Elder <[email protected]>
libceph: clear CONNECTING in ceph_con_close()
Alex Elder <[email protected]>
libceph: don't touch con state in con_close_socket()
Alex Elder <[email protected]>
libceph: just set SOCK_CLOSED when state changes
Alex Elder <[email protected]>
libceph: don't change socket state on sock event
Alex Elder <[email protected]>
libceph: SOCK_CLOSED is a flag, not a state
Alex Elder <[email protected]>
libceph: don't use bio_iter as a flag
Alex Elder <[email protected]>
libceph: move init of bio_iter
Alex Elder <[email protected]>
libceph: move init_bio_*() functions up
Alex Elder <[email protected]>
libceph: don't mark footer complete before it is
Alex Elder <[email protected]>
libceph: encapsulate advancing msg page
Alex Elder <[email protected]>
libceph: encapsulate out message data setup
Sage Weil <[email protected]>
libceph: drop ceph_con_get/put helpers and nref member
Sage Weil <[email protected]>
libceph: use con get/put methods
Dan Carpenter <[email protected]>
libceph: fix NULL dereference in reset_connection()
Sage Weil <[email protected]>
libceph: transition socket state prior to actual connect
Xi Wang <[email protected]>
libceph: fix overflow in osdmap_apply_incremental()
Xi Wang <[email protected]>
libceph: fix overflow in osdmap_decode()
Xi Wang <[email protected]>
libceph: fix overflow in __decode_pool_names()
Alex Elder <[email protected]>
libceph: make ceph_con_revoke_message() a msg op
Alex Elder <[email protected]>
libceph: make ceph_con_revoke() a msg operation
Alex Elder <[email protected]>
libceph: have messages take a connection reference
Alex Elder <[email protected]>
libceph: have messages point to their connection
Alex Elder <[email protected]>
libceph: tweak ceph_alloc_msg()
Alex Elder <[email protected]>
libceph: fully initialize connection in con_init()
Alex Elder <[email protected]>
libceph: init monitor connection when opening
Sage Weil <[email protected]>
libceph: drop connection refcounting for mon_client
Alex Elder <[email protected]>
libceph: embed ceph connection structure in mon_client
Alex Elder <[email protected]>
libceph: set CLOSED state bit in con_init
Alex Elder <[email protected]>
libceph: provide osd number when creating osd
Alex Elder <[email protected]>
libceph: start tracking connection socket state
Alex Elder <[email protected]>
libceph: start separating connection flags from state
Alex Elder <[email protected]>
libceph: embed ceph messenger structure in ceph_client
Alex Elder <[email protected]>
libceph: rename kvec_reset and kvec_add functions
Alex Elder <[email protected]>
libceph: rename socket callbacks
Alex Elder <[email protected]>
libceph: kill bad_proto ceph connection op
Alex Elder <[email protected]>
libceph: eliminate connection state "DEAD"
Yan, Zheng <[email protected]>
ceph: check PG_Private flag before accessing page->private
Yan, Zheng <[email protected]>
rbd: Fix ceph_snap_context size calculation
Josh Durgin <[email protected]>
rbd: store snapshot id instead of index
Josh Durgin <[email protected]>
rbd: protect read of snapshot sequence number
Alex Elder <[email protected]>
rbd: don't hold spinlock during messenger flush
Sage Weil <[email protected]>
libceph: fix messenger retry
Sage Weil <[email protected]>
libceph: flush msgr queue during mon_client shutdown
Yan, Zheng <[email protected]>
rbd: Clear ceph_msg->bio_iter for retransmitted message
Sage Weil <[email protected]>
libceph: use con get/put ops from osd_client
Alex Elder <[email protected]>
libceph: osd_client: don't drop reply reference too early
Sage Weil <[email protected]>
libceph: fix pg_temp updates
Sage Weil <[email protected]>
libceph: avoid unregistering osd request when not registered
Alex Elder <[email protected]>
ceph: add auth buf in prepare_write_connect()
Alex Elder <[email protected]>
ceph: rename prepare_connect_authorizer()
Alex Elder <[email protected]>
ceph: return pointer from prepare_connect_authorizer()
Alex Elder <[email protected]>
ceph: use info returned by get_authorizer
Alex Elder <[email protected]>
ceph: have get_authorizer methods return pointers
Alex Elder <[email protected]>
ceph: ensure auth ops are defined before use
Alex Elder <[email protected]>
ceph: messenger: reduce args to create_authorizer
Alex Elder <[email protected]>
ceph: define ceph_auth_handshake type
Alex Elder <[email protected]>
ceph: messenger: check return from get_authorizer
Alex Elder <[email protected]>
ceph: messenger: rework prepare_connect_authorizer()
Alex Elder <[email protected]>
ceph: messenger: check prepare_write_connect() result
Alex Elder <[email protected]>
ceph: don't set WRITE_PENDING too early
Alex Elder <[email protected]>
ceph: drop msgr argument from prepare_write_connect()
Alex Elder <[email protected]>
ceph: messenger: send banner in process_connect()
Alex Elder <[email protected]>
ceph: messenger: reset connection kvec caller
Alex Elder <[email protected]>
libceph: don't reset kvec in prepare_write_banner()
Alex Elder <[email protected]>
ceph: messenger: change read_partial() to take "end" arg
Alex Elder <[email protected]>
ceph: messenger: update "to" in read_partial() caller
Alex Elder <[email protected]>
ceph: messenger: use read_partial() in read_partial_message()
Alex Elder <[email protected]>
ceph: osd_client: fix endianness bug in osd_req_encode_op()
Sage Weil <[email protected]>
crush: fix memory leak when destroying tree buckets
Sage Weil <[email protected]>
crush: fix tree node weight lookup
Sage Weil <[email protected]>
crush: be more tolerant of nonsensical crush maps
Sage Weil <[email protected]>
crush: adjust local retry threshold
Sage Weil <[email protected]>
crush: clean up types, const-ness
Dave Jones <[email protected]>
selinux: fix sel_netnode_insert() suspicious rcu dereference
Jan Kara <[email protected]>
reiserfs: Protect reiserfs_quota_write() with write lock
Jan Kara <[email protected]>
reiserfs: Move quota calls out of write lock
Jan Kara <[email protected]>
reiserfs: Protect reiserfs_quota_on() with write lock
Jan Kara <[email protected]>
reiserfs: Fix lock ordering during remount
Bryan Schumaker <[email protected]>
NFS: Wait for session recovery to finish before returning
Daniel Vetter <[email protected]>
drm/i915: fix overlay on i830M
Martin Schwidefsky <[email protected]>
s390/signal: set correct address space control
Mirko Lindner <[email protected]>
sky2: Fix for interrupt handler
Tim Sally <[email protected]>
eCryptfs: check for eCryptfs cipher support at mount
Tyler Hicks <[email protected]>
eCryptfs: Copy up POSIX ACL and read-only flags from lower mount
Jan Safrata <[email protected]>
usb: use usb_serial_put in usb_serial_probe errors
Ulrich Weber <[email protected]>
netfilter: nf_nat: don't check for port change on ICMP tuples
Jozsef Kadlecsik <[email protected]>
netfilter: Mark SYN/ACK packets as invalid from original direction
Jozsef Kadlecsik <[email protected]>
netfilter: Validate the sequence number of dataless ACK packets as well
Nathan Walp <[email protected]>
r8169: allow multicast packets on sub-8168f chipset.
Cyril Brulebois <[email protected]>
r8169: Fix WoL on RTL8168d/8111d.
Mojiong Qiu <[email protected]>
xen/events: fix RCU warning, or Call idle notifier after irq_enter()
Michal Schmidt <[email protected]>
r8169: use unlimited DMA burst for TX
Hugh Dickins <[email protected]>
tmpfs: change final i_blocks BUG to WARNING
Tom Herbert <[email protected]>
net-rps: Fix brokeness causing OOO packets
Jiri Pirko <[email protected]>
net: correct check in dev_addr_del()
Hannes Frederic Sowa <[email protected]>
ipv6: setsockopt(IPIPPROTO_IPV6, IPV6_MINHOPCOUNT) forgot to set return value
Xi Wang <[email protected]>
ipv4: avoid undefined behavior in do_ip_setsockopt()
Andreas Schwab <[email protected]>
m68k: fix sigset_t accessor functions
Johannes Berg <[email protected]>
wireless: allow 40 MHz on world roaming channels 12/13
Michal Hocko <[email protected]>
memcg: oom: fix totalpages calculation for memory.swappiness==0
Zhao Yakui <[email protected]>
ttm: Clear the ttm page allocated from high memory zone correctly
Alex Deucher <[email protected]>
drm/radeon: fix logic error in atombios_encoders.c
Dan Williams <[email protected]>
USB: option: add Alcatel X220/X500D USB IDs
Dan Williams <[email protected]>
USB: option: add Novatel E362 and Dell Wireless 5800 USB IDs
Heiko Carstens <[email protected]>
s390/gup: add missing TASK_SIZE check to get_user_pages_fast()
Colin Cross <[email protected]>
Revert "Staging: Android alarm: IOCTL command encoding fix"
Artem Bityutskiy <[email protected]>
UBIFS: introduce categorized lprops counter
Artem Bityutskiy <[email protected]>
UBIFS: fix mounting problems after power cuts
Misael Lopez Cruz <[email protected]>
ASoC: dapm: Use card_list during DAPM shutdown
Eric Millbrandt <[email protected]>
ASoC: wm8978: pll incorrectly configured when codec is master
Takashi Iwai <[email protected]>
ALSA: hda - Add a missing quirk entry for iMac 9,1
Kailang Yang <[email protected]>
ALSA: hda - Add new codec ALC668 and ALC900 (default name ALC1150)
Takashi Iwai <[email protected]>
ALSA: hda - Fix invalid connections in VT1802 codec
Takashi Iwai <[email protected]>
ALSA: hda - Fix empty DAC filling in patch_via.c
Takashi Iwai <[email protected]>
ALSA: hda - Force to reset IEC958 status bits for AD codecs
Daniel J Blueman <[email protected]>
ALSA: HDA: Fix digital microphone on CS420x
Alexander Stein <[email protected]>
ALSA: hda: Cirrus: Fix coefficient index for beep configuration
Jacob Keller <[email protected]>
ptp: update adjfreq callback description
Jussi Kivilinna <[email protected]>
crypto: cryptd - disable softirqs in cryptd_queue_worker to prevent data corruption
Jeff Layton <[email protected]>
cifs: fix potential buffer overrun in cifs.idmap handling code
Rusty Russell <[email protected]>
module: fix out-by-one error in kallsyms
Eric Paris <[email protected]>
fanotify: fix missing break
Huang Ying <[email protected]>
PCI/PM: Fix deadlock when unbinding device if parent in D3cold
Felix Fietkau <[email protected]>
mac80211: call skb_dequeue/ieee80211_free_txskb instead of __skb_queue_purge
Johannes Berg <[email protected]>
mac80211: don't send null data packet when not associated
Arik Nemtsov <[email protected]>
mac80211: sync acccess to tx_filtered/ps_tx_buf queues
Dave Chinner <[email protected]>
xfs: drop buffer io reference when a bad bio is built
Takamori Yamaguchi <[email protected]>
mm: bugfix: set current->reclaim_state to NULL while returning from kswapd()
-------------
Diffstat:
 Documentation/cgroups/memory.txt              |    4 +
 Makefile                                      |    4 +-
 arch/arm/plat-omap/include/plat/omap-serial.h |    4 +-
 arch/m68k/include/asm/signal.h                |    6 +-
 arch/s390/include/asm/compat.h                |    2 +-
 arch/s390/include/asm/ptrace.h                |    4 +-
 arch/s390/kernel/compat_signal.c              |   14 +-
 arch/s390/kernel/signal.c                     |   14 +-
 arch/s390/mm/gup.c                            |    2 +-
 crypto/cryptd.c                               |   11 +-
 drivers/acpi/video.c                          |   11 +-
 drivers/block/rbd.c                           |   37 +-
 drivers/gpu/drm/i915/intel_overlay.c          |   14 +-
 drivers/gpu/drm/radeon/atombios_encoders.c    |    2 +-
 drivers/gpu/drm/ttm/ttm_page_alloc.c          |    5 +-
 drivers/net/ethernet/marvell/sky2.c           |    4 +-
 drivers/net/ethernet/realtek/r8169.c          |    7 +-
 drivers/pci/bus.c                             |    3 -
 drivers/pci/pcie/aer/aerdrv_core.c            |   20 +-
 drivers/staging/android/android_alarm.h       |    4 +-
 drivers/tty/serial/omap-serial.c              |   12 +-
 drivers/usb/serial/option.c                   |    9 +
 drivers/usb/serial/usb-serial.c               |    6 +-
 drivers/xen/events.c                          |    2 +-
 fs/ceph/addr.c                                |   32 +-
 fs/ceph/debugfs.c                             |    1 +
 fs/ceph/mds_client.c                          |   67 +-
 fs/ceph/mds_client.h                          |    5 +-
 fs/cifs/cifsacl.c                             |   49 +-
 fs/ecryptfs/main.c                            |   23 +-
 fs/nfs/nfs4proc.c                             |    3 +-
 fs/notify/fanotify/fanotify.c                 |    1 +
 fs/reiserfs/inode.c                           |   10 +-
 fs/reiserfs/stree.c                           |    4 +
 fs/reiserfs/super.c                           |   60 +-
 fs/ubifs/find.c                               |   12 +-
 fs/ubifs/lprops.c                             |    6 +
 fs/ubifs/ubifs.h                              |    3 +
 fs/xfs/xfs_buf.c                              |   14 +-
 include/linux/ceph/auth.h                     |   12 +-
 include/linux/ceph/libceph.h                  |    2 +-
 include/linux/ceph/messenger.h                |   76 +-
 include/linux/ceph/mon_client.h               |    2 +-
 include/linux/ceph/msgpool.h                  |    3 +-
 include/linux/ceph/osd_client.h               |   13 +-
 include/linux/ceph/osdmap.h                   |    6 +-
 include/linux/crush/crush.h                   |    7 +-
 include/linux/crush/mapper.h                  |    6 +-
 include/linux/ptp_clock_kernel.h              |    3 +-
 kernel/module.c                               |   27 +-
 mm/memcontrol.c                               |   21 +-
 mm/shmem.c                                    |    2 +-
 mm/vmscan.c                                   |    2 +
 net/ceph/auth_none.c                          |   15 +-
 net/ceph/auth_x.c                             |   15 +-
 net/ceph/ceph_common.c                        |   28 +-
 net/ceph/crush/crush.c                        |   14 +-
 net/ceph/crush/mapper.c                       |   66 +-
 net/ceph/crypto.c                             |    1 +
 net/ceph/crypto.h                             |    3 +-
 net/ceph/debugfs.c                            |    4 +
 net/ceph/messenger.c                          | 1103 +++++++++++++++----------
 net/ceph/mon_client.c                         |  135 ++-
 net/ceph/msgpool.c                            |    7 +-
 net/ceph/osd_client.c                         |  175 ++--
 net/ceph/osdmap.c                             |   44 +-
 net/core/dev.c                                |    4 +-
 net/core/dev_addr_lists.c                     |    3 +-
 net/ipv4/ip_sockglue.c                        |   35 +-
 net/ipv4/netfilter/nf_nat_standalone.c        |    6 +-
 net/ipv6/ipv6_sockglue.c                      |    1 +
 net/mac80211/ieee80211_i.h                    |    2 +
 net/mac80211/sta_info.c                       |   11 +-
 net/mac80211/status.c                         |    9 +
 net/mac80211/tx.c                             |    9 +-
 net/mac80211/util.c                           |    2 +
 net/netfilter/nf_conntrack_proto_tcp.c        |   29 +-
 net/wireless/reg.c                            |    5 +-
 security/selinux/netnode.c                    |    3 +-
 sound/pci/hda/patch_analog.c                  |    1 +
 sound/pci/hda/patch_cirrus.c                  |   16 +-
 sound/pci/hda/patch_realtek.c                 |    3 +
 sound/pci/hda/patch_via.c                     |   25 +-
 sound/soc/codecs/wm8978.c                     |    2 +-
 sound/soc/soc-dapm.c                          |    2 +-
 85 files changed, 1506 insertions(+), 945 deletions(-)
Greg Kroah-Hartman
maintainerPATCH 1/171 mm: bugfix: set current->reclaim_state to NULL while returning from kswapd()
3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Takamori Yamaguchi <[email protected]>
commit b0a8cc58e6b9aaae3045752059e5e6260c0b94bc upstream.
In kswapd(), set current->reclaim_state to NULL before returning, as current->reclaim_state holds reference to variable on kswapd()'s stack.
In rare cases, while returning from kswapd() during memory offlining, __free_slab() and freepages() can access the dangling pointer of current->reclaim_state.
---
 mm/vmscan.c |    2 ++
 1 file changed, 2 insertions(+)
mm/vmscan.c +2 -0
@@ -3128,6 +3128,8 @@ static int kswapd(void *p) &balanced_classzone_idx); } } + + current->reclaim_state =NULL ;return 0 ; }
Greg Kroah-Hartman
maintainerPATCH 2/171 xfs: drop buffer io reference when a bad bio is built
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Dave Chinner <[email protected]>
commit d69043c42d8c6414fa28ad18d99973aa6c1c2e24 upstream.
Error handling in xfs_buf_ioapply_map() does not handle IO reference counts correctly. We increment the b_io_remaining count before building the bio, but then fail to decrement it in the failure case. This leads to the buffer never running IO completion and releasing the reference that the IO holds, so at unmount we can leak the buffer. This leak is captured by this assert failure during unmount:
XFS: Assertion failed: atomic_read(&pag->pag_ref) == 0, file: fs/xfs/xfs_mount.c, line: 273
This is not a new bug - the b_io_remaining accounting has had this problem for a long, long time - it's just very hard to get a zero length bio being built by this code...
Further, the buffer IO error can be overwritten on a multi-segment buffer by subsequent bio completions for partial sections of the buffer. Hence we should only set the buffer error status if the buffer is not already carrying an error status. This ensures that a partial IO error on a multi-segment buffer will not be lost. This part of the problem is a regression, however.
---
 fs/xfs/xfs_buf.c |   14 ++++++++++++--
 1 file changed, 12 insertions(+), 2 deletions(-)
fs/xfs/xfs_buf.c +12 -2
@@ -1165,9 +1165,14 @@ xfs_buf_bio_end_io( {xfs_buf_t *bp = (xfs_buf_t *)bio->bi_private; -xfs_buf_ioerror (bp, -error); +/* +* don't overwrite existing errors - otherwise we can lose errors on +* buffers that require multiple bios to complete. +*/ +if (!bp->b_error) +xfs_buf_ioerror (bp, -error); -if (!error &&xfs_buf_is_vmapped (bp) && (bp->b_flags &XBF_READ )) +if (!bp->b_error &&xfs_buf_is_vmapped (bp) && (bp->b_flags &XBF_READ ))invalidate_kernel_vmap_range (bp->b_addr,xfs_buf_vmap_len (bp));_xfs_buf_ioend (bp,1 );
@@ -1243,6 +1248,11 @@ next_chunk:if (size) goto next_chunk; }else { +/* +* This is guaranteed not to be the last io reference count +* because the caller (xfs_buf_iorequest) holds a count itself. +*/ +atomic_dec (&bp->b_io_remaining);xfs_buf_ioerror (bp,EIO );bio_put (bio); }
Greg Kroah-Hartman
maintainerPATCH 3/171 mac80211: sync acccess to tx_filtered/ps_tx_buf queues
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Arik Nemtsov <[email protected]>
commit 987c285c2ae2e4e32aca3a9b3252d28171c75711 upstream.
These are accessed without a lock when ending STA PSM. If the sta_cleanup timer accesses these lists at the same time, we might crash.
This may fix some mysterious crashes we had during ieee80211_sta_ps_deliver_wakeup.
---
 net/mac80211/sta_info.c |    5 +++++
 1 file changed, 5 insertions(+)
net/mac80211/sta_info.c +5 -0
@@ -959,6 +959,7 @@ void ieee80211_sta_ps_deliver_wakeup(strstruct ieee80211_local *local = sdata->local;struct sk_buff_head pending;int filtered =0 , buffered =0 , ac; +unsigned long flags;clear_sta_flag (sta,WLAN_STA_SP );
@@ -974,12 +975,16 @@ void ieee80211_sta_ps_deliver_wakeup(strfor (ac =0 ; ac <IEEE80211_NUM_ACS ; ac++) {int count =skb_queue_len (&pending), tmp; +spin_lock_irqsave (&sta->tx_filtered[ac].lock, flags);skb_queue_splice_tail_init (&sta->tx_filtered[ac], &pending); +spin_unlock_irqrestore (&sta->tx_filtered[ac].lock, flags); tmp =skb_queue_len (&pending); filtered += tmp - count; count = tmp; +spin_lock_irqsave (&sta->ps_tx_buf[ac].lock, flags);skb_queue_splice_tail_init (&sta->ps_tx_buf[ac], &pending); +spin_unlock_irqrestore (&sta->ps_tx_buf[ac].lock, flags); tmp =skb_queue_len (&pending); buffered += tmp - count; }
Greg Kroah-Hartman
maintainerPATCH 4/171 mac80211: dont send null data packet when not associated
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Johannes Berg <[email protected]>
commit 20f544eea03db4b498942558b882d463ce575c3e upstream.
On resume or firmware recovery, mac80211 sends a null data packet to see if the AP is still around and hasn't disconnected us. However, it always does this even if it wasn't even connected before, leading to a warning in the new channel context code. Fix this by checking that it's associated.
---
 net/mac80211/util.c |    2 ++
 1 file changed, 2 insertions(+)
net/mac80211/util.c +2 -0
@@ -1341,6 +1341,8 @@ int ieee80211_reconfig(struct ieee80211_list_for_each_entry (sdata, &local->interfaces, list) {if (sdata->vif.type !=NL80211_IFTYPE_STATION )continue ; +if (!sdata->u.mgd.associated) +continue ;ieee80211_send_nullfunc (local, sdata,0 ); }
Greg Kroah-Hartman
maintainerPATCH 5/171 mac80211: call skb_dequeue/ieee80211_free_txskb instead of __skb_queue_purge
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Felix Fietkau <[email protected]>
commit 1f98ab7fef48a2968f37f422c256c9fbd978c3f0 upstream.
Fixes more wifi status skb leaks, leading to hostapd/wpa_supplicant hangs.
---
 net/mac80211/ieee80211_i.h |    2 ++
 net/mac80211/sta_info.c    |    6 +++---
 net/mac80211/status.c      |    9 +++++++++
 net/mac80211/tx.c          |    9 ++++++---
 4 files changed, 20 insertions(+), 6 deletions(-)
net/mac80211/ieee80211_i.h +2 -0
@@ -1297,6 +1297,8 @@ netdev_tx_t ieee80211_monitor_start_xmit struct net_device *dev);netdev_tx_t ieee80211_subif_start_xmit (struct sk_buff *skb,struct net_device *dev); +void ieee80211_purge_tx_queue (struct ieee80211_hw *hw, +struct sk_buff_head *skbs);/* HT */ bool ieee80111_cfg_override_disables_ht40 (struct ieee80211_sub_if_data *sdata);
net/mac80211/sta_info.c +3 -3
@@ -738,8 +738,8 @@ int __must_check __sta_info_destroy(strufor (ac =0 ; ac <IEEE80211_NUM_ACS ; ac++) { local->total_ps_buffered -=skb_queue_len (&sta->ps_tx_buf[ac]); -__skb_queue_purge (&sta->ps_tx_buf[ac]); -__skb_queue_purge (&sta->tx_filtered[ac]); +ieee80211_purge_tx_queue (&local->hw, &sta->ps_tx_buf[ac]); +ieee80211_purge_tx_queue (&local->hw, &sta->tx_filtered[ac]); }#ifdef CONFIG_MAC80211_MESH
@@ -774,7 +774,7 @@ int __must_check __sta_info_destroy(stru tid_tx =rcu_dereference_raw (sta->ampdu_mlme.tid_tx[i]);if (!tid_tx)continue ; -__skb_queue_purge (&tid_tx->pending); +ieee80211_purge_tx_queue (&local->hw, &tid_tx->pending);kfree (tid_tx); }
net/mac80211/status.c +9 -0
@@ -660,3 +660,12 @@ void ieee80211_free_txskb(struct ieee802dev_kfree_skb_any (skb); }EXPORT_SYMBOL (ieee80211_free_txskb); + +void ieee80211_purge_tx_queue (struct ieee80211_hw *hw, +struct sk_buff_head *skbs) +{ +struct sk_buff *skb; + +while ((skb =__skb_dequeue (skbs))) +ieee80211_free_txskb (hw, skb); +}
net/mac80211/tx.c +6 -3
@@ -1357,7 +1357,7 @@ static int invoke_tx_handlers(struct ieeif (tx->skb)dev_kfree_skb (tx->skb);else -__skb_queue_purge (&tx->skbs); +ieee80211_purge_tx_queue (&tx->local->hw, &tx->skbs);return -1 ; }else if (unlikely (res ==TX_QUEUED )) {I802_DEBUG_INC (tx->local->tx_handlers_queued);
@@ -2126,10 +2126,13 @@ netdev_tx_t ieee80211_subif_start_xmit(s*/ void ieee80211_clear_tx_pending (struct ieee80211_local *local) { +struct sk_buff *skb;int i; -for (i =0 ; i < local->hw.queues; i++) -skb_queue_purge (&local->pending[i]); +for (i =0 ; i < local->hw.queues; i++) { +while ((skb =skb_dequeue (&local->pending[i])) !=NULL ) +ieee80211_free_txskb (&local->hw, skb); + } }/*
Greg Kroah-Hartman
maintainerPATCH 6/171 PCI/PM: Fix deadlock when unbinding device if parent in D3cold
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Huang Ying <[email protected]>
commit 90b5c1d7c45eeb622302680ff96ed30c1a2b6f0e upstream.
If a PCI device and its parents are put into D3cold, unbinding the device will trigger deadlock as follow:
- driver_unbind
- device_release_driver
- device_lock(dev) <--- previous lock here
- __device_release_driver
- pm_runtime_get_sync
...
- rpm_resume(dev)
- rpm_resume(dev->parent)
...
- pci_pm_runtime_resume
...
- pci_set_power_state
- __pci_start_power_transition
- pci_wakeup_bus(dev->parent->subordinate)
- pci_walk_bus
- device_lock(dev) <--- deadlock here
If we do not do device_lock in pci_walk_bus, we can avoid deadlock. Device_lock in pci_walk_bus is introduced in commit:d71374dafbba7ec3f67371d3b7e9f6310a588808, corresponding email thread
is: https://lkml.org/lkml/2006/5/26/38. The patch author Zhang Yanmin said device_lock is added to pci_walk_bus because:
Some error handling functions call pci_walk_bus. For example, PCIe aer. Here we lock the device, so the driver wouldn't detach from the device, as the cb might call driver's callback function.
So I fixed the deadlock as follows:
- remove device_lock from pci_walk_bus
- add device_lock into callback if callback will call driver's callback
I checked pci_walk_bus users one by one, and found only PCIe aer needs device lock.
---
 drivers/pci/bus.c                  |    3 ---
 drivers/pci/pcie/aer/aerdrv_core.c |   20 ++++++++++++++++----
 2 files changed, 16 insertions(+), 7 deletions(-)
drivers/pci/bus.c +0 -3
@@ -314,10 +314,7 @@ void pci_walk_bus(struct pci_bus *top, i }else next = dev->bus_list.next; -/* Run device routines with the device locked */ -device_lock (&dev->dev); retval =cb (dev, userdata); -device_unlock (&dev->dev);if (retval)break ; }
drivers/pci/pcie/aer/aerdrv_core.c +16 -4
@@ -244,6 +244,7 @@ static int report_error_detected(structstruct aer_broadcast_data *result_data; result_data = (struct aer_broadcast_data *) data; +device_lock (&dev->dev); dev->error_state = result_data->state; if (!dev->driver ||
@@ -262,12 +263,14 @@ static int report_error_detected(struct dev->driver ? "no AER-aware driver" : "no driver"); } -return 0 ; + goto out; } err_handler = dev->driver->err_handler; vote = err_handler->error_detected (dev, result_data->state); result_data->result =merge_result (result_data->result, vote); +out: +device_unlock (&dev->dev);return 0 ; }
@@ -278,14 +281,17 @@ static int report_mmio_enabled(struct pcstruct aer_broadcast_data *result_data; result_data = (struct aer_broadcast_data *) data; +device_lock (&dev->dev);if (!dev->driver || !dev->driver->err_handler || !dev->driver->err_handler->mmio_enabled) -return 0 ; + goto out; err_handler = dev->driver->err_handler; vote = err_handler->mmio_enabled (dev); result_data->result =merge_result (result_data->result, vote); +out: +device_unlock (&dev->dev);return 0 ; }
@@ -296,14 +302,17 @@ static int report_slot_reset(struct pci_struct aer_broadcast_data *result_data; result_data = (struct aer_broadcast_data *) data; +device_lock (&dev->dev);if (!dev->driver || !dev->driver->err_handler || !dev->driver->err_handler->slot_reset) -return 0 ; + goto out; err_handler = dev->driver->err_handler; vote = err_handler->slot_reset (dev); result_data->result =merge_result (result_data->result, vote); +out: +device_unlock (&dev->dev);return 0 ; }
@@ -311,15 +320,18 @@ static int report_resume(struct pci_dev {struct pci_error_handlers *err_handler; +device_lock (&dev->dev); dev->error_state = pci_channel_io_normal;if (!dev->driver || !dev->driver->err_handler || !dev->driver->err_handler->resume) -return 0 ; + goto out; err_handler = dev->driver->err_handler; err_handler->resume (dev); +out: +device_unlock (&dev->dev);return 0 ; }
Greg Kroah-Hartman
maintainerPATCH 7/171 fanotify: fix missing break
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Eric Paris <[email protected]>
commit 848561d368751a1c0f679b9f045a02944506a801 upstream.
Anders Blomdell noted in 2010 that Fanotify lost events and provided a test case. Eric Paris confirmed it was a bug and posted a fix to the list
https://groups.google.com/forum/?fromgroups=#!topic/linux.kernel/RrJfTfyW2BE
but never applied it. Repeated attempts over time to actually get him to apply it have never had a reply from anyone who has raised it
So apply it anyway
---
 fs/notify/fanotify/fanotify.c |    1 +
 1 file changed, 1 insertion(+)
fs/notify/fanotify/fanotify.c +1 -0
@@ -21,6 +21,7 @@ static bool should_merge(struct fsnotifyif ((old->path.mnt == new->path.mnt) && (old->path.dentry == new->path.dentry))return true; +break ;case (FSNOTIFY_EVENT_NONE ):return true;default :
Greg Kroah-Hartman
maintainerPATCH 8/171 module: fix out-by-one error in kallsyms
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Rusty Russell <[email protected]>
commit 59ef28b1f14899b10d6b2682c7057ca00a9a3f47 upstream.
Masaki found and patched a kallsyms issue: the last symbol in a module's symtab wasn't transferred. This is because we manually copy the zero'th entry (which is always empty) then copy the rest in a loop starting at 1, though from src[0]. His fix was minimal, I prefer to rewrite the loops in more standard form.
There are two loops: one to get the size, and one to copy. Make these
identical: always count entry 0 and any defined symbol in an allocated non-init section.
This bug exists since the following commit was introduced.
module: reduce symbol table for loaded modules (v2)
commit: 4a4962263f07d14660849ec134ee42b63e95ea9a
LKML: http://lkml.org/lkml/2012/10/24/27
---
 kernel/module.c |   27 ++++++++++++++++-----------
 1 file changed, 16 insertions(+), 11 deletions(-)
kernel/module.c +16 -11
@@ -2273,12 +2273,17 @@ static void layout_symtab(struct module src = (void *)info->hdr + symsect->sh_offset; nsrc = symsect->sh_size /sizeof (*src); +/* strtab always starts with a nul, so offset 0 is the empty string. */ + strtab_size =1 ; +/* Compute total space required for the core symbols' strtab. */ -for (ndst = i = strtab_size =1 ; i < nsrc; ++i, ++src) -if (is_core_symbol (src, info->sechdrs, info->hdr->e_shnum)) { - strtab_size +=strlen (&info->strtab[src->st_name]) +1 ; +for (ndst = i =0 ; i < nsrc; i++) { +if (i ==0 || +is_core_symbol (src+i, info->sechdrs, info->hdr->e_shnum)) { + strtab_size +=strlen (&info->strtab[src[i].st_name])+1 ; ndst++; } + }/* Append room for core symbols at end of core part. */ info->symoffs =ALIGN (mod->core_size, symsect->sh_addralign ?:1 );
@@ -2312,15 +2317,15 @@ static void add_kallsyms(struct module * mod->core_symtab = dst = mod->module_core + info->symoffs; mod->core_strtab = s = mod->module_core + info->stroffs; src = mod->symtab; - *dst = *src; *s++ =0 ; -for (ndst = i =1 ; i < mod->num_symtab; ++i, ++src) { -if (!is_core_symbol (src, info->sechdrs, info->hdr->e_shnum)) -continue ; - - dst[ndst] = *src; - dst[ndst++].st_name = s - mod->core_strtab; - s +=strlcpy (s, &mod->strtab[src->st_name],KSYM_NAME_LEN ) +1 ; +for (ndst = i =0 ; i < mod->num_symtab; i++) { +if (i ==0 || +is_core_symbol (src+i, info->sechdrs, info->hdr->e_shnum)) { + dst[ndst] = src[i]; + dst[ndst++].st_name = s - mod->core_strtab; + s +=strlcpy (s, &mod->strtab[src[i].st_name], +KSYM_NAME_LEN ) +1 ; + } } mod->core_num_syms = ndst; }
Greg Kroah-Hartman
maintainerPATCH 9/171 cifs: fix potential buffer overrun in cifs.idmap handling code
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jeff Layton <[email protected]>
commit 36960e440ccf94349c09fb944930d3bfe4bc473f upstream.
The userspace cifs.idmap program generally works with the wbclient libs to generate binary SIDs in userspace. That program defines the struct that holds these values as having a max of 15 subauthorities. The kernel idmapping code however limits that value to 5.
When the kernel copies those values around though, it doesn't sanity check the num_subauths value handed back from userspace or from the server. It's possible therefore for userspace to hand us back a bogus num_subauths value (or one that's valid, but greater than 5) that could cause the kernel to walk off the end of the cifs_sid->sub_auths array.
Fix this by defining a new routine for copying sids and using that in all of the places that copy it. If we end up with a sid that's longer than expected then this approach will just lop off the "extra" subauths, but that's basically what the code does today already. Better approaches might be to fix this code to reject SIDs with >5 subauths, or fix it to handle the subauths array dynamically.
At the same time, change the kernel to check the length of the data returned by userspace. If it's shorter than struct cifs_sid, reject it and return -EIO. If that happens we'll end up with fields that are basically uninitialized.
Long term, it might make sense to redefine cifs_sid using a flexarray at the end, to allow for variable-length subauth lists, and teach the code to handle the case where the subauths array being passed in from userspace is shorter than 5 elements.
Note too, that I don't consider this a security issue since you'd need a compromised cifs.idmap program. If you have that, you can do all sorts of nefarious stuff. Still, this is probably reasonable for stable.
---
 fs/cifs/cifsacl.c |   49 ++++++++++++++++++++-----------------------------
 1 file changed, 20 insertions(+), 29 deletions(-)
fs/cifs/cifsacl.c +20 -29
@@ -225,6 +225,13 @@ sid_to_str(struct cifs_sid *sidptr, char }static void +cifs_copy_sid (struct cifs_sid *dst,const struct cifs_sid *src) +{ +memcpy (dst, src,sizeof (*dst)); + dst->num_subauth =min_t (u8, src->num_subauth,NUM_SUBAUTHS ); +} + +static void id_rb_insert (struct rb_root *root,struct cifs_sid *sidptr,struct cifs_sid_id **psidid,char *typestr) {
@@ -248,7 +255,7 @@ id_rb_insert(struct rb_root *root, struc } } -memcpy (&(*psidid)->sid, sidptr,sizeof (struct cifs_sid )); +cifs_copy_sid (&(*psidid)->sid, sidptr); (*psidid)->time = jiffies - (SID_MAP_RETRY +1 ); (*psidid)->refcount =0 ;
@@ -354,7 +361,7 @@ id_to_sid(unsigned long cid, uint sidtyp* any fields of the node after a reference is put . */ if (test_bit (SID_ID_MAPPED , &psidid->state)) { -memcpy (ssid, &psidid->sid,sizeof (struct cifs_sid )); +cifs_copy_sid (ssid, &psidid->sid); psidid->time = jiffies;/* update ts for accessing */ goto id_sid_out; }
@@ -370,14 +377,14 @@ id_to_sid(unsigned long cid, uint sidtypif (IS_ERR (sidkey)) { rc = -EINVAL ;cFYI (1 ,"%s: Can't map and id to a SID" , __func__); + }else if (sidkey->datalen <sizeof (struct cifs_sid )) { + rc = -EIO ; +cFYI (1 ,"%s: Downcall contained malformed key " +"(datalen=%hu)" , __func__, sidkey->datalen); }else { lsid = (struct cifs_sid *)sidkey->payload.data; -memcpy (&psidid->sid, lsid, - sidkey->datalen <sizeof (struct cifs_sid ) ? - sidkey->datalen :sizeof (struct cifs_sid )); -memcpy (ssid, &psidid->sid, - sidkey->datalen <sizeof (struct cifs_sid ) ? - sidkey->datalen :sizeof (struct cifs_sid )); +cifs_copy_sid (&psidid->sid, lsid); +cifs_copy_sid (ssid, &psidid->sid);set_bit (SID_ID_MAPPED , &psidid->state);key_put (sidkey);kfree (psidid->sidstr);
@@ -396,7 +403,7 @@ id_to_sid(unsigned long cid, uint sidtypreturn rc; }if (test_bit (SID_ID_MAPPED , &psidid->state)) -memcpy (ssid, &psidid->sid,sizeof (struct cifs_sid )); +cifs_copy_sid (ssid, &psidid->sid);else rc = -EINVAL ; }
@@ -675,8 +682,6 @@ int compare_sids(const struct cifs_sid *static void copy_sec_desc (const struct cifs_ntsd *pntsd,struct cifs_ntsd *pnntsd,__u32 sidsoffset) { -int i; -struct cifs_sid *owner_sid_ptr, *group_sid_ptr;struct cifs_sid *nowner_sid_ptr, *ngroup_sid_ptr;
@@ -692,26 +697,14 @@ static void copy_sec_desc(const struct c owner_sid_ptr = (struct cifs_sid *)((char *)pntsd +le32_to_cpu (pntsd->osidoffset)); nowner_sid_ptr = (struct cifs_sid *)((char *)pnntsd + sidsoffset); - - nowner_sid_ptr->revision = owner_sid_ptr->revision; - nowner_sid_ptr->num_subauth = owner_sid_ptr->num_subauth; -for (i =0 ; i <6 ; i++) - nowner_sid_ptr->authority[i] = owner_sid_ptr->authority[i]; -for (i =0 ; i <5 ; i++) - nowner_sid_ptr->sub_auth[i] = owner_sid_ptr->sub_auth[i]; +cifs_copy_sid (nowner_sid_ptr, owner_sid_ptr);/* copy group sid */ group_sid_ptr = (struct cifs_sid *)((char *)pntsd +le32_to_cpu (pntsd->gsidoffset)); ngroup_sid_ptr = (struct cifs_sid *)((char *)pnntsd + sidsoffset +sizeof (struct cifs_sid )); - - ngroup_sid_ptr->revision = group_sid_ptr->revision; - ngroup_sid_ptr->num_subauth = group_sid_ptr->num_subauth; -for (i =0 ; i <6 ; i++) - ngroup_sid_ptr->authority[i] = group_sid_ptr->authority[i]; -for (i =0 ; i <5 ; i++) - ngroup_sid_ptr->sub_auth[i] = group_sid_ptr->sub_auth[i]; +cifs_copy_sid (ngroup_sid_ptr, group_sid_ptr);return ; }
@@ -1120,8 +1113,7 @@ static int build_sec_desc(struct cifs_ntkfree (nowner_sid_ptr);return rc; } -memcpy (owner_sid_ptr, nowner_sid_ptr, -sizeof (struct cifs_sid )); +cifs_copy_sid (owner_sid_ptr, nowner_sid_ptr);kfree (nowner_sid_ptr); *aclflag =CIFS_ACL_OWNER ; }
@@ -1139,8 +1131,7 @@ static int build_sec_desc(struct cifs_ntkfree (ngroup_sid_ptr);return rc; } -memcpy (group_sid_ptr, ngroup_sid_ptr, -sizeof (struct cifs_sid )); +cifs_copy_sid (group_sid_ptr, ngroup_sid_ptr);kfree (ngroup_sid_ptr); *aclflag =CIFS_ACL_GROUP ; }
Greg Kroah-Hartman
maintainerPATCH 10/171 crypto: cryptd - disable softirqs in cryptd_queue_worker to prevent data corruption
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jussi Kivilinna <[email protected]>
commit 9efade1b3e981f5064f9db9ca971b4dc7557ae42 upstream.
cryptd_queue_worker attempts to prevent simultaneous accesses to crypto workqueue by cryptd_enqueue_request using preempt_disable/preempt_enable. However cryptd_enqueue_request might be called from softirq context, so add local_bh_disable/local_bh_enable to prevent data corruption and panics.
Bug report at http://marc.info/?l=linux-crypto-vger&m=134858649616319&w=2
v2:
- Disable software interrupts instead of hardware interrupts
---
 crypto/cryptd.c |   11 ++++++++---
 1 file changed, 8 insertions(+), 3 deletions(-)
crypto/cryptd.c +8 -3
@@ -137,13 +137,18 @@ static void cryptd_queue_worker(struct wstruct crypto_async_request *req, *backlog; cpu_queue = container_of(work, struct cryptd_cpu_queue, work); -/* Only handle one request at a time to avoid hogging crypto -* workqueue. preempt_disable/enable is used to prevent -* being preempted by cryptd_enqueue_request() */ +/* +* Only handle one request at a time to avoid hogging crypto workqueue. +* preempt_disable/enable is used to prevent being preempted by +* cryptd_enqueue_request(). local_bh_disable/enable is used to prevent +* cryptd_enqueue_request() being accessed from software interrupts. +*/ +local_bh_disable ();preempt_disable (); backlog =crypto_get_backlog (&cpu_queue->queue); req =crypto_dequeue_request (&cpu_queue->queue);preempt_enable (); +local_bh_enable ();if (!req)return ;
Greg Kroah-Hartman
maintainerPATCH 11/171 ptp: update adjfreq callback description
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jacob Keller <[email protected]>
commit 87f4d7c1d36f44b0822053b7e5dedc31fdd0ab99 upstream.
This patch updates the adjfreq callback description to include a note that the delta in ppb is always relative to the base frequency, and not to the current frequency of the hardware clock.
---
 include/linux/ptp_clock_kernel.h |    3 ++-
 1 file changed, 2 insertions(+), 1 deletion(-)
include/linux/ptp_clock_kernel.h +2 -1
@@ -50,7 +50,8 @@ struct ptp_clock_request {* clock operations * * @adjfreq: Adjusts the frequency of the hardware clock. -* parameter delta: Desired period change in parts per billion. +* parameter delta: Desired frequency offset from nominal frequency +* in parts per billion * * @adjtime: Shifts the time of the hardware clock. * parameter delta: Desired change in nanoseconds.
Re: [ 011/171] ptp: update adjfreq callback description
Quoted 27 lines · Greg Kroah-Hartman
3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jacob Keller <[email protected]>
commit
87f4d7c1d36f44b0822053b7e5dedc31fdd0ab99upstream.This patch updates the adjfreq callback description to include a note that the delta in ppb is always relative to the base frequency, and not to the current frequency of the hardware clock.
Signed-off-by Jacob Keller <[email protected]>CC Richard Cochran <[email protected]>CC John Stultz <[email protected]>Signed-off-by Jeff Kirsher <[email protected]>Signed-off-by David S. Miller <[email protected]>Signed-off-by Greg Kroah-Hartman <[email protected]>--- include/linux/ptp_clock_kernel.h | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)
include/linux/ptp_clock_kernel.h struct ptp_clock_request { · line 57
Quoted 9 lines
include/linux/ptp_clock_kernel.h +2
-1@@ -50,7 +50,8 @@ struct ptp_clock_request {* clock operations * * @adjfreq: Adjusts the frequency of the hardware clock. -* parameter delta: Desired period change in parts per billion. +* parameter delta: Desired frequency offset from nominal frequency +* in parts per billion * * @adjtime: Shifts the time of the hardware clock. * parameter delta: Desired change in nanoseconds.
This was marked for only 3.5 or later on the original changelog:
"CC: [email protected] [v3.5+]"
Signature · 2 lines
[]'s
Herton
RE: [ 011/171] ptp: update adjfreq callback description
Quoted 52 lines
-----Original Message-----
From: Herton Ronaldo Krzesinski [mailto:[email protected]]
Sent: Friday, November 23, 2012 4:27 PM
To: Greg Kroah-Hartman
Cc: [email protected]; [email protected]; [email protected]; Keller, Jacob E; Richard Cochran; John Stultz; Kirsher, Jeffrey T; David S. Miller
Subject: Re: [ 011/171] ptp: update adjfreq callback descriptionQuoted 1 line · Greg Kroah-Hartman
3.4-stable review patch. If anyone has any objections, please let me
know.
Quoted 8 lines
------------------
From: Jacob Keller <[email protected]>
commit
87f4d7c1d36f44b0822053b7e5dedc31fdd0ab99upstream.This patch updates the adjfreq callback description to include a note
that the
Quoted 1 line
delta in ppb is always relative to the base frequency, and not to the
current
Quoted 16 lines
frequency of the hardware clock.
Signed-off-by Jacob Keller <[email protected]>CC Richard Cochran <[email protected]>CC John Stultz <[email protected]>Signed-off-by Jeff Kirsher <[email protected]>Signed-off-by David S. Miller <[email protected]>Signed-off-by Greg Kroah-Hartman <[email protected]>--- include/linux/ptp_clock_kernel.h | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)include/linux/ptp_clock_kernel.h struct ptp_clock_request { · line 53
Quoted 4 lines
include/linux/ptp_clock_kernel.h +0
-1@@ -50,7 +50,8 @@ struct ptp_clock_request {* clock operations * * @adjfreq: Adjusts the frequency of the hardware clock. -* parameter delta: Desired period change in parts per billion.
include/linux/ptp_clock_kernel.h struct ptp_clock_request { · line 53
Quoted 1 line
include/linux/ptp_clock_kernel.h +1
-0+* parameter delta: Desired frequency offset from nominal frequency
include/linux/ptp_clock_kernel.h struct ptp_clock_request { · line 57
Quoted 5 lines
include/linux/ptp_clock_kernel.h +1
-0+* in parts per billion * * @adjtime: Shifts the time of the hardware clock. * parameter delta: Desired change in nanoseconds.
Quoted 6 lines
This was marked for only 3.5 or later on the original changelog:
"CC: [email protected] [v3.5+]"--
[]'s
Herton
Originally didn't notice how far back PTP went.
-Jake
Greg Kroah-Hartman
maintainerPATCH 12/171 ALSA: hda: Cirrus: Fix coefficient index for beep configuration
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alexander Stein <[email protected]>
commit 5a83b4b5a391f07141b157ac9daa51c409e71ab5 upstream.
---
 sound/pci/hda/patch_cirrus.c |    2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
sound/pci/hda/patch_cirrus.c +1 -1
@@ -1112,7 +1112,7 @@ static const struct hda_verb cs_coef_ini | 0x0400 /* Disable Coefficient Auto increment */ )},/* Beep */ - {0x11, AC_VERB_SET_COEF_INDEX, IDX_DAC_CFG}, + {0x11, AC_VERB_SET_COEF_INDEX, IDX_BEEP_CFG}, {0x11, AC_VERB_SET_PROC_COEF, 0x0007}, /* Enable Beep thru DAC1/2/3 */ {} /* terminator */
Greg Kroah-Hartman
maintainerPATCH 13/171 ALSA: HDA: Fix digital microphone on CS420x
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Daniel J Blueman <[email protected]>
commit 16337e028a6dae9fbdd718c0d42161540a668ff3 upstream.
Correctly enable the digital microphones with the right bits in the right coeffecient registers on Cirrus CS4206/7 codecs. It also prevents misconfiguring ADC1/2.
This fixes the digital mic on the Macbook Pro 10,1/Retina.
---
 sound/pci/hda/patch_cirrus.c |   14 +++++++++-----
 1 file changed, 9 insertions(+), 5 deletions(-)
sound/pci/hda/patch_cirrus.c +9 -5
@@ -95,8 +95,8 @@ enum {#define CS420X_VENDOR_NID 0x11#define CS_DIG_OUT1_PIN_NID 0x10#define CS_DIG_OUT2_PIN_NID 0x15 -#define CS_DMIC1_PIN_NID 0x12 -#define CS_DMIC2_PIN_NID 0x0e +#define CS_DMIC1_PIN_NID 0x0e +#define CS_DMIC2_PIN_NID 0x12/* coef indices */ #define IDX_SPDIF_STAT 0x0000
@@ -1084,14 +1084,18 @@ static void init_input(struct hda_codeccs_automic (codec); coef =0x000a ;/* ADC1/2 - Digital and Analog Soft Ramp */ +cs_vendor_coef_set (codec,IDX_ADC_CFG , coef); + + coef =cs_vendor_coef_get (codec,IDX_BEEP_CFG );if (is_active_pin (codec,CS_DMIC2_PIN_NID )) - coef |=0x0500 ;/* DMIC2 2 chan on, GPIO1 off */ + coef |=1 <<4 ;/* DMIC2 2 chan on, GPIO1 off */ if (is_active_pin (codec,CS_DMIC1_PIN_NID )) - coef |=0x1800 ;/* DMIC1 2 chan on, GPIO0 off + coef |=1 <<3 ;/* DMIC1 2 chan on, GPIO0 off * No effect if SPDIF_OUT2 is * selected in IDX_SPDIF_CTL. */ -cs_vendor_coef_set (codec,IDX_ADC_CFG , coef); + +cs_vendor_coef_set (codec,IDX_BEEP_CFG , coef); }else {if (spec->mic_detect)cs_automic (codec);
Greg Kroah-Hartman
maintainerPATCH 14/171 ALSA: hda - Force to reset IEC958 status bits for AD codecs
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Takashi Iwai <[email protected]>
commit ae24c3191ba2ab03ec6b4be323e730e00404b4b6 upstream.
Several bug reports suggest that the forcibly resetting IEC958 status bits is required for AD codecs to get the SPDIF output working properly after changing streams.
Original fix credit to Javeed Shaikh.
---
 sound/pci/hda/patch_analog.c |    1 +
 1 file changed, 1 insertion(+)
sound/pci/hda/patch_analog.c +1 -0
@@ -544,6 +544,7 @@ static int ad198x_build_pcms(struct hda_if (spec->multiout.dig_out_nid) { info++; codec->num_pcms++; + codec->spdif_status_reset =1 ; info->name ="AD198x Digital" ; info->pcm_type =HDA_PCM_TYPE_SPDIF ; info->stream[SNDRV_PCM_STREAM_PLAYBACK ] = ad198x_pcm_digital_playback;
Greg Kroah-Hartman
maintainerPATCH 15/171 ALSA: hda - Fix empty DAC filling in patch_via.c
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Takashi Iwai <[email protected]>
commit 5b3761954dac2d1393beef8210eb8cee81d16b8d upstream.
In via_auto_fill_adc_nids(), the parser tries to fill dac_nids[] at the point of the current line-out (i). When no valid path is found for this output, this results in dac = 0, thus it creates a hole in dac_nids[]. This confuses is_empty_dac() and trims the detected DAC in later reference.
This patch fixes the bug by appending DAC properly to dac_nids[] in via_auto_fill_adc_nids().
---
 sound/pci/hda/patch_via.c |   11 ++++-------
 1 file changed, 4 insertions(+), 7 deletions(-)
sound/pci/hda/patch_via.c +4 -7
@@ -1868,11 +1868,11 @@ static int via_auto_fill_dac_nids(struct {struct via_spec *spec = codec->spec;const struct auto_pin_cfg *cfg = &spec->autocfg; -int i, dac_num; +int i;hda_nid_t nid; + spec->multiout.num_dacs =0 ; spec->multiout.dac_nids = spec->private_dac_nids; - dac_num =0 ;for (i =0 ; i < cfg->line_outs; i++) {hda_nid_t dac =0 ; nid = cfg->line_out_pins[i];
@@ -1883,16 +1883,13 @@ static int via_auto_fill_dac_nids(structif (!i &&parse_output_path (codec, nid, dac,1 , &spec->out_mix_path)) dac = spec->out_mix_path.path[0 ]; -if (dac) { - spec->private_dac_nids[i] = dac; - dac_num++; - } +if (dac) + spec->private_dac_nids[spec->multiout.num_dacs++] = dac; }if (!spec->out_path[0 ].depth && spec->out_mix_path.depth) { spec->out_path[0 ] = spec->out_mix_path; spec->out_mix_path.depth =0 ; } - spec->multiout.num_dacs = dac_num;return 0 ; }
Greg Kroah-Hartman
maintainerPATCH 16/171 ALSA: hda - Fix invalid connections in VT1802 codec
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Takashi Iwai <[email protected]>
commit ef4da45828603df57e5e21b8aa21a66ce309f79b upstream.
VT1802 codec provides the invalid connection lists of NID 0x24 and 0x33 containing the routes to a non-exist widget 0x3e. This confuses the auto-parser. Fix it up in the driver by overriding these connections.
---
 sound/pci/hda/patch_via.c |   14 ++++++++++++++
 1 file changed, 14 insertions(+)
sound/pci/hda/patch_via.c +14 -0
@@ -3665,6 +3665,18 @@ static void set_widgets_power_state_vt20update_power_state (codec,0x21 ,AC_PWRST_D3 ); } +/* NIDs 0x24 and 0x33 on VT1802 have connections to non-existing NID 0x3e +* Replace this with mixer NID 0x1c +*/ +static void fix_vt1802_connections (struct hda_codec *codec) +{ +static hda_nid_t conn_24[] = {0x14 ,0x1c }; +static hda_nid_t conn_33[] = {0x1c }; + +snd_hda_override_conn_list (codec,0x24 ,ARRAY_SIZE (conn_24), conn_24); +snd_hda_override_conn_list (codec,0x33 ,ARRAY_SIZE (conn_33), conn_33); +} +/* patch for vt2002P */ static int patch_vt2002P (struct hda_codec *codec) {
@@ -3679,6 +3691,8 @@ static int patch_vt2002P(struct hda_code spec->aa_mix_nid =0x21 ;override_mic_boost (codec,0x2b ,0 ,3 ,40 );override_mic_boost (codec,0x29 ,0 ,3 ,40 ); +if (spec->codec_type ==VT1802 ) +fix_vt1802_connections (codec);add_secret_dac_path (codec);/* automatic parse from the BIOS config */
Greg Kroah-Hartman
maintainerPATCH 17/171 ALSA: hda - Add new codec ALC668 and ALC900 (default name ALC1150)
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Kailang Yang <[email protected]>
commit 19a62823eae453619604636082085812c14ee391 upstream.
---
 sound/pci/hda/patch_realtek.c |    2 ++
 1 file changed, 2 insertions(+)
sound/pci/hda/patch_realtek.c +2 -0
@@ -7047,6 +7047,7 @@ static const struct hda_codec_preset snd
 	  .patch = patch_alc662 },
 	{ .id = 0x10ec0663, .name = "ALC663", .patch = patch_alc662 },
 	{ .id = 0x10ec0665, .name = "ALC665", .patch = patch_alc662 },
+	{ .id = 0x10ec0668, .name = "ALC668", .patch = patch_alc662 },
 	{ .id = 0x10ec0670, .name = "ALC670", .patch = patch_alc662 },
 	{ .id = 0x10ec0680, .name = "ALC680", .patch = patch_alc680 },
 	{ .id = 0x10ec0880, .name = "ALC880", .patch = patch_alc880 },
@@ -7064,6 +7065,7 @@ static const struct hda_codec_preset snd { .id = 0x10ec0889, .name = "ALC889", .patch = patch_alc882 }, { .id = 0x10ec0892, .name = "ALC892", .patch = patch_alc662 }, { .id = 0x10ec0899, .name = "ALC898", .patch = patch_alc882 }, + { .id = 0x10ec0900, .name = "ALC1150", .patch = patch_alc882 }, {}/* terminator */ };
Greg Kroah-Hartman
maintainerPATCH 18/171 ALSA: hda - Add a missing quirk entry for iMac 9,1
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Takashi Iwai <[email protected]>
commit 05193639ca977cc889668718adb38db6d585045b upstream.
This is another variant of iMac 9,1 with a different codec SSID.
---
 sound/pci/hda/patch_realtek.c |    1 +
 1 file changed, 1 insertion(+)
sound/pci/hda/patch_realtek.c +1 -0
@@ -5458,6 +5458,7 @@ static const struct snd_pci_quirk alc882SND_PCI_QUIRK (0x106b ,0x4000 ,"MacbookPro 5,1" ,ALC889_FIXUP_IMAC91_VREF ),SND_PCI_QUIRK (0x106b ,0x4100 ,"Macmini 3,1" ,ALC889_FIXUP_IMAC91_VREF ),SND_PCI_QUIRK (0x106b ,0x4200 ,"Mac Pro 5,1" ,ALC885_FIXUP_MACPRO_GPIO ), +SND_PCI_QUIRK (0x106b ,0x4300 ,"iMac 9,1" ,ALC889_FIXUP_IMAC91_VREF ),SND_PCI_QUIRK (0x106b ,0x4600 ,"MacbookPro 5,2" ,ALC889_FIXUP_IMAC91_VREF ),SND_PCI_QUIRK (0x106b ,0x4900 ,"iMac 9,1 Aluminum" ,ALC889_FIXUP_IMAC91_VREF ), SND_PCI_QUIRK(0x106b, 0x4a00, "Macbook 5,2", ALC889_FIXUP_IMAC91_VREF),
Greg Kroah-Hartman
maintainerPATCH 19/171 ASoC: wm8978: pll incorrectly configured when codec is master
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Eric Millbrandt <[email protected]>
commit 55c6f4cb6ef49afbb86222c6a3ff85329199c729 upstream.
When MCLK is supplied externally and BCLK and LRC are configured as outputs (codec is master), the PLL values are only calculated correctly on the first transmission. On subsequent transmissions, at differenct sample rates, the wrong PLL values are used. Test for f_opclk instead of f_pllout to determine if the PLL values are needed.
---
 sound/soc/codecs/wm8978.c |    2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
sound/soc/codecs/wm8978.c +1 -1
@@ -783,7 +783,7 @@ static int wm8978_hw_params(struct snd_p wm8978->mclk_idx =-1 ; f_sel = wm8978->f_mclk; }else { -if (!wm8978->f_pllout) { +if (!wm8978->f_opclk) {/* We only enter here, if OPCLK is not used */ int ret =wm8978_configure_pll (codec);if (ret <0 )
Greg Kroah-Hartman
maintainerPATCH 20/171 ASoC: dapm: Use card_list during DAPM shutdown
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Misael Lopez Cruz <[email protected]>
commit 445632ad6dda42f4d3f9df2569a852ca0d4ea608 upstream.
DAPM shutdown incorrectly uses "list" field of codec struct while iterating over probed components (codec_dev_list). "list" field refers to codecs registered in the system, "card_list" field is used for probed components.
---
 sound/soc/soc-dapm.c |    2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
sound/soc/soc-dapm.c +1 -1
@@ -3253,7 +3253,7 @@ void snd_soc_dapm_shutdown(struct snd_so {struct snd_soc_codec *codec; -list_for_each_entry (codec, &card->codec_dev_list, list) { +list_for_each_entry (codec, &card->codec_dev_list, card_list) {soc_dapm_shutdown_codec (&codec->dapm);if (codec->dapm.bias_level ==SND_SOC_BIAS_STANDBY ) snd_soc_dapm_set_bias_level(&codec->dapm,
Greg Kroah-Hartman
maintainerPATCH 21/171 UBIFS: fix mounting problems after power cuts
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Artem Bityutskiy <[email protected]>
commit a28ad42a4a0c6f302f488f26488b8b37c9b30024 upstream.
This is a bugfix for a problem with the following symptoms:
1. A power cut happens
2. After reboot, we try to mount UBIFS
3. Mount fails with "No space left on device" error message
UBIFS complains like this:
UBIFS error (pid 28225): grab_empty_leb: could not find an empty LEB
The root cause of this problem is that when we mount, not all LEBs are categorized. Only those which were read are. However, the 'ubifs_find_free_leb_for_idx()' function assumes that all LEBs were categorized and 'c->freeable_cnt' is valid, which is a false assumption.
This patch fixes the problem by teaching 'ubifs_find_free_leb_for_idx()' to always fall back to LPT scanning if no freeable LEBs were found.
This problem was reported by few people in the past, but Brent Taylor was able to reproduce it and send me a flash image which cannot be mounted, which made it easy to hunt the bug. Kudos to Brent.
---
 fs/ubifs/find.c |   12 ++++++++++--
 1 file changed, 10 insertions(+), 2 deletions(-)
fs/ubifs/find.c +10 -2
@@ -681,8 +681,16 @@ int ubifs_find_free_leb_for_idx(struct uif (!lprops) { lprops =ubifs_fast_find_freeable (c);if (!lprops) { -ubifs_assert (c->freeable_cnt ==0 ); -if (c->lst.empty_lebs - c->lst.taken_empty_lebs >0 ) { +/* +* The first condition means the following: go scan the +* LPT if there are uncategorized lprops, which means +* there may be freeable LEBs there (UBIFS does not +* store the information about freeable LEBs in the +* master node). +*/ +if (c->in_a_category_cnt != c->main_lebs || + c->lst.empty_lebs - c->lst.taken_empty_lebs >0 ) { +ubifs_assert (c->freeable_cnt ==0 ); lprops =scan_for_leb_for_idx (c);if (IS_ERR (lprops)) { err =PTR_ERR (lprops);
Greg Kroah-Hartman
maintainerPATCH 22/171 UBIFS: introduce categorized lprops counter
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Artem Bityutskiy <[email protected]>
commit 98a1eebda3cb2a84ecf1f219bb3a95769033d1bf upstream.
This commit is a preparation for a subsequent bugfix. We introduce a counter for categorized lprops.
---
 fs/ubifs/lprops.c |    6 ++++++
 fs/ubifs/ubifs.h  |    3 +++
 2 files changed, 9 insertions(+)
fs/ubifs/lprops.c +6 -0
@@ -300,8 +300,11 @@ void ubifs_add_to_cat(struct ubifs_infodefault :ubifs_assert (0 ); } + lprops->flags &= ~LPROPS_CAT_MASK ; lprops->flags |= cat; + c->in_a_category_cnt +=1 ; +ubifs_assert (c->in_a_category_cnt <= c->main_lebs); }/**
@@ -334,6 +337,9 @@ static void ubifs_remove_from_cat(structdefault :ubifs_assert (0 ); } + + c->in_a_category_cnt -=1 ; +ubifs_assert (c->in_a_category_cnt >=0 ); }/**
fs/ubifs/ubifs.h +3 -0
@@ -1184,6 +1184,8 @@ struct ubifs_debug_info;* @freeable_list: list of freeable non-index LEBs (free + dirty == @leb_size) * @frdi_idx_list: list of freeable index LEBs (free + dirty == @leb_size) * @freeable_cnt: number of freeable LEBs in @freeable_list +* @in_a_category_cnt: count of lprops which are in a certain category, which +* basically meants that they were loaded from the flash * * @ltab_lnum: LEB number of LPT's own lprops table * @ltab_offs: offset of LPT's own lprops table
@@ -1413,6 +1415,7 @@ struct ubifs_info {struct list_head freeable_list;struct list_head frdi_idx_list;int freeable_cnt; +int in_a_category_cnt;int ltab_lnum;int ltab_offs;
Greg Kroah-Hartman
maintainerPATCH 23/171 Revert "Staging: Android alarm: IOCTL command encoding fix"
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Colin Cross <[email protected]>
commit d38e0e3fed4f58bcddef4dc93a591dfe2f651cb0 upstream.
Commit 6bd4a5d96c08dc2380f8053b1bd4f879f55cd3c9 changed the ANDROID_ALARM_GET_TIME ioctls from IOW to IOR. While technically correct, the _IOC_DIR bits are ignored by alarm_ioctl, so the commit breaks a userspace ABI used by all existing Android devices for a purely cosmetic reason. Revert it.
---
 drivers/staging/android/android_alarm.h |    4 +---
 1 file changed, 1 insertion(+), 3 deletions(-)
drivers/staging/android/android_alarm.h +1 -3
@@ -110,12 +110,10 @@ enum android_alarm_return_flags {#define ANDROID_ALARM_WAIT _IO('a', 1)#define ALARM_IOW (c, type, size) _IOW('a', (c) | ((type) << 4), size) -#define ALARM_IOR (c, type, size) _IOR('a', (c) | ((type) << 4), size) -/* Set alarm */ #define ANDROID_ALARM_SET (type) ALARM_IOW(2, type, struct timespec)#define ANDROID_ALARM_SET_AND_WAIT (type) ALARM_IOW(3, type, struct timespec) -#define ANDROID_ALARM_GET_TIME (type) ALARM_IOR(4, type, struct timespec) +#define ANDROID_ALARM_GET_TIME (type) ALARM_IOW(4, type, struct timespec)#define ANDROID_ALARM_SET_RTC _IOW('a', 5, struct timespec)#define ANDROID_ALARM_BASE_CMD (cmd) (cmd & ~(_IOC(0, 0, 0xf0, 0)))#define ANDROID_ALARM_IOCTL_TO_TYPE (cmd) (_IOC_NR(cmd) >> 4)
Greg Kroah-Hartman
maintainerPATCH 24/171 s390/gup: add missing TASK_SIZE check to get_user_pages_fast()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Heiko Carstens <[email protected]>
commit d55c4c613fc4d4ad2ba0fc6fa2b57176d420f7e4 upstream.
When walking page tables we need to make sure that everything is within bounds of the ASCE limit of the task's address space. Otherwise we might calculate e.g. a pud pointer which is not within a pud and dereference it.
So check against TASK_SIZE (which is the ASCE limit) before walking page tables.
---
 arch/s390/mm/gup.c |    2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
arch/s390/mm/gup.c +1 -1
@@ -183,7 +183,7 @@ int get_user_pages_fast(unsigned long st addr = start; len = (unsigned long ) nr_pages <<PAGE_SHIFT ; end = start + len; -if (end < start) +if ((end < start) || (end >TASK_SIZE )) goto slow_irqon;/*
Greg Kroah-Hartman
maintainerPATCH 25/171 USB: option: add Novatel E362 and Dell Wireless 5800 USB IDs
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Dan Williams <[email protected]>
commit fcb21645f1bd86d2be29baf48aa1b298de52ccc7 upstream.
The Dell 5800 appears to be a simple rebrand of the Novatel E362.
---
 drivers/usb/serial/option.c |    7 +++++++
 1 file changed, 7 insertions(+)
drivers/usb/serial/option.c +7 -0
@@ -157,6 +157,7 @@ static void option_instat_callback(struc#define NOVATELWIRELESS_PRODUCT_EVDO_EMBEDDED_HIGHSPEED 0x8001#define NOVATELWIRELESS_PRODUCT_HSPA_EMBEDDED_FULLSPEED 0x9000#define NOVATELWIRELESS_PRODUCT_HSPA_EMBEDDED_HIGHSPEED 0x9001 +#define NOVATELWIRELESS_PRODUCT_E362 0x9010#define NOVATELWIRELESS_PRODUCT_G1 0xA001#define NOVATELWIRELESS_PRODUCT_G1_M 0xA002#define NOVATELWIRELESS_PRODUCT_G2 0xA010
@@ -192,6 +193,9 @@ static void option_instat_callback(struc#define DELL_PRODUCT_5730_MINICARD_TELUS 0x8181#define DELL_PRODUCT_5730_MINICARD_VZW 0x8182 +#define DELL_PRODUCT_5800_MINICARD_VZW 0x8195/* Novatel E362 */ +#define DELL_PRODUCT_5800_V2_MINICARD_VZW 0x8196/* Novatel E362 */ +#define KYOCERA_VENDOR_ID 0x0c88#define KYOCERA_PRODUCT_KPC650 0x17da#define KYOCERA_PRODUCT_KPC680 0x180a
@@ -705,6 +709,7 @@ static const struct usb_device_id option { USB_DEVICE(NOVATELWIRELESS_VENDOR_ID, NOVATELWIRELESS_PRODUCT_G2) },/* Novatel Ovation MC551 a.k.a. Verizon USB551L */ { USB_DEVICE_AND_INTERFACE_INFO(NOVATELWIRELESS_VENDOR_ID, NOVATELWIRELESS_PRODUCT_MC551, 0xff, 0xff, 0xff) }, + { USB_DEVICE_AND_INTERFACE_INFO(NOVATELWIRELESS_VENDOR_ID, NOVATELWIRELESS_PRODUCT_E362, 0xff, 0xff, 0xff) }, { USB_DEVICE(AMOI_VENDOR_ID, AMOI_PRODUCT_H01) }, { USB_DEVICE(AMOI_VENDOR_ID, AMOI_PRODUCT_H01A) },
@@ -727,6 +732,8 @@ static const struct usb_device_id option
 	{ USB_DEVICE(DELL_VENDOR_ID, DELL_PRODUCT_5730_MINICARD_SPRINT) },	/* Dell Wireless 5730 Mobile Broadband EVDO/HSPA Mini-Card */
 	{ USB_DEVICE(DELL_VENDOR_ID, DELL_PRODUCT_5730_MINICARD_TELUS) },	/* Dell Wireless 5730 Mobile Broadband EVDO/HSPA Mini-Card */
 	{ USB_DEVICE(DELL_VENDOR_ID, DELL_PRODUCT_5730_MINICARD_VZW) }, 	/* Dell Wireless 5730 Mobile Broadband EVDO/HSPA Mini-Card */
+	{ USB_DEVICE_AND_INTERFACE_INFO(DELL_VENDOR_ID, DELL_PRODUCT_5800_MINICARD_VZW, 0xff, 0xff, 0xff) },
+	{ USB_DEVICE_AND_INTERFACE_INFO(DELL_VENDOR_ID, DELL_PRODUCT_5800_V2_MINICARD_VZW, 0xff, 0xff, 0xff) },
 	{ USB_DEVICE(ANYDATA_VENDOR_ID, ANYDATA_PRODUCT_ADU_E100A) },	/* ADU-E100, ADU-310 */
 	{ USB_DEVICE(ANYDATA_VENDOR_ID, ANYDATA_PRODUCT_ADU_500A) },
 	{ USB_DEVICE(ANYDATA_VENDOR_ID, ANYDATA_PRODUCT_ADU_620UW) },
Greg Kroah-Hartman
maintainerPATCH 26/171 USB: option: add Alcatel X220/X500D USB IDs
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Dan Williams <[email protected]>
commit c0bc3098871dd9b964f6b45ec1e4d70d87811744 upstream.
---
 drivers/usb/serial/option.c |    2 ++
 1 file changed, 2 insertions(+)
drivers/usb/serial/option.c +2 -0
@@ -286,6 +286,7 @@ static void option_instat_callback(struc/* ALCATEL PRODUCTS */ #define ALCATEL_VENDOR_ID 0x1bbb#define ALCATEL_PRODUCT_X060S_X200 0x0000 +#define ALCATEL_PRODUCT_X220_X500D 0x0017#define PIRELLI_VENDOR_ID 0x1266#define PIRELLI_PRODUCT_C100_1 0x1002
@@ -1163,6 +1164,7 @@ static const struct usb_device_id option
 	{ USB_DEVICE(ALCATEL_VENDOR_ID, ALCATEL_PRODUCT_X060S_X200),
 	  .driver_info = (kernel_ulong_t)&alcatel_x200_blacklist
 	},
+	{ USB_DEVICE(ALCATEL_VENDOR_ID, ALCATEL_PRODUCT_X220_X500D) },
 	{ USB_DEVICE(AIRPLUS_VENDOR_ID, AIRPLUS_PRODUCT_MCD650) },
 	{ USB_DEVICE(TLAYTECH_VENDOR_ID, TLAYTECH_PRODUCT_TEU800) },
 	{ USB_DEVICE(LONGCHEER_VENDOR_ID, FOUR_G_SYSTEMS_PRODUCT_W14),
Greg Kroah-Hartman
maintainerPATCH 27/171 drm/radeon: fix logic error in atombios_encoders.c
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Deucher <[email protected]>
commit b9196395c905edec512dfd6690428084228c16ec upstream.
Fixes:
https://bugzilla.kernel.org/show_bug.cgi?id=50431
---
 drivers/gpu/drm/radeon/atombios_encoders.c |    2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/gpu/drm/radeon/atombios_encoders.c +1 -1
@@ -1421,7 +1421,7 @@ radeon_atom_encoder_dpms_dig(struct drm_atombios_dig_transmitter_setup (encoder,ATOM_TRANSMITTER_ACTION_SETUP ,0 ,0 );atombios_dig_transmitter_setup (encoder,ATOM_TRANSMITTER_ACTION_ENABLE ,0 ,0 );/* some early dce3.2 boards have a bug in their transmitter control table */ -if ((rdev->family !=CHIP_RV710 ) || (rdev->family !=CHIP_RV730 )) +if ((rdev->family !=CHIP_RV710 ) && (rdev->family !=CHIP_RV730 ))atombios_dig_transmitter_setup (encoder,ATOM_TRANSMITTER_ACTION_ENABLE_OUTPUT ,0 ,0 ); }if (ENCODER_MODE_IS_DP (atombios_get_encoder_mode (encoder)) && connector) {
Greg Kroah-Hartman
maintainerPATCH 28/171 ttm: Clear the ttm page allocated from high memory zone correctly
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Zhao Yakui <[email protected]>
commit ac207ed2471150e06af0afc76e4becc701fa2733 upstream.
The TTM page can be allocated from high memory. In such case it is wrong to use the page_address(page) as the virtual address for the high memory page.
bugzilla: https://bugzilla.kernel.org/show_bug.cgi?id=50241
---
 drivers/gpu/drm/ttm/ttm_page_alloc.c |    5 ++++-
 1 file changed, 4 insertions(+), 1 deletion(-)
drivers/gpu/drm/ttm/ttm_page_alloc.c +4 -1
@@ -749,7 +749,10 @@ static int ttm_get_pages(struct page **p/* clear the pages coming from the pool if requested */ if (flags &TTM_PAGE_FLAG_ZERO_ALLOC ) {list_for_each_entry (p, &plist, lru) { -clear_page (page_address (p)); +if (PageHighMem (p)) +clear_highpage (p); +else +clear_page (page_address (p)); } }
Greg Kroah-Hartman
maintainerPATCH 29/171 memcg: oom: fix totalpages calculation for memory.swappiness==0
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Michal Hocko <[email protected]>
commit 9a5a8f19b43430752067ecaee62fc59e11e88fa6 upstream.
oom_badness() takes a totalpages argument which says how many pages are available and it uses it as a base for the score calculation. The value is calculated by mem_cgroup_get_limit which considers both limit and total_swap_pages (resp. memsw portion of it).
This is usually correct but since fe35004fbf9e ("mm: avoid swapping out with swappiness==0") we do not swap when swappiness is 0 which means that we cannot really use up all the totalpages pages. This in turn confuses oom score calculation if the memcg limit is much smaller than the available swap because the used memory (capped by the limit) is negligible comparing to totalpages so the resulting score is too small if adj!=0 (typically task with CAP_SYS_ADMIN or non zero oom_score_adj). A wrong process might be selected as result.
The problem can be worked around by checking mem_cgroup_swappiness==0 and not considering swap at all in such a case.
---
 Documentation/cgroups/memory.txt |    4 ++++
 mm/memcontrol.c                  |   21 +++++++++++++++------
 2 files changed, 19 insertions(+), 6 deletions(-)
Documentation/cgroups/memory.txt +4 -0
@@ -466,6 +466,10 @@ Note:
 5.3 swappiness

 Similar to /proc/sys/vm/swappiness, but affecting a hierarchy of groups only.
+Please note that unlike the global swappiness, memcg knob set to 0
+really prevents from any swapping even if there is a swap storage
+available. This might lead to memcg OOM killer if there are no file
+pages to reclaim.

 Following cgroups' swappiness can't be changed.
 - root cgroup (uses /proc/sys/vm/swappiness).
mm/memcontrol.c +15 -6
@@ -1489,17 +1489,26 @@ static int mem_cgroup_count_children(stru64 mem_cgroup_get_limit (struct mem_cgroup *memcg) {u64 limit; -u64 memsw; limit =res_counter_read_u64 (&memcg->res,RES_LIMIT ); - limit += total_swap_pages <<PAGE_SHIFT ; - memsw =res_counter_read_u64 (&memcg->memsw,RES_LIMIT );/* -* If memsw is finite and limits the amount of swap space available -* to this memcg, return that limit. +* Do not consider swap space if we cannot swap due to swappiness */ -return min (limit, memsw); +if (mem_cgroup_swappiness (memcg)) { +u64 memsw; + + limit += total_swap_pages <<PAGE_SHIFT ; + memsw =res_counter_read_u64 (&memcg->memsw,RES_LIMIT ); + +/* +* If memsw is finite and limits the amount of swap space +* available to this memcg, return that limit. +*/ + limit =min (limit, memsw); + } + +return limit; } static unsigned long mem_cgroup_reclaim(struct mem_cgroup *memcg,
Greg Kroah-Hartman
maintainerPATCH 30/171 wireless: allow 40 MHz on world roaming channels 12/13
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Johannes Berg <[email protected]>
commit 43c771a1963ab461a2f194e3c97fded1d5fe262f upstream.
When in world roaming mode, allow 40 MHz to be used on channels 12 and 13 so that an AP that is, e.g., using HT40+ on channel 9 (in the UK) can be used.
---
 net/wireless/reg.c |    5 ++---
 1 file changed, 2 insertions(+), 3 deletions(-)
net/wireless/reg.c +2 -3
@@ -134,9 +134,8 @@ static const struct ieee80211_regdomain .reg_rules = {/* IEEE 802.11b/g, channels 1..11 */ REG_RULE (2412 -10 ,2462 +10 ,40 ,6 ,20 ,0 ), -/* IEEE 802.11b/g, channels 12..13. No HT40 -* channel fits here. */ -REG_RULE (2467 -10 ,2472 +10 ,20 ,6 ,20 , +/* IEEE 802.11b/g, channels 12..13. */ +REG_RULE (2467 -10 ,2472 +10 ,40 ,6 ,20 ,NL80211_RRF_PASSIVE_SCAN | NL80211_RRF_NO_IBSS),/* IEEE 802.11 channel 14 - Only JP enables
Greg Kroah-Hartman
maintainerPATCH 31/171 m68k: fix sigset_t accessor functions
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Andreas Schwab <[email protected]>
commit 34fa78b59c52d1db3513db4c1a999db26b2e9ac2 upstream.
The sigaddset/sigdelset/sigismember functions that are implemented with bitfield insn cannot allow the sigset argument to be placed in a data register since the sigset is wider than 32 bits. Remove the "d" constraint from the asm statements.
The effect of the bug is that sending RT signals does not work, the signal number is truncated modulo 32.
---
 arch/m68k/include/asm/signal.h |    6 +++---
 1 file changed, 3 insertions(+), 3 deletions(-)
arch/m68k/include/asm/signal.h +3 -3
@@ -156,7 +156,7 @@ typedef struct sigaltstack {static inline void sigaddset (sigset_t *set,int _sig) { asm ("bfset %0{%1,#1}" - :"+od" (*set) + :"+o" (*set) :"id" ((_sig -1 ) ^31 ) :"cc" ); }
@@ -164,7 +164,7 @@ static inline void sigaddset(sigset_t *sstatic inline void sigdelset (sigset_t *set,int _sig) { asm ("bfclr %0{%1,#1}" - :"+od" (*set) + :"+o" (*set) :"id" ((_sig -1 ) ^31 ) :"cc" ); }
@@ -180,7 +180,7 @@ static inline int __gen_sigismember(sigsint ret; asm ("bfextu %1{%2,#1},%0" :"=d" (ret) - :"od" (*set),"id" ((_sig-1 ) ^31 ) + :"o" (*set),"id" ((_sig-1 ) ^31 ) :"cc" );return ret; }
Greg Kroah-Hartman
maintainerPATCH 32/171 ipv4: avoid undefined behavior in do_ip_setsockopt()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Xi Wang <[email protected]>
[ Upstream commit 0c9f79be295c99ac7e4b569ca493d75fdcc19e4e ]
(1<<optname) is undefined behavior in C with a negative optname or optname larger than 31. In those cases the result of the shift is not necessarily zero (e.g., on x86).
This patch simplifies the code with a switch statement on optname. It also allows the compiler to generate better code (e.g., using a 64-bit mask).
---
 net/ipv4/ip_sockglue.c |   35 ++++++++++++++++++++++-------------
 1 file changed, 22 insertions(+), 13 deletions(-)
net/ipv4/ip_sockglue.c +22 -13
@@ -456,19 +456,28 @@ static int do_ip_setsockopt(struct sockstruct inet_sock *inet =inet_sk (sk);int val =0 , err; -if (((1 <<optname) & ((1 <<IP_PKTINFO ) | (1 <<IP_RECVTTL ) | - (1 <<IP_RECVOPTS ) | (1 <<IP_RECVTOS ) | - (1 <<IP_RETOPTS ) | (1 <<IP_TOS ) | - (1 <<IP_TTL ) | (1 <<IP_HDRINCL ) | - (1 <<IP_MTU_DISCOVER ) | (1 <<IP_RECVERR ) | - (1 <<IP_ROUTER_ALERT ) | (1 <<IP_FREEBIND ) | - (1 <<IP_PASSSEC ) | (1 <<IP_TRANSPARENT ) | - (1 <<IP_MINTTL ) | (1 <<IP_NODEFRAG ))) || - optname ==IP_UNICAST_IF || - optname ==IP_MULTICAST_TTL || - optname ==IP_MULTICAST_ALL || - optname ==IP_MULTICAST_LOOP || - optname ==IP_RECVORIGDSTADDR ) { +switch (optname) { +case IP_PKTINFO : +case IP_RECVTTL : +case IP_RECVOPTS : +case IP_RECVTOS : +case IP_RETOPTS : +case IP_TOS : +case IP_TTL : +case IP_HDRINCL : +case IP_MTU_DISCOVER : +case IP_RECVERR : +case IP_ROUTER_ALERT : +case IP_FREEBIND : +case IP_PASSSEC : +case IP_TRANSPARENT : +case IP_MINTTL : +case IP_NODEFRAG : +case IP_UNICAST_IF : +case IP_MULTICAST_TTL : +case IP_MULTICAST_ALL : +case IP_MULTICAST_LOOP : +case IP_RECVORIGDSTADDR :if (optlen >=sizeof (int )) {if (get_user (val, (int __user *) optval))return -EFAULT ;
Greg Kroah-Hartman
maintainerPATCH 33/171 ipv6: setsockopt(IPIPPROTO_IPV6, IPV6_MINHOPCOUNT) forgot to set return value
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Hannes Frederic Sowa <[email protected]>
[ Upstream commit d4596bad2a713fcd0def492b1960e6d899d5baa8 ]
---
 net/ipv6/ipv6_sockglue.c |    1 +
 1 file changed, 1 insertion(+)
net/ipv6/ipv6_sockglue.c +1 -0
@@ -828,6 +828,7 @@ pref_skip_coa:if (val <0 || val >255 ) goto e_inval; np->min_hopcount = val; + retv =0 ;break ;case IPV6_DONTFRAG : np->dontfrag = valbool;
Greg Kroah-Hartman
maintainerPATCH 34/171 net: correct check in dev_addr_del()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jiri Pirko <[email protected]>
[ Upstream commit a652208e0b52c190e57f2a075ffb5e897fe31c3b ]
Check (ha->addr == dev->dev_addr) is always true because dev_addr_init() sets this. Correct the check to behave properly on addr removal.
---
 net/core/dev_addr_lists.c |    3 ++-
 1 file changed, 2 insertions(+), 1 deletion(-)
net/core/dev_addr_lists.c +2 -1
@@ -308,7 +308,8 @@ int dev_addr_del(struct net_device *dev,*/ ha =list_first_entry (&dev->dev_addrs.list, struct netdev_hw_addr, list); -if (ha->addr == dev->dev_addr && ha->refcount ==1 ) +if (!memcmp (ha->addr, addr, dev->addr_len) && + ha->type == addr_type && ha->refcount ==1 )return -ENOENT ; err = __hw_addr_del(&dev->dev_addrs, addr, dev->addr_len,
Greg Kroah-Hartman
maintainerPATCH 35/171 net-rps: Fix brokeness causing OOO packets
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Tom Herbert <[email protected]>
[ Upstream commit baefa31db2f2b13a05d1b81bdf2d20d487f58b0a ]
In commit c445477d74ab3779 which adds aRFS to the kernel, the CPU selected for RFS is not set correctly when CPU is changing. This is causing OOO packets and probably other issues.
---
 net/core/dev.c |    4 +++-
 1 file changed, 3 insertions(+), 1 deletion(-)
net/core/dev.c +3 -1
@@ -2763,8 +2763,10 @@ static int get_rps_cpu(struct net_deviceif (unlikely (tcpu != next_cpu) && (tcpu ==RPS_NO_CPU || !cpu_online (tcpu) || ((int )(per_cpu (softnet_data, tcpu).input_queue_head - - rflow->last_qtail)) >=0 )) + rflow->last_qtail)) >=0 )) { + tcpu = next_cpu; rflow =set_rps_cpu (dev, skb, rflow, next_cpu); + }if (tcpu !=RPS_NO_CPU &&cpu_online (tcpu)) { *rflowp = rflow;
Greg Kroah-Hartman
maintainerPATCH 36/171 tmpfs: change final i_blocks BUG to WARNING
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Hugh Dickins <[email protected]>
commit 0f3c42f522dc1ad7e27affc0a4aa8c790bce0a66 upstream.
Under a particular load on one machine, I have hit shmem_evict_inode()'s BUG_ON(inode->i_blocks), enough times to narrow it down to a particular race between swapout and eviction.
It comes from the "if (freed > 0)" asymmetry in shmem_recalc_inode(), and the lack of coherent locking between mapping's nrpages and shmem's swapped count. There's a window in shmem_writepage(), between lowering nrpages in shmem_delete_from_page_cache() and then raising swapped count, when the freed count appears to be +1 when it should be 0, and then the asymmetry stops it from being corrected with -1 before hitting the BUG.
One answer is coherent locking: using tree_lock throughout, without info->lock; reasonable, but the raw_spin_lock in percpu_counter_add() on used_blocks makes that messier than expected. Another answer may be a further effort to eliminate the weird shmem_recalc_inode() altogether, but previous attempts at that failed.
So far undecided, but for now change the BUG_ON to WARN_ON: in usual circumstances it remains a useful consistency check.
---
 mm/shmem.c |    2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
mm/shmem.c +1 -1
@@ -595,7 +595,7 @@ static void shmem_evict_inode(struct inokfree (xattr->name);kfree (xattr); } -BUG_ON (inode->i_blocks); +WARN_ON (inode->i_blocks);shmem_free_inode (inode->i_sb);end_writeback (inode); }
Greg Kroah-Hartman
maintainerPATCH 37/171 r8169: use unlimited DMA burst for TX
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Michal Schmidt <[email protected]>
commit aee77e4accbeb2c86b1d294cd84fec4a12dde3bd upstream.
The r8169 driver currently limits the DMA burst for TX to 1024 bytes. I have a box where this prevents the interface from using the gigabit line to its full potential. This patch solves the problem by setting TX_DMA_BURST to unlimited.
The box has an ASRock B75M motherboard with on-board RTL8168evl/8111evl (XID 0c900880). TSO is enabled.
I used netperf (TCP_STREAM test) to measure the dependency of TX throughput on MTU. I did it for three different values of TX_DMA_BURST ('5'=512, '6'=1024, '7'=unlimited). This chart shows the results:
http://michich.fedorapeople.org/r8169/r8169-effects-of-TX_DMA_BURST.png
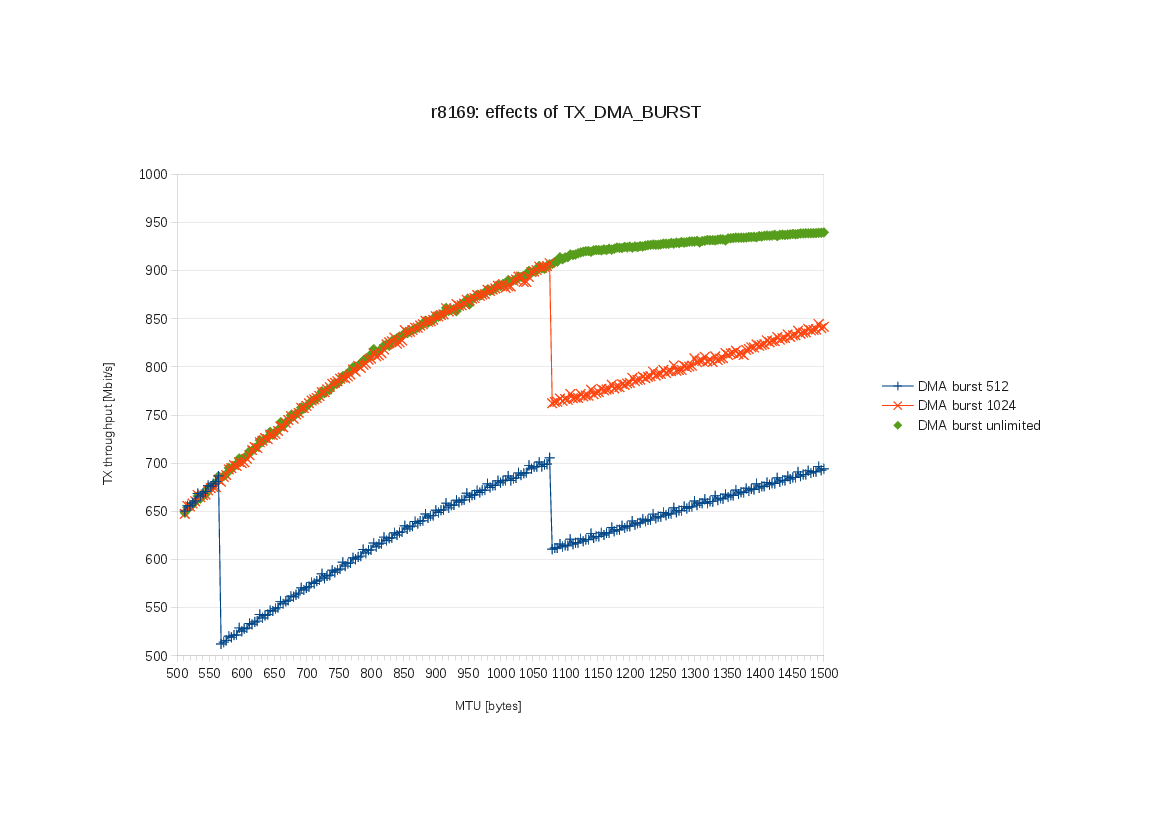
Interesting points:
- With the current DMA burst limit (1024):
- at the default MTU=1500 I get only 842 Mbit/s.
- when going from small MTU, the performance rises monotonically with increasing MTU only up to a peak at MTU=1076 (908 MBit/s). Then there's a sudden drop to 762 MBit/s from which the throughput rises monotonically again with further MTU increases.
- With a smaller DMA burst limit (512):
- there's a similar peak at MTU=1076 and another one at MTU=564.
- With unlimited DMA burst:
- at the default MTU=1500 I get nice 940 Mbit/s.
- the throughput rises monotonically with increasing MTU with no strange peaks.
Notice that the peaks occur at MTU sizes that are multiples of the DMA burst limit plus 52. Why 52? Because:
20 (IP header) + 20 (TCP header) + 12 (TCP options) = 52
The Realtek-provided r8168 driver (v8.032.00) uses unlimited TX DMA burst too, except for CFG_METHOD_1 where the TX DMA burst is set to 512 bytes. CFG_METHOD_1 appears to be the oldest MAC version of "RTL8168B/8111B", i.e. RTL_GIGA_MAC_VER_11 in r8169. Not sure if this MAC version really needs the smaller burst limit, or if any other versions have similar requirements.
---
 drivers/net/ethernet/realtek/r8169.c |    2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/net/ethernet/realtek/r8169.c +1 -1
@@ -73,7 +73,7 @@static const int multicast_filter_limit =32 ;#define MAX_READ_REQUEST_SHIFT 12 -#define TX_DMA_BURST 6/* Maximum PCI burst, '6' is 1024 */ +#define TX_DMA_BURST 7/* Maximum PCI burst, '7' is unlimited */ #define SafeMtu 0x1c20/* ... actually life sucks beyond ~7k */ #define InterFrameGap 0x03/* 3 means InterFrameGap = the shortest one */
Greg Kroah-Hartman
maintainerPATCH 38/171 xen/events: fix RCU warning, or Call idle notifier after irq_enter()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Mojiong Qiu <[email protected]>
commit 772aebcefeff310f80e32b874988af0076cb799d upstream.
exit_idle() should be called after irq_enter(), otherwise it throws:
[ INFO: suspicious RCU usage. ]
3.6.5 #1 Not tainted
-------------------------------include/linux/rcupdate.h:725 rcu_read_lock() used illegally while idle!
other info that might help us debug this:
RCU used illegally from idle CPU!rcu_scheduler_active = 1, debug_locks = 1
RCU used illegally from extended quiescent state!
1 lock held by swapper/0/0:
#0: (rcu_read_lock){......}, at: [<ffffffff810e9fe0>] __atomic_notifier_call_chain+0x0/0x140
stack backtrace:
Pid: 0, comm: swapper/0 Not tainted 3.6.5 #1
Call Trace:
 <IRQ>  [<ffffffff811259a2>] lockdep_rcu_suspicious+0xe2/0x130
 [<ffffffff810ea10c>] __atomic_notifier_call_chain+0x12c/0x140
 [<ffffffff810e9fe0>] ? atomic_notifier_chain_unregister+0x90/0x90
 [<ffffffff811216cd>] ? trace_hardirqs_off+0xd/0x10
 [<ffffffff810ea136>] atomic_notifier_call_chain+0x16/0x20
 [<ffffffff810777c3>] exit_idle+0x43/0x50
 [<ffffffff81568865>] xen_evtchn_do_upcall+0x25/0x50
 [<ffffffff81aa690e>] xen_do_hypervisor_callback+0x1e/0x30
 <EOI>  [<ffffffff810013aa>] ? hypercall_page+0x3aa/0x1000
 [<ffffffff810013aa>] ? hypercall_page+0x3aa/0x1000
 [<ffffffff81061540>] ? xen_safe_halt+0x10/0x20
 [<ffffffff81075cfa>] ? default_idle+0xba/0x570
 [<ffffffff810778af>] ? cpu_idle+0xdf/0x140
 [<ffffffff81a4d881>] ? rest_init+0x135/0x144
 [<ffffffff81a4d74c>] ? csum_partial_copy_generic+0x16c/0x16c
 [<ffffffff82520c45>] ? start_kernel+0x3db/0x3e8
 [<ffffffff8252066a>] ? repair_env_string+0x5a/0x5a
 [<ffffffff82520356>] ? x86_64_start_reservations+0x131/0x135
 [<ffffffff82524aca>] ? xen_start_kernel+0x465/0x46
Git commit 98ad1cc14a5c4fd658f9d72c6ba5c86dfd3ce0d5
Author: Frederic Weisbecker <[email protected]>
Date:   Fri Oct 7 18:22:09 2011 +0200
x86: Call idle notifier after irq_enter()
did this, but it missed the Xen code.
---
 drivers/xen/events.c |    2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/xen/events.c +1 -1
@@ -1365,8 +1365,8 @@ void xen_evtchn_do_upcall(struct pt_regs {struct pt_regs *old_regs =set_irq_regs (regs); -exit_idle ();irq_enter (); +exit_idle ();__xen_evtchn_do_upcall ();
Greg Kroah-Hartman
maintainerPATCH 39/171 r8169: Fix WoL on RTL8168d/8111d.
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Cyril Brulebois <[email protected]>
commit b00e69dee4ccbb3a19989e3d4f1385bc2e3406cd upstream.
This regression was spotted between Debian squeeze and Debian wheezy kernels (respectively based on 2.6.32 and 3.2). More info about Wake-on-LAN issues with Realtek's 816x chipsets can be found in the following thread: http://marc.info/?t=132079219400004
Probable regression from d4ed95d796e5126bba51466dc07e287cebc8bd19; more chipsets are likely affected.
Tested on top of a 3.2.23 kernel.
---
 drivers/net/ethernet/realtek/r8169.c |    2 ++
 1 file changed, 2 insertions(+)
drivers/net/ethernet/realtek/r8169.c +2 -0
@@ -3488,6 +3488,8 @@ static void rtl_wol_suspend_quirk(structvoid __iomem *ioaddr = tp->mmio_addr;switch (tp->mac_version) { +case RTL_GIGA_MAC_VER_25 : +case RTL_GIGA_MAC_VER_26 :case RTL_GIGA_MAC_VER_29 :case RTL_GIGA_MAC_VER_30 :case RTL_GIGA_MAC_VER_32 :
Greg Kroah-Hartman
maintainerPATCH 40/171 r8169: allow multicast packets on sub-8168f chipset.
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Nathan Walp <[email protected]>
commit 0481776b7a70f09acf7d9d97c288c3a8403fbfe4 upstream.
RTL_GIGA_MAC_VER_35 includes no multicast hardware filter.
---
 drivers/net/ethernet/realtek/r8169.c |    3 +++
 1 file changed, 3 insertions(+)
drivers/net/ethernet/realtek/r8169.c +3 -0
@@ -4131,6 +4131,9 @@ static void rtl_set_rx_mode(struct net_d mc_filter[1 ] =swab32 (data); } +if (tp->mac_version ==RTL_GIGA_MAC_VER_35 ) + mc_filter[1 ] = mc_filter[0 ] =0xffffffff ; +RTL_W32 (MAR0 +4 , mc_filter[1 ]);RTL_W32 (MAR0 +0 , mc_filter[0 ]);
Greg Kroah-Hartman
maintainerPATCH 41/171 netfilter: Validate the sequence number of dataless ACK packets as well
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jozsef Kadlecsik <[email protected]>
commit 4a70bbfaef0361d27272629d1a250a937edcafe4 upstream.
We spare nothing by not validating the sequence number of dataless ACK packets and enabling it makes harder off-path attacks.
See: "Reflection scan: an Off-Path Attack on TCP" by Jan Wrobel,
http://arxiv.org/abs/1201.2074
---
 net/netfilter/nf_conntrack_proto_tcp.c |   10 ++--------
 1 file changed, 2 insertions(+), 8 deletions(-)
net/netfilter/nf_conntrack_proto_tcp.c +2 -8
@@ -627,15 +627,9 @@ static bool tcp_in_window(const struct n ack = sack = receiver->td_end; } -if (seq == end - && (!tcph->rst - || (seq ==0 && state->state ==TCP_CONNTRACK_SYN_SENT ))) +if (tcph->rst && seq ==0 && state->state ==TCP_CONNTRACK_SYN_SENT )/* -* Packets contains no data: we assume it is valid -* and check the ack value only. -* However RST segments are always validated by their -* SEQ number, except when seq == 0 (reset sent answering -* SYN. +* RST sent answering SYN. */ seq = end = sender->td_end;
Greg Kroah-Hartman
maintainerPATCH 42/171 netfilter: Mark SYN/ACK packets as invalid from original direction
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jozsef Kadlecsik <[email protected]>
commit 64f509ce71b08d037998e93dd51180c19b2f464c upstream.
Clients should not send such packets. By accepting them, we open up a hole by wich ephemeral ports can be discovered in an off-path attack.
See: "Reflection scan: an Off-Path Attack on TCP" by Jan Wrobel,
http://arxiv.org/abs/1201.2074
---
 net/netfilter/nf_conntrack_proto_tcp.c |   19 ++++++++-----------
 1 file changed, 8 insertions(+), 11 deletions(-)
net/netfilter/nf_conntrack_proto_tcp.c +8 -11
@@ -158,21 +158,18 @@ static const u8 tcp_conntracks[2][6][TCP* sCL -> sSS */ /* sNO, sSS, sSR, sES, sFW, sCW, sLA, sTW, sCL, sS2 */ -/*synack*/ { sIV, sIV, sIG, sIG, sIG, sIG, sIG, sIG, sIG, sSR }, +/*synack*/ { sIV, sIV, sSR, sIV, sIV, sIV, sIV, sIV, sIV, sSR },/* * sNO -> sIV Too late and no reason to do anything * sSS -> sIV Client can't send SYN and then SYN/ACK * sS2 -> sSR SYN/ACK sent to SYN2 in simultaneous open -* sSR -> sIG -* sES -> sIG Error: SYNs in window outside the SYN_SENT state -* are errors. Receiver will reply with RST -* and close the connection. -* Or we are not in sync and hold a dead connection. -* sFW -> sIG -* sCW -> sIG -* sLA -> sIG -* sTW -> sIG -* sCL -> sIG +* sSR -> sSR Late retransmitted SYN/ACK in simultaneous open +* sES -> sIV Invalid SYN/ACK packets sent by the client +* sFW -> sIV +* sCW -> sIV +* sLA -> sIV +* sTW -> sIV +* sCL -> sIV */ /* sNO, sSS, sSR, sES, sFW, sCW, sLA, sTW, sCL, sS2 */ /*fin*/ { sIV, sIV, sFW, sFW, sLA, sLA, sLA, sTW, sCL, sIV },
Greg Kroah-Hartman
maintainerPATCH 43/171 netfilter: nf_nat: dont check for port change on ICMP tuples
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Ulrich Weber <[email protected]>
commit 38fe36a248ec3228f8e6507955d7ceb0432d2000 upstream.
ICMP tuples have id in src and type/code in dst. So comparing src.u.all with dst.u.all will always fail here and ip_xfrm_me_harder() is called for every ICMP packet, even if there was no NAT.
---
 net/ipv4/netfilter/nf_nat_standalone.c |    6 ++++--
 1 file changed, 4 insertions(+), 2 deletions(-)
net/ipv4/netfilter/nf_nat_standalone.c +4 -2
@@ -194,7 +194,8 @@ nf_nat_out(unsigned int hooknum,if ((ct->tuplehash[dir].tuple.src.u3.ip != ct->tuplehash[!dir].tuple.dst.u3.ip) || - (ct->tuplehash[dir].tuple.src.u.all != + (ct->tuplehash[dir].tuple.dst.protonum !=IPPROTO_ICMP && + ct->tuplehash[dir].tuple.src.u.all != ct->tuplehash[!dir].tuple.dst.u.all) )return ip_xfrm_me_harder (skb) ==0 ? ret :NF_DROP ;
@@ -230,7 +231,8 @@ nf_nat_local_fn(unsigned int hooknum, ret =NF_DROP ; }#ifdef CONFIG_XFRM - else if (ct->tuplehash[dir].tuple.dst.u.all != + else if (ct->tuplehash[dir].tuple.dst.protonum != IPPROTO_ICMP && + ct->tuplehash[dir].tuple.dst.u.all != ct->tuplehash[!dir].tuple.src.u.all) if (ip_xfrm_me_harder(skb)) ret =NF_DROP ;
Greg Kroah-Hartman
maintainerPATCH 44/171 usb: use usb_serial_put in usb_serial_probe errors
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jan Safrata <[email protected]>
commit 0658a3366db7e27fa32c12e886230bb58c414c92 upstream.
The use of kfree(serial) in error cases of usb_serial_probe was invalid - usb_serial structure allocated in create_serial() gets reference of usb_device that needs to be put, so we need to use usb_serial_put() instead of simple kfree().
---
 drivers/usb/serial/usb-serial.c |    6 +++---
 1 file changed, 3 insertions(+), 3 deletions(-)
drivers/usb/serial/usb-serial.c +3 -3
@@ -768,7 +768,7 @@ int usb_serial_probe(struct usb_interfacif (retval) {dbg ("sub driver rejected device" ); -kfree (serial); +usb_serial_put (serial);module_put (type->driver.owner);return retval; }
@@ -840,7 +840,7 @@ int usb_serial_probe(struct usb_interfac*/ if (num_bulk_in ==0 || num_bulk_out ==0 ) {dev_info (&interface->dev,"PL-2303 hack: descriptors matched but endpoints did not\n" ); -kfree (serial); +usb_serial_put (serial);module_put (type->driver.owner);return -ENODEV ; }
@@ -854,7 +854,7 @@ int usb_serial_probe(struct usb_interfacif (num_ports ==0 ) {dev_err (&interface->dev,"Generic device with no bulk out, not allowed.\n" ); -kfree (serial); +usb_serial_put (serial);module_put (type->driver.owner);return -EIO ; }
Greg Kroah-Hartman
maintainerPATCH 45/171 eCryptfs: Copy up POSIX ACL and read-only flags from lower mount
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Tyler Hicks <[email protected]>
commit 069ddcda37b2cf5bb4b6031a944c0e9359213262 upstream.
When the eCryptfs mount options do not include '-o acl', but the lower filesystem's mount options do include 'acl', the MS_POSIXACL flag is not flipped on in the eCryptfs super block flags. This flag is what the VFS checks in do_last() when deciding if the current umask should be applied to a newly created inode's mode or not. When a default POSIX ACL mask is set on a directory, the current umask is incorrectly applied to new inodes created in the directory. This patch ignores the MS_POSIXACL flag passed into ecryptfs_mount() and sets the flag on the eCryptfs super block depending on the flag's presence on the lower super block.
Additionally, it is incorrect to allow a writeable eCryptfs mount on top of a read-only lower mount. This missing check did not allow writes to the read-only lower mount because permissions checks are still performed on the lower filesystem's objects but it is best to simply not allow a rw mount on top of ro mount. However, a ro eCryptfs mount on top of a rw mount is valid and still allowed.
https://launchpad.net/bugs/1009207
---
 fs/ecryptfs/main.c |   10 +++++++++-
 1 file changed, 9 insertions(+), 1 deletion(-)
fs/ecryptfs/main.c +9 -1
@@ -506,7 +506,6 @@ static struct dentry *ecryptfs_mount(str goto out; } - s->s_flags = flags; rc =bdi_setup_and_register (&sbi->bdi,"ecryptfs" ,BDI_CAP_MAP_COPY );if (rc) goto out1;
@@ -542,6 +541,15 @@ static struct dentry *ecryptfs_mount(str }ecryptfs_set_superblock_lower (s, path.dentry->d_sb); + +/** +* Set the POSIX ACL flag based on whether they're enabled in the lower +* mount. Force a read-only eCryptfs mount if the lower mount is ro. +* Allow a ro eCryptfs mount even when the lower mount is rw. +*/ + s->s_flags = flags & ~MS_POSIXACL ; + s->s_flags |= path.dentry->d_sb->s_flags & (MS_RDONLY |MS_POSIXACL ); + s->s_maxbytes = path.dentry->d_sb->s_maxbytes; s->s_blocksize = path.dentry->d_sb->s_blocksize; s->s_magic =ECRYPTFS_SUPER_MAGIC ;
Greg Kroah-Hartman
maintainerPATCH 46/171 eCryptfs: check for eCryptfs cipher support at mount
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Tim Sally <[email protected]>
commit 5f5b331d5c21228a6519dcb793fc1629646c51a6 upstream.
The issue occurs when eCryptfs is mounted with a cipher supported by the crypto subsystem but not by eCryptfs. The mount succeeds and an error does not occur until a write. This change checks for eCryptfs cipher support at mount time.
Resolves Launchpad issue #338914, reported by Tyler Hicks in 03/2009.
https://bugs.launchpad.net/ecryptfs/+bug/338914
---
 fs/ecryptfs/main.c |   13 +++++++++++++
 1 file changed, 13 insertions(+)
fs/ecryptfs/main.c +13 -0
@@ -280,6 +280,7 @@ static int ecryptfs_parse_options(structchar *fnek_src;char *cipher_key_bytes_src;char *fn_cipher_key_bytes_src; +u8 cipher_code; *check_ruid =0 ;
@@ -421,6 +422,18 @@ static int ecryptfs_parse_options(struct && !fn_cipher_key_bytes_set) mount_crypt_stat->global_default_fn_cipher_key_bytes = mount_crypt_stat->global_default_cipher_key_size; + + cipher_code =ecryptfs_code_for_cipher_string ( + mount_crypt_stat->global_default_cipher_name, + mount_crypt_stat->global_default_cipher_key_size); +if (!cipher_code) { +ecryptfs_printk (KERN_ERR , +"eCryptfs doesn't support cipher: %s" , + mount_crypt_stat->global_default_cipher_name); + rc = -EINVAL ; + goto out; + } +mutex_lock (&key_tfm_list_mutex);if (!ecryptfs_tfm_exists (mount_crypt_stat->global_default_cipher_name,NULL )) {
Greg Kroah-Hartman
maintainerPATCH 47/171 sky2: Fix for interrupt handler
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Mirko Lindner <[email protected]>
commit d663d181b9e92d80c2455e460e932d34e7a2a7ae upstream.
Re-enable interrupts if it is not our interrupt
---
 drivers/net/ethernet/marvell/sky2.c |    4 +++-
 1 file changed, 3 insertions(+), 1 deletion(-)
drivers/net/ethernet/marvell/sky2.c +3 -1
@@ -3079,8 +3079,10 @@ static irqreturn_t sky2_intr(int irq, vo/* Reading this mask interrupts as side effect */ status =sky2_read32 (hw,B0_Y2_SP_ISRC2 ); -if (status ==0 || status == ~0 ) +if (status ==0 || status == ~0 ) { +sky2_write32 (hw,B0_Y2_SP_ICR ,2 );return IRQ_NONE ; + }prefetch (&hw->st_le[hw->st_idx]);
Greg Kroah-Hartman
maintainerPATCH 48/171 s390/signal: set correct address space control
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Martin Schwidefsky <[email protected]>
commit fa968ee215c0ca91e4a9c3a69ac2405aae6e5d2f upstream.
If user space is running in primary mode it can switch to secondary or access register mode, this is used e.g. in the clock_gettime code of the vdso. If a signal is delivered to the user space process while it has been running in access register mode the signal handler is executed in access register mode as well which will result in a crash most of the time.
Set the address space control bits in the PSW to the default for the execution of the signal handler and make sure that the previous address space control is restored on signal return. Take care that user space can not switch to the kernel address space by modifying the registers in the signal frame.
---
 arch/s390/include/asm/compat.h   |    2 +-
 arch/s390/include/asm/ptrace.h   |    4 ++--
 arch/s390/kernel/compat_signal.c |   14 ++++++++++++--
 arch/s390/kernel/signal.c        |   14 ++++++++++++--
 4 files changed, 27 insertions(+), 7 deletions(-)
arch/s390/include/asm/compat.h +1 -1
@@ -20,7 +20,7 @@#define PSW32_MASK_CC 0x00003000UL#define PSW32_MASK_PM 0x00000f00UL -#define PSW32_MASK_USER 0x00003F00UL +#define PSW32_MASK_USER 0x0000FF00UL#define PSW32_ADDR_AMODE 0x80000000UL#define PSW32_ADDR_INSN 0x7FFFFFFFUL
arch/s390/include/asm/ptrace.h +2 -2
@@ -240,7 +240,7 @@ typedef struct#define PSW_MASK_EA 0x00000000UL#define PSW_MASK_BA 0x00000000UL -#define PSW_MASK_USER 0x00003F00UL +#define PSW_MASK_USER 0x0000FF00UL#define PSW_ADDR_AMODE 0x80000000UL#define PSW_ADDR_INSN 0x7FFFFFFFUL
@@ -269,7 +269,7 @@ typedef struct#define PSW_MASK_EA 0x0000000100000000UL#define PSW_MASK_BA 0x0000000080000000UL -#define PSW_MASK_USER 0x00003F0180000000UL +#define PSW_MASK_USER 0x0000FF0180000000UL#define PSW_ADDR_AMODE 0x0000000000000000UL#define PSW_ADDR_INSN 0xFFFFFFFFFFFFFFFFUL
arch/s390/kernel/compat_signal.c +12 -2
@@ -313,6 +313,10 @@ static int restore_sigregs32(struct pt_r regs->psw.mask = (regs->psw.mask & ~PSW_MASK_USER ) | (__u64)(regs32.psw.mask &PSW32_MASK_USER ) <<32 | (__u64)(regs32.psw.addr &PSW32_ADDR_AMODE ); +/* Check for invalid user address space control. */ +if ((regs->psw.mask &PSW_MASK_ASC ) >= (psw_kernel_bits &PSW_MASK_ASC )) + regs->psw.mask = (psw_user_bits &PSW_MASK_ASC ) | + (regs->psw.mask & ~PSW_MASK_ASC ); regs->psw.addr = (__u64)(regs32.psw.addr &PSW32_ADDR_INSN );for (i =0 ; i <NUM_GPRS ; i++) regs->gprs[i] = (__u64 ) regs32.gprs[i];
@@ -494,7 +498,10 @@ static int setup_frame32(int sig, struct/* Set up registers for signal handler */ regs->gprs[15 ] = (__force __u64 ) frame; - regs->psw.mask |=PSW_MASK_BA ;/* force amode 31 */ +/* Force 31 bit amode and default user address space control. */ + regs->psw.mask =PSW_MASK_BA | + (psw_user_bits &PSW_MASK_ASC ) | + (regs->psw.mask & ~PSW_MASK_ASC ); regs->psw.addr = (__force __u64 ) ka->sa.sa_handler; regs->gprs[2 ] =map_signal (sig);
@@ -562,7 +569,10 @@ static int setup_rt_frame32(int sig, str/* Set up registers for signal handler */ regs->gprs[15 ] = (__force __u64 ) frame; - regs->psw.mask |=PSW_MASK_BA ;/* force amode 31 */ +/* Force 31 bit amode and default user address space control. */ + regs->psw.mask =PSW_MASK_BA | + (psw_user_bits &PSW_MASK_ASC ) | + (regs->psw.mask & ~PSW_MASK_ASC ); regs->psw.addr = (__u64 ) ka->sa.sa_handler; regs->gprs[2 ] =map_signal (sig);
arch/s390/kernel/signal.c +12 -2
@@ -148,6 +148,10 @@ static int restore_sigregs(struct pt_reg/* Use regs->psw.mask instead of psw_user_bits to preserve PER bit. */ regs->psw.mask = (regs->psw.mask & ~PSW_MASK_USER ) | (user_sregs.regs.psw.mask &PSW_MASK_USER ); +/* Check for invalid user address space control. */ +if ((regs->psw.mask &PSW_MASK_ASC ) >= (psw_kernel_bits &PSW_MASK_ASC )) + regs->psw.mask = (psw_user_bits &PSW_MASK_ASC ) | + (regs->psw.mask & ~PSW_MASK_ASC );/* Check for invalid amode */ if (regs->psw.mask &PSW_MASK_EA ) regs->psw.mask |=PSW_MASK_BA ;
@@ -294,7 +298,10 @@ static int setup_frame(int sig, struct k/* Set up registers for signal handler */ regs->gprs[15 ] = (unsigned long ) frame; - regs->psw.mask |=PSW_MASK_EA |PSW_MASK_BA ;/* 64 bit amode */ +/* Force default amode and default user address space control. */ + regs->psw.mask =PSW_MASK_EA |PSW_MASK_BA | + (psw_user_bits &PSW_MASK_ASC ) | + (regs->psw.mask & ~PSW_MASK_ASC ); regs->psw.addr = (unsigned long ) ka->sa.sa_handler |PSW_ADDR_AMODE ; regs->gprs[2 ] =map_signal (sig);
@@ -367,7 +374,10 @@ static int setup_rt_frame(int sig, struc/* Set up registers for signal handler */ regs->gprs[15 ] = (unsigned long ) frame; - regs->psw.mask |=PSW_MASK_EA |PSW_MASK_BA ;/* 64 bit amode */ +/* Force default amode and default user address space control. */ + regs->psw.mask =PSW_MASK_EA |PSW_MASK_BA | + (psw_user_bits &PSW_MASK_ASC ) | + (regs->psw.mask & ~PSW_MASK_ASC ); regs->psw.addr = (unsigned long ) ka->sa.sa_handler |PSW_ADDR_AMODE ; regs->gprs[2 ] =map_signal (sig);
Greg Kroah-Hartman
maintainerPATCH 49/171 drm/i915: fix overlay on i830M
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Daniel Vetter <[email protected]>
commit a9193983f4f292a82a00c72971c17ec0ee8c6c15 upstream.
The overlay on the i830M has a peculiar failure mode: It works the first time around after boot-up, but consistenly hangs the second time it's used.
Chris Wilson has dug out a nice errata:
"1.5.12 Clock Gating Disable for Display Register
Address Offset: 06200h–06203h
"Bit 3
Ovrunit Clock Gating Disable.
0 = Clock gating controlled by unit enabling logic
1 = Disable clock gating function
DevALM Errata ALM049: Overlay Clock Gating Must be Disabled: Overlay & L2 Cache clock gating must be disabled in order to prevent device hangs when turning off overlay.SW must turn off Ovrunit clock gating (6200h) and L2 Cache clock gating (C8h)."
Now I've nowhere found that 0xc8 register and hence couldn't apply the l2 cache workaround. But I've remembered that part of the magic that the OVERLAY_ON/OFF commands are supposed to do is to rearrange cache allocations so that the overlay scaler has some scratch space.
And while pondering how that could explain the hang the 2nd time we enable the overlay, I've remembered that the old ums overlay code did _not_ issue the OVERLAY_OFF cmd.
And indeed, disabling the OFF cmd results in the overlay working flawlessly, so I guess we can workaround the lack of the above workaround by simply never disabling the overlay engine once it's enabled.
Note that we have the first part of the above w/a already implemented in i830_init_clock_gating - leave that as-is to avoid surprises.
v2: Add a comment in the code.
Bugzilla: https://bugs.freedesktop.org/show_bug.cgi?id=47827
[bwh: Backported to 3.2:
- Adjust context
- s/intel_ring_emit(ring, /OUT_RING(/]
---
 drivers/gpu/drm/i915/intel_overlay.c |   14 +++++++++++---
 1 file changed, 11 insertions(+), 3 deletions(-)
drivers/gpu/drm/i915/intel_overlay.c +11 -3
@@ -427,9 +427,17 @@ static int intel_overlay_off(struct inteOUT_RING (flip_addr);OUT_RING (MI_WAIT_FOR_EVENT |MI_WAIT_FOR_OVERLAY_FLIP );/* turn overlay off */ -OUT_RING (MI_OVERLAY_FLIP |MI_OVERLAY_OFF ); -OUT_RING (flip_addr); -OUT_RING (MI_WAIT_FOR_EVENT |MI_WAIT_FOR_OVERLAY_FLIP ); +if (IS_I830 (dev)) { +/* Workaround: Don't disable the overlay fully, since otherwise +* it dies on the next OVERLAY_ON cmd. */ +OUT_RING (MI_NOOP ); +OUT_RING (MI_NOOP ); +OUT_RING (MI_NOOP ); + }else { +OUT_RING (MI_OVERLAY_FLIP |MI_OVERLAY_OFF ); +OUT_RING (flip_addr); +OUT_RING (MI_WAIT_FOR_EVENT |MI_WAIT_FOR_OVERLAY_FLIP ); + }ADVANCE_LP_RING (); return intel_overlay_do_wait_request(overlay, request,
Greg Kroah-Hartman
maintainerPATCH 50/171 NFS: Wait for session recovery to finish before returning
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Bryan Schumaker <[email protected]>
commit 399f11c3d872bd748e1575574de265a6304c7c43 upstream.
Currently, we will schedule session recovery and then return to the caller of nfs4_handle_exception. This works for most cases, but causes a hang on the following test case:
Client Server
------ ------
Open file over NFS v4.1
Write to file
Expire client
Try to lock file
The server will return NFS4ERR_BADSESSION, prompting the client to schedule recovery. However, the client will continue placing lock attempts and the open recovery never seems to be scheduled. The simplest solution is to wait for session recovery to run before retrying the lock.
---
 fs/nfs/nfs4proc.c |    3 +--
 1 file changed, 1 insertion(+), 2 deletions(-)
fs/nfs/nfs4proc.c +1 -2
@@ -307,8 +307,7 @@ static int nfs4_handle_exception(structdprintk ("%s ERROR: %d Reset session\n" , __func__, errorcode);nfs4_schedule_session_recovery (clp->cl_session); - exception->retry =1 ; -break ; + goto wait_on_recovery;#endif /* defined(CONFIG_NFS_V4_1) */ case -NFS4ERR_FILE_OPEN :if (exception->timeout >HZ ) {
Greg Kroah-Hartman
maintainerPATCH 51/171 reiserfs: Fix lock ordering during remount
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jan Kara <[email protected]>
commit 3bb3e1fc47aca554e7e2cc4deeddc24750987ac2 upstream.
When remounting reiserfs dquot_suspend() or dquot_resume() can be called. These functions take dqonoff_mutex which ranks above write lock so we have to drop it before calling into quota code.
---
 fs/reiserfs/super.c |   27 ++++++++++++++++++++-------
 1 file changed, 20 insertions(+), 7 deletions(-)
fs/reiserfs/super.c +20 -7
@@ -1292,7 +1292,7 @@ static int reiserfs_remount(struct superkfree (qf_names[i]);#endif err = -EINVAL ; - goto out_err; + goto out_unlock; }#ifdef CONFIG_QUOTA handle_quota_files (s, qf_names, &qfmt);
@@ -1336,7 +1336,7 @@ static int reiserfs_remount(struct superif (blocks) { err =reiserfs_resize (s, blocks);if (err !=0 ) - goto out_err; + goto out_unlock; }if (*mount_flags &MS_RDONLY ) {
@@ -1346,9 +1346,15 @@ static int reiserfs_remount(struct super/* it is read-only already */ goto out_ok; +/* +* Drop write lock. Quota will retake it when needed and lock +* ordering requires calling dquot_suspend() without it. +*/ +reiserfs_write_unlock (s); err =dquot_suspend (s,-1 );if (err <0 ) goto out_err; +reiserfs_write_lock (s);/* try to remount file system with read-only permissions */ if (sb_umount_state(rs) == REISERFS_VALID_FS
@@ -1358,7 +1364,7 @@ static int reiserfs_remount(struct super err =journal_begin (&th, s,10 );if (err) - goto out_err; + goto out_unlock;/* Mounting a rw partition read-only. */ reiserfs_prepare_for_journal (s,SB_BUFFER_WITH_SB (s),1 );
@@ -1373,7 +1379,7 @@ static int reiserfs_remount(struct superif (reiserfs_is_journal_aborted (journal)) { err = journal->j_errno; - goto out_err; + goto out_unlock; }handle_data_mode (s, mount_options);
@@ -1382,7 +1388,7 @@ static int reiserfs_remount(struct super s->s_flags &= ~MS_RDONLY ;/* now it is safe to call journal_begin */ err =journal_begin (&th, s,10 );if (err) - goto out_err; + goto out_unlock;/* Mount a partition which is read-only, read-write */ reiserfs_prepare_for_journal (s,SB_BUFFER_WITH_SB (s),1 );
@@ -1399,11 +1405,17 @@ static int reiserfs_remount(struct superSB_JOURNAL (s)->j_must_wait =1 ; err =journal_end (&th, s,10 );if (err) - goto out_err; + goto out_unlock; s->s_dirt =0 ;if (!(*mount_flags &MS_RDONLY )) { +/* +* Drop write lock. Quota will retake it when needed and lock +* ordering requires calling dquot_resume() without it. +*/ +reiserfs_write_unlock (s);dquot_resume (s,-1 ); +reiserfs_write_lock (s);finish_unfinished (s);reiserfs_xattr_init (s, *mount_flags); }
@@ -1413,9 +1425,10 @@ out_ok:reiserfs_write_unlock (s);return 0 ; +out_unlock: +reiserfs_write_unlock (s); out_err:kfree (new_opts); -reiserfs_write_unlock (s);return err; }
Greg Kroah-Hartman
maintainerPATCH 52/171 reiserfs: Protect reiserfs_quota_on() with write lock
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jan Kara <[email protected]>
commit b9e06ef2e8706fe669b51f4364e3aeed58639eb2 upstream.
In reiserfs_quota_on() we do quite some work - for example unpacking tail of a quota file. Thus we have to hold write lock until a moment we call back into the quota code.
---
 fs/reiserfs/super.c |   11 ++++++++---
 1 file changed, 8 insertions(+), 3 deletions(-)
fs/reiserfs/super.c +8 -3
@@ -2170,8 +2170,11 @@ static int reiserfs_quota_on(struct supestruct reiserfs_transaction_handle th;int opt = type ==USRQUOTA ?REISERFS_USRQUOTA :REISERFS_GRPQUOTA ; -if (!(REISERFS_SB (sb)->s_mount_opt & (1 << opt))) -return -EINVAL ; +reiserfs_write_lock (sb); +if (!(REISERFS_SB (sb)->s_mount_opt & (1 << opt))) { + err = -EINVAL ; + goto out; + }/* Quotafile not on the same filesystem? */ if (path->dentry->d_sb != sb) {
@@ -2213,8 +2216,10 @@ static int reiserfs_quota_on(struct supeif (err) goto out; } - err =dquot_quota_on (sb, type, format_id, path); +reiserfs_write_unlock (sb); +return dquot_quota_on (sb, type, format_id, path); out: +reiserfs_write_unlock (sb);return err; }
Greg Kroah-Hartman
maintainerPATCH 53/171 reiserfs: Move quota calls out of write lock
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jan Kara <[email protected]>
commit 7af11686933726e99af22901d622f9e161404e6b upstream.
Calls into highlevel quota code cannot happen under the write lock. These calls take dqio_mutex which ranks above write lock. So drop write lock before calling back into quota code.
---
 fs/reiserfs/inode.c |   10 +++++++---
 fs/reiserfs/stree.c |    4 ++++
 fs/reiserfs/super.c |   18 ++++++++++++++----
 3 files changed, 25 insertions(+), 7 deletions(-)
fs/reiserfs/inode.c +7 -3
@@ -1788,8 +1788,9 @@ int reiserfs_new_inode(struct reiserfs_tBUG_ON (!th->t_trans_id); -dquot_initialize (inode); +reiserfs_write_unlock (inode->i_sb); err =dquot_alloc_inode (inode); +reiserfs_write_lock (inode->i_sb);if (err) goto out_end_trans;if (!dir->i_nlink) {
@@ -1985,8 +1986,10 @@ int reiserfs_new_inode(struct reiserfs_t out_end_trans:journal_end (th, th->t_super, th->t_blocks_allocated); +reiserfs_write_unlock (inode->i_sb);/* Drop can be outside and it needs more credits so it's better to have it outside */ dquot_drop (inode); +reiserfs_write_lock (inode->i_sb); inode->i_flags |=S_NOQUOTA ;make_bad_inode (inode);
@@ -3109,10 +3112,9 @@ int reiserfs_setattr(struct dentry *dent/* must be turned off for recursive notify_change calls */ ia_valid = attr->ia_valid &= ~(ATTR_KILL_SUID |ATTR_KILL_SGID ); - depth =reiserfs_write_lock_once (inode->i_sb);if (is_quota_modification (inode, attr))dquot_initialize (inode); - + depth =reiserfs_write_lock_once (inode->i_sb);if (attr->ia_valid &ATTR_SIZE ) {/* version 2 items will be caught by the s_maxbytes check ** done for us in vmtruncate
@@ -3176,7 +3178,9 @@ int reiserfs_setattr(struct dentry *dent error =journal_begin (&th, inode->i_sb, jbegin_count);if (error) goto out; +reiserfs_write_unlock_once (inode->i_sb, depth); error =dquot_transfer (inode, attr); + depth =reiserfs_write_lock_once (inode->i_sb);if (error) {journal_end (&th, inode->i_sb, jbegin_count); goto out;
fs/reiserfs/stree.c +4 -0
@@ -1968,7 +1968,9 @@ int reiserfs_paste_into_item(struct reis key2type(&(key->on_disk_key)));#endif +reiserfs_write_unlock (inode->i_sb); retval =dquot_alloc_space_nodirty (inode, pasted_size); +reiserfs_write_lock (inode->i_sb);if (retval) {pathrelse (search_path);return retval;
@@ -2061,9 +2063,11 @@ int reiserfs_insert_item(struct reiserfs"reiserquota insert_item(): allocating %u id=%u type=%c" , quota_bytes, inode->i_uid, head2type(ih));#endif +reiserfs_write_unlock (inode->i_sb);/* We can't dirty inode here. It would be immediately written but * appropriate stat item isn't inserted yet... */ retval =dquot_alloc_space_nodirty (inode, quota_bytes); +reiserfs_write_lock (inode->i_sb);if (retval) {pathrelse (path);return retval;
fs/reiserfs/super.c +14 -4
@@ -256,7 +256,9 @@ static int finish_unfinished(struct supe retval =remove_save_link_only (s, &save_link_key,0 );continue ; } +reiserfs_write_unlock (s);dquot_initialize (inode); +reiserfs_write_lock (s);if (truncate &&S_ISDIR (inode->i_mode)) {/* We got a truncate request for a dir which is impossible.
@@ -2062,13 +2064,15 @@ static int reiserfs_write_dquot(struct d REISERFS_QUOTA_TRANS_BLOCKS(dquot->dq_sb));if (ret) goto out; +reiserfs_write_unlock (dquot->dq_sb); ret =dquot_commit (dquot); +reiserfs_write_lock (dquot->dq_sb); err =journal_end (&th, dquot->dq_sb,REISERFS_QUOTA_TRANS_BLOCKS (dquot->dq_sb));if (!ret && err) ret = err; - out: +out:reiserfs_write_unlock (dquot->dq_sb);return ret; }
@@ -2084,13 +2088,15 @@ static int reiserfs_acquire_dquot(struct REISERFS_QUOTA_INIT_BLOCKS(dquot->dq_sb));if (ret) goto out; +reiserfs_write_unlock (dquot->dq_sb); ret =dquot_acquire (dquot); +reiserfs_write_lock (dquot->dq_sb); err =journal_end (&th, dquot->dq_sb,REISERFS_QUOTA_INIT_BLOCKS (dquot->dq_sb));if (!ret && err) ret = err; - out: +out:reiserfs_write_unlock (dquot->dq_sb);return ret; }
@@ -2104,19 +2110,21 @@ static int reiserfs_release_dquot(struct ret =journal_begin (&th, dquot->dq_sb,REISERFS_QUOTA_DEL_BLOCKS (dquot->dq_sb)); +reiserfs_write_unlock (dquot->dq_sb);if (ret) {/* Release dquot anyway to avoid endless cycle in dqput() */ dquot_release (dquot); goto out; } ret =dquot_release (dquot); +reiserfs_write_lock (dquot->dq_sb); err =journal_end (&th, dquot->dq_sb,REISERFS_QUOTA_DEL_BLOCKS (dquot->dq_sb));if (!ret && err) ret = err; - out:reiserfs_write_unlock (dquot->dq_sb); +out:return ret; }
@@ -2141,11 +2149,13 @@ static int reiserfs_write_info(struct su ret =journal_begin (&th, sb,2 );if (ret) goto out; +reiserfs_write_unlock (sb); ret =dquot_commit_info (sb, type); +reiserfs_write_lock (sb); err =journal_end (&th, sb,2 );if (!ret && err) ret = err; - out: +out:reiserfs_write_unlock (sb);return ret; }
Greg Kroah-Hartman
maintainerPATCH 54/171 reiserfs: Protect reiserfs_quota_write() with write lock
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Jan Kara <[email protected]>
commit 361d94a338a3fd0cee6a4ea32bbc427ba228e628 upstream.
Calls into reiserfs journalling code and reiserfs_get_block() need to be protected with write lock. We remove write lock around calls to high level quota code in the next patch so these paths would suddently become unprotected.
---
 fs/reiserfs/super.c |    4 ++++
 1 file changed, 4 insertions(+)
fs/reiserfs/super.c +4 -0
@@ -2303,7 +2303,9 @@ static ssize_t reiserfs_quota_write(stru tocopy = sb->s_blocksize - offset < towrite ? sb->s_blocksize - offset : towrite; tmp_bh.b_state =0 ; +reiserfs_write_lock (sb); err =reiserfs_get_block (inode, blk, &tmp_bh,GET_BLOCK_CREATE ); +reiserfs_write_unlock (sb);if (err) goto out;if (offset || tocopy != sb->s_blocksize)
@@ -2319,10 +2321,12 @@ static ssize_t reiserfs_quota_write(struflush_dcache_page (bh->b_page);set_buffer_uptodate (bh);unlock_buffer (bh); +reiserfs_write_lock (sb);reiserfs_prepare_for_journal (sb, bh,1 );journal_mark_dirty (current->journal_info, sb, bh);if (!journal_quota)reiserfs_add_ordered_list (inode, bh); +reiserfs_write_unlock (sb);brelse (bh); offset =0 ; towrite -= tocopy;
Greg Kroah-Hartman
maintainerPATCH 55/171 selinux: fix sel_netnode_insert() suspicious rcu dereference
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Dave Jones <[email protected]>
commit 88a693b5c1287be4da937699cb82068ce9db0135 upstream.
===============================
[ INFO: suspicious RCU usage. ]
3.5.0-rc1+ #63 Not tainted
-------------------------------security/selinux/netnode.c:178 suspicious rcu_dereference_check() usage!
other info that might help us debug this:
rcu_scheduler_active = 1, debug_locks = 0
1 lock held by trinity-child1/8750:
#0: (sel_netnode_lock){+.....}, at: [<ffffffff812d8f8a>] sel_netnode_sid+0x16a/0x3e0
stack backtrace:
Pid: 8750, comm: trinity-child1 Not tainted 3.5.0-rc1+ #63
Call Trace:
 [<ffffffff810cec2d>] lockdep_rcu_suspicious+0xfd/0x130
 [<ffffffff812d91d1>] sel_netnode_sid+0x3b1/0x3e0
 [<ffffffff812d8e20>] ? sel_netnode_find+0x1a0/0x1a0
 [<ffffffff812d24a6>] selinux_socket_bind+0xf6/0x2c0
 [<ffffffff810cd1dd>] ? trace_hardirqs_off+0xd/0x10
 [<ffffffff810cdb55>] ? lock_release_holdtime.part.9+0x15/0x1a0
 [<ffffffff81093841>] ? lock_hrtimer_base+0x31/0x60
 [<ffffffff812c9536>] security_socket_bind+0x16/0x20
 [<ffffffff815550ca>] sys_bind+0x7a/0x100
 [<ffffffff816c03d5>] ? sysret_check+0x22/0x5d
 [<ffffffff810d392d>] ? trace_hardirqs_on_caller+0x10d/0x1a0
 [<ffffffff8133b09e>] ? trace_hardirqs_on_thunk+0x3a/0x3f
 [<ffffffff816c03a9>] system_call_fastpath+0x16/0x1b
This patch below does what Paul McKenney suggested in the previous thread.
---
 security/selinux/netnode.c |    3 ++-
 1 file changed, 2 insertions(+), 1 deletion(-)
security/selinux/netnode.c +2 -1
@@ -174,7 +174,8 @@ static void sel_netnode_insert(struct seif (sel_netnode_hash[idx].size ==SEL_NETNODE_HASH_BKT_LIMIT ) {struct sel_netnode *tail; tail =list_entry ( -rcu_dereference (sel_netnode_hash[idx].list.prev), +rcu_dereference_protected (sel_netnode_hash[idx].list.prev, +lockdep_is_held (&sel_netnode_lock)), struct sel_netnode, list);list_del_rcu (&tail->list);kfree_rcu (tail, rcu);
Greg Kroah-Hartman
maintainerPATCH 56/171 crush: clean up types, const-ness
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 8b12d47b80c7a34dffdd98244d99316db490ec58)
Move various types from int -> __u32 (or similar), and add const as appropriate.
This reflects changes that have been present in the userland implementation for some time.
---
 include/linux/crush/crush.h  |    2 +-
 include/linux/crush/mapper.h |    6 +++---
 net/ceph/crush/crush.c       |    8 ++++----
 net/ceph/crush/mapper.c      |   31 ++++++++++++++++---------------
 4 files changed, 24 insertions(+), 23 deletions(-)
include/linux/crush/crush.h +1 -1
@@ -168,7 +168,7 @@ struct crush_map {/* crush.c */ -extern int crush_get_bucket_item_weight (struct crush_bucket *b,int pos); +extern int crush_get_bucket_item_weight (const struct crush_bucket *b,int pos);extern void crush_calc_parents (struct crush_map *map);extern void crush_destroy_bucket_uniform (struct crush_bucket_uniform *b);extern void crush_destroy_bucket_list (struct crush_bucket_list *b);
include/linux/crush/mapper.h +3 -3
@@ -10,11 +10,11 @@#include "crush.h" -extern int crush_find_rule (struct crush_map *map,int pool,int type,int size); -extern int crush_do_rule (struct crush_map *map, +extern int crush_find_rule (const struct crush_map *map,int ruleset,int type,int size); +extern int crush_do_rule (const struct crush_map *map,int ruleno,int x,int *result,int result_max,int forcefeed,/* -1 for none */ -__u32 *weights); +const __u32 *weights);#endif
net/ceph/crush/crush.c +4 -4
@@ -26,9 +26,9 @@ const char *crush_bucket_alg_name(int al* @b: bucket pointer * @p: item index in bucket */ -int crush_get_bucket_item_weight (struct crush_bucket *b,int p) +int crush_get_bucket_item_weight (const struct crush_bucket *b,int p) { -if (p >= b->size) +if ((__u32 )p >= b->size)return 0 ;switch (b->alg) {
@@ -124,10 +124,9 @@ void crush_destroy_bucket(struct crush_b*/ void crush_destroy (struct crush_map *map) { -int b; -/* buckets */ if (map->buckets) { +__s32 b;for (b =0 ; b < map->max_buckets; b++) {if (map->buckets[b] ==NULL )continue ;
@@ -138,6 +137,7 @@ void crush_destroy(struct crush_map *map/* rules */ if (map->rules) { +__u32 b;for (b =0 ; b < map->max_rules; b++)kfree (map->rules[b]);kfree (map->rules);
net/ceph/crush/mapper.c +16 -15
@@ -32,9 +32,9 @@* @type: storage ruleset type (user defined) * @size: output set size */ -int crush_find_rule (struct crush_map *map,int ruleset,int type,int size) +int crush_find_rule (const struct crush_map *map,int ruleset,int type,int size) { -int i; +__u32 i;for (i =0 ; i < map->max_rules; i++) { if (map->rules[i] &&
@@ -72,7 +72,7 @@ static int bucket_perm_choose(struct cruunsigned i, s;/* start a new permutation if @x has changed */ -if (bucket->perm_x != x || bucket->perm_n ==0 ) { +if (bucket->perm_x != (__u32 )x || bucket->perm_n ==0 ) {dprintk ("bucket %d new x=%d\n" , bucket->id, x); bucket->perm_x = x;
@@ -219,7 +219,7 @@ static int bucket_tree_choose(struct crustatic int bucket_straw_choose (struct crush_bucket_straw *bucket,int x,int r) { -int i; +__u32 i;int high =0 ;__u64 high_draw =0 ;__u64 draw;
@@ -262,7 +262,7 @@ static int crush_bucket_choose(struct cr* true if device is marked "out" (failed, fully offloaded) * of the cluster */ -static int is_out (struct crush_map *map,__u32 *weight,int item,int x) +static int is_out (const struct crush_map *map,const __u32 *weight,int item,int x) {if (weight[item] >=0x10000 )return 0 ;
@@ -287,16 +287,16 @@ static int is_out(struct crush_map *map,* @recurse_to_leaf: true if we want one device under each item of given type * @out2: second output vector for leaf items (if @recurse_to_leaf) */ -static int crush_choose (struct crush_map *map, +static int crush_choose (const struct crush_map *map,struct crush_bucket *bucket, -__u32 *weight, +const __u32 *weight,int x,int numrep,int type,int *out,int outpos,int firstn,int recurse_to_leaf,int *out2) {int rep; -int ftotal, flocal; +unsigned int ftotal, flocal;int retry_descent, retry_bucket, skip_rep;struct crush_bucket *in = bucket;int r;
@@ -304,7 +304,7 @@ static int crush_choose(struct crush_mapint item =0 ;int itemtype;int collide, reject; -const int orig_tries =5 ;/* attempts before we fall back to search */ +const unsigned int orig_tries =5 ;/* attempts before we fall back to search */ dprintk ("CHOOSE%s bucket %d x %d outpos %d numrep %d\n" , recurse_to_leaf ?"_LEAF" :"" , bucket->id, x, outpos, numrep);
@@ -325,7 +325,7 @@ static int crush_choose(struct crush_map r = rep;if (in->alg ==CRUSH_BUCKET_UNIFORM ) {/* be careful */ -if (firstn || numrep >= in->size) +if (firstn || (__u32 )numrep >= in->size)/* r' = r + f_total */ r += ftotal;else if (in->size % numrep ==0 )
@@ -425,7 +425,7 @@ reject:/* else give up */ skip_rep =1 ;dprintk (" reject %d collide %d " -"ftotal %d flocal %d\n" , +"ftotal %u flocal %u\n" , reject, collide, ftotal, flocal); }
@@ -456,9 +456,9 @@ reject:* @result_max: maximum result size * @force: force initial replica choice; -1 for none */ -int crush_do_rule (struct crush_map *map, +int crush_do_rule (const struct crush_map *map,int ruleno,int x,int *result,int result_max, -int force,__u32 *weight) +int force,const __u32 *weight) {int result_len;int force_context[CRUSH_MAX_DEPTH ];
@@ -473,7 +473,7 @@ int crush_do_rule(struct crush_map *map,int osize;int *tmp;struct crush_rule *rule; -int step; +__u32 step;int i, j;int numrep;int firstn;
@@ -488,7 +488,8 @@ int crush_do_rule(struct crush_map *map,/* * determine hierarchical context of force, if any. note * that this may or may not correspond to the specific types -* referenced by the crush rule. +* referenced by the crush rule. it will also only affect +* the first descent (TAKE). */ if (force >= 0 && force < map->max_devices &&
Greg Kroah-Hartman
maintainerPATCH 57/171 crush: adjust local retry threshold
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit c90f95ed46393e29d843686e21947d1c6fcb1164)
This small adjustment reflects a change that was made in ceph.git commit af6a9f30696c900a2a8bd7ae24e8ed15fb4964bb, about 6 months ago. An N-1 search is not exhaustive. Fixed ceph.git bug #1594.
--- net/ceph/crush/mapper.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
net/ceph/crush/mapper.c +1 -1
@@ -415,7 +415,7 @@ reject:if (collide && flocal <3 )/* retry locally a few times */ retry_bucket =1 ; -else if (flocal < in->size + orig_tries) +else if (flocal <= in->size + orig_tries)/* exhaustive bucket search */ retry_bucket =1 ;else if (ftotal <20 )
Greg Kroah-Hartman
maintainerPATCH 58/171 crush: be more tolerant of nonsensical crush maps
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit a1f4895be8bf1ba56c2306b058f51619e9b0e8f8)
If we get a map that doesn't make sense, error out or ignore the badness instead of BUGging out. This reflects the ceph.git commits 9895f0bff7dc68e9b49b572613d242315fb11b6c and 8ded26472058d5205803f244c2f33cb6cb10de79.
--- net/ceph/crush/mapper.c | 33 ++++++++++++++++++++++++--------- 1 file changed, 24 insertions(+), 9 deletions(-)
net/ceph/crush/mapper.c +24 -9
@@ -152,8 +152,8 @@ static int bucket_list_choose(struct crureturn bucket->h.items[i]; } -BUG_ON (1 ); -return 0 ; +dprintk ("bad list sums for bucket %d\n" , bucket->h.id); +return bucket->h.items[0 ]; }
@@ -239,6 +239,7 @@ static int bucket_straw_choose(struct crstatic int crush_bucket_choose (struct crush_bucket *in,int x,int r) {dprintk (" crush_bucket_choose %d x=%d r=%d\n" , in->id, x, r); +BUG_ON (in->size ==0 );switch (in->alg) {case CRUSH_BUCKET_UNIFORM : return bucket_uniform_choose((struct crush_bucket_uniform *)in,
@@ -253,7 +254,7 @@ static int crush_bucket_choose(struct crreturn bucket_straw_choose ((struct crush_bucket_straw *)in, x, r);default : -BUG_ON (1 ); +dprintk ("unknown bucket %d alg %d\n" , in->id, in->alg);return in->items[0 ]; } }
@@ -354,7 +355,11 @@ static int crush_choose(const struct cru item =bucket_perm_choose (in, x, r); else item =crush_bucket_choose (in, x, r); -BUG_ON (item >= map->max_devices); +if (item >= map->max_devices) { +dprintk (" bad item %d\n" , item); + skip_rep =1 ; +break ; + }/* desired type? */ if (item <0 )
@@ -365,8 +370,12 @@ static int crush_choose(const struct cru/* keep going? */ if (itemtype != type) { -BUG_ON (item >=0 || - (-1 -item) >= map->max_buckets); +if (item >=0 || + (-1 -item) >= map->max_buckets) { +dprintk (" bad item type %d\n" , type); + skip_rep =1 ; +break ; + } in = map->buckets[-1 -item]; retry_bucket =1 ;continue ;
@@ -478,7 +487,10 @@ int crush_do_rule(const struct crush_mapint numrep;int firstn; -BUG_ON (ruleno >= map->max_rules); +if ((__u32 )ruleno >= map->max_rules) { +dprintk (" bad ruleno %d\n" , ruleno); +return 0 ; + } rule = map->rules[ruleno]; result_len =0 ;
@@ -528,7 +540,8 @@ int crush_do_rule(const struct crush_map firstn =1 ;case CRUSH_RULE_CHOOSE_LEAF_INDEP :case CRUSH_RULE_CHOOSE_INDEP : -BUG_ON (wsize ==0 ); +if (wsize ==0 ) +break ; recurse_to_leaf = rule->steps[step].op ==
@@ -597,7 +610,9 @@ int crush_do_rule(const struct crush_mapbreak ;default : -BUG_ON (1 ); +dprintk (" unknown op %d at step %d\n" , + curstep->op, step); +break ; } }return result_len;
Greg Kroah-Hartman
maintainerPATCH 59/171 crush: fix tree node weight lookup
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit f671d4cd9b36691ac4ef42cde44c1b7a84e13631)
Fix the node weight lookup for tree buckets by using a correct accessor.
Reflects ceph.git commit d287ade5bcbdca82a3aef145b92924cf1e856733.
--- include/linux/crush/crush.h | 5 +++++ net/ceph/crush/crush.c | 4 +--- 2 files changed, 6 insertions(+), 3 deletions(-)
include/linux/crush/crush.h +5 -0
@@ -177,4 +177,9 @@ extern void crush_destroy_bucket_straw(sextern void crush_destroy_bucket (struct crush_bucket *b);extern void crush_destroy (struct crush_map *map); +static inline int crush_calc_tree_node (int i) +{ +return ((i+1 ) <<1 )-1 ; +} +#endif
net/ceph/crush/crush.c +1 -3
@@ -37,9 +37,7 @@ int crush_get_bucket_item_weight(const scase CRUSH_BUCKET_LIST :return ((struct crush_bucket_list *)b)->item_weights[p];case CRUSH_BUCKET_TREE : -if (p &1 ) -return ((struct crush_bucket_tree *)b)->node_weights[p]; -return 0 ; +return ((struct crush_bucket_tree *)b)->node_weights[crush_calc_tree_node (p)];case CRUSH_BUCKET_STRAW :return ((struct crush_bucket_straw *)b)->item_weights[p]; }
Greg Kroah-Hartman
maintainerPATCH 60/171 crush: fix memory leak when destroying tree buckets
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 6eb43f4b5a2a74599b4ff17a97c03a342327ca65)
Reflects ceph.git commit 46d63d98434b3bc9dad2fc9ab23cbaedc3bcb0e4.
--- net/ceph/crush/crush.c | 2 ++ 1 file changed, 2 insertions(+)
net/ceph/crush/crush.c +2 -0
@@ -85,6 +85,8 @@ void crush_destroy_bucket_list(struct crvoid crush_destroy_bucket_tree (struct crush_bucket_tree *b) { +kfree (b->h.perm); +kfree (b->h.items);kfree (b->node_weights);kfree (b); }
Greg Kroah-Hartman
maintainerPATCH 61/171 ceph: osd_client: fix endianness bug in osd_req_encode_op()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 065a68f9167e20f321a62d044cb2c3024393d455)
Quoted 1 line
Quoted 1 line
From Al Viro <[email protected]>
Al Viro noticed that we were using a non-cpu-encoded value in a switch statement in osd_req_encode_op(). The result would clearly not work correctly on a big-endian machine.
--- net/ceph/osd_client.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
net/ceph/osd_client.c +1 -1
@@ -278,7 +278,7 @@ static void osd_req_encode_op(struct cep { dst->op =cpu_to_le16 (src->op); -switch (dst->op) { +switch (src->op) {case CEPH_OSD_OP_READ :case CEPH_OSD_OP_WRITE : dst->extent.offset =
Greg Kroah-Hartman
maintainerPATCH 62/171 ceph: messenger: use read_partial() in read_partial_message()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 57dac9d1620942608306d8c17c98a9d1568ffdf4)
There are two blocks of code in read_partial_message()--those that read the header and footer of the message--that can be replaced by a call to read_partial(). Do that.
--- net/ceph/messenger.c | 30 ++++++++++-------------------- 1 file changed, 10 insertions(+), 20 deletions(-)
net/ceph/messenger.c +10 -20
@@ -1628,7 +1628,7 @@ static int read_partial_message(struct c {struct ceph_msg *m = con->in_msg;int ret; -int to, left; +int to;unsigned front_len, middle_len, data_len;bool do_datacrc = !con->msgr->nocrc;int skip;
@@ -1638,15 +1638,10 @@ static int read_partial_message(struct cdout ("read_partial_message con %p msg %p\n" , con, m);/* header */ -while (con->in_base_pos <sizeof (con->in_hdr)) { - left =sizeof (con->in_hdr) - con->in_base_pos; - ret =ceph_tcp_recvmsg (con->sock, - (char *)&con->in_hdr + con->in_base_pos, - left); -if (ret <=0 ) -return ret; - con->in_base_pos += ret; - } + to =0 ; + ret =read_partial (con, &to,sizeof (con->in_hdr), &con->in_hdr); +if (ret <=0 ) +return ret; crc =crc32c (0 , &con->in_hdr, offsetof(struct ceph_msg_header , crc));if (cpu_to_le32 (crc) != con->in_hdr.crc) {
@@ -1759,16 +1754,11 @@ static int read_partial_message(struct c }/* footer */ - to =sizeof (m->hdr) +sizeof (m->footer); -while (con->in_base_pos < to) { - left = to - con->in_base_pos; - ret =ceph_tcp_recvmsg (con->sock, (char *)&m->footer + - (con->in_base_pos -sizeof (m->hdr)), - left); -if (ret <=0 ) -return ret; - con->in_base_pos += ret; - } + to =sizeof (m->hdr); + ret =read_partial (con, &to,sizeof (m->footer), &m->footer); +if (ret <=0 ) +return ret; +dout ("read_partial_message got msg %p %d (%u) + %d (%u) + %d (%u)\n" , m, front_len, m->footer.front_crc, middle_len, m->footer.middle_crc, data_len, m->footer.data_crc);
Greg Kroah-Hartman
maintainerPATCH 63/171 ceph: messenger: update "to" in read_partial() caller
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit e6cee71fac27c946a0bbad754dd076e66c4e9dbd)
read_partial() always increases whatever "to" value is supplied by adding the requested size to it, and that's the only thing it does with that pointed-to value.
Do that pointer advance in the caller (and then only when the updated value will be subsequently used), and change the "to" parameter to be an in-only and non-pointer value.
--- net/ceph/messenger.c | 31 ++++++++++++++++--------------- 1 file changed, 16 insertions(+), 15 deletions(-)
net/ceph/messenger.c +16 -15
@@ -992,11 +992,12 @@ static int prepare_read_message(struct cstatic int read_partial (struct ceph_connection *con, -int *to,int size,void *object) +int to,int size,void *object) { - *to += size; -while (con->in_base_pos < *to) { -int left = *to - con->in_base_pos; +int end = to + size; + +while (con->in_base_pos < end) { +int left = end - con->in_base_pos;int have = size - left;int ret =ceph_tcp_recvmsg (con->sock, object + have, left);if (ret <=0 )
@@ -1017,14 +1018,16 @@ static int read_partial_banner(struct cedout ("read_partial_banner %p at %d\n" , con, con->in_base_pos);/* peer's banner */ - ret =read_partial (con, &to,strlen (CEPH_BANNER ), con->in_banner); + ret =read_partial (con, to,strlen (CEPH_BANNER ), con->in_banner);if (ret <=0 ) goto out; - ret =read_partial (con, &to,sizeof (con->actual_peer_addr), + to +=strlen (CEPH_BANNER ); + ret =read_partial (con, to,sizeof (con->actual_peer_addr), &con->actual_peer_addr);if (ret <=0 ) goto out; - ret =read_partial (con, &to,sizeof (con->peer_addr_for_me), + to +=sizeof (con->actual_peer_addr); + ret =read_partial (con, to,sizeof (con->peer_addr_for_me), &con->peer_addr_for_me);if (ret <=0 ) goto out;
@@ -1038,10 +1041,11 @@ static int read_partial_connect(struct cdout ("read_partial_connect %p at %d\n" , con, con->in_base_pos); - ret =read_partial (con, &to,sizeof (con->in_reply), &con->in_reply); + ret =read_partial (con, to,sizeof (con->in_reply), &con->in_reply);if (ret <=0 ) goto out; - ret =read_partial (con, &to,le32_to_cpu (con->in_reply.authorizer_len), + to +=sizeof (con->in_reply); + ret =read_partial (con, to,le32_to_cpu (con->in_reply.authorizer_len), con->auth_reply_buf);if (ret <=0 ) goto out;
@@ -1491,9 +1495,7 @@ static int process_connect(struct ceph_c*/ static int read_partial_ack (struct ceph_connection *con) { -int to =0 ; - -return read_partial (con, &to,sizeof (con->in_temp_ack), +return read_partial (con,0 ,sizeof (con->in_temp_ack), &con->in_temp_ack); }
@@ -1638,8 +1640,7 @@ static int read_partial_message(struct cdout ("read_partial_message con %p msg %p\n" , con, m);/* header */ - to =0 ; - ret =read_partial (con, &to,sizeof (con->in_hdr), &con->in_hdr); + ret =read_partial (con,0 ,sizeof (con->in_hdr), &con->in_hdr);if (ret <=0 )return ret;
@@ -1755,7 +1756,7 @@ static int read_partial_message(struct c/* footer */ to =sizeof (m->hdr); - ret =read_partial (con, &to,sizeof (m->footer), &m->footer); + ret =read_partial (con, to,sizeof (m->footer), &m->footer);if (ret <=0 )return ret;
Greg Kroah-Hartman
maintainerPATCH 64/171 ceph: messenger: change read_partial() to take "end" arg
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit fd51653f78cf40a0516e521b6de22f329c5bad8d)
Make the second argument to read_partial() be the ending input byte position rather than the beginning offset it now represents. This amounts to moving the addition "to + size" into the caller.
--- net/ceph/messenger.c | 60 ++++++++++++++++++++++++++++++++------------------- 1 file changed, 38 insertions(+), 22 deletions(-)
net/ceph/messenger.c +38 -22
@@ -992,10 +992,8 @@ static int prepare_read_message(struct cstatic int read_partial (struct ceph_connection *con, -int to,int size,void *object) +int end,int size,void *object) { -int end = to + size; -while (con->in_base_pos < end) {int left = end - con->in_base_pos;int have = size - left;
@@ -1013,40 +1011,52 @@ static int read_partial(struct ceph_conn*/ static int read_partial_banner (struct ceph_connection *con) { -int ret, to =0 ; +int size; +int end; +int ret;dout ("read_partial_banner %p at %d\n" , con, con->in_base_pos);/* peer's banner */ - ret =read_partial (con, to,strlen (CEPH_BANNER ), con->in_banner); + size =strlen (CEPH_BANNER ); + end = size; + ret =read_partial (con, end, size, con->in_banner);if (ret <=0 ) goto out; - to +=strlen (CEPH_BANNER ); - ret =read_partial (con, to,sizeof (con->actual_peer_addr), - &con->actual_peer_addr); + + size =sizeof (con->actual_peer_addr); + end += size; + ret =read_partial (con, end, size, &con->actual_peer_addr);if (ret <=0 ) goto out; - to +=sizeof (con->actual_peer_addr); - ret =read_partial (con, to,sizeof (con->peer_addr_for_me), - &con->peer_addr_for_me); + + size =sizeof (con->peer_addr_for_me); + end += size; + ret =read_partial (con, end, size, &con->peer_addr_for_me);if (ret <=0 ) goto out; + out:return ret; }static int read_partial_connect (struct ceph_connection *con) { -int ret, to =0 ; +int size; +int end; +int ret;dout ("read_partial_connect %p at %d\n" , con, con->in_base_pos); - ret =read_partial (con, to,sizeof (con->in_reply), &con->in_reply); + size =sizeof (con->in_reply); + end = size; + ret =read_partial (con, end, size, &con->in_reply);if (ret <=0 ) goto out; - to +=sizeof (con->in_reply); - ret =read_partial (con, to,le32_to_cpu (con->in_reply.authorizer_len), - con->auth_reply_buf); + + size =le32_to_cpu (con->in_reply.authorizer_len); + end += size; + ret =read_partial (con, end, size, con->auth_reply_buf);if (ret <=0 ) goto out;
@@ -1495,8 +1505,10 @@ static int process_connect(struct ceph_c*/ static int read_partial_ack (struct ceph_connection *con) { -return read_partial (con,0 ,sizeof (con->in_temp_ack), - &con->in_temp_ack); +int size =sizeof (con->in_temp_ack); +int end = size; + +return read_partial (con, end, size, &con->in_temp_ack); }
@@ -1629,8 +1641,9 @@ static int read_partial_message_bio(strustatic int read_partial_message (struct ceph_connection *con) {struct ceph_msg *m = con->in_msg; +int size; +int end;int ret; -int to;unsigned front_len, middle_len, data_len;bool do_datacrc = !con->msgr->nocrc;int skip;
@@ -1640,7 +1653,9 @@ static int read_partial_message(struct cdout ("read_partial_message con %p msg %p\n" , con, m);/* header */ - ret =read_partial (con,0 ,sizeof (con->in_hdr), &con->in_hdr); + size =sizeof (con->in_hdr); + end = size; + ret =read_partial (con, end, size, &con->in_hdr);if (ret <=0 )return ret;
@@ -1755,8 +1770,9 @@ static int read_partial_message(struct c }/* footer */ - to =sizeof (m->hdr); - ret =read_partial (con, to,sizeof (m->footer), &m->footer); + size =sizeof (m->footer); + end += size; + ret =read_partial (con, end, size, &m->footer);if (ret <=0 )return ret;
Greg Kroah-Hartman
maintainerPATCH 65/171 libceph: dont reset kvec in prepare_write_banner()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit d329156f16306449c273002486c28de3ddddfd89)
Move the kvec reset for a connection out of prepare_write_banner and into its only caller.
--- net/ceph/messenger.c | 4 +--- 1 file changed, 1 insertion(+), 3 deletions(-)
net/ceph/messenger.c +1 -3
@@ -686,7 +686,6 @@ static int prepare_connect_authorizer(ststatic void prepare_write_banner (struct ceph_messenger *msgr,struct ceph_connection *con) { -ceph_con_out_kvec_reset (con);ceph_con_out_kvec_add (con,strlen (CEPH_BANNER ),CEPH_BANNER );ceph_con_out_kvec_add (con,sizeof (msgr->my_enc_addr), &msgr->my_enc_addr);
@@ -726,10 +725,9 @@ static int prepare_write_connect(struct con->out_connect.protocol_version =cpu_to_le32 (proto); con->out_connect.flags =0 ; +ceph_con_out_kvec_reset (con);if (include_banner)prepare_write_banner (msgr, con); -else -ceph_con_out_kvec_reset (con);ceph_con_out_kvec_add (con,sizeof (con->out_connect), &con->out_connect); con->out_more =0 ;
Greg Kroah-Hartman
maintainerPATCH 66/171 ceph: messenger: reset connection kvec caller
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 84fb3adf6413862cff51d8af3fce5f0b655586a2)
Reset a connection's kvec fields in the caller rather than inprepare_write_connect(). This ends up repeating a few lines of
code but it's improving the separation between distinct operations on the connection, which we can take advantage of later.
--- net/ceph/messenger.c | 6 +++++- 1 file changed, 5 insertions(+), 1 deletion(-)
net/ceph/messenger.c +5 -1
@@ -725,7 +725,6 @@ static int prepare_write_connect(struct con->out_connect.protocol_version =cpu_to_le32 (proto); con->out_connect.flags =0 ; -ceph_con_out_kvec_reset (con);if (include_banner)prepare_write_banner (msgr, con);ceph_con_out_kvec_add (con,sizeof (con->out_connect), &con->out_connect);
@@ -1389,6 +1388,7 @@ static int process_connect(struct ceph_creturn -1 ; } con->auth_retry =1 ; +ceph_con_out_kvec_reset (con); ret =prepare_write_connect (con->msgr, con,0 );if (ret <0 )return ret;
@@ -1409,6 +1409,7 @@ static int process_connect(struct ceph_cENTITY_NAME (con->peer_name), ceph_pr_addr(&con->peer_addr.in_addr));reset_connection (con); +ceph_con_out_kvec_reset (con);prepare_write_connect (con->msgr, con,0 );prepare_read_connect (con);
@@ -1432,6 +1433,7 @@ static int process_connect(struct ceph_cle32_to_cpu (con->out_connect.connect_seq), le32_to_cpu(con->in_connect.connect_seq)); con->connect_seq =le32_to_cpu (con->in_connect.connect_seq); +ceph_con_out_kvec_reset (con);prepare_write_connect (con->msgr, con,0 );prepare_read_connect (con);break ;
@@ -1446,6 +1448,7 @@ static int process_connect(struct ceph_c le32_to_cpu(con->in_connect.global_seq));get_global_seq (con->msgr,le32_to_cpu (con->in_connect.global_seq)); +ceph_con_out_kvec_reset (con);prepare_write_connect (con->msgr, con,0 );prepare_read_connect (con);break ;
@@ -1851,6 +1854,7 @@ more:/* open the socket first? */ if (con->sock ==NULL ) { +ceph_con_out_kvec_reset (con);prepare_write_connect (msgr, con,1 );prepare_read_banner (con);set_bit (CONNECTING , &con->state);
Greg Kroah-Hartman
maintainerPATCH 67/171 ceph: messenger: send banner in process_connect()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 41b90c00858129f52d08e6a05c9cfdb0f2bd074d)
prepare_write_connect() has an argument indicating whether a banner should be sent out before sending out a connection message. It's only ever set in one of its callers, so move the code that arranges to send the banner into that caller and drop the "include_banner" argument from prepare_write_connect().
--- net/ceph/messenger.c | 16 +++++++--------- 1 file changed, 7 insertions(+), 9 deletions(-)
net/ceph/messenger.c +7 -9
@@ -695,8 +695,7 @@ static void prepare_write_banner(struct }static int prepare_write_connect (struct ceph_messenger *msgr, -struct ceph_connection *con, -int include_banner) +struct ceph_connection *con) {unsigned global_seq =get_global_seq (con->msgr,0 );int proto;
@@ -725,8 +724,6 @@ static int prepare_write_connect(struct con->out_connect.protocol_version =cpu_to_le32 (proto); con->out_connect.flags =0 ; -if (include_banner) -prepare_write_banner (msgr, con);ceph_con_out_kvec_add (con,sizeof (con->out_connect), &con->out_connect); con->out_more =0 ;
@@ -1389,7 +1386,7 @@ static int process_connect(struct ceph_c } con->auth_retry =1 ;ceph_con_out_kvec_reset (con); - ret =prepare_write_connect (con->msgr, con,0 ); + ret =prepare_write_connect (con->msgr, con);if (ret <0 )return ret;prepare_read_connect (con);
@@ -1410,7 +1407,7 @@ static int process_connect(struct ceph_c ceph_pr_addr(&con->peer_addr.in_addr));reset_connection (con);ceph_con_out_kvec_reset (con); -prepare_write_connect (con->msgr, con,0 ); +prepare_write_connect (con->msgr, con);prepare_read_connect (con);/* Tell ceph about it. */
@@ -1434,7 +1431,7 @@ static int process_connect(struct ceph_c le32_to_cpu(con->in_connect.connect_seq)); con->connect_seq =le32_to_cpu (con->in_connect.connect_seq);ceph_con_out_kvec_reset (con); -prepare_write_connect (con->msgr, con,0 ); +prepare_write_connect (con->msgr, con);prepare_read_connect (con);break ;
@@ -1449,7 +1446,7 @@ static int process_connect(struct ceph_cget_global_seq (con->msgr,le32_to_cpu (con->in_connect.global_seq));ceph_con_out_kvec_reset (con); -prepare_write_connect (con->msgr, con,0 ); +prepare_write_connect (con->msgr, con);prepare_read_connect (con);break ;
@@ -1855,7 +1852,8 @@ more:/* open the socket first? */ if (con->sock ==NULL ) {ceph_con_out_kvec_reset (con); -prepare_write_connect (msgr, con,1 ); +prepare_write_banner (msgr, con); +prepare_write_connect (msgr, con);prepare_read_banner (con);set_bit (CONNECTING , &con->state);clear_bit (NEGOTIATING , &con->state);
Greg Kroah-Hartman
maintainerPATCH 68/171 ceph: drop msgr argument from prepare_write_connect()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit e825a66df97776d30a48a187e3a986736af43945)
In all cases, the value passed as the msgr argument to prepare_write_connect() is just con->msgr. Just get the msgr value from the ceph connection and drop the unneeded argument.
The only msgr passed to prepare_write_banner() is also therefore just the one from con->msgr, so change that function to drop the msgr argument as well.
--- net/ceph/messenger.c | 25 +++++++++++-------------- 1 file changed, 11 insertions(+), 14 deletions(-)
net/ceph/messenger.c +11 -14
@@ -683,19 +683,17 @@ static int prepare_connect_authorizer(st/* * We connected to a peer and are saying hello. */ -static void prepare_write_banner (struct ceph_messenger *msgr, -struct ceph_connection *con) +static void prepare_write_banner (struct ceph_connection *con) {ceph_con_out_kvec_add (con,strlen (CEPH_BANNER ),CEPH_BANNER ); -ceph_con_out_kvec_add (con,sizeof (msgr->my_enc_addr), - &msgr->my_enc_addr); +ceph_con_out_kvec_add (con,sizeof (con->msgr->my_enc_addr), + &con->msgr->my_enc_addr); con->out_more =0 ;set_bit (WRITE_PENDING , &con->state); } -static int prepare_write_connect (struct ceph_messenger *msgr, -struct ceph_connection *con) +static int prepare_write_connect (struct ceph_connection *con) {unsigned global_seq =get_global_seq (con->msgr,0 );int proto;
@@ -717,7 +715,7 @@ static int prepare_write_connect(structdout ("prepare_write_connect %p cseq=%d gseq=%d proto=%d\n" , con, con->connect_seq, global_seq, proto); - con->out_connect.features =cpu_to_le64 (msgr->supported_features); + con->out_connect.features =cpu_to_le64 (con->msgr->supported_features); con->out_connect.host_type =cpu_to_le32 (CEPH_ENTITY_TYPE_CLIENT ); con->out_connect.connect_seq =cpu_to_le32 (con->connect_seq); con->out_connect.global_seq =cpu_to_le32 (global_seq);
@@ -1386,7 +1384,7 @@ static int process_connect(struct ceph_c } con->auth_retry =1 ;ceph_con_out_kvec_reset (con); - ret =prepare_write_connect (con->msgr, con); + ret =prepare_write_connect (con);if (ret <0 )return ret;prepare_read_connect (con);
@@ -1407,7 +1405,7 @@ static int process_connect(struct ceph_c ceph_pr_addr(&con->peer_addr.in_addr));reset_connection (con);ceph_con_out_kvec_reset (con); -prepare_write_connect (con->msgr, con); +prepare_write_connect (con);prepare_read_connect (con);/* Tell ceph about it. */
@@ -1431,7 +1429,7 @@ static int process_connect(struct ceph_c le32_to_cpu(con->in_connect.connect_seq)); con->connect_seq =le32_to_cpu (con->in_connect.connect_seq);ceph_con_out_kvec_reset (con); -prepare_write_connect (con->msgr, con); +prepare_write_connect (con);prepare_read_connect (con);break ;
@@ -1446,7 +1444,7 @@ static int process_connect(struct ceph_cget_global_seq (con->msgr,le32_to_cpu (con->in_connect.global_seq));ceph_con_out_kvec_reset (con); -prepare_write_connect (con->msgr, con); +prepare_write_connect (con);prepare_read_connect (con);break ;
@@ -1840,7 +1838,6 @@ static void process_message(struct ceph_*/ static int try_write (struct ceph_connection *con) { -struct ceph_messenger *msgr = con->msgr;int ret =1 ; dout("try_write start %p state %lu nref %d\n", con, con->state,
@@ -1852,8 +1849,8 @@ more:/* open the socket first? */ if (con->sock ==NULL ) {ceph_con_out_kvec_reset (con); -prepare_write_banner (msgr, con); -prepare_write_connect (msgr, con); +prepare_write_banner (con); +prepare_write_connect (con);prepare_read_banner (con);set_bit (CONNECTING , &con->state);clear_bit (NEGOTIATING , &con->state);
Greg Kroah-Hartman
maintainerPATCH 69/171 ceph: dont set WRITE_PENDING too early
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit e10c758e4031a801ea4d2f8fb39bf14c2658d74b)
prepare_write_connect() prepares a connect message, then sets WRITE_PENDING on the connection. Then *after* this, it calls prepare_connect_authorizer(), which updates the content of the connection buffer already queued for sending. It's also possible it will result in prepare_write_connect() returning -EAGAIN despite the WRITE_PENDING big getting set.
Fix this by preparing the connect authorizer first, setting the WRITE_PENDING bit only after that is done.
Partially addresses http://tracker.newdream.net/issues/2424
--- net/ceph/messenger.c | 6 +++++- 1 file changed, 5 insertions(+), 1 deletion(-)
net/ceph/messenger.c +5 -1
@@ -697,6 +697,7 @@ static int prepare_write_connect(struct {unsigned global_seq =get_global_seq (con->msgr,0 );int proto; +int ret;switch (con->peer_name.type) {case CEPH_ENTITY_TYPE_MON :
@@ -723,11 +724,14 @@ static int prepare_write_connect(struct con->out_connect.flags =0 ;ceph_con_out_kvec_add (con,sizeof (con->out_connect), &con->out_connect); + ret =prepare_connect_authorizer (con); +if (ret) +return ret; con->out_more =0 ;set_bit (WRITE_PENDING , &con->state); -return prepare_connect_authorizer (con); +return 0 ; }/*
Greg Kroah-Hartman
maintainerPATCH 70/171 ceph: messenger: check prepare_write_connect() result
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 5a0f8fdd8a0ebe320952a388331dc043d7e14ced)
prepare_write_connect() can return an error, but only one of its callers checks for it. All the rest are in functions that already return errors, so it should be fine to return the error if one gets returned.
--- net/ceph/messenger.c | 16 ++++++++++++---- 1 file changed, 12 insertions(+), 4 deletions(-)
net/ceph/messenger.c +12 -4
@@ -1409,7 +1409,9 @@ static int process_connect(struct ceph_c ceph_pr_addr(&con->peer_addr.in_addr));reset_connection (con);ceph_con_out_kvec_reset (con); -prepare_write_connect (con); + ret =prepare_write_connect (con); +if (ret <0 ) +return ret;prepare_read_connect (con);/* Tell ceph about it. */
@@ -1433,7 +1435,9 @@ static int process_connect(struct ceph_c le32_to_cpu(con->in_connect.connect_seq)); con->connect_seq =le32_to_cpu (con->in_connect.connect_seq);ceph_con_out_kvec_reset (con); -prepare_write_connect (con); + ret =prepare_write_connect (con); +if (ret <0 ) +return ret;prepare_read_connect (con);break ;
@@ -1448,7 +1452,9 @@ static int process_connect(struct ceph_cget_global_seq (con->msgr,le32_to_cpu (con->in_connect.global_seq));ceph_con_out_kvec_reset (con); -prepare_write_connect (con); + ret =prepare_write_connect (con); +if (ret <0 ) +return ret;prepare_read_connect (con);break ;
@@ -1854,7 +1860,9 @@ more:if (con->sock ==NULL ) {ceph_con_out_kvec_reset (con);prepare_write_banner (con); -prepare_write_connect (con); + ret =prepare_write_connect (con); +if (ret <0 ) + goto out;prepare_read_banner (con);set_bit (CONNECTING , &con->state);clear_bit (NEGOTIATING , &con->state);
Greg Kroah-Hartman
maintainerPATCH 71/171 ceph: messenger: rework prepare_connect_authorizer()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit b1c6b9803f5491e94041e6da96bc9dec3870e792)
Change prepare_connect_authorizer() so it returns without dropping the connection mutex if the connection has no get_authorizer method.
Use the symbolic CEPH_AUTH_UNKNOWN instead of 0 when assigning authorization protocols.
--- net/ceph/messenger.c | 28 +++++++++++++++++++--------- 1 file changed, 19 insertions(+), 9 deletions(-)
net/ceph/messenger.c +19 -9
@@ -656,19 +656,29 @@ static void prepare_write_keepalive(strustatic int prepare_connect_authorizer (struct ceph_connection *con) {void *auth_buf; -int auth_len =0 ; -int auth_protocol =0 ; +int auth_len; +int auth_protocol; + +if (!con->ops->get_authorizer) { + con->out_connect.authorizer_protocol =CEPH_AUTH_UNKNOWN ; + con->out_connect.authorizer_len =0 ; + +return 0 ; + } + +/* Can't hold the mutex while getting authorizer */ mutex_unlock (&con->mutex); -if (con->ops->get_authorizer) - con->ops->get_authorizer (con, &auth_buf, &auth_len, - &auth_protocol, &con->auth_reply_buf, - &con->auth_reply_buf_len, - con->auth_retry); + + auth_buf =NULL ; + auth_len =0 ; + auth_protocol =CEPH_AUTH_UNKNOWN ; + con->ops->get_authorizer (con, &auth_buf, &auth_len, &auth_protocol, + &con->auth_reply_buf, &con->auth_reply_buf_len, + con->auth_retry);mutex_lock (&con->mutex); -if (test_bit (CLOSED , &con->state) || -test_bit (OPENING , &con->state)) +if (test_bit (CLOSED , &con->state) ||test_bit (OPENING , &con->state))return -EAGAIN ; con->out_connect.authorizer_protocol =cpu_to_le32 (auth_protocol);
Greg Kroah-Hartman
maintainerPATCH 72/171 ceph: messenger: check return from get_authorizer
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit ed96af646011412c2bf1ffe860db170db355fae5)
In prepare_connect_authorizer(), a connection's get_authorizer method is called but ignores its return value. This function can return an error, so check for it and return it if that ever occurs.
--- net/ceph/messenger.c | 10 +++++++--- 1 file changed, 7 insertions(+), 3 deletions(-)
net/ceph/messenger.c +7 -3
@@ -658,6 +658,7 @@ static int prepare_connect_authorizer(stvoid *auth_buf;int auth_len;int auth_protocol; +int ret;if (!con->ops->get_authorizer) { con->out_connect.authorizer_protocol =CEPH_AUTH_UNKNOWN ;
@@ -673,11 +674,14 @@ static int prepare_connect_authorizer(st auth_buf =NULL ; auth_len =0 ; auth_protocol =CEPH_AUTH_UNKNOWN ; - con->ops->get_authorizer (con, &auth_buf, &auth_len, &auth_protocol, - &con->auth_reply_buf, &con->auth_reply_buf_len, - con->auth_retry); + ret = con->ops->get_authorizer (con, &auth_buf, &auth_len, + &auth_protocol, &con->auth_reply_buf, + &con->auth_reply_buf_len, con->auth_retry);mutex_lock (&con->mutex); +if (ret) +return ret; +if (test_bit (CLOSED , &con->state) ||test_bit (OPENING , &con->state))return -EAGAIN ;
Greg Kroah-Hartman
maintainerPATCH 73/171 ceph: define ceph_auth_handshake type
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 6c4a19158b96ea1fb8acbe0c1d5493d9dcd2f147)
The definitions for the ceph_mds_session and ceph_osd both contain five fields related only to "authorizers." Encapsulate those fields into their own struct type, allowing for better isolation in some upcoming patches.
Fix the #includes in "linux/ceph/osd_client.h" to lay out their more complete canonical path.
--- fs/ceph/mds_client.c | 32 ++++++++++++++++---------------- fs/ceph/mds_client.h | 5 ++--- include/linux/ceph/auth.h | 8 ++++++++ include/linux/ceph/osd_client.h | 11 +++++------ net/ceph/osd_client.c | 32 ++++++++++++++++---------------- 5 files changed, 47 insertions(+), 41 deletions(-)
fs/ceph/mds_client.c +16 -16
@@ -334,10 +334,10 @@ void ceph_put_mds_session(struct ceph_mddout ("mdsc put_session %p %d -> %d\n" , s,atomic_read (&s->s_ref),atomic_read (&s->s_ref)-1 );if (atomic_dec_and_test (&s->s_ref)) { -if (s->s_authorizer) +if (s->s_auth.authorizer) s->s_mdsc->fsc->client->monc.auth->ops->destroy_authorizer ( s->s_mdsc->fsc->client->monc.auth, - s->s_authorizer); + s->s_auth.authorizer);kfree (s); } }
@@ -3404,29 +3404,29 @@ static int get_authorizer(struct ceph_costruct ceph_auth_client *ac = mdsc->fsc->client->monc.auth;int ret =0 ; -if (force_new && s->s_authorizer) { - ac->ops->destroy_authorizer (ac, s->s_authorizer); - s->s_authorizer =NULL ; +if (force_new && s->s_auth.authorizer) { + ac->ops->destroy_authorizer (ac, s->s_auth.authorizer); + s->s_auth.authorizer =NULL ; } -if (s->s_authorizer ==NULL ) { +if (s->s_auth.authorizer ==NULL ) {if (ac->ops->create_authorizer) { ret = ac->ops->create_authorizer ( ac,CEPH_ENTITY_TYPE_MDS , - &s->s_authorizer, - &s->s_authorizer_buf, - &s->s_authorizer_buf_len, - &s->s_authorizer_reply_buf, - &s->s_authorizer_reply_buf_len); + &s->s_auth.authorizer, + &s->s_auth.authorizer_buf, + &s->s_auth.authorizer_buf_len, + &s->s_auth.authorizer_reply_buf, + &s->s_auth.authorizer_reply_buf_len);if (ret)return ret; } } *proto = ac->protocol; - *buf = s->s_authorizer_buf; - *len = s->s_authorizer_buf_len; - *reply_buf = s->s_authorizer_reply_buf; - *reply_len = s->s_authorizer_reply_buf_len; + *buf = s->s_auth.authorizer_buf; + *len = s->s_auth.authorizer_buf_len; + *reply_buf = s->s_auth.authorizer_reply_buf; + *reply_len = s->s_auth.authorizer_reply_buf_len;return 0 ; }
@@ -3437,7 +3437,7 @@ static int verify_authorizer_reply(strucstruct ceph_mds_client *mdsc = s->s_mdsc;struct ceph_auth_client *ac = mdsc->fsc->client->monc.auth; -return ac->ops->verify_authorizer_reply (ac, s->s_authorizer, len); +return ac->ops->verify_authorizer_reply (ac, s->s_auth.authorizer, len); }static int invalidate_authorizer (struct ceph_connection *con)
fs/ceph/mds_client.h +2 -3
@@ -11,6 +11,7 @@#include <linux/ceph/types.h> #include <linux/ceph/messenger.h> #include <linux/ceph/mdsmap.h> +#include <linux/ceph/auth.h> /* * Some lock dependencies:
@@ -113,9 +114,7 @@ struct ceph_mds_session {struct ceph_connection s_con; -struct ceph_authorizer *s_authorizer; -void *s_authorizer_buf, *s_authorizer_reply_buf; -size_t s_authorizer_buf_len, s_authorizer_reply_buf_len; +struct ceph_auth_handshake s_auth;/* protected by s_gen_ttl_lock */ spinlock_t s_gen_ttl_lock;
include/linux/ceph/auth.h +8 -0
@@ -14,6 +14,14 @@struct ceph_auth_client ;struct ceph_authorizer ; +struct ceph_auth_handshake { +struct ceph_authorizer *authorizer; +void *authorizer_buf; +size_t authorizer_buf_len; +void *authorizer_reply_buf; +size_t authorizer_reply_buf_len; +}; +struct ceph_auth_client_ops {const char *name;
include/linux/ceph/osd_client.h +5 -6
@@ -6,9 +6,10 @@#include <linux/mempool.h> #include <linux/rbtree.h> -#include "types.h" -#include "osdmap.h" -#include "messenger.h" +#include <linux/ceph/types.h> +#include <linux/ceph/osdmap.h> +#include <linux/ceph/messenger.h> +#include <linux/ceph/auth.h> /* * Maximum object name size
@@ -40,9 +41,7 @@ struct ceph_osd {struct list_head o_requests;struct list_head o_linger_requests;struct list_head o_osd_lru; -struct ceph_authorizer *o_authorizer; -void *o_authorizer_buf, *o_authorizer_reply_buf; -size_t o_authorizer_buf_len, o_authorizer_reply_buf_len; +struct ceph_auth_handshake o_auth;unsigned long lru_ttl;int o_marked_for_keepalive;struct list_head o_keepalive_item;
net/ceph/osd_client.c +16 -16
@@ -667,8 +667,8 @@ static void put_osd(struct ceph_osd *osdif (atomic_dec_and_test (&osd->o_ref)) {struct ceph_auth_client *ac = osd->o_osdc->client->monc.auth; -if (osd->o_authorizer) - ac->ops->destroy_authorizer (ac, osd->o_authorizer); +if (osd->o_auth.authorizer) + ac->ops->destroy_authorizer (ac, osd->o_auth.authorizer);kfree (osd); } }
@@ -2117,27 +2117,27 @@ static int get_authorizer(struct ceph_costruct ceph_auth_client *ac = osdc->client->monc.auth;int ret =0 ; -if (force_new && o->o_authorizer) { - ac->ops->destroy_authorizer (ac, o->o_authorizer); - o->o_authorizer =NULL ; +if (force_new && o->o_auth.authorizer) { + ac->ops->destroy_authorizer (ac, o->o_auth.authorizer); + o->o_auth.authorizer =NULL ; } -if (o->o_authorizer ==NULL ) { +if (o->o_auth.authorizer ==NULL ) { ret = ac->ops->create_authorizer ( ac,CEPH_ENTITY_TYPE_OSD , - &o->o_authorizer, - &o->o_authorizer_buf, - &o->o_authorizer_buf_len, - &o->o_authorizer_reply_buf, - &o->o_authorizer_reply_buf_len); + &o->o_auth.authorizer, + &o->o_auth.authorizer_buf, + &o->o_auth.authorizer_buf_len, + &o->o_auth.authorizer_reply_buf, + &o->o_auth.authorizer_reply_buf_len);if (ret)return ret; } *proto = ac->protocol; - *buf = o->o_authorizer_buf; - *len = o->o_authorizer_buf_len; - *reply_buf = o->o_authorizer_reply_buf; - *reply_len = o->o_authorizer_reply_buf_len; + *buf = o->o_auth.authorizer_buf; + *len = o->o_auth.authorizer_buf_len; + *reply_buf = o->o_auth.authorizer_reply_buf; + *reply_len = o->o_auth.authorizer_reply_buf_len;return 0 ; }
@@ -2148,7 +2148,7 @@ static int verify_authorizer_reply(strucstruct ceph_osd_client *osdc = o->o_osdc;struct ceph_auth_client *ac = osdc->client->monc.auth; -return ac->ops->verify_authorizer_reply (ac, o->o_authorizer, len); +return ac->ops->verify_authorizer_reply (ac, o->o_auth.authorizer, len); }static int invalidate_authorizer (struct ceph_connection *con)
Greg Kroah-Hartman
maintainerPATCH 74/171 ceph: messenger: reduce args to create_authorizer
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 74f1869f76d043bad12ec03b4d5f04a8c3d1f157)
Make use of the new ceph_auth_handshake structure in order to reduce the number of arguments passed to the create_authorizor method in ceph_auth_client_ops. Use a local variable of that type as a shorthand in the get_authorizer method definitions.
--- fs/ceph/mds_client.c | 27 ++++++++++++--------------- include/linux/ceph/auth.h | 4 +--- net/ceph/auth_none.c | 15 +++++++-------- net/ceph/auth_x.c | 15 +++++++-------- net/ceph/osd_client.c | 26 +++++++++++--------------- 5 files changed, 38 insertions(+), 49 deletions(-)
fs/ceph/mds_client.c +12 -15
@@ -3402,31 +3402,28 @@ static int get_authorizer(struct ceph_costruct ceph_mds_session *s = con->private;struct ceph_mds_client *mdsc = s->s_mdsc;struct ceph_auth_client *ac = mdsc->fsc->client->monc.auth; +struct ceph_auth_handshake *auth = &s->s_auth;int ret =0 ; -if (force_new && s->s_auth.authorizer) { - ac->ops->destroy_authorizer (ac, s->s_auth.authorizer); - s->s_auth.authorizer =NULL ; +if (force_new && auth->authorizer) { + ac->ops->destroy_authorizer (ac, auth->authorizer); + auth->authorizer =NULL ; } -if (s->s_auth.authorizer ==NULL ) { +if (auth->authorizer ==NULL ) {if (ac->ops->create_authorizer) { - ret = ac->ops->create_authorizer ( - ac,CEPH_ENTITY_TYPE_MDS , - &s->s_auth.authorizer, - &s->s_auth.authorizer_buf, - &s->s_auth.authorizer_buf_len, - &s->s_auth.authorizer_reply_buf, - &s->s_auth.authorizer_reply_buf_len); + ret = ac->ops->create_authorizer (ac, +CEPH_ENTITY_TYPE_MDS , auth);if (ret)return ret; } } *proto = ac->protocol; - *buf = s->s_auth.authorizer_buf; - *len = s->s_auth.authorizer_buf_len; - *reply_buf = s->s_auth.authorizer_reply_buf; - *reply_len = s->s_auth.authorizer_reply_buf_len; + *buf = auth->authorizer_buf; + *len = auth->authorizer_buf_len; + *reply_buf = auth->authorizer_reply_buf; + *reply_len = auth->authorizer_reply_buf_len; +return 0 ; }
include/linux/ceph/auth.h +1 -3
@@ -51,9 +51,7 @@ struct ceph_auth_client_ops {* the response to authenticate the service. */ int (*create_authorizer)(struct ceph_auth_client *ac,int peer_type, -struct ceph_authorizer **a, -void **buf,size_t *len, -void **reply_buf,size_t *reply_len); +struct ceph_auth_handshake *auth);int (*verify_authorizer_reply)(struct ceph_auth_client *ac,struct ceph_authorizer *a,size_t len); void (*destroy_authorizer)(struct ceph_auth_client *ac,
net/ceph/auth_none.c +7 -8
@@ -59,9 +59,7 @@ static int handle_reply(struct ceph_auth*/ static int ceph_auth_none_create_authorizer (struct ceph_auth_client *ac,int peer_type, -struct ceph_authorizer **a, -void **buf,size_t *len, -void **reply_buf,size_t *reply_len) +struct ceph_auth_handshake *auth) {struct ceph_auth_none_info *ai = ac->private;struct ceph_none_authorizer *au = &ai->au;
@@ -82,11 +80,12 @@ static int ceph_auth_none_create_authoridout ("built authorizer len %d\n" , au->buf_len); } - *a = (struct ceph_authorizer *)au; - *buf = au->buf; - *len = au->buf_len; - *reply_buf = au->reply_buf; - *reply_len =sizeof (au->reply_buf); + auth->authorizer = (struct ceph_authorizer *) au; + auth->authorizer_buf = au->buf; + auth->authorizer_buf_len = au->buf_len; + auth->authorizer_reply_buf = au->reply_buf; + auth->authorizer_reply_buf_len =sizeof (au->reply_buf); +return 0 ; bad2:
net/ceph/auth_x.c +7 -8
@@ -526,9 +526,7 @@ static int ceph_x_handle_reply(struct cestatic int ceph_x_create_authorizer (struct ceph_auth_client *ac,int peer_type, -struct ceph_authorizer **a, -void **buf,size_t *len, -void **reply_buf,size_t *reply_len) +struct ceph_auth_handshake *auth) {struct ceph_x_authorizer *au;struct ceph_x_ticket_handler *th;
@@ -548,11 +546,12 @@ static int ceph_x_create_authorizer(return ret; } - *a = (struct ceph_authorizer *)au; - *buf = au->buf->vec.iov_base; - *len = au->buf->vec.iov_len; - *reply_buf = au->reply_buf; - *reply_len =sizeof (au->reply_buf); + auth->authorizer = (struct ceph_authorizer *) au; + auth->authorizer_buf = au->buf->vec.iov_base; + auth->authorizer_buf_len = au->buf->vec.iov_len; + auth->authorizer_reply_buf = au->reply_buf; + auth->authorizer_reply_buf_len =sizeof (au->reply_buf); +return 0 ; }
net/ceph/osd_client.c +11 -15
@@ -2115,29 +2115,25 @@ static int get_authorizer(struct ceph_costruct ceph_osd *o = con->private;struct ceph_osd_client *osdc = o->o_osdc;struct ceph_auth_client *ac = osdc->client->monc.auth; +struct ceph_auth_handshake *auth = &o->o_auth;int ret =0 ; -if (force_new && o->o_auth.authorizer) { - ac->ops->destroy_authorizer (ac, o->o_auth.authorizer); - o->o_auth.authorizer =NULL ; +if (force_new && auth->authorizer) { + ac->ops->destroy_authorizer (ac, auth->authorizer); + auth->authorizer =NULL ; } -if (o->o_auth.authorizer ==NULL ) { - ret = ac->ops->create_authorizer ( - ac,CEPH_ENTITY_TYPE_OSD , - &o->o_auth.authorizer, - &o->o_auth.authorizer_buf, - &o->o_auth.authorizer_buf_len, - &o->o_auth.authorizer_reply_buf, - &o->o_auth.authorizer_reply_buf_len); +if (auth->authorizer ==NULL ) { + ret = ac->ops->create_authorizer (ac,CEPH_ENTITY_TYPE_OSD , auth);if (ret)return ret; } *proto = ac->protocol; - *buf = o->o_auth.authorizer_buf; - *len = o->o_auth.authorizer_buf_len; - *reply_buf = o->o_auth.authorizer_reply_buf; - *reply_len = o->o_auth.authorizer_reply_buf_len; + *buf = auth->authorizer_buf; + *len = auth->authorizer_buf_len; + *reply_buf = auth->authorizer_reply_buf; + *reply_len = auth->authorizer_reply_buf_len; +return 0 ; }
Greg Kroah-Hartman
maintainerPATCH 75/171 ceph: ensure auth ops are defined before use
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit a255651d4cad89f1a606edd36135af892ada4f20)
In the create_authorizer method for both the mds and osd clients, the auth_client->ops pointer is blindly dereferenced. There is no obvious guarantee that this pointer has been assigned. And furthermore, even if the ops pointer is non-null there is definitely no guarantee that the create_authorizer or destroy_authorizer methods are defined.
Add checks in both routines to make sure they are defined (non-null) before use. Add similar checks in a few other spots in these files while we're at it.
--- fs/ceph/mds_client.c | 14 ++++++-------- net/ceph/osd_client.c | 15 ++++++++++----- 2 files changed, 16 insertions(+), 13 deletions(-)
fs/ceph/mds_client.c +6 -8
@@ -3406,16 +3406,14 @@ static int get_authorizer(struct ceph_coint ret =0 ;if (force_new && auth->authorizer) { - ac->ops->destroy_authorizer (ac, auth->authorizer); +if (ac->ops && ac->ops->destroy_authorizer) + ac->ops->destroy_authorizer (ac, auth->authorizer); auth->authorizer =NULL ; } -if (auth->authorizer ==NULL ) { -if (ac->ops->create_authorizer) { - ret = ac->ops->create_authorizer (ac, -CEPH_ENTITY_TYPE_MDS , auth); -if (ret) -return ret; - } +if (!auth->authorizer && ac->ops && ac->ops->create_authorizer) { + ret = ac->ops->create_authorizer (ac,CEPH_ENTITY_TYPE_MDS , auth); +if (ret) +return ret; } *proto = ac->protocol;
net/ceph/osd_client.c +10 -5
@@ -664,10 +664,10 @@ static void put_osd(struct ceph_osd *osd {dout ("put_osd %p %d -> %d\n" , osd,atomic_read (&osd->o_ref),atomic_read (&osd->o_ref) -1 ); -if (atomic_dec_and_test (&osd->o_ref)) { +if (atomic_dec_and_test (&osd->o_ref) && osd->o_auth.authorizer) {struct ceph_auth_client *ac = osd->o_osdc->client->monc.auth; -if (osd->o_auth.authorizer) +if (ac->ops && ac->ops->destroy_authorizer) ac->ops->destroy_authorizer (ac, osd->o_auth.authorizer);kfree (osd); }
@@ -2119,10 +2119,11 @@ static int get_authorizer(struct ceph_coint ret =0 ;if (force_new && auth->authorizer) { - ac->ops->destroy_authorizer (ac, auth->authorizer); +if (ac->ops && ac->ops->destroy_authorizer) + ac->ops->destroy_authorizer (ac, auth->authorizer); auth->authorizer =NULL ; } -if (auth->authorizer ==NULL ) { +if (!auth->authorizer && ac->ops && ac->ops->create_authorizer) { ret = ac->ops->create_authorizer (ac,CEPH_ENTITY_TYPE_OSD , auth);if (ret)return ret;
@@ -2144,6 +2145,10 @@ static int verify_authorizer_reply(strucstruct ceph_osd_client *osdc = o->o_osdc;struct ceph_auth_client *ac = osdc->client->monc.auth; +/* +* XXX If ac->ops or ac->ops->verify_authorizer_reply is null, +* XXX which do we do: succeed or fail? +*/ return ac->ops->verify_authorizer_reply (ac, o->o_auth.authorizer, len); }
@@ -2153,7 +2158,7 @@ static int invalidate_authorizer(structstruct ceph_osd_client *osdc = o->o_osdc;struct ceph_auth_client *ac = osdc->client->monc.auth; -if (ac->ops->invalidate_authorizer) +if (ac->ops && ac->ops->invalidate_authorizer) ac->ops->invalidate_authorizer (ac,CEPH_ENTITY_TYPE_OSD );return ceph_monc_validate_auth (&osdc->client->monc);
Greg Kroah-Hartman
maintainerPATCH 76/171 ceph: have get_authorizer methods return pointers
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit a3530df33eb91d787d08c7383a0a9982690e42d0)
Have the get_authorizer auth_client method return a ceph_auth pointer rather than an integer, pointer-encoding any returned error value. This is to pave the way for making use of the returned value in an upcoming patch.
--- fs/ceph/mds_client.c | 20 +++++++++++++------- include/linux/ceph/messenger.h | 8 +++++--- net/ceph/messenger.c | 8 ++++---- net/ceph/osd_client.c | 19 ++++++++++++------- 4 files changed, 34 insertions(+), 21 deletions(-)
fs/ceph/mds_client.c +13 -7
@@ -3395,15 +3395,20 @@ out:/* * authentication */ -static int get_authorizer (struct ceph_connection *con, -void **buf,int *len,int *proto, -void **reply_buf,int *reply_len,int force_new) + +/* +* Note: returned pointer is the address of a structure that's +* managed separately. Caller must *not* attempt to free it. +*/ +static struct ceph_auth_handshake *get_authorizer (struct ceph_connection *con, +void **buf,int *len,int *proto, +void **reply_buf,int *reply_len, +int force_new) {struct ceph_mds_session *s = con->private;struct ceph_mds_client *mdsc = s->s_mdsc;struct ceph_auth_client *ac = mdsc->fsc->client->monc.auth;struct ceph_auth_handshake *auth = &s->s_auth; -int ret =0 ;if (force_new && auth->authorizer) {if (ac->ops && ac->ops->destroy_authorizer)
@@ -3411,9 +3416,10 @@ static int get_authorizer(struct ceph_co auth->authorizer =NULL ; }if (!auth->authorizer && ac->ops && ac->ops->create_authorizer) { - ret = ac->ops->create_authorizer (ac,CEPH_ENTITY_TYPE_MDS , auth); +int ret = ac->ops->create_authorizer (ac,CEPH_ENTITY_TYPE_MDS , + auth);if (ret) -return ret; +return ERR_PTR (ret); } *proto = ac->protocol;
@@ -3422,7 +3428,7 @@ static int get_authorizer(struct ceph_co *reply_buf = auth->authorizer_reply_buf; *reply_len = auth->authorizer_reply_buf_len; -return 0 ; +return auth; }
include/linux/ceph/messenger.h +5 -3
@@ -25,9 +25,11 @@ struct ceph_connection_operations {void (*dispatch) (struct ceph_connection *con,struct ceph_msg *m);/* authorize an outgoing connection */ -int (*get_authorizer) (struct ceph_connection *con, -void **buf,int *len,int *proto, -void **reply_buf,int *reply_len,int force_new); +struct ceph_auth_handshake *(*get_authorizer) ( +struct ceph_connection *con, +void **buf,int *len,int *proto, +void **reply_buf,int *reply_len, +int force_new);int (*verify_authorizer_reply) (struct ceph_connection *con,int len);int (*invalidate_authorizer)(struct ceph_connection *con);
net/ceph/messenger.c +4 -4
@@ -658,7 +658,7 @@ static int prepare_connect_authorizer(stvoid *auth_buf;int auth_len;int auth_protocol; -int ret; +struct ceph_auth_handshake *auth;if (!con->ops->get_authorizer) { con->out_connect.authorizer_protocol =CEPH_AUTH_UNKNOWN ;
@@ -674,13 +674,13 @@ static int prepare_connect_authorizer(st auth_buf =NULL ; auth_len =0 ; auth_protocol =CEPH_AUTH_UNKNOWN ; - ret = con->ops->get_authorizer (con, &auth_buf, &auth_len, + auth = con->ops->get_authorizer (con, &auth_buf, &auth_len, &auth_protocol, &con->auth_reply_buf, &con->auth_reply_buf_len, con->auth_retry);mutex_lock (&con->mutex); -if (ret) -return ret; +if (IS_ERR (auth)) +return PTR_ERR (auth);if (test_bit (CLOSED , &con->state) ||test_bit (OPENING , &con->state))return -EAGAIN ;
net/ceph/osd_client.c +12 -7
@@ -2108,15 +2108,19 @@ static void put_osd_con(struct ceph_conn/* * authentication */ -static int get_authorizer (struct ceph_connection *con, -void **buf,int *len,int *proto, -void **reply_buf,int *reply_len,int force_new) +/* +* Note: returned pointer is the address of a structure that's +* managed separately. Caller must *not* attempt to free it. +*/ +static struct ceph_auth_handshake *get_authorizer (struct ceph_connection *con, +void **buf,int *len,int *proto, +void **reply_buf,int *reply_len, +int force_new) {struct ceph_osd *o = con->private;struct ceph_osd_client *osdc = o->o_osdc;struct ceph_auth_client *ac = osdc->client->monc.auth;struct ceph_auth_handshake *auth = &o->o_auth; -int ret =0 ;if (force_new && auth->authorizer) {if (ac->ops && ac->ops->destroy_authorizer)
@@ -2124,9 +2128,10 @@ static int get_authorizer(struct ceph_co auth->authorizer =NULL ; }if (!auth->authorizer && ac->ops && ac->ops->create_authorizer) { - ret = ac->ops->create_authorizer (ac,CEPH_ENTITY_TYPE_OSD , auth); +int ret = ac->ops->create_authorizer (ac,CEPH_ENTITY_TYPE_OSD , + auth);if (ret) -return ret; +return ERR_PTR (ret); } *proto = ac->protocol;
@@ -2135,7 +2140,7 @@ static int get_authorizer(struct ceph_co *reply_buf = auth->authorizer_reply_buf; *reply_len = auth->authorizer_reply_buf_len; -return 0 ; +return auth; }
Greg Kroah-Hartman
maintainerPATCH 77/171 ceph: use info returned by get_authorizer
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 8f43fb53894079bf0caab6e348ceaffe7adc651a)
Rather than passing a bunch of arguments to be filled in with the content of the ceph_auth_handshake buffer now returned by the get_authorizer method, just use the returned information in the caller, and drop the unnecessary arguments.
--- fs/ceph/mds_client.c | 9 +-------- include/linux/ceph/messenger.h | 4 +--- net/ceph/messenger.c | 13 +++++++------ net/ceph/osd_client.c | 9 +-------- 4 files changed, 10 insertions(+), 25 deletions(-)
fs/ceph/mds_client.c +1 -8
@@ -3401,9 +3401,7 @@ out:* managed separately. Caller must *not* attempt to free it. */ static struct ceph_auth_handshake *get_authorizer (struct ceph_connection *con, -void **buf,int *len,int *proto, -void **reply_buf,int *reply_len, -int force_new) +int *proto,int force_new) {struct ceph_mds_session *s = con->private;struct ceph_mds_client *mdsc = s->s_mdsc;
@@ -3421,12 +3419,7 @@ static struct ceph_auth_handshake *get_aif (ret)return ERR_PTR (ret); } - *proto = ac->protocol; - *buf = auth->authorizer_buf; - *len = auth->authorizer_buf_len; - *reply_buf = auth->authorizer_reply_buf; - *reply_len = auth->authorizer_reply_buf_len;return auth; }
include/linux/ceph/messenger.h +1 -3
@@ -27,9 +27,7 @@ struct ceph_connection_operations {/* authorize an outgoing connection */ struct ceph_auth_handshake *(*get_authorizer) (struct ceph_connection *con, -void **buf,int *len,int *proto, -void **reply_buf,int *reply_len, -int force_new); +int *proto,int force_new);int (*verify_authorizer_reply) (struct ceph_connection *con,int len);int (*invalidate_authorizer)(struct ceph_connection *con);
net/ceph/messenger.c +7 -6
@@ -671,20 +671,21 @@ static int prepare_connect_authorizer(stmutex_unlock (&con->mutex); - auth_buf =NULL ; - auth_len =0 ; auth_protocol =CEPH_AUTH_UNKNOWN ; - auth = con->ops->get_authorizer (con, &auth_buf, &auth_len, - &auth_protocol, &con->auth_reply_buf, - &con->auth_reply_buf_len, con->auth_retry); + auth = con->ops->get_authorizer (con, &auth_protocol, con->auth_retry); +mutex_lock (&con->mutex);if (IS_ERR (auth))return PTR_ERR (auth); -if (test_bit (CLOSED , &con->state) ||test_bit (OPENING , &con->state))return -EAGAIN ; + auth_buf = auth->authorizer_buf; + auth_len = auth->authorizer_buf_len; + con->auth_reply_buf = auth->authorizer_reply_buf; + con->auth_reply_buf_len = auth->authorizer_reply_buf_len; + con->out_connect.authorizer_protocol =cpu_to_le32 (auth_protocol); con->out_connect.authorizer_len =cpu_to_le32 (auth_len);
net/ceph/osd_client.c +1 -8
@@ -2113,9 +2113,7 @@ static void put_osd_con(struct ceph_conn* managed separately. Caller must *not* attempt to free it. */ static struct ceph_auth_handshake *get_authorizer (struct ceph_connection *con, -void **buf,int *len,int *proto, -void **reply_buf,int *reply_len, -int force_new) +int *proto,int force_new) {struct ceph_osd *o = con->private;struct ceph_osd_client *osdc = o->o_osdc;
@@ -2133,12 +2131,7 @@ static struct ceph_auth_handshake *get_aif (ret)return ERR_PTR (ret); } - *proto = ac->protocol; - *buf = auth->authorizer_buf; - *len = auth->authorizer_buf_len; - *reply_buf = auth->authorizer_reply_buf; - *reply_len = auth->authorizer_reply_buf_len;return auth; }
Greg Kroah-Hartman
maintainerPATCH 78/171 ceph: return pointer from prepare_connect_authorizer()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 729796be9190f57ca40ccca315e8ad34a1eb8fef)
Change prepare_connect_authorizer() so it returns a pointer (or pointer-coded error).
--- net/ceph/messenger.c | 18 +++++++++--------- 1 file changed, 9 insertions(+), 9 deletions(-)
net/ceph/messenger.c +9 -9
@@ -653,7 +653,7 @@ static void prepare_write_keepalive(stru* Connection negotiation. */ -static int prepare_connect_authorizer (struct ceph_connection *con) +static struct ceph_auth_handshake *prepare_connect_authorizer (struct ceph_connection *con) {void *auth_buf;int auth_len;
@@ -664,7 +664,7 @@ static int prepare_connect_authorizer(st con->out_connect.authorizer_protocol =CEPH_AUTH_UNKNOWN ; con->out_connect.authorizer_len =0 ; -return 0 ; +return NULL ; }/* Can't hold the mutex while getting authorizer */
@@ -677,9 +677,9 @@ static int prepare_connect_authorizer(stmutex_lock (&con->mutex);if (IS_ERR (auth)) -return PTR_ERR (auth); +return auth;if (test_bit (CLOSED , &con->state) ||test_bit (OPENING , &con->state)) -return -EAGAIN ; +return ERR_PTR (-EAGAIN ); auth_buf = auth->authorizer_buf; auth_len = auth->authorizer_buf_len;
@@ -692,7 +692,7 @@ static int prepare_connect_authorizer(stif (auth_len)ceph_con_out_kvec_add (con, auth_len, auth_buf); -return 0 ; +return auth; }/*
@@ -712,7 +712,7 @@ static int prepare_write_connect(struct {unsigned global_seq =get_global_seq (con->msgr,0 );int proto; -int ret; +struct ceph_auth_handshake *auth;switch (con->peer_name.type) {case CEPH_ENTITY_TYPE_MON :
@@ -739,9 +739,9 @@ static int prepare_write_connect(struct con->out_connect.flags =0 ;ceph_con_out_kvec_add (con,sizeof (con->out_connect), &con->out_connect); - ret =prepare_connect_authorizer (con); -if (ret) -return ret; + auth =prepare_connect_authorizer (con); +if (IS_ERR (auth)) +return PTR_ERR (auth); con->out_more =0 ;set_bit (WRITE_PENDING , &con->state);
Greg Kroah-Hartman
maintainerPATCH 79/171 ceph: rename prepare_connect_authorizer()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit dac1e716c60161867a47745bca592987ca3a9cb2)
Change the name of prepare_connect_authorizer(). The next patch is going to make this function no longer add anything to the connection's out_kvec, so it will no longer fit the pattern of the rest of the prepare_connect_*() functions.
In addition, pass the address of a variable that will hold the authorization protocol to use. Move the assignment of that to the connection's out_connect structure into prepare_write_connect().
--- net/ceph/messenger.c | 13 +++++++------ 1 file changed, 7 insertions(+), 6 deletions(-)
net/ceph/messenger.c +7 -6
@@ -653,11 +653,11 @@ static void prepare_write_keepalive(stru* Connection negotiation. */ -static struct ceph_auth_handshake *prepare_connect_authorizer (struct ceph_connection *con) +static struct ceph_auth_handshake *get_connect_authorizer (struct ceph_connection *con, +int *auth_proto) {void *auth_buf;int auth_len; -int auth_protocol;struct ceph_auth_handshake *auth;if (!con->ops->get_authorizer) {
@@ -671,8 +671,7 @@ static struct ceph_auth_handshake *prepamutex_unlock (&con->mutex); - auth_protocol =CEPH_AUTH_UNKNOWN ; - auth = con->ops->get_authorizer (con, &auth_protocol, con->auth_retry); + auth = con->ops->get_authorizer (con, auth_proto, con->auth_retry);mutex_lock (&con->mutex);
@@ -686,7 +685,6 @@ static struct ceph_auth_handshake *prepa con->auth_reply_buf = auth->authorizer_reply_buf; con->auth_reply_buf_len = auth->authorizer_reply_buf_len; - con->out_connect.authorizer_protocol =cpu_to_le32 (auth_protocol); con->out_connect.authorizer_len =cpu_to_le32 (auth_len);if (auth_len)
@@ -712,6 +710,7 @@ static int prepare_write_connect(struct {unsigned global_seq =get_global_seq (con->msgr,0 );int proto; +int auth_proto;struct ceph_auth_handshake *auth;switch (con->peer_name.type) {
@@ -739,9 +738,11 @@ static int prepare_write_connect(struct con->out_connect.flags =0 ;ceph_con_out_kvec_add (con,sizeof (con->out_connect), &con->out_connect); - auth =prepare_connect_authorizer (con); + auth_proto =CEPH_AUTH_UNKNOWN ; + auth =get_connect_authorizer (con, &auth_proto);if (IS_ERR (auth))return PTR_ERR (auth); + con->out_connect.authorizer_protocol =cpu_to_le32 (auth_proto); con->out_more =0 ;set_bit (WRITE_PENDING , &con->state);
Greg Kroah-Hartman
maintainerPATCH 80/171 ceph: add auth buf in prepare_write_connect()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 3da54776e2c0385c32d143fd497a7f40a88e29dd)
Move the addition of the authorizer buffer to a connection's out_kvec out of get_connect_authorizer() and into its caller. This way, the caller--prepare_write_connect()--can avoid adding the connect header to out_kvec before it has been fully initialized.
Prior to this patch, it was possible for a connect header to be sent over the wire before the authorizer protocol or buffer length fields were initialized. An authorizer buffer associated with that header could also be queued to send only after the connection header that describes it was on the wire.
Fixes http://tracker.newdream.net/issues/2424
--- net/ceph/messenger.c | 18 +++++++++--------- 1 file changed, 9 insertions(+), 9 deletions(-)
net/ceph/messenger.c +9 -9
@@ -656,8 +656,6 @@ static void prepare_write_keepalive(strustatic struct ceph_auth_handshake *get_connect_authorizer (struct ceph_connection *con,int *auth_proto) { -void *auth_buf; -int auth_len;struct ceph_auth_handshake *auth;if (!con->ops->get_authorizer) {
@@ -680,15 +678,9 @@ static struct ceph_auth_handshake *get_cif (test_bit (CLOSED , &con->state) ||test_bit (OPENING , &con->state))return ERR_PTR (-EAGAIN ); - auth_buf = auth->authorizer_buf; - auth_len = auth->authorizer_buf_len; con->auth_reply_buf = auth->authorizer_reply_buf; con->auth_reply_buf_len = auth->authorizer_reply_buf_len; - con->out_connect.authorizer_len =cpu_to_le32 (auth_len); - -if (auth_len) -ceph_con_out_kvec_add (con, auth_len, auth_buf);return auth; }
@@ -737,12 +729,20 @@ static int prepare_write_connect(struct con->out_connect.protocol_version =cpu_to_le32 (proto); con->out_connect.flags =0 ; -ceph_con_out_kvec_add (con,sizeof (con->out_connect), &con->out_connect); auth_proto =CEPH_AUTH_UNKNOWN ; auth =get_connect_authorizer (con, &auth_proto);if (IS_ERR (auth))return PTR_ERR (auth); + con->out_connect.authorizer_protocol =cpu_to_le32 (auth_proto); + con->out_connect.authorizer_len = auth ? +cpu_to_le32 (auth->authorizer_buf_len) :0 ; + +ceph_con_out_kvec_add (con,sizeof (con->out_connect), + &con->out_connect); +if (auth && auth->authorizer_buf_len) +ceph_con_out_kvec_add (con, auth->authorizer_buf_len, + auth->authorizer_buf); con->out_more =0 ;set_bit (WRITE_PENDING , &con->state);
Greg Kroah-Hartman
maintainerPATCH 81/171 libceph: avoid unregistering osd request when not registered
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 35f9f8a09e1e88e31bd34a1e645ca0e5f070dd5c)
There is a race between two __unregister_request() callers: the reply path and the ceph_osdc_wait_request(). If we get a reply *and* the timeout expires at roughly the same time, both callers will try to unregister the request, and the second one will do bad things.
Simply check if the request is still already unregistered; if so, return immediately and do nothing.
Fixes http://tracker.newdream.net/issues/2420
--- net/ceph/osd_client.c | 6 ++++++ 1 file changed, 6 insertions(+)
net/ceph/osd_client.c +6 -0
@@ -841,6 +841,12 @@ static void register_request(struct cephstatic void __unregister_request (struct ceph_osd_client *osdc,struct ceph_osd_request *req) { +if (RB_EMPTY_NODE (&req->r_node)) { +dout ("__unregister_request %p tid %lld not registered\n" , + req, req->r_tid); +return ; + } +dout ("__unregister_request %p tid %lld\n" , req, req->r_tid);rb_erase (&req->r_node, &osdc->requests); osdc->num_requests--;
Greg Kroah-Hartman
maintainerPATCH 82/171 libceph: fix pg_temp updates
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 6bd9adbdf9ca6a052b0b7455ac67b925eb38cfad)
Usually, we are adding pg_temp entries or removing them. Occasionally they update. In that case, osdmap_apply_incremental() was failing because the rbtree entry already exists.
Fix by removing the existing entry before inserting a new one.
Fixes http://tracker.newdream.net/issues/2446
--- net/ceph/osdmap.c | 6 +++++- 1 file changed, 5 insertions(+), 1 deletion(-)
net/ceph/osdmap.c +5 -1
@@ -890,8 +890,12 @@ struct ceph_osdmap *osdmap_apply_increme pglen =ceph_decode_32 (p);if (pglen) { -/* insert */ ceph_decode_need (p, end, pglen*sizeof (u32), bad); + +/* removing existing (if any) */ + (void )__remove_pg_mapping (&map->pg_temp, pgid); + +/* insert */ pg =kmalloc (sizeof (*pg) +sizeof (u32)*pglen,GFP_NOFS );if (!pg) { err = -ENOMEM ;
Greg Kroah-Hartman
maintainerPATCH 83/171 libceph: osd_client: dont drop reply reference too early
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit ab8cb34a4b2f60281a4b18b1f1ad23bc2313d91b)
In ceph_osdc_release_request(), a reference to the r_reply message is dropped. But just after that, that same message is revoked if it was in use to receive an incoming reply. Reorder these so we are sure we hold a reference until we're actually done with the message.
--- net/ceph/osd_client.c | 4 ++-- 1 file changed, 2 insertions(+), 2 deletions(-)
net/ceph/osd_client.c +2 -2
@@ -139,8 +139,6 @@ void ceph_osdc_release_request(struct krif (req->r_request)ceph_msg_put (req->r_request); -if (req->r_reply) -ceph_msg_put (req->r_reply);if (req->r_con_filling_msg) {dout ("release_request revoking pages %p from con %p\n" , req->r_pages, req->r_con_filling_msg);
@@ -148,6 +146,8 @@ void ceph_osdc_release_request(struct kr req->r_reply);ceph_con_put (req->r_con_filling_msg); } +if (req->r_reply) +ceph_msg_put (req->r_reply);if (req->r_own_pages)ceph_release_page_vector (req->r_pages, req->r_num_pages);
Greg Kroah-Hartman
maintainerPATCH 84/171 libceph: use con get/put ops from osd_client
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 0d47766f14211a73eaf54cab234db134ece79f49)
There were a few direct calls to ceph_con_{get,put}() instead of the con ops from osd_client.c. This is a bug since those ops aren't defined to be ceph_con_get/put.
This breaks refcounting on the ceph_osd structs that contain the ceph_connections, and could lead to all manner of strangeness.
The purpose of the ->get and ->put methods in a ceph connection are to allow the connection to indicate it has a reference to something external to the messaging system, *not* to indicate something external has a reference to the connection.
[[email protected]: added that last sentence]
--- net/ceph/osd_client.c | 8 ++++---- 1 file changed, 4 insertions(+), 4 deletions(-)
net/ceph/osd_client.c +4 -4
@@ -144,7 +144,7 @@ void ceph_osdc_release_request(struct kr req->r_pages, req->r_con_filling_msg);ceph_con_revoke_message (req->r_con_filling_msg, req->r_reply); -ceph_con_put (req->r_con_filling_msg); + req->r_con_filling_msg->ops->put (req->r_con_filling_msg); }if (req->r_reply)ceph_msg_put (req->r_reply);
@@ -1216,7 +1216,7 @@ static void handle_reply(struct ceph_osdif (req->r_con_filling_msg == con && req->r_reply == msg) {dout (" dropping con_filling_msg ref %p\n" , con); req->r_con_filling_msg =NULL ; -ceph_con_put (con); + con->ops->put (con); }if (!req->r_got_reply) {
@@ -2028,7 +2028,7 @@ static struct ceph_msg *get_reply(structdout ("get_reply revoking msg %p from old con %p\n" , req->r_reply, req->r_con_filling_msg);ceph_con_revoke_message (req->r_con_filling_msg, req->r_reply); -ceph_con_put (req->r_con_filling_msg); + req->r_con_filling_msg->ops->put (req->r_con_filling_msg); req->r_con_filling_msg =NULL ; }
@@ -2063,7 +2063,7 @@ static struct ceph_msg *get_reply(struct#endif } *skip =0 ; - req->r_con_filling_msg =ceph_con_get (con); + req->r_con_filling_msg = con->ops->get (con);dout ("get_reply tid %lld %p\n" , tid, m); out:
Greg Kroah-Hartman
maintainerPATCH 85/171 rbd: Clear ceph_msg->bio_iter for retransmitted message
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: "Yan, Zheng" <[email protected]>
(cherry picked from commit 43643528cce60ca184fe8197efa8e8da7c89a037) (cherry picked from commit b132cf4c733f91bb4dd2277ea049243cf16e8b66)
The bug can cause NULL pointer dereference in write_partial_msg_pages
--- net/ceph/messenger.c | 4 ++++ 1 file changed, 4 insertions(+)
net/ceph/messenger.c +4 -0
@@ -563,6 +563,10 @@ static void prepare_write_message(struct m->hdr.seq =cpu_to_le64 (++con->out_seq); m->needs_out_seq = false; } +#ifdef CONFIG_BLOCK + else + m->bio_iter = NULL; +#endif dout("prepare_write_message %p seq %lld type %d len %d+%d+%d %d pgs\n", m, con->out_seq, le16_to_cpu(m->hdr.type),
Greg Kroah-Hartman
maintainerPATCH 86/171 libceph: flush msgr queue during mon_client shutdown
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit f3dea7edd3d449fe7a6d402c1ce56a294b985261) (cherry picked from commit 642c0dbde32f34baa7886e988a067089992adc8f)
We need to flush the msgr workqueue during mon_client shutdown to ensure that any work affecting our embedded ceph_connection is finished so that we can be safely destroyed.
Previously, we were flushing the work queue after osd_client shutdown and before mon_client shutdown to ensure that any osd connection refs to authorizers are flushed. Remove the redundant flush, and document in the comment that the mon_client flush is needed to cover that case as well.
--- net/ceph/ceph_common.c | 7 ------- net/ceph/mon_client.c | 8 ++++++++ 2 files changed, 8 insertions(+), 7 deletions(-)
net/ceph/ceph_common.c +0 -7
@@ -504,13 +504,6 @@ void ceph_destroy_client(struct ceph_cli/* unmount */ ceph_osdc_stop (&client->osdc); -/* -* make sure osd connections close out before destroying the -* auth module, which is needed to free those connections' -* ceph_authorizers. -*/ -ceph_msgr_flush (); -ceph_monc_stop (&client->monc);ceph_debugfs_client_cleanup (client);
net/ceph/mon_client.c +8 -0
@@ -847,6 +847,14 @@ void ceph_monc_stop(struct ceph_mon_cliemutex_unlock (&monc->mutex); +/* +* flush msgr queue before we destroy ourselves to ensure that: +* - any work that references our embedded con is finished. +* - any osd_client or other work that may reference an authorizer +* finishes before we shut down the auth subsystem. +*/ +ceph_msgr_flush (); +ceph_auth_destroy (monc->auth);ceph_msg_put (monc->m_auth);
Greg Kroah-Hartman
maintainerPATCH 87/171 libceph: fix messenger retry
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 5bdca4e0768d3e0f4efa43d9a2cc8210aeb91ab9)
In ancient times, the messenger could both initiate and accept connections. An artifact if that was data structures to store/process an incoming ceph_msg_connect request and send an outgoing ceph_msg_connect_reply. Sadly, the negotiation code was referencing those structures and ignoring important information (like the peer's connect_seq) from the correct ones.
Among other things, this fixes tight reconnect loops where the server sends RETRY_SESSION and we (the client) retries with the same connect_seq as last time. This bug pretty easily triggered by injecting socket failures on the MDS and running some fs workload like workunits/direct_io/test_sync_io.
--- include/linux/ceph/messenger.h | 12 ++---------- net/ceph/messenger.c | 12 ++++++------ 2 files changed, 8 insertions(+), 16 deletions(-)
include/linux/ceph/messenger.h +2 -10
@@ -163,16 +163,8 @@ struct ceph_connection {/* connection negotiation temps */ char in_banner[CEPH_BANNER_MAX_LEN ]; -union { -struct {/* outgoing connection */ -struct ceph_msg_connect out_connect; -struct ceph_msg_connect_reply in_reply; - }; -struct {/* incoming */ -struct ceph_msg_connect in_connect; -struct ceph_msg_connect_reply out_reply; - }; - }; +struct ceph_msg_connect out_connect; +struct ceph_msg_connect_reply in_reply;struct ceph_entity_addr actual_peer_addr;/* message out temps */
net/ceph/messenger.c +6 -6
@@ -1423,7 +1423,7 @@ static int process_connect(struct ceph_c* dropped messages. */ dout ("process_connect got RESET peer seq %u\n" , -le32_to_cpu (con->in_connect.connect_seq)); +le32_to_cpu (con->in_reply.connect_seq));pr_err ("%s%lld %s connection reset\n" ,ENTITY_NAME (con->peer_name),ceph_pr_addr (&con->peer_addr.in_addr));
@@ -1450,10 +1450,10 @@ static int process_connect(struct ceph_c* If we sent a smaller connect_seq than the peer has, try * again with a larger value. */ -dout ("process_connect got RETRY my seq = %u, peer_seq = %u\n" , +dout ("process_connect got RETRY_SESSION my seq %u, peer %u\n" ,le32_to_cpu (con->out_connect.connect_seq), -le32_to_cpu (con->in_connect.connect_seq)); - con->connect_seq =le32_to_cpu (con->in_connect.connect_seq); +le32_to_cpu (con->in_reply.connect_seq)); + con->connect_seq =le32_to_cpu (con->in_reply.connect_seq);ceph_con_out_kvec_reset (con); ret =prepare_write_connect (con);if (ret <0 )
@@ -1468,9 +1468,9 @@ static int process_connect(struct ceph_c*/ dout ("process_connect got RETRY_GLOBAL my %u peer_gseq %u\n" , con->peer_global_seq, -le32_to_cpu (con->in_connect.global_seq)); +le32_to_cpu (con->in_reply.global_seq));get_global_seq (con->msgr, -le32_to_cpu (con->in_connect.global_seq)); +le32_to_cpu (con->in_reply.global_seq));ceph_con_out_kvec_reset (con); ret =prepare_write_connect (con);if (ret <0 )
Greg Kroah-Hartman
maintainerPATCH 88/171 rbd: dont hold spinlock during messenger flush
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit cd9d9f5df6098c50726200d4185e9e8da32785b3)
A recent change made changes to the rbd_client_list be protected by a spinlock. Unfortunately in rbd_put_client(), the lock is taken before possibly dropping the last reference to an rbd_client, and on the last reference that eventually calls flush_workqueue() which can sleep.
The problem was flagged by a debug spinlock warning:
BUG: spinlock wrong CPU on CPU#3, rbd/27814
The solution is to move the spinlock acquisition and release inside rbd_client_release(), which is the spot where it's really needed for protecting the removal of the rbd_client from the client list.
--- drivers/block/rbd.c | 4 ++-- 1 file changed, 2 insertions(+), 2 deletions(-)
drivers/block/rbd.c +2 -2
@@ -450,7 +450,9 @@ static void rbd_client_release(struct kr struct rbd_client *rbdc = container_of(kref, struct rbd_client, kref);dout ("rbd_release_client %p\n" , rbdc); +spin_lock (&rbd_client_list_lock);list_del (&rbdc->node); +spin_unlock (&rbd_client_list_lock);ceph_destroy_client (rbdc->client);kfree (rbdc->rbd_opts);
@@ -463,9 +465,7 @@ static void rbd_client_release(struct kr*/ static void rbd_put_client (struct rbd_device *rbd_dev) { -spin_lock (&rbd_client_list_lock);kref_put (&rbd_dev->rbd_client->kref, rbd_client_release); -spin_unlock (&rbd_client_list_lock); rbd_dev->rbd_client =NULL ; }
Greg Kroah-Hartman
maintainerPATCH 89/171 rbd: protect read of snapshot sequence number
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Josh Durgin <[email protected]>
(cherry picked from commit 403f24d3d51760a8b9368d595fa5f48c309f1a0f)
This is updated whenever a snapshot is added or deleted, and the snapc pointer is changed with every refresh of the header.
--- drivers/block/rbd.c | 4 +++- 1 file changed, 3 insertions(+), 1 deletion(-)
drivers/block/rbd.c +3 -1
@@ -1683,7 +1683,9 @@ static int rbd_header_add_snap(struct rbif (ret <0 )return ret; - dev->header.snapc->seq = new_snapid; +down_write (&dev->header_rwsem); + dev->header.snapc->seq = new_snapid; +up_write (&dev->header_rwsem);return 0 ; bad:
Greg Kroah-Hartman
maintainerPATCH 90/171 rbd: store snapshot id instead of index
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Josh Durgin <[email protected]>
(cherry picked from commit 77dfe99fe3cb0b2b0545e19e2d57b7a9134ee3c0)
When a device was open at a snapshot, and snapshots were deleted or added, data from the wrong snapshot could be read. Instead of assuming the snap context is constant, store the actual snap id when the device is initialized, and rely on the OSDs to signal an error if we try reading from a snapshot that was deleted.
--- drivers/block/rbd.c | 27 +++++---------------------- 1 file changed, 5 insertions(+), 22 deletions(-)
drivers/block/rbd.c +5 -22
@@ -175,8 +175,7 @@ struct rbd_device {/* protects updating the header */ struct rw_semaphore header_rwsem;char snap_name[RBD_MAX_SNAP_NAME_LEN ]; -u32 cur_snap;/* index+1 of current snapshot within snap context -0 - for the head */ +u64 snap_id;/* current snapshot id */ int read_only;struct list_head node;
@@ -552,21 +551,6 @@ err_snapc:return -ENOMEM ; } -static int snap_index (struct rbd_image_header *header,int snap_num) -{ -return header->total_snaps - snap_num; -} - -static u64 cur_snap_id (struct rbd_device *rbd_dev) -{ -struct rbd_image_header *header = &rbd_dev->header; - -if (!rbd_dev->cur_snap) -return 0 ; - -return header->snapc->snaps[snap_index (header, rbd_dev->cur_snap)]; -} -static int snap_by_name (struct rbd_image_header *header,const char *snap_name,u64 *seq,u64 *size) {
@@ -605,7 +589,7 @@ static int rbd_header_set_snap(struct rb snapc->seq = header->snap_seq; else snapc->seq = 0; - dev->cur_snap =0 ; + dev->snap_id =CEPH_NOSNAP ; dev->read_only =0 ;if (size) *size = header->image_size;
@@ -613,8 +597,7 @@ static int rbd_header_set_snap(struct rb ret =snap_by_name (header, dev->snap_name, &snapc->seq, size);if (ret <0 ) goto done; - - dev->cur_snap = header->total_snaps - ret; + dev->snap_id = snapc->seq; dev->read_only =1 ; }
@@ -1521,7 +1504,7 @@ static void rbd_rq_fn(struct request_que coll, cur_seg); else rbd_req_read(rq, rbd_dev, -cur_snap_id (rbd_dev ), + rbd_dev->snap_id, ofs, op_size, bio, coll, cur_seg);
@@ -1656,7 +1639,7 @@ static int rbd_header_add_snap(struct rbstruct ceph_mon_client *monc;/* we should create a snapshot only if we're pointing at the head */ -if (dev->cur_snap) +if (dev->snap_id !=CEPH_NOSNAP )return -EINVAL ; monc = &dev->rbd_client->client->monc;
Greg Kroah-Hartman
maintainerPATCH 91/171 rbd: Fix ceph_snap_context size calculation
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: "Yan, Zheng" <[email protected]>
(cherry picked from commit f9f9a1904467816452fc70740165030e84c2c659)
ceph_snap_context->snaps is an u64 array
--- drivers/block/rbd.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/block/rbd.c +1 -1
@@ -497,7 +497,7 @@ static int rbd_header_from_disk(struct r snap_count =le32_to_cpu (ondisk->snap_count); header->snapc =kmalloc (sizeof (struct ceph_snap_context ) + - snap_count *sizeof (*ondisk), + snap_count *sizeof (u64), gfp_flags);if (!header->snapc)return -ENOMEM ;
Greg Kroah-Hartman
maintainerPATCH 92/171 ceph: check PG_Private flag before accessing page->private
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: "Yan, Zheng" <[email protected]>
(cherry picked from commit 28c0254ede13ab575d2df5c6585ed3d4817c3e6b)
I got lots of NULL pointer dereference Oops when compiling kernel on ceph. The bug is because the kernel page migration routine replaces some pages in the page cache with new pages, these new pages' private can be non-zero.
--- fs/ceph/addr.c | 21 ++++++++++++--------- 1 file changed, 12 insertions(+), 9 deletions(-)
fs/ceph/addr.c +12 -9
@@ -54,7 +54,12 @@ (CONGESTION_ON_THRESH (congestion_kb) - \ (CONGESTION_ON_THRESH(congestion_kb) >> 2)) - +static inline struct ceph_snap_context *page_snap_context (struct page *page) +{ +if (PagePrivate (page)) +return (void *)page->private; +return NULL ; +}/* * Dirty a page. Optimistically adjust accounting, on the assumption
@@ -142,10 +147,9 @@ static void ceph_invalidatepage(struct p {struct inode *inode;struct ceph_inode_info *ci; -struct ceph_snap_context *snapc = (void *)page->private; +struct ceph_snap_context *snapc =page_snap_context (page);BUG_ON (!PageLocked (page)); -BUG_ON (!page->private);BUG_ON (!PagePrivate (page));BUG_ON (!page->mapping);
@@ -182,7 +186,6 @@ static int ceph_releasepage(struct pagestruct inode *inode = page->mapping ? page->mapping->host :NULL ;dout ("%p releasepage %p idx %lu\n" , inode, page, page->index);WARN_ON (PageDirty (page)); -WARN_ON (page->private);WARN_ON (PagePrivate (page));return 0 ; }
@@ -443,7 +446,7 @@ static int writepage_nounlock(struct pag osdc = &fsc->client->osdc;/* verify this is a writeable snap context */ - snapc = (void *)page->private; + snapc =page_snap_context (page);if (snapc ==NULL ) {dout ("writepage %p page %p not dirty?\n" , inode, page); goto out;
@@ -451,7 +454,7 @@ static int writepage_nounlock(struct pag oldest =get_oldest_context (inode, &snap_size);if (snapc->seq > oldest->seq) {dout ("writepage %p page %p snapc %p not writeable - noop\n" , - inode, page, (void *)page->private); + inode, page, snapc);/* we should only noop if called by kswapd */ WARN_ON ((current->flags &PF_MEMALLOC ) ==0 );ceph_put_snap_context (oldest);
@@ -591,7 +594,7 @@ static void writepages_finish(struct cepclear_bdi_congested (&fsc->backing_dev_info,BLK_RW_ASYNC ); -ceph_put_snap_context ((void *)page->private); +ceph_put_snap_context (page_snap_context (page)); page->private =0 ;ClearPagePrivate (page);dout ("unlocking %d %p\n" , i, page);
@@ -795,7 +798,7 @@ get_more_pages: }/* only if matching snap context */ - pgsnapc = (void *)page->private; + pgsnapc =page_snap_context (page);if (pgsnapc->seq > snapc->seq) {dout ("page snapc %p %lld > oldest %p %lld\n" , pgsnapc, pgsnapc->seq, snapc, snapc->seq);
@@ -984,7 +987,7 @@ retry_locked:BUG_ON (!ci->i_snap_realm);down_read (&mdsc->snap_rwsem);BUG_ON (!ci->i_snap_realm->cached_context); - snapc = (void *)page->private; + snapc =page_snap_context (page);if (snapc && snapc != ci->i_head_snapc) {/* * this page is already dirty in another (older) snap
Greg Kroah-Hartman
maintainerPATCH 93/171 libceph: eliminate connection state "DEAD"
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit e5e372da9a469dfe3ece40277090a7056c566838)
The ceph connection state "DEAD" is never set and is therefore not needed. Eliminate it.
--- include/linux/ceph/messenger.h | 1 - net/ceph/messenger.c | 6 ------ 2 files changed, 7 deletions(-)
include/linux/ceph/messenger.h +0 -1
@@ -119,7 +119,6 @@ struct ceph_msg_pos {#define CLOSED 10/* we've closed the connection */ #define SOCK_CLOSED 11/* socket state changed to closed */ #define OPENING 13/* open connection w/ (possibly new) peer */ -#define DEAD 14/* dead, about to kfree */ #define BACKOFF 15/*
net/ceph/messenger.c +0 -6
@@ -2091,12 +2091,6 @@ bad_tag:*/ static void queue_con (struct ceph_connection *con) { -if (test_bit (DEAD , &con->state)) { -dout ("queue_con %p ignoring: DEAD\n" , - con); -return ; - } -if (!con->ops->get (con)) {dout ("queue_con %p ref count 0\n" , con);return ;
Greg Kroah-Hartman
maintainerPATCH 94/171 libceph: kill bad_proto ceph connection op
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 6384bb8b8e88a9c6bf2ae0d9517c2c0199177c34)
No code sets a bad_proto method in its ceph connection operations vector, so just get rid of it.
--- include/linux/ceph/messenger.h | 3 --- net/ceph/messenger.c | 5 ----- 2 files changed, 8 deletions(-)
include/linux/ceph/messenger.h +0 -3
@@ -31,9 +31,6 @@ struct ceph_connection_operations {int (*verify_authorizer_reply) (struct ceph_connection *con,int len);int (*invalidate_authorizer)(struct ceph_connection *con); -/* protocol version mismatch */ -void (*bad_proto) (struct ceph_connection *con); -/* there was some error on the socket (disconnect, whatever) */ void (*fault) (struct ceph_connection *con);
net/ceph/messenger.c +0 -5
@@ -1360,11 +1360,6 @@ static void fail_protocol(struct ceph_co {reset_connection (con);set_bit (CLOSED , &con->state);/* in case there's queued work */ - -mutex_unlock (&con->mutex); -if (con->ops->bad_proto) - con->ops->bad_proto (con); -mutex_lock (&con->mutex); }static int process_connect (struct ceph_connection *con)
Greg Kroah-Hartman
maintainerPATCH 95/171 libceph: rename socket callbacks
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 327800bdc2cb9b71f4b458ca07aa9d522668dde0)
Change the names of the three socket callback functions to make it more obvious they're specifically associated with a connection's socket (not the ceph connection that uses it).
--- net/ceph/messenger.c | 28 ++++++++++++++-------------- 1 file changed, 14 insertions(+), 14 deletions(-)
net/ceph/messenger.c +14 -14
@@ -153,46 +153,46 @@ EXPORT_SYMBOL(ceph_msgr_flush);*/ /* data available on socket, or listen socket received a connect */ -static void ceph_data_ready (struct sock *sk,int count_unused) +static void ceph_sock_data_ready (struct sock *sk,int count_unused) {struct ceph_connection *con = sk->sk_user_data;if (sk->sk_state !=TCP_CLOSE_WAIT ) { -dout ("ceph_data_ready on %p state = %lu, queueing work\n" , +dout ("%s on %p state = %lu, queueing work\n" , __func__, con, con->state);queue_con (con); } }/* socket has buffer space for writing */ -static void ceph_write_space (struct sock *sk) +static void ceph_sock_write_space (struct sock *sk) {struct ceph_connection *con = sk->sk_user_data;/* only queue to workqueue if there is data we want to write, * and there is sufficient space in the socket buffer to accept -* more data. clear SOCK_NOSPACE so that ceph_write_space() +* more data. clear SOCK_NOSPACE so that ceph_sock_write_space() * doesn't get called again until try_write() fills the socket * buffer. See net/ipv4/tcp_input.c:tcp_check_space() * and net/core/stream.c:sk_stream_write_space(). */ if (test_bit (WRITE_PENDING , &con->state)) {if (sk_stream_wspace (sk) >=sk_stream_min_wspace (sk)) { -dout ("ceph_write_space %p queueing write work\n" , con); +dout ("%s %p queueing write work\n" , __func__, con);clear_bit (SOCK_NOSPACE , &sk->sk_socket->flags);queue_con (con); } }else { -dout ("ceph_write_space %p nothing to write\n" , con); +dout ("%s %p nothing to write\n" , __func__, con); } }/* socket's state has changed */ -static void ceph_state_change (struct sock *sk) +static void ceph_sock_state_change (struct sock *sk) {struct ceph_connection *con = sk->sk_user_data; -dout ("ceph_state_change %p state = %lu sk_state = %u\n" , +dout ("%s %p state = %lu sk_state = %u\n" , __func__, con, con->state, sk->sk_state);if (test_bit (CLOSED , &con->state))
@@ -200,9 +200,9 @@ static void ceph_state_change(struct socswitch (sk->sk_state) {case TCP_CLOSE : -dout ("ceph_state_change TCP_CLOSE\n" ); +dout ("%s TCP_CLOSE\n" , __func__);case TCP_CLOSE_WAIT : -dout ("ceph_state_change TCP_CLOSE_WAIT\n" ); +dout ("%s TCP_CLOSE_WAIT\n" , __func__);if (test_and_set_bit (SOCK_CLOSED , &con->state) ==0 ) {if (test_bit (CONNECTING , &con->state)) con->error_msg ="connection failed" ;
@@ -212,7 +212,7 @@ static void ceph_state_change(struct soc }break ;case TCP_ESTABLISHED : -dout ("ceph_state_change TCP_ESTABLISHED\n" ); +dout ("%s TCP_ESTABLISHED\n" , __func__);queue_con (con);break ;default :/* Everything else is uninteresting */
@@ -228,9 +228,9 @@ static void set_sock_callbacks(struct so {struct sock *sk = sock->sk; sk->sk_user_data = con; - sk->sk_data_ready = ceph_data_ready; - sk->sk_write_space = ceph_write_space; - sk->sk_state_change = ceph_state_change; + sk->sk_data_ready = ceph_sock_data_ready; + sk->sk_write_space = ceph_sock_write_space; + sk->sk_state_change = ceph_sock_state_change; }
Greg Kroah-Hartman
maintainerPATCH 96/171 libceph: rename kvec_reset and kvec_add functions
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit e22004235a900213625acd6583ac913d5a30c155)
The functions ceph_con_out_kvec_reset() and ceph_con_out_kvec_add() are entirely private functions, so drop the "ceph_" prefix in their name to make them slightly more wieldy.
--- net/ceph/messenger.c | 48 ++++++++++++++++++++++++------------------------ 1 file changed, 24 insertions(+), 24 deletions(-)
net/ceph/messenger.c +24 -24
@@ -486,14 +486,14 @@ static u32 get_global_seq(struct ceph_mereturn ret; } -static void ceph_con_out_kvec_reset (struct ceph_connection *con) +static void con_out_kvec_reset (struct ceph_connection *con) { con->out_kvec_left =0 ; con->out_kvec_bytes =0 ; con->out_kvec_cur = &con->out_kvec[0 ]; } -static void ceph_con_out_kvec_add (struct ceph_connection *con, +static void con_out_kvec_add (struct ceph_connection *con,size_t size,void *data) {int index;
@@ -534,7 +534,7 @@ static void prepare_write_message(structstruct ceph_msg *m;u32 crc; -ceph_con_out_kvec_reset (con); +con_out_kvec_reset (con); con->out_kvec_is_msg = true; con->out_msg_done = false;
@@ -542,9 +542,9 @@ static void prepare_write_message(struct* TCP packet that's a good thing. */ if (con->in_seq > con->in_seq_acked) { con->in_seq_acked = con->in_seq; -ceph_con_out_kvec_add (con,sizeof (tag_ack), &tag_ack); +con_out_kvec_add (con,sizeof (tag_ack), &tag_ack); con->out_temp_ack =cpu_to_le64 (con->in_seq_acked); -ceph_con_out_kvec_add (con,sizeof (con->out_temp_ack), +con_out_kvec_add (con,sizeof (con->out_temp_ack), &con->out_temp_ack); }
@@ -576,12 +576,12 @@ static void prepare_write_message(structBUG_ON (le32_to_cpu (m->hdr.front_len) != m->front.iov_len);/* tag + hdr + front + middle */ -ceph_con_out_kvec_add (con,sizeof (tag_msg), &tag_msg); -ceph_con_out_kvec_add (con,sizeof (m->hdr), &m->hdr); -ceph_con_out_kvec_add (con, m->front.iov_len, m->front.iov_base); +con_out_kvec_add (con,sizeof (tag_msg), &tag_msg); +con_out_kvec_add (con,sizeof (m->hdr), &m->hdr); +con_out_kvec_add (con, m->front.iov_len, m->front.iov_base);if (m->middle) -ceph_con_out_kvec_add (con, m->middle->vec.iov_len, +con_out_kvec_add (con, m->middle->vec.iov_len, m->middle->vec.iov_base);/* fill in crc (except data pages), footer */
@@ -630,12 +630,12 @@ static void prepare_write_ack(struct cep con->in_seq_acked, con->in_seq); con->in_seq_acked = con->in_seq; -ceph_con_out_kvec_reset (con); +con_out_kvec_reset (con); -ceph_con_out_kvec_add (con,sizeof (tag_ack), &tag_ack); +con_out_kvec_add (con,sizeof (tag_ack), &tag_ack); con->out_temp_ack =cpu_to_le64 (con->in_seq_acked); -ceph_con_out_kvec_add (con,sizeof (con->out_temp_ack), +con_out_kvec_add (con,sizeof (con->out_temp_ack), &con->out_temp_ack); con->out_more =1 ;/* more will follow.. eventually.. */
@@ -648,8 +648,8 @@ static void prepare_write_ack(struct cepstatic void prepare_write_keepalive (struct ceph_connection *con) {dout ("prepare_write_keepalive %p\n" , con); -ceph_con_out_kvec_reset (con); -ceph_con_out_kvec_add (con,sizeof (tag_keepalive), &tag_keepalive); +con_out_kvec_reset (con); +con_out_kvec_add (con,sizeof (tag_keepalive), &tag_keepalive);set_bit (WRITE_PENDING , &con->state); }
@@ -694,8 +694,8 @@ static struct ceph_auth_handshake *get_c*/ static void prepare_write_banner (struct ceph_connection *con) { -ceph_con_out_kvec_add (con,strlen (CEPH_BANNER ),CEPH_BANNER ); -ceph_con_out_kvec_add (con,sizeof (con->msgr->my_enc_addr), +con_out_kvec_add (con,strlen (CEPH_BANNER ),CEPH_BANNER ); +con_out_kvec_add (con,sizeof (con->msgr->my_enc_addr), &con->msgr->my_enc_addr); con->out_more =0 ;
@@ -742,10 +742,10 @@ static int prepare_write_connect(struct con->out_connect.authorizer_len = auth ?cpu_to_le32 (auth->authorizer_buf_len) :0 ; -ceph_con_out_kvec_add (con,sizeof (con->out_connect), +con_out_kvec_add (con,sizeof (con->out_connect), &con->out_connect);if (auth && auth->authorizer_buf_len) -ceph_con_out_kvec_add (con, auth->authorizer_buf_len, +con_out_kvec_add (con, auth->authorizer_buf_len, auth->authorizer_buf); con->out_more =0 ;
@@ -939,7 +939,7 @@ static int write_partial_msg_pages(struc/* prepare and queue up footer, too */ if (!do_datacrc) con->out_msg->footer.flags |=CEPH_MSG_FOOTER_NOCRC ; -ceph_con_out_kvec_reset (con); +con_out_kvec_reset (con);prepare_write_message_footer (con); ret =1 ; out:
@@ -1402,7 +1402,7 @@ static int process_connect(struct ceph_creturn -1 ; } con->auth_retry =1 ; -ceph_con_out_kvec_reset (con); +con_out_kvec_reset (con); ret =prepare_write_connect (con);if (ret <0 )return ret;
@@ -1423,7 +1423,7 @@ static int process_connect(struct ceph_cENTITY_NAME (con->peer_name), ceph_pr_addr(&con->peer_addr.in_addr));reset_connection (con); -ceph_con_out_kvec_reset (con); +con_out_kvec_reset (con); ret =prepare_write_connect (con);if (ret <0 )return ret;
@@ -1449,7 +1449,7 @@ static int process_connect(struct ceph_cle32_to_cpu (con->out_connect.connect_seq), le32_to_cpu(con->in_reply.connect_seq)); con->connect_seq =le32_to_cpu (con->in_reply.connect_seq); -ceph_con_out_kvec_reset (con); +con_out_kvec_reset (con); ret =prepare_write_connect (con);if (ret <0 )return ret;
@@ -1466,7 +1466,7 @@ static int process_connect(struct ceph_c le32_to_cpu(con->in_reply.global_seq));get_global_seq (con->msgr,le32_to_cpu (con->in_reply.global_seq)); -ceph_con_out_kvec_reset (con); +con_out_kvec_reset (con); ret =prepare_write_connect (con);if (ret <0 )return ret;
@@ -1873,7 +1873,7 @@ more:/* open the socket first? */ if (con->sock ==NULL ) { -ceph_con_out_kvec_reset (con); +con_out_kvec_reset (con);prepare_write_banner (con); ret =prepare_write_connect (con);if (ret <0 )
Greg Kroah-Hartman
maintainerPATCH 97/171 libceph: embed ceph messenger structure in ceph_client
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 15d9882c336db2db73ccf9871ae2398e452f694c)
A ceph client has a pointer to a ceph messenger structure in it. There is always exactly one ceph messenger for a ceph client, so there is no need to allocate it separate from the ceph client structure.
Switch the ceph_client structure to embed its ceph_messenger structure.
--- fs/ceph/mds_client.c | 2 +- include/linux/ceph/libceph.h | 2 +- include/linux/ceph/messenger.h | 9 +++++---- net/ceph/ceph_common.c | 18 +++++------------- net/ceph/messenger.c | 30 +++++++++--------------------- net/ceph/mon_client.c | 6 +++--- net/ceph/osd_client.c | 4 ++-- 7 files changed, 26 insertions(+), 45 deletions(-)
fs/ceph/mds_client.c +1 -1
@@ -394,7 +394,7 @@ static struct ceph_mds_session *register s->s_seq =0 ;mutex_init (&s->s_mutex); -ceph_con_init (mdsc->fsc->client->msgr, &s->s_con); +ceph_con_init (&mdsc->fsc->client->msgr, &s->s_con); s->s_con.private = s; s->s_con.ops = &mds_con_ops; s->s_con.peer_name.type =CEPH_ENTITY_TYPE_MDS ;
include/linux/ceph/libceph.h +1 -1
@@ -132,7 +132,7 @@ struct ceph_client {u32 supported_features;u32 required_features; -struct ceph_messenger *msgr;/* messenger instance */ +struct ceph_messenger msgr;/* messenger instance */ struct ceph_mon_client monc;struct ceph_osd_client osdc;
include/linux/ceph/messenger.h +5 -4
@@ -203,10 +203,11 @@ extern int ceph_msgr_init(void);extern void ceph_msgr_exit (void );extern void ceph_msgr_flush (void ); -extern struct ceph_messenger *ceph_messenger_create ( -struct ceph_entity_addr *myaddr, -u32 features,u32 required); -extern void ceph_messenger_destroy (struct ceph_messenger *); +extern void ceph_messenger_init (struct ceph_messenger *msgr, +struct ceph_entity_addr *myaddr, +u32 supported_features, +u32 required_features, +bool nocrc);extern void ceph_con_init (struct ceph_messenger *msgr,struct ceph_connection *con);
net/ceph/ceph_common.c +5 -13
@@ -468,19 +468,15 @@ struct ceph_client *ceph_create_client(s/* msgr */ if (ceph_test_opt (client,MYIP )) myaddr = &client->options->my_addr; - client->msgr =ceph_messenger_create (myaddr, - client->supported_features, - client->required_features); -if (IS_ERR (client->msgr)) { - err =PTR_ERR (client->msgr); - goto fail; - } - client->msgr->nocrc =ceph_test_opt (client,NOCRC ); +ceph_messenger_init (&client->msgr, myaddr, + client->supported_features, + client->required_features, +ceph_test_opt (client,NOCRC ));/* subsystems */ err =ceph_monc_init (&client->monc, client);if (err <0 ) - goto fail_msgr; + goto fail; err =ceph_osdc_init (&client->osdc, client);if (err <0 ) goto fail_monc;
@@ -489,8 +485,6 @@ struct ceph_client *ceph_create_client(s fail_monc:ceph_monc_stop (&client->monc); -fail_msgr: -ceph_messenger_destroy (client->msgr); fail:kfree (client);return ERR_PTR (err);
@@ -508,8 +502,6 @@ void ceph_destroy_client(struct ceph_cliceph_debugfs_client_cleanup (client); -ceph_messenger_destroy (client->msgr); -ceph_destroy_options (client->options);kfree (client);
net/ceph/messenger.c +9 -21
@@ -2249,18 +2249,14 @@ out:/* -* create a new messenger instance +* initialize a new messenger instance */ -struct ceph_messenger *ceph_messenger_create (struct ceph_entity_addr *myaddr, -u32 supported_features, -u32 required_features) +void ceph_messenger_init (struct ceph_messenger *msgr, +struct ceph_entity_addr *myaddr, +u32 supported_features, +u32 required_features, +bool nocrc) { -struct ceph_messenger *msgr; - - msgr =kzalloc (sizeof (*msgr),GFP_KERNEL ); -if (msgr ==NULL ) -return ERR_PTR (-ENOMEM ); - msgr->supported_features = supported_features; msgr->required_features = required_features;
@@ -2273,19 +2269,11 @@ struct ceph_messenger *ceph_messenger_cr msgr->inst.addr.type =0 ;get_random_bytes (&msgr->inst.addr.nonce,sizeof (msgr->inst.addr.nonce));encode_my_addr (msgr); + msgr->nocrc = nocrc; -dout ("messenger_create %p\n" , msgr); -return msgr; -} -EXPORT_SYMBOL (ceph_messenger_create); - -void ceph_messenger_destroy (struct ceph_messenger *msgr) -{ -dout ("destroy %p\n" , msgr); -kfree (msgr); -dout ("destroyed messenger %p\n" , msgr); +dout ("%s %p\n" , __func__, msgr); } -EXPORT_SYMBOL (ceph_messenger_destroy); +EXPORT_SYMBOL (ceph_messenger_init);static void clear_standby (struct ceph_connection *con) {
net/ceph/mon_client.c +3 -3
@@ -763,7 +763,7 @@ int ceph_monc_init(struct ceph_mon_clien monc->con =kmalloc (sizeof (*monc->con),GFP_KERNEL );if (!monc->con) goto out_monmap; -ceph_con_init (monc->client->msgr, monc->con); +ceph_con_init (&monc->client->msgr, monc->con); monc->con->private = monc; monc->con->ops = &mon_con_ops;
@@ -888,8 +888,8 @@ static void handle_auth_reply(struct cep }else if (!was_auth && monc->auth->ops->is_authenticated (monc->auth)) {dout ("authenticated, starting session\n" ); - monc->client->msgr->inst.name.type =CEPH_ENTITY_TYPE_CLIENT ; - monc->client->msgr->inst.name.num = + monc->client->msgr.inst.name.type =CEPH_ENTITY_TYPE_CLIENT ; + monc->client->msgr.inst.name.num =cpu_to_le64 (monc->auth->global_id);__send_subscribe (monc);
net/ceph/osd_client.c +2 -2
@@ -639,7 +639,7 @@ static struct ceph_osd *create_osd(strucINIT_LIST_HEAD (&osd->o_osd_lru); osd->o_incarnation =1 ; -ceph_con_init (osdc->client->msgr, &osd->o_con); +ceph_con_init (&osdc->client->msgr, &osd->o_con); osd->o_con.private = osd; osd->o_con.ops = &osd_con_ops; osd->o_con.peer_name.type =CEPH_ENTITY_TYPE_OSD ;
@@ -1391,7 +1391,7 @@ void ceph_osdc_handle_map(struct ceph_os epoch, maplen); newmap =osdmap_apply_incremental (&p, next, osdc->osdmap, - osdc->client->msgr); + &osdc->client->msgr);if (IS_ERR (newmap)) { err =PTR_ERR (newmap); goto bad;
Greg Kroah-Hartman
maintainerPATCH 98/171 libceph: start separating connection flags from state
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 928443cd9644e7cfd46f687dbeffda2d1a357ff9)
A ceph_connection holds a mixture of connection state (as in "state machine" state) and connection flags in a single "state" field. To make the distinction more clear, define a new "flags" field and use it rather than the "state" field to hold Boolean flag values.
--- include/linux/ceph/messenger.h | 18 +++++++++----- net/ceph/messenger.c | 50 ++++++++++++++++++++--------------------- 2 files changed, 37 insertions(+), 31 deletions(-)
include/linux/ceph/messenger.h +12 -6
@@ -103,20 +103,25 @@ struct ceph_msg_pos {#define MAX_DELAY_INTERVAL (5 * 60 * HZ)/* -* ceph_connection state bit flags +* ceph_connection flag bits */ +#define LOSSYTX 0/* we can close channel or drop messages on errors */ -#define CONNECTING 1 -#define NEGOTIATING 2#define KEEPALIVE_PENDING 3#define WRITE_PENDING 4/* we have data ready to send */ +#define SOCK_CLOSED 11/* socket state changed to closed */ +#define BACKOFF 15 + +/* +* ceph_connection states +*/ +#define CONNECTING 1 +#define NEGOTIATING 2#define STANDBY 8/* no outgoing messages, socket closed. we keep * the ceph_connection around to maintain shared * state with the peer. */ #define CLOSED 10/* we've closed the connection */ -#define SOCK_CLOSED 11/* socket state changed to closed */ #define OPENING 13/* open connection w/ (possibly new) peer */ -#define BACKOFF 15/* * A single connection with another host.
@@ -133,7 +138,8 @@ struct ceph_connection {struct ceph_messenger *msgr;struct socket *sock; -unsigned long state;/* connection state (see flags above) */ +unsigned long flags; +unsigned long state;const char *error_msg;/* error message, if any */ struct ceph_entity_addr peer_addr;/* peer address */
net/ceph/messenger.c +25 -25
171 lines not on this page · raw message
Greg Kroah-Hartman
maintainerPATCH 99/171 libceph: start tracking connection socket state
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit ce2c8903e76e690846a00a0284e4bd9ee954d680)
Start explicitly keeping track of the state of a ceph connection's socket, separate from the state of the connection itself. Create placeholder functions to encapsulate the state transitions.
--------
| NEW* | transient initial state
--------
| con_sock_state_init()
v
----------
| CLOSED | initialized, but no socket (and no
---------- TCP connection)
^ \
| \ con_sock_state_connecting()
| ----------------------
| \
+ con_sock_state_closed() \
|\ \
| \ \
| ----------- \
| | CLOSING | socket event; \
| ----------- await close \
| ^ |
| | |
| + con_sock_state_closing() |
| / \ |
| / --------------- |
| / \ v
| / --------------
| / -----------------| CONNECTING | socket created, TCP
| | / -------------- connect initiated
| | | con_sock_state_connected()
| | v
-------------
| CONNECTED | TCP connection established
-------------Make the socket state an atomic variable, reinforcing that it's a distinct transtion with no possible "intermediate/both" states. This is almost certainly overkill at this point, though the transitions into CONNECTED and CLOSING state do get called via socket callback (the rest of the transitions occur with the connection mutex held). We can back out the atomicity later.
--- include/linux/ceph/messenger.h | 8 +++-- net/ceph/messenger.c | 64 +++++++++++++++++++++++++++++++++++++++++ 2 files changed, 70 insertions(+), 2 deletions(-)
include/linux/ceph/messenger.h +6 -2
@@ -137,14 +137,18 @@ struct ceph_connection {const struct ceph_connection_operations *ops;struct ceph_messenger *msgr; + +atomic_t sock_state;struct socket *sock; +struct ceph_entity_addr peer_addr;/* peer address */ +struct ceph_entity_addr peer_addr_for_me; +unsigned long flags;unsigned long state;const char *error_msg;/* error message, if any */ -struct ceph_entity_addr peer_addr;/* peer address */ struct ceph_entity_name peer_name;/* peer name */ -struct ceph_entity_addr peer_addr_for_me; +unsigned peer_features;u32 connect_seq;/* identify the most recent connection attempt for this connection, client */
net/ceph/messenger.c +64 -0
106 lines not on this page · raw message
Greg Kroah-Hartman
maintainerPATCH 100/171 libceph: provide osd number when creating osd
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit e10006f807ffc4d5b1d861305d18d9e8145891ca)
Pass the osd number to the create_osd() routine, and move the initialization of fields that depend on it therein.
--- net/ceph/osd_client.c | 8 ++++---- 1 file changed, 4 insertions(+), 4 deletions(-)
net/ceph/osd_client.c +4 -4
@@ -624,7 +624,7 @@ static void osd_reset(struct ceph_connec/* * Track open sessions with osds. */ -static struct ceph_osd *create_osd (struct ceph_osd_client *osdc) +static struct ceph_osd *create_osd (struct ceph_osd_client *osdc,int onum) {struct ceph_osd *osd;
@@ -634,6 +634,7 @@ static struct ceph_osd *create_osd(strucatomic_set (&osd->o_ref,1 ); osd->o_osdc = osdc; + osd->o_osd = onum;INIT_LIST_HEAD (&osd->o_requests);INIT_LIST_HEAD (&osd->o_linger_requests);INIT_LIST_HEAD (&osd->o_osd_lru);
@@ -643,6 +644,7 @@ static struct ceph_osd *create_osd(struc osd->o_con.private = osd; osd->o_con.ops = &osd_con_ops; osd->o_con.peer_name.type =CEPH_ENTITY_TYPE_OSD ; + osd->o_con.peer_name.num =cpu_to_le64 (onum);INIT_LIST_HEAD (&osd->o_keepalive_item);return osd;
@@ -998,15 +1000,13 @@ static int __map_request(struct ceph_osd req->r_osd =__lookup_osd (osdc, o);if (!req->r_osd && o >=0 ) { err = -ENOMEM ; - req->r_osd =create_osd (osdc); + req->r_osd =create_osd (osdc, o);if (!req->r_osd) {list_move (&req->r_req_lru_item, &osdc->req_notarget); goto out; }dout ("map_request osd %p is osd%d\n" , req->r_osd, o); - req->r_osd->o_osd = o; - req->r_osd->o_con.peer_name.num =cpu_to_le64 (o);__insert_osd (osdc, req->r_osd);ceph_con_open (&req->r_osd->o_con, &osdc->osdmap->osd_addr[o]);
Greg Kroah-Hartman
maintainerPATCH 101/171 libceph: set CLOSED state bit in con_init
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit a5988c490ef66cb04ea2f610681949b25c773b3c)
Once a connection is fully initialized, it is really in a CLOSED state, so make that explicit by setting the bit in its state field.
It is possible for a connection in NEGOTIATING state to get a failure, leading to ceph_fault() and ultimately ceph_con_close(). Clear that bits if it is set in that case, to reflect that the connection truly is closed and is no longer participating in a connect sequence.
Issue a warning if ceph_con_open() is called on a connection that is not in CLOSED state.
--- net/ceph/messenger.c | 15 +++++++++++---- 1 file changed, 11 insertions(+), 4 deletions(-)
net/ceph/messenger.c +11 -4
@@ -454,11 +454,14 @@ void ceph_con_close(struct ceph_connecti {dout ("con_close %p peer %s\n" , con,ceph_pr_addr (&con->peer_addr.in_addr)); -set_bit (CLOSED , &con->state);/* in case there's queued work */ +clear_bit (NEGOTIATING , &con->state);clear_bit (STANDBY , &con->state);/* avoid connect_seq bump */ +set_bit (CLOSED , &con->state); +clear_bit (LOSSYTX , &con->flags);/* so we retry next connect */ clear_bit (KEEPALIVE_PENDING , &con->flags);clear_bit (WRITE_PENDING , &con->flags); +mutex_lock (&con->mutex);reset_connection (con); con->peer_global_seq =0 ;
@@ -475,7 +478,8 @@ void ceph_con_open(struct ceph_connectio {dout ("con_open %p %s\n" , con,ceph_pr_addr (&addr->in_addr));set_bit (OPENING , &con->state); -clear_bit (CLOSED , &con->state); +WARN_ON (!test_and_clear_bit (CLOSED , &con->state)); +memcpy (&con->peer_addr, addr,sizeof (*addr)); con->delay =0 ;/* reset backoff memory */ queue_con (con);
@@ -530,6 +534,8 @@ void ceph_con_init(struct ceph_messengerINIT_LIST_HEAD (&con->out_queue);INIT_LIST_HEAD (&con->out_sent);INIT_DELAYED_WORK (&con->work, con_work); + +set_bit (CLOSED , &con->state); }EXPORT_SYMBOL (ceph_con_init);
@@ -1937,14 +1943,15 @@ more:/* open the socket first? */ if (con->sock ==NULL ) { +clear_bit (NEGOTIATING , &con->state); +set_bit (CONNECTING , &con->state); +con_out_kvec_reset (con);prepare_write_banner (con); ret =prepare_write_connect (con);if (ret <0 ) goto out;prepare_read_banner (con); -set_bit (CONNECTING , &con->state); -clear_bit (NEGOTIATING , &con->state);BUG_ON (con->in_msg); con->in_tag =CEPH_MSGR_TAG_READY ;
Greg Kroah-Hartman
maintainerPATCH 102/171 libceph: embed ceph connection structure in mon_client
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 67130934fb579fdf0f2f6d745960264378b57dc8)
A monitor client has a pointer to a ceph connection structure in it. This is the only one of the three ceph client types that do it this way; the OSD and MDS clients embed the connection into their main structures. There is always exactly one ceph connection for a monitor client, so there is no need to allocate it separate from the monitor client structure.
So switch the ceph_mon_client structure to embed its ceph_connection structure.
--- include/linux/ceph/mon_client.h | 2 - net/ceph/mon_client.c | 47 +++++++++++++++++----------------------- 2 files changed, 21 insertions(+), 28 deletions(-)
include/linux/ceph/mon_client.h +1 -1
@@ -70,7 +70,7 @@ struct ceph_mon_client {bool hunting;int cur_mon;/* last monitor i contacted */ unsigned long sub_sent, sub_renew_after; -struct ceph_connection *con; +struct ceph_connection con;bool have_fsid;/* pending generic requests */
net/ceph/mon_client.c +20 -27
126 lines not on this page · raw message
Greg Kroah-Hartman
maintainerPATCH 103/171 libceph: drop connection refcounting for mon_client
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit ec87ef4309d33bd9c87a53bb5152a86ae7a65f25)
All references to the embedded ceph_connection come from the msgr workqueue, which is drained prior to mon_client destruction. That means we can ignore con refcounting entirely.
--- net/ceph/mon_client.c | 18 ++++++++++++++++-- 1 file changed, 16 insertions(+), 2 deletions(-)
net/ceph/mon_client.c +16 -2
@@ -1037,9 +1037,23 @@ out:mutex_unlock (&monc->mutex); } +/* +* We can ignore refcounting on the connection struct, as all references +* will come from the messenger workqueue, which is drained prior to +* mon_client destruction. +*/ +static struct ceph_connection *con_get (struct ceph_connection *con) +{ +return con; +} + +static void con_put (struct ceph_connection *con) +{ +} +static const struct ceph_connection_operations mon_con_ops = { - .get = ceph_con_get, - .put = ceph_con_put, + .get = con_get, + .put = con_put, .dispatch = dispatch, .fault = mon_fault, .alloc_msg = mon_alloc_msg,
Greg Kroah-Hartman
maintainerPATCH 104/171 libceph: init monitor connection when opening
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 20581c1faf7b15ae1f8b80c0ec757877b0b53151)
Hold off initializing a monitor client's connection until just before it gets opened for use.
--- net/ceph/mon_client.c | 13 ++++++------- 1 file changed, 6 insertions(+), 7 deletions(-)
net/ceph/mon_client.c +6 -7
@@ -119,6 +119,7 @@ static void __close_session(struct ceph_dout ("__close_session closing mon%d\n" , monc->cur_mon);ceph_con_revoke (&monc->con, monc->m_auth);ceph_con_close (&monc->con); + monc->con.private =NULL ; monc->cur_mon =-1 ; monc->pending_auth =0 ;ceph_auth_reset (monc->auth);
@@ -141,9 +142,13 @@ static int __open_session(struct ceph_mo monc->sub_renew_after = jiffies;/* i.e., expired */ monc->want_next_osdmap = !!monc->want_next_osdmap; -dout ("open_session mon%d opening\n" , monc->cur_mon); +ceph_con_init (&monc->client->msgr, &monc->con); + monc->con.private = monc; + monc->con.ops = &mon_con_ops; monc->con.peer_name.type =CEPH_ENTITY_TYPE_MON ; monc->con.peer_name.num =cpu_to_le64 (monc->cur_mon); + +dout ("open_session mon%d opening\n" , monc->cur_mon);ceph_con_open (&monc->con, &monc->monmap->mon_inst[monc->cur_mon].addr);
@@ -760,10 +765,6 @@ int ceph_monc_init(struct ceph_mon_clien goto out;/* connection */ -ceph_con_init (&monc->client->msgr, &monc->con); - monc->con.private = monc; - monc->con.ops = &mon_con_ops; -/* authentication */ monc->auth =ceph_auth_init (cl->options->name, cl->options->key);
@@ -836,8 +837,6 @@ void ceph_monc_stop(struct ceph_mon_cliemutex_lock (&monc->mutex);__close_session (monc); - monc->con.private =NULL ; -mutex_unlock (&monc->mutex);/*
Greg Kroah-Hartman
maintainerPATCH 105/171 libceph: fully initialize connection in con_init()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 1bfd89f4e6e1adc6a782d94aa5d4c53be1e404d7)
Move the initialization of a ceph connection's private pointer, operations vector pointer, and peer name information into ceph_con_init(). Rearrange the arguments so the connection pointer is first. Hide the byte-swapping of the peer entity number inside ceph_con_init()
--- fs/ceph/mds_client.c | 7 ++----- include/linux/ceph/messenger.h | 6 ++++-- net/ceph/messenger.c | 9 ++++++++- net/ceph/mon_client.c | 8 +++----- net/ceph/osd_client.c | 7 ++----- 5 files changed, 19 insertions(+), 18 deletions(-)
fs/ceph/mds_client.c +2 -5
@@ -394,11 +394,8 @@ static struct ceph_mds_session *register s->s_seq =0 ;mutex_init (&s->s_mutex); -ceph_con_init (&mdsc->fsc->client->msgr, &s->s_con); - s->s_con.private = s; - s->s_con.ops = &mds_con_ops; - s->s_con.peer_name.type =CEPH_ENTITY_TYPE_MDS ; - s->s_con.peer_name.num =cpu_to_le64 (mds); +ceph_con_init (&s->s_con, s, &mds_con_ops, &mdsc->fsc->client->msgr, +CEPH_ENTITY_TYPE_MDS , mds);spin_lock_init (&s->s_gen_ttl_lock); s->s_cap_gen =0 ;
include/linux/ceph/messenger.h +4 -2
@@ -219,8 +219,10 @@ extern void ceph_messenger_init(struct cu32 required_features, bool nocrc); -extern void ceph_con_init (struct ceph_messenger *msgr, -struct ceph_connection *con); +extern void ceph_con_init (struct ceph_connection *con,void *private, +const struct ceph_connection_operations *ops, +struct ceph_messenger *msgr,__u8 entity_type, +__u64 entity_num);extern void ceph_con_open (struct ceph_connection *con,struct ceph_entity_addr *addr);extern bool ceph_con_opened (struct ceph_connection *con);
net/ceph/messenger.c +8 -1
@@ -521,15 +521,22 @@ void ceph_con_put(struct ceph_connection/* * initialize a new connection. */ -void ceph_con_init (struct ceph_messenger *msgr,struct ceph_connection *con) +void ceph_con_init (struct ceph_connection *con,void *private, +const struct ceph_connection_operations *ops, +struct ceph_messenger *msgr,__u8 entity_type,__u64 entity_num) {dout ("con_init %p\n" , con);memset (con,0 ,sizeof (*con)); + con->private = private; + con->ops = ops;atomic_set (&con->nref,1 ); con->msgr = msgr;con_sock_state_init (con); + con->peer_name.type = (__u8 ) entity_type; + con->peer_name.num =cpu_to_le64 (entity_num); +mutex_init (&con->mutex);INIT_LIST_HEAD (&con->out_queue);INIT_LIST_HEAD (&con->out_sent);
net/ceph/mon_client.c +3 -5
@@ -142,11 +142,9 @@ static int __open_session(struct ceph_mo monc->sub_renew_after = jiffies;/* i.e., expired */ monc->want_next_osdmap = !!monc->want_next_osdmap; -ceph_con_init (&monc->client->msgr, &monc->con); - monc->con.private = monc; - monc->con.ops = &mon_con_ops; - monc->con.peer_name.type =CEPH_ENTITY_TYPE_MON ; - monc->con.peer_name.num =cpu_to_le64 (monc->cur_mon); +ceph_con_init (&monc->con, monc, &mon_con_ops, + &monc->client->msgr, +CEPH_ENTITY_TYPE_MON , monc->cur_mon);dout ("open_session mon%d opening\n" , monc->cur_mon); ceph_con_open(&monc->con,
net/ceph/osd_client.c +2 -5
@@ -640,11 +640,8 @@ static struct ceph_osd *create_osd(strucINIT_LIST_HEAD (&osd->o_osd_lru); osd->o_incarnation =1 ; -ceph_con_init (&osdc->client->msgr, &osd->o_con); - osd->o_con.private = osd; - osd->o_con.ops = &osd_con_ops; - osd->o_con.peer_name.type =CEPH_ENTITY_TYPE_OSD ; - osd->o_con.peer_name.num =cpu_to_le64 (onum); +ceph_con_init (&osd->o_con, osd, &osd_con_ops, &osdc->client->msgr, +CEPH_ENTITY_TYPE_OSD , onum);INIT_LIST_HEAD (&osd->o_keepalive_item);return osd;
Greg Kroah-Hartman
maintainerPATCH 106/171 libceph: tweak ceph_alloc_msg()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 1c20f2d26795803fc4f5155fe4fca5717a5944b6)
The function ceph_alloc_msg() is only used to allocate a message that will be assigned to a connection's in_msg pointer. Rename the function so this implied usage is more clear.
In addition, make that assignment inside the function (again, since that's precisely what it's intended to be used for). This allows us to return what is now provided via the passed-in address of a "skip" variable. The return type is now Boolean to be explicit that there are only two possible outcomes.
Make sure the result of an ->alloc_msg method call always sets the value of *skip properly.
--- net/ceph/messenger.c | 61 +++++++++++++++++++++++++++----------------------- net/ceph/mon_client.c | 3 ++ net/ceph/osd_client.c | 1 3 files changed, 38 insertions(+), 27 deletions(-)
net/ceph/messenger.c +34 -27
@@ -1659,9 +1659,8 @@ static int read_partial_message_section(return 1 ; } -static struct ceph_msg *ceph_alloc_msg (struct ceph_connection *con, -struct ceph_msg_header *hdr, -int *skip); +static bool ceph_con_in_msg_alloc (struct ceph_connection *con, +struct ceph_msg_header *hdr); static int read_partial_message_pages(struct ceph_connection *con,
@@ -1744,7 +1743,6 @@ static int read_partial_message(struct cint ret;unsigned front_len, middle_len, data_len;bool do_datacrc = !con->msgr->nocrc; -int skip;u64 seq;u32 crc;
@@ -1797,9 +1795,7 @@ static int read_partial_message(struct cif (!con->in_msg) {dout ("got hdr type %d front %d data %d\n" , con->in_hdr.type, con->in_hdr.front_len, con->in_hdr.data_len); - skip =0 ; - con->in_msg =ceph_alloc_msg (con, &con->in_hdr, &skip); -if (skip) { +if (ceph_con_in_msg_alloc (con, &con->in_hdr)) {/* skip this message */ dout ("alloc_msg said skip message\n" );BUG_ON (con->in_msg);
@@ -2581,46 +2577,57 @@ static int ceph_alloc_middle(struct ceph }/* -* Generic message allocator, for incoming messages. +* Allocate a message for receiving an incoming message on a +* connection, and save the result in con->in_msg. Uses the +* connection's private alloc_msg op if available. +* +* Returns true if the message should be skipped, false otherwise. +* If true is returned (skip message), con->in_msg will be NULL. +* If false is returned, con->in_msg will contain a pointer to the +* newly-allocated message, or NULL in case of memory exhaustion. */ -static struct ceph_msg *ceph_alloc_msg (struct ceph_connection *con, -struct ceph_msg_header *hdr, -int *skip) +static bool ceph_con_in_msg_alloc (struct ceph_connection *con, +struct ceph_msg_header *hdr) {int type =le16_to_cpu (hdr->type);int front_len =le32_to_cpu (hdr->front_len);int middle_len =le32_to_cpu (hdr->middle_len); -struct ceph_msg *msg =NULL ;int ret; +BUG_ON (con->in_msg !=NULL ); +if (con->ops->alloc_msg) { +int skip =0 ; +mutex_unlock (&con->mutex); - msg = con->ops->alloc_msg (con, hdr, skip); + con->in_msg = con->ops->alloc_msg (con, hdr, &skip);mutex_lock (&con->mutex); -if (!msg || *skip) -return NULL ; +if (skip) + con->in_msg =NULL ; + +if (!con->in_msg) +return skip !=0 ; } -if (!msg) { - *skip =0 ; - msg =ceph_msg_new (type, front_len,GFP_NOFS , false); -if (!msg) { +if (!con->in_msg) { + con->in_msg =ceph_msg_new (type, front_len,GFP_NOFS , false); +if (!con->in_msg) {pr_err ("unable to allocate msg type %d len %d\n" , type, front_len); -return NULL ; +return false; } - msg->page_alignment =le16_to_cpu (hdr->data_off); + con->in_msg->page_alignment =le16_to_cpu (hdr->data_off); } -memcpy (&msg->hdr, &con->in_hdr,sizeof (con->in_hdr)); +memcpy (&con->in_msg->hdr, &con->in_hdr,sizeof (con->in_hdr)); -if (middle_len && !msg->middle) { - ret =ceph_alloc_middle (con, msg); +if (middle_len && !con->in_msg->middle) { + ret =ceph_alloc_middle (con, con->in_msg);if (ret <0 ) { -ceph_msg_put (msg); -return NULL ; +ceph_msg_put (con->in_msg); + con->in_msg =NULL ; } } -return msg; +return false; }
net/ceph/mon_client.c +3 -0
@@ -442,6 +442,7 @@ static struct ceph_msg *get_generic_repl m =NULL ; }else {dout ("get_generic_reply %lld got %p\n" , tid, req->reply); + *skip =0 ; m =ceph_msg_get (req->reply);/* * we don't need to track the connection reading into
@@ -990,6 +991,8 @@ static struct ceph_msg *mon_alloc_msg(stcase CEPH_MSG_MDS_MAP :case CEPH_MSG_OSD_MAP : m =ceph_msg_new (type, front_len,GFP_NOFS , false); +if (!m) +return NULL ;/* ENOMEM--return skip == 0 */ break ; }
net/ceph/osd_client.c +1 -0
@@ -2077,6 +2077,7 @@ static struct ceph_msg *alloc_msg(structint type =le16_to_cpu (hdr->type);int front =le32_to_cpu (hdr->front_len); + *skip =0 ;switch (type) {case CEPH_MSG_OSD_MAP :case CEPH_MSG_WATCH_NOTIFY :
Greg Kroah-Hartman
maintainerPATCH 107/171 libceph: have messages point to their connection
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 38941f8031bf042dba3ced6394ba3a3b16c244ea)
When a ceph message is queued for sending it is placed on a list of pending messages (ceph_connection->out_queue). When they are actually sent over the wire, they are moved from that list to another (ceph_connection->out_sent). When acknowledgement for the message is received, it is removed from the sent messages list.
During that entire time the message is "in the possession" of a single ceph connection. Keep track of that connection in the message. This will be used in the next patch (and is a helpful bit of information for debugging anyway).
--- include/linux/ceph/messenger.h | 3 +++ net/ceph/messenger.c | 27 +++++++++++++++++++++++++-- 2 files changed, 28 insertions(+), 2 deletions(-)
include/linux/ceph/messenger.h +3 -0
@@ -77,7 +77,10 @@ struct ceph_msg {unsigned nr_pages;/* size of page array */ unsigned page_alignment;/* io offset in first page */ struct ceph_pagelist *pagelist;/* instead of pages */ + +struct ceph_connection *con;struct list_head list_head; +struct kref kref;struct bio *bio;/* instead of pages/pagelist */ struct bio *bio_iter;/* bio iterator */
net/ceph/messenger.c +25 -2
@@ -414,6 +414,9 @@ static int con_close_socket(struct ceph_static void ceph_msg_remove (struct ceph_msg *msg) {list_del_init (&msg->list_head); +BUG_ON (msg->con ==NULL ); + msg->con =NULL ; +ceph_msg_put (msg); }static void ceph_msg_remove_list (struct list_head *head)
@@ -433,6 +436,8 @@ static void reset_connection(struct cephceph_msg_remove_list (&con->out_sent);if (con->in_msg) { +BUG_ON (con->in_msg->con != con); + con->in_msg->con =NULL ;ceph_msg_put (con->in_msg); con->in_msg =NULL ; }
@@ -625,8 +630,10 @@ static void prepare_write_message(struct &con->out_temp_ack); } +BUG_ON (list_empty (&con->out_queue)); m = list_first_entry(&con->out_queue, struct ceph_msg, list_head); con->out_msg = m; +BUG_ON (m->con != con);/* put message on sent list */ ceph_msg_get (m);
@@ -1810,6 +1817,8 @@ static int read_partial_message(struct c"error allocating memory for incoming message" ;return -ENOMEM ; } + +BUG_ON (con->in_msg->con != con); m = con->in_msg; m->front.iov_len =0 ;/* haven't read it yet */ if (m->middle)
@@ -1905,6 +1914,8 @@ static void process_message(struct ceph_ {struct ceph_msg *msg; +BUG_ON (con->in_msg->con != con); + con->in_msg->con =NULL ; msg = con->in_msg; con->in_msg =NULL ;
@@ -2264,6 +2275,8 @@ static void ceph_fault(struct ceph_connecon_close_socket (con);if (con->in_msg) { +BUG_ON (con->in_msg->con != con); + con->in_msg->con =NULL ;ceph_msg_put (con->in_msg); con->in_msg =NULL ; }
@@ -2382,6 +2395,8 @@ void ceph_con_send(struct ceph_connectio/* queue */ mutex_lock (&con->mutex); +BUG_ON (msg->con !=NULL ); + msg->con = con;BUG_ON (!list_empty (&msg->list_head));list_add_tail (&msg->list_head, &con->out_queue); dout("----- %p to %s%lld %d=%s len %d+%d+%d -----\n", msg,
@@ -2407,13 +2422,16 @@ void ceph_con_revoke(struct ceph_connect {mutex_lock (&con->mutex);if (!list_empty (&msg->list_head)) { -dout ("con_revoke %p msg %p - was on queue\n" , con, msg); +dout ("%s %p msg %p - was on queue\n" , __func__, con, msg);list_del_init (&msg->list_head); +BUG_ON (msg->con ==NULL ); + msg->con =NULL ; +ceph_msg_put (msg); msg->hdr.seq =0 ; }if (con->out_msg == msg) { -dout ("con_revoke %p msg %p - was sending\n" , con, msg); +dout ("%s %p msg %p - was sending\n" , __func__, con, msg); con->out_msg =NULL ;if (con->out_kvec_is_msg) { con->out_skip = con->out_kvec_bytes;
@@ -2482,6 +2500,8 @@ struct ceph_msg *ceph_msg_new(int type,if (m ==NULL ) goto out;kref_init (&m->kref); + + m->con =NULL ;INIT_LIST_HEAD (&m->list_head); m->hdr.tid =0 ;
@@ -2602,6 +2622,8 @@ static bool ceph_con_in_msg_alloc(structmutex_unlock (&con->mutex); con->in_msg = con->ops->alloc_msg (con, hdr, &skip);mutex_lock (&con->mutex); +if (con->in_msg) + con->in_msg->con = con;if (skip) con->in_msg =NULL ;
@@ -2615,6 +2637,7 @@ static bool ceph_con_in_msg_alloc(struct type, front_len);return false; } + con->in_msg->con = con; con->in_msg->page_alignment =le16_to_cpu (hdr->data_off); }memcpy (&con->in_msg->hdr, &con->in_hdr,sizeof (con->in_hdr));
Greg Kroah-Hartman
maintainerPATCH 108/171 libceph: have messages take a connection reference
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 92ce034b5a740046cc643a21ea21eaad589e0043)
There are essentially two types of ceph messages: incoming and outgoing. Outgoing messages are always allocated via ceph_msg_new(), and at the time of their allocation they are not associated with any particular connection. Incoming messages are always allocated via ceph_con_in_msg_alloc(), and they are initially associated with the connection from which incoming data will be placed into the message.
When an outgoing message gets sent, it becomes associated with a connection and remains that way until the message is successfully sent. The association of an incoming message goes away at the point it is sent to an upper layer via a con->ops->dispatch method.
This patch implements reference counting for all ceph messages, such that every message holds a reference (and a pointer) to a connection if and only if it is associated with that connection (as described above).
For background, here is an explanation of the ceph message lifecycle, emphasizing when an association exists between a message and a connection.
Outgoing Messages
An outgoing message is "owned" by its allocator, from the time it is allocated in ceph_msg_new() up to the point it gets queued for sending in ceph_con_send(). Prior to that point the message's msg->con pointer is null; at the point it is queued for sending its message pointer is assigned to refer to the connection. At that time the message is inserted into a connection's out_queue list.
When a message on the out_queue list has been sent to the socket layer to be put on the wire, it is transferred out of that list and into the connection's out_sent list. At that point it is still owned by the connection, and will remain so until an acknowledgement is received from the recipient that indicates the message was successfully transferred. When such an acknowledgement is received (in process_ack()), the message is removed from its list (in ceph_msg_remove()), at which point it is no longer associated with the connection.
So basically, any time a message is on one of a connection's lists, it is associated with that connection. Reference counting outgoing messages can thus be done at the points a message is added to the out_queue (in ceph_con_send()) and the point it is removed from either its two lists (in ceph_msg_remove())--at which point its connection pointer becomes null.
Incoming Messages
When an incoming message on a connection is getting read (in read_partial_message()) and there is no message in con->in_msg, a new one is allocated using ceph_con_in_msg_alloc(). At that point the message is associated with the connection. Once that message has been completely and successfully read, it is passed to upper layer code using the connection's con->ops->dispatch method. At that point the association between the message and the connection no longer exists.
Reference counting of connections for incoming messages can be done by taking a reference to the connection when the message gets allocated, and releasing that reference when it gets handed off using the dispatch method.
We should never fail to get a connection reference for a message--the since the caller should already hold one.
--- net/ceph/messenger.c | 24 ++++++++++++++++++------ 1 file changed, 18 insertions(+), 6 deletions(-)
net/ceph/messenger.c +18 -6
@@ -415,6 +415,7 @@ static void ceph_msg_remove(struct ceph_ {list_del_init (&msg->list_head);BUG_ON (msg->con ==NULL ); +ceph_con_put (msg->con); msg->con =NULL ;ceph_msg_put (msg);
@@ -440,6 +441,7 @@ static void reset_connection(struct ceph con->in_msg->con =NULL ;ceph_msg_put (con->in_msg); con->in_msg =NULL ; +ceph_con_put (con->in_msg->con); } con->connect_seq =0 ;
@@ -1918,6 +1920,7 @@ static void process_message(struct ceph_ con->in_msg->con =NULL ; msg = con->in_msg; con->in_msg =NULL ; +ceph_con_put (con);/* if first message, set peer_name */ if (con->peer_name.type ==0 )
@@ -2279,6 +2282,7 @@ static void ceph_fault(struct ceph_conne con->in_msg->con =NULL ;ceph_msg_put (con->in_msg); con->in_msg =NULL ; +ceph_con_put (con); }/* Requeue anything that hasn't been acked */
@@ -2395,8 +2399,11 @@ void ceph_con_send(struct ceph_connectio/* queue */ mutex_lock (&con->mutex); +BUG_ON (msg->con !=NULL ); - msg->con = con; + msg->con =ceph_con_get (con); +BUG_ON (msg->con ==NULL ); +BUG_ON (!list_empty (&msg->list_head));list_add_tail (&msg->list_head, &con->out_queue); dout("----- %p to %s%lld %d=%s len %d+%d+%d -----\n", msg,
@@ -2425,10 +2432,11 @@ void ceph_con_revoke(struct ceph_connectdout ("%s %p msg %p - was on queue\n" , __func__, con, msg);list_del_init (&msg->list_head);BUG_ON (msg->con ==NULL ); +ceph_con_put (msg->con); msg->con =NULL ; + msg->hdr.seq =0 ;ceph_msg_put (msg); - msg->hdr.seq =0 ; }if (con->out_msg == msg) {dout ("%s %p msg %p - was sending\n" , __func__, con, msg);
@@ -2437,8 +2445,9 @@ void ceph_con_revoke(struct ceph_connect con->out_skip = con->out_kvec_bytes; con->out_kvec_is_msg = false; } -ceph_msg_put (msg); msg->hdr.seq =0 ; + +ceph_msg_put (msg); }mutex_unlock (&con->mutex); }
@@ -2622,8 +2631,10 @@ static bool ceph_con_in_msg_alloc(structmutex_unlock (&con->mutex); con->in_msg = con->ops->alloc_msg (con, hdr, &skip);mutex_lock (&con->mutex); -if (con->in_msg) - con->in_msg->con = con; +if (con->in_msg) { + con->in_msg->con =ceph_con_get (con); +BUG_ON (con->in_msg->con ==NULL ); + }if (skip) con->in_msg =NULL ;
@@ -2637,7 +2648,8 @@ static bool ceph_con_in_msg_alloc(struct type, front_len);return false; } - con->in_msg->con = con; + con->in_msg->con =ceph_con_get (con); +BUG_ON (con->in_msg->con ==NULL ); con->in_msg->page_alignment =le16_to_cpu (hdr->data_off); }memcpy (&con->in_msg->hdr, &con->in_hdr,sizeof (con->in_hdr));
Greg Kroah-Hartman
maintainerPATCH 109/171 libceph: make ceph_con_revoke() a msg operation
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 6740a845b2543cc46e1902ba21bac743fbadd0dc)
ceph_con_revoke() is passed both a message and a ceph connection. Now that any message associated with a connection holds a pointer to that connection, there's no need to provide the connection when revoking a message.
This has the added benefit of precluding the possibility of the providing the wrong connection pointer. If the message's connection pointer is null, it is not being tracked by any connection, so revoking it is a no-op. This is supported as a convenience for upper layers, so they can revoke a message that is not actually "in flight."
Rename the function ceph_msg_revoke() to reflect that it is really an operation on a message, not a connection.
--- include/linux/ceph/messenger.h | 3 ++- net/ceph/messenger.c | 7 ++++++- net/ceph/mon_client.c | 8 ++++---- net/ceph/osd_client.c | 4 ++-- 4 files changed, 14 insertions(+), 8 deletions(-)
include/linux/ceph/messenger.h +2 -1
@@ -231,7 +231,8 @@ extern void ceph_con_open(struct ceph_coextern bool ceph_con_opened (struct ceph_connection *con);extern void ceph_con_close (struct ceph_connection *con);extern void ceph_con_send (struct ceph_connection *con,struct ceph_msg *msg); -extern void ceph_con_revoke (struct ceph_connection *con,struct ceph_msg *msg); + +extern void ceph_msg_revoke (struct ceph_msg *msg);extern void ceph_con_revoke_message (struct ceph_connection *con,struct ceph_msg *msg);extern void ceph_con_keepalive (struct ceph_connection *con);
net/ceph/messenger.c +6 -1
@@ -2425,8 +2425,13 @@ EXPORT_SYMBOL(ceph_con_send);/* * Revoke a message that was previously queued for send */ -void ceph_con_revoke (struct ceph_connection *con,struct ceph_msg *msg) +void ceph_msg_revoke (struct ceph_msg *msg) { +struct ceph_connection *con = msg->con; + +if (!con) +return ;/* Message not in our possession */ +mutex_lock (&con->mutex);if (!list_empty (&msg->list_head)) {dout ("%s %p msg %p - was on queue\n" , __func__, con, msg);
net/ceph/mon_client.c +4 -4
@@ -106,7 +106,7 @@ static void __send_prepared_auth_request monc->pending_auth =1 ; monc->m_auth->front.iov_len = len; monc->m_auth->hdr.front_len =cpu_to_le32 (len); -ceph_con_revoke (&monc->con, monc->m_auth); +ceph_msg_revoke (monc->m_auth);ceph_msg_get (monc->m_auth);/* keep our ref */ ceph_con_send (&monc->con, monc->m_auth); }
@@ -117,7 +117,7 @@ static void __send_prepared_auth_requeststatic void __close_session (struct ceph_mon_client *monc) {dout ("__close_session closing mon%d\n" , monc->cur_mon); -ceph_con_revoke (&monc->con, monc->m_auth); +ceph_msg_revoke (monc->m_auth);ceph_con_close (&monc->con); monc->con.private =NULL ; monc->cur_mon =-1 ;
@@ -229,7 +229,7 @@ static void __send_subscribe(struct ceph msg->front.iov_len = p - msg->front.iov_base; msg->hdr.front_len =cpu_to_le32 (msg->front.iov_len); -ceph_con_revoke (&monc->con, msg); +ceph_msg_revoke (msg);ceph_con_send (&monc->con,ceph_msg_get (msg)); monc->sub_sent = jiffies |1 ;/* never 0 */
@@ -688,7 +688,7 @@ static void __resend_generic_request(strfor (p =rb_first (&monc->generic_request_tree); p; p =rb_next (p)) { req = rb_entry(p, struct ceph_mon_generic_request, node); -ceph_con_revoke (&monc->con, req->request); +ceph_msg_revoke (req->request);ceph_con_send (&monc->con,ceph_msg_get (req->request)); } }
net/ceph/osd_client.c +2 -2
@@ -852,7 +852,7 @@ static void __unregister_request(structif (req->r_osd) {/* make sure the original request isn't in flight. */ -ceph_con_revoke (&req->r_osd->o_con, req->r_request); +ceph_msg_revoke (req->r_request);list_del_init (&req->r_osd_item); if (list_empty(&req->r_osd->o_requests) &&
@@ -879,7 +879,7 @@ static void __unregister_request(structstatic void __cancel_request (struct ceph_osd_request *req) {if (req->r_sent && req->r_osd) { -ceph_con_revoke (&req->r_osd->o_con, req->r_request); +ceph_msg_revoke (req->r_request); req->r_sent =0 ; } }
Greg Kroah-Hartman
maintainerPATCH 110/171 libceph: make ceph_con_revoke_message() a msg op
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 8921d114f5574c6da2cdd00749d185633ecf88f3)
ceph_con_revoke_message() is passed both a message and a ceph connection. A ceph_msg allocated for incoming messages on a connection always has a pointer to that connection, so there's no need to provide the connection when revoking such a message.
Note that the existing logic does not preclude the message supplied being a null/bogus message pointer. The only user of this interface is the OSD client, and the only value an osd client passes is a request's r_reply field. That is always non-null (except briefly in an error path in ceph_osdc_alloc_request(), and that drops the only reference so the request won't ever have a reply to revoke). So we can safely assume the passed-in message is non-null, but add a BUG_ON() to make it very obvious we are imposing this restriction.
Rename the function ceph_msg_revoke_incoming() to reflect that it is really an operation on an incoming message.
--- include/linux/ceph/messenger.h | 4 ++-- net/ceph/messenger.c | 22 ++++++++++++++++------ net/ceph/osd_client.c | 9 ++++----- 3 files changed, 22 insertions(+), 13 deletions(-)
include/linux/ceph/messenger.h +2 -2
@@ -233,8 +233,8 @@ extern void ceph_con_close(struct ceph_cextern void ceph_con_send (struct ceph_connection *con,struct ceph_msg *msg);extern void ceph_msg_revoke (struct ceph_msg *msg); -extern void ceph_con_revoke_message (struct ceph_connection *con, -struct ceph_msg *msg); +extern void ceph_msg_revoke_incoming (struct ceph_msg *msg); +extern void ceph_con_keepalive (struct ceph_connection *con);extern struct ceph_connection *ceph_con_get (struct ceph_connection *con);extern void ceph_con_put (struct ceph_connection *con);
net/ceph/messenger.c +16 -6
@@ -2460,17 +2460,27 @@ void ceph_msg_revoke(struct ceph_msg *ms/* * Revoke a message that we may be reading data into */ -void ceph_con_revoke_message (struct ceph_connection *con,struct ceph_msg *msg) +void ceph_msg_revoke_incoming (struct ceph_msg *msg) { +struct ceph_connection *con; + +BUG_ON (msg ==NULL ); +if (!msg->con) { +dout ("%s msg %p null con\n" , __func__, msg); + +return ;/* Message not in our possession */ + } + + con = msg->con;mutex_lock (&con->mutex); -if (con->in_msg && con->in_msg == msg) { +if (con->in_msg == msg) {unsigned front_len =le32_to_cpu (con->in_hdr.front_len);unsigned middle_len =le32_to_cpu (con->in_hdr.middle_len);unsigned data_len =le32_to_cpu (con->in_hdr.data_len);/* skip rest of message */ -dout ("con_revoke_pages %p msg %p revoked\n" , con, msg); - con->in_base_pos = con->in_base_pos - +dout ("%s %p msg %p revoked\n" , __func__, con, msg); + con->in_base_pos = con->in_base_pos -sizeof (struct ceph_msg_header ) - front_len - middle_len -
@@ -2481,8 +2491,8 @@ void ceph_con_revoke_message(struct ceph con->in_tag =CEPH_MSGR_TAG_READY ; con->in_seq++; }else { -dout ("con_revoke_pages %p msg %p pages %p no-op\n" , - con, con->in_msg, msg); +dout ("%s %p in_msg %p msg %p no-op\n" , + __func__, con, con->in_msg, msg); }mutex_unlock (&con->mutex); }
net/ceph/osd_client.c +4 -5
@@ -140,10 +140,9 @@ void ceph_osdc_release_request(struct krif (req->r_request)ceph_msg_put (req->r_request);if (req->r_con_filling_msg) { -dout ("release_request revoking pages %p from con %p\n" , +dout ("%s revoking pages %p from con %p\n" , __func__, req->r_pages, req->r_con_filling_msg); -ceph_con_revoke_message (req->r_con_filling_msg, - req->r_reply); +ceph_msg_revoke_incoming (req->r_reply); req->r_con_filling_msg->ops->put (req->r_con_filling_msg); }if (req->r_reply)
@@ -2022,9 +2021,9 @@ static struct ceph_msg *get_reply(struct }if (req->r_con_filling_msg) { -dout ("get_reply revoking msg %p from old con %p\n" , +dout ("%s revoking msg %p from old con %p\n" , __func__, req->r_reply, req->r_con_filling_msg); -ceph_con_revoke_message (req->r_con_filling_msg, req->r_reply); +ceph_msg_revoke_incoming (req->r_reply); req->r_con_filling_msg->ops->put (req->r_con_filling_msg); req->r_con_filling_msg =NULL ; }
Greg Kroah-Hartman
maintainerPATCH 111/171 libceph: fix overflow in __decode_pool_names()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Xi Wang <[email protected]>
(cherry picked from commit ad3b904c07dfa88603689bf9a67bffbb9b99beb5)
len' is read from network and thus needs validation. Otherwise a large len' would cause out-of-bounds access via the memcpy() call. In addition, len = 0xffffffff would overflow the kmalloc() size, leading to out-of-bounds write.
This patch adds a check of `len' via ceph_decode_need(). Also use kstrndup rather than kmalloc/memcpy.
[[email protected]: added -ENOMEM return for null kstrndup() result]
--- net/ceph/osdmap.c | 13 +++++++------ 1 file changed, 7 insertions(+), 6 deletions(-)
net/ceph/osdmap.c +7 -6
@@ -495,15 +495,16 @@ static int __decode_pool_names(void **p,ceph_decode_32_safe (p, end, pool, bad);ceph_decode_32_safe (p, end, len, bad);dout (" pool %d len %d\n" , pool, len); +ceph_decode_need (p, end, len, bad); pi =__lookup_pg_pool (&map->pg_pools, pool);if (pi) { +char *name =kstrndup (*p, len,GFP_NOFS ); + +if (!name) +return -ENOMEM ;kfree (pi->name); - pi->name =kmalloc (len +1 ,GFP_NOFS ); -if (pi->name) { -memcpy (pi->name, *p, len); - pi->name[len] ='\0' ; -dout (" name is %s\n" , pi->name); - } + pi->name = name; +dout (" name is %s\n" , pi->name); } *p += len; }
Greg Kroah-Hartman
maintainerPATCH 112/171 libceph: fix overflow in osdmap_decode()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Xi Wang <[email protected]>
(cherry picked from commit e91a9b639a691e0982088b5954eaafb5a25c8f1c)
On 32-bit systems, a large n' would overflow n * sizeof(u32)' and bypass the check ceph_decode_need(p, end, n * sizeof(u32), bad). It would also overflow the subsequent kmalloc() size, leading to out-of-bounds write.
--- net/ceph/osdmap.c | 3 +++ 1 file changed, 3 insertions(+)
net/ceph/osdmap.c +3 -0
@@ -674,6 +674,9 @@ struct ceph_osdmap *osdmap_decode(void *ceph_decode_need (p, end,sizeof (u32) +sizeof (u64), bad);ceph_decode_copy (p, &pgid,sizeof (pgid)); n =ceph_decode_32 (p); + err = -EINVAL ; +if (n > (UINT_MAX -sizeof (*pg)) /sizeof (u32)) + goto bad;ceph_decode_need (p, end, n *sizeof (u32), bad); err = -ENOMEM ; pg =kmalloc (sizeof (*pg) + n*sizeof (u32),GFP_NOFS );
Greg Kroah-Hartman
maintainerPATCH 113/171 libceph: fix overflow in osdmap_apply_incremental()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Xi Wang <[email protected]>
(cherry picked from commit a5506049500b30dbc5edb4d07a3577477c1f3643)
On 32-bit systems, a large pglen' would overflow pglen*sizeof(u32)' and bypass the check ceph_decode_need(p, end, pglen*sizeof(u32), bad). It would also overflow the subsequent kmalloc() size, leading to out-of-bounds write.
--- net/ceph/osdmap.c | 4 ++++ 1 file changed, 4 insertions(+)
net/ceph/osdmap.c +4 -0
@@ -900,6 +900,10 @@ struct ceph_osdmap *osdmap_apply_increme (void )__remove_pg_mapping (&map->pg_temp, pgid);/* insert */ +if (pglen > (UINT_MAX -sizeof (*pg)) /sizeof (u32)) { + err = -EINVAL ; + goto bad; + } pg =kmalloc (sizeof (*pg) +sizeof (u32)*pglen,GFP_NOFS );if (!pg) { err = -ENOMEM ;
Greg Kroah-Hartman
maintainerPATCH 114/171 libceph: transition socket state prior to actual connect
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 89a86be0ce20022f6ede8bccec078dbb3d63caaa)
Once we call ->connect(), we are racing against the actual connection, and a subsequent transition from CONNECTING -> CONNECTED. Set the state to CONNECTING before that, under the protection of the mutex, to avoid the race.
This was introduced in 928443cd9644e7cfd46f687dbeffda2d1a357ff9, with the original socket state code.
--- net/ceph/messenger.c | 3 +-- 1 file changed, 1 insertion(+), 2 deletions(-)
net/ceph/messenger.c +1 -2
@@ -321,6 +321,7 @@ static int ceph_tcp_connect(struct ceph_dout ("connect %s\n" ,ceph_pr_addr (&con->peer_addr.in_addr)); +con_sock_state_connecting (con); ret = sock->ops->connect (sock, (struct sockaddr *)paddr,sizeof (*paddr),O_NONBLOCK );if (ret == -EINPROGRESS ) {
@@ -336,8 +337,6 @@ static int ceph_tcp_connect(struct ceph_return ret; } con->sock = sock; -con_sock_state_connecting (con); -return 0 ; }
Greg Kroah-Hartman
maintainerPATCH 115/171 libceph: fix NULL dereference in reset_connection()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Dan Carpenter <[email protected]>
(cherry picked from commit 26ce171915f348abd1f41da1ed139d93750d987f)
We dereference "con->in_msg" on the line after it was set to NULL.
--- net/ceph/messenger.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
net/ceph/messenger.c +1 -1
@@ -440,7 +440,7 @@ static void reset_connection(struct ceph con->in_msg->con =NULL ;ceph_msg_put (con->in_msg); con->in_msg =NULL ; -ceph_con_put (con->in_msg->con); +ceph_con_put (con); } con->connect_seq =0 ;
Greg Kroah-Hartman
maintainerPATCH 116/171 libceph: use con get/put methods
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 36eb71aa57e6a33d61fd90a2fd87f00c6844bc86)
The ceph_con_get/put() helpers manipulate the embedded con ref count, which isn't used now that ceph_connections are embedded in other structures.
--- net/ceph/messenger.c | 16 ++++++++-------- 1 file changed, 8 insertions(+), 8 deletions(-)
net/ceph/messenger.c +8 -8
@@ -414,7 +414,7 @@ static void ceph_msg_remove(struct ceph_ {list_del_init (&msg->list_head);BUG_ON (msg->con ==NULL ); -ceph_con_put (msg->con); + msg->con->ops->put (msg->con); msg->con =NULL ;ceph_msg_put (msg);
@@ -440,7 +440,7 @@ static void reset_connection(struct ceph con->in_msg->con =NULL ;ceph_msg_put (con->in_msg); con->in_msg =NULL ; -ceph_con_put (con); + con->ops->put (con); } con->connect_seq =0 ;
@@ -1919,7 +1919,7 @@ static void process_message(struct ceph_ con->in_msg->con =NULL ; msg = con->in_msg; con->in_msg =NULL ; -ceph_con_put (con); + con->ops->put (con);/* if first message, set peer_name */ if (con->peer_name.type ==0 )
@@ -2281,7 +2281,7 @@ static void ceph_fault(struct ceph_conne con->in_msg->con =NULL ;ceph_msg_put (con->in_msg); con->in_msg =NULL ; -ceph_con_put (con); + con->ops->put (con); }/* Requeue anything that hasn't been acked */
@@ -2400,7 +2400,7 @@ void ceph_con_send(struct ceph_connectiomutex_lock (&con->mutex);BUG_ON (msg->con !=NULL ); - msg->con =ceph_con_get (con); + msg->con = con->ops->get (con);BUG_ON (msg->con ==NULL );BUG_ON (!list_empty (&msg->list_head));
@@ -2436,7 +2436,7 @@ void ceph_msg_revoke(struct ceph_msg *msdout ("%s %p msg %p - was on queue\n" , __func__, con, msg);list_del_init (&msg->list_head);BUG_ON (msg->con ==NULL ); -ceph_con_put (msg->con); + msg->con->ops->put (msg->con); msg->con =NULL ; msg->hdr.seq =0 ;
@@ -2646,7 +2646,7 @@ static bool ceph_con_in_msg_alloc(struct con->in_msg = con->ops->alloc_msg (con, hdr, &skip);mutex_lock (&con->mutex);if (con->in_msg) { - con->in_msg->con =ceph_con_get (con); + con->in_msg->con = con->ops->get (con);BUG_ON (con->in_msg->con ==NULL ); }if (skip)
@@ -2662,7 +2662,7 @@ static bool ceph_con_in_msg_alloc(struct type, front_len);return false; } - con->in_msg->con =ceph_con_get (con); + con->in_msg->con = con->ops->get (con);BUG_ON (con->in_msg->con ==NULL ); con->in_msg->page_alignment =le16_to_cpu (hdr->data_off); }
Greg Kroah-Hartman
maintainerPATCH 117/171 libceph: drop ceph_con_get/put helpers and nref member
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit d59315ca8c0de00df9b363f94a2641a30961ca1c)
These are no longer used. Every ceph_connection instance is embedded in another structure, and refcounts manipulated via the get/put ops.
--- include/linux/ceph/messenger.h | 1 - net/ceph/messenger.c | 28 +--------------------------- 2 files changed, 1 insertion(+), 28 deletions(-)
include/linux/ceph/messenger.h +0 -1
@@ -135,7 +135,6 @@ struct ceph_msg_pos {*/ struct ceph_connection {void *private; -atomic_t nref;const struct ceph_connection_operations *ops;
net/ceph/messenger.c +1 -27
@@ -501,30 +501,6 @@ bool ceph_con_opened(struct ceph_connect }/* -* generic get/put -*/ -struct ceph_connection *ceph_con_get (struct ceph_connection *con) -{ -int nref =__atomic_add_unless (&con->nref,1 ,0 ); - -dout ("con_get %p nref = %d -> %d\n" , con, nref, nref +1 ); - -return nref ? con :NULL ; -} - -void ceph_con_put (struct ceph_connection *con) -{ -int nref =atomic_dec_return (&con->nref); - -BUG_ON (nref <0 ); -if (nref ==0 ) { -BUG_ON (con->sock); -kfree (con); - } -dout ("con_put %p nref = %d -> %d\n" , con, nref +1 , nref); -} - -/* * initialize a new connection. */ void ceph_con_init(struct ceph_connection *con, void *private,
@@ -535,7 +511,6 @@ void ceph_con_init(struct ceph_connectiomemset (con,0 ,sizeof (*con)); con->private = private; con->ops = ops; -atomic_set (&con->nref,1 ); con->msgr = msgr;con_sock_state_init (con);
@@ -1951,8 +1926,7 @@ static int try_write(struct ceph_connect {int ret =1 ; -dout ("try_write start %p state %lu nref %d\n" , con, con->state, -atomic_read (&con->nref)); +dout ("try_write start %p state %lu\n" , con, con->state); more:dout ("try_write out_kvec_bytes %d\n" , con->out_kvec_bytes);
Re: [ 117/171] libceph: drop ceph_con_get/put helpers and nref member
Quoted 13 lines · Greg Kroah-Hartman
3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit
d59315ca8c0de00df9b363f94a2641a30961ca1c)These are no longer used. Every
ceph_connectioninstance is embedded in another structure, and refcounts manipulated via the get/put ops.Signed-off-by Sage Weil <[email protected]>Signed-off-by Greg Kroah-Hartman <[email protected]>
[...]
Quoted 17 lines
/*
- * generic get/put
- */net/ceph/messenger.c +0
-13-struct ceph_connection *ceph_con_get (struct ceph_connection *con) -{ -int nref =__atomic_add_unless (&con->nref,1 ,0 ); - -dout ("con_get %p nref = %d -> %d\n" , con, nref, nref +1 ); - -return nref ? con :NULL ; -} - -void ceph_con_put (struct ceph_connection *con) -{ -int nref =atomic_dec_return (&con->nref); -
net/ceph/messenger.c bool ceph_con_opened(struct ceph_connect · line 504
Quoted 10 lines
net/ceph/messenger.c +0
-9-BUG_ON (nref <0 ); -if (nref ==0 ) { -BUG_ON (con->sock); -kfree (con); - } -dout ("con_put %p nref = %d -> %d\n" , con, nref +1 , nref); -} - -/* * initialize a new connection.
Although harmless in functionality not having it, may be it would be good to also apply with this also the following commit:
commit 261030215d970c62f799e6e508e3c68fc7ec2aa9
Author: Alex Elder <[email protected]> Date: Thu Jun 21 12:49:23 2012 -0700
libceph: drop declaration of ceph_con_get()
For some reason the declaration of ceph_con_get() and ceph_con_put() did not get deleted in this commit:
d59315ca libceph: drop ceph_con_get/put helpers and nref member
Clean that up.
Signature · 2 lines
[]'s Herton
Greg Kroah-Hartman
maintainerRe: [ 117/171] libceph: drop ceph_con_get/put helpers and nref member
Quoted 50 lines · Herton Ronaldo Krzesinski
Quoted 13 lines · Greg Kroah-Hartman
3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit
d59315ca8c0de00df9b363f94a2641a30961ca1c)These are no longer used. Every
ceph_connectioninstance is embedded in another structure, and refcounts manipulated via the get/put ops.Signed-off-by Sage Weil <[email protected]>Signed-off-by Greg Kroah-Hartman <[email protected]>[...]
Quoted 17 lines
/*
- * generic get/put
- */net/ceph/messenger.c +0
-13-struct ceph_connection *ceph_con_get (struct ceph_connection *con) -{ -int nref =__atomic_add_unless (&con->nref,1 ,0 ); - -dout ("con_get %p nref = %d -> %d\n" , con, nref, nref +1 ); - -return nref ? con :NULL ; -} - -void ceph_con_put (struct ceph_connection *con) -{ -int nref =atomic_dec_return (&con->nref); -net/ceph/messenger.c bool ceph_con_opened(struct ceph_connect · line 504
Quoted 10 lines
net/ceph/messenger.c +0
-9-BUG_ON (nref <0 ); -if (nref ==0 ) { -BUG_ON (con->sock); -kfree (con); - } -dout ("con_put %p nref = %d -> %d\n" , con, nref +1 , nref); -} - -/* * initialize a new connection. Although harmless in functionality not having it, may be it would be good to also apply with this also the following commit:
commit
261030215d970c62f799e6e508e3c68fc7ec2aa9Author: Alex Elder <[email protected]> Date: Thu Jun 21 12:49:23 2012 -0700
Quoted 7 lines
libceph: drop declaration of
ceph_con_get()For some reason the declaration of
ceph_con_get()andceph_con_put()did not get deleted in this commit:
d59315calibceph: drop ceph_con_get/put helpers and nref memberClean that up.
Ok, now added, thanks.
greg k-h
Greg Kroah-Hartman
maintainerPATCH 118/171 libceph: encapsulate out message data setup
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 739c905baa018c99003564ebc367d93aa44d4861)
Move the code that prepares to write the data portion of a message into its own function.
--- net/ceph/messenger.c | 37 +++++++++++++++++++++++-------------- 1 file changed, 23 insertions(+), 14 deletions(-)
net/ceph/messenger.c +23 -14
@@ -565,6 +565,24 @@ static void con_out_kvec_add(struct ceph con->out_kvec_bytes += size; } +static void prepare_write_message_data (struct ceph_connection *con) +{ +struct ceph_msg *msg = con->out_msg; + +BUG_ON (!msg); +BUG_ON (!msg->hdr.data_len); + +/* initialize page iterator */ + con->out_msg_pos.page =0 ; +if (msg->pages) + con->out_msg_pos.page_pos = msg->page_alignment; +else + con->out_msg_pos.page_pos =0 ; + con->out_msg_pos.data_pos =0 ; + con->out_msg_pos.did_page_crc = false; + con->out_more =1 ;/* data + footer will follow */ +} +/* * Prepare footer for currently outgoing message, and finish things * off. Assumes out_kvec* are already valid.. we just add on to the end.
@@ -657,26 +675,17 @@ static void prepare_write_message(struct con->out_msg->footer.middle_crc =cpu_to_le32 (crc); }else con->out_msg->footer.middle_crc =0 ; - con->out_msg->footer.data_crc =0 ; -dout ("prepare_write_message front_crc %u data_crc %u\n" , +dout ("%s front_crc %u middle_crc %u\n" , __func__,le32_to_cpu (con->out_msg->footer.front_crc),le32_to_cpu (con->out_msg->footer.middle_crc));/* is there a data payload? */ -if (le32_to_cpu (m->hdr.data_len) >0 ) { -/* initialize page iterator */ - con->out_msg_pos.page =0 ; -if (m->pages) - con->out_msg_pos.page_pos = m->page_alignment; -else - con->out_msg_pos.page_pos =0 ; - con->out_msg_pos.data_pos =0 ; - con->out_msg_pos.did_page_crc = false; - con->out_more =1 ;/* data + footer will follow */ - }else { + con->out_msg->footer.data_crc =0 ; +if (m->hdr.data_len) +prepare_write_message_data (con); +else /* no, queue up footer too and be done */ prepare_write_message_footer (con); - }set_bit (WRITE_PENDING , &con->flags); }
Greg Kroah-Hartman
maintainerPATCH 119/171 libceph: encapsulate advancing msg page
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 84ca8fc87fcf4ab97bb8acdb59bf97bb4820cb14)
In write_partial_msg_pages(), once all the data from a page has been sent we advance to the next one. Put the code that takes care of this into its own function.
While modifying write_partial_msg_pages(), make its local variable "in_trail" be Boolean, and use the local variable "msg" (which is just the connection's current out_msg pointer) consistently.
--- net/ceph/messenger.c | 58 +++++++++++++++++++++++++++++---------------------- 1 file changed, 34 insertions(+), 24 deletions(-)
net/ceph/messenger.c +34 -24
@@ -891,6 +891,33 @@ static void iter_bio_next(struct bio **b }#endif +static void out_msg_pos_next (struct ceph_connection *con,struct page *page, +size_t len,size_t sent,bool in_trail) +{ +struct ceph_msg *msg = con->out_msg; + +BUG_ON (!msg); +BUG_ON (!sent); + + con->out_msg_pos.data_pos += sent; + con->out_msg_pos.page_pos += sent; +if (sent == len) { + con->out_msg_pos.page_pos =0 ; + con->out_msg_pos.page++; + con->out_msg_pos.did_page_crc = false; +if (in_trail) +list_move_tail (&page->lru, + &msg->trail->head); +else if (msg->pagelist) +list_move_tail (&page->lru, + &msg->pagelist->head); +#ifdef CONFIG_BLOCK + else if (msg->bio) + iter_bio_next(&msg->bio_iter, &msg->bio_seg); +#endif + } +} +/* * Write as much message data payload as we can. If we finish, queue * up the footer.
@@ -906,11 +933,11 @@ static int write_partial_msg_pages(strucbool do_datacrc = !con->msgr->nocrc;int ret;int total_max_write; -int in_trail =0 ; +bool in_trail = false;size_t trail_len = (msg->trail ? msg->trail->length :0 );dout ("write_partial_msg_pages %p msg %p page %d/%d offset %d\n" , - con, con->out_msg, con->out_msg_pos.page, con->out_msg->nr_pages, + con, msg, con->out_msg_pos.page, msg->nr_pages, con->out_msg_pos.page_pos);#ifdef CONFIG_BLOCK
@@ -934,13 +961,12 @@ static int write_partial_msg_pages(struc/* have we reached the trail part of the data? */ if (con->out_msg_pos.data_pos >= data_len - trail_len) { - in_trail =1 ; + in_trail = true; total_max_write = data_len - con->out_msg_pos.data_pos; page =list_first_entry (&msg->trail->head, struct page, lru); - max_write =PAGE_SIZE ; }else if (msg->pages) { page = msg->pages[con->out_msg_pos.page]; }else if (msg->pagelist) {
@@ -964,14 +990,14 @@ static int write_partial_msg_pages(strucif (do_datacrc && !con->out_msg_pos.did_page_crc) {void *base;u32 crc; -u32 tmpcrc =le32_to_cpu (con->out_msg->footer.data_crc); +u32 tmpcrc =le32_to_cpu (msg->footer.data_crc);char *kaddr; kaddr =kmap (page);BUG_ON (kaddr ==NULL ); base = kaddr + con->out_msg_pos.page_pos + bio_offset; crc =crc32c (tmpcrc, base, len); - con->out_msg->footer.data_crc =cpu_to_le32 (crc); + msg->footer.data_crc =cpu_to_le32 (crc); con->out_msg_pos.did_page_crc = true; } ret = ceph_tcp_sendpage(con->sock, page,
@@ -984,30 +1010,14 @@ static int write_partial_msg_pages(strucif (ret <=0 ) goto out; - con->out_msg_pos.data_pos += ret; - con->out_msg_pos.page_pos += ret; -if (ret == len) { - con->out_msg_pos.page_pos =0 ; - con->out_msg_pos.page++; - con->out_msg_pos.did_page_crc = false; -if (in_trail) -list_move_tail (&page->lru, - &msg->trail->head); -else if (msg->pagelist) -list_move_tail (&page->lru, - &msg->pagelist->head); -#ifdef CONFIG_BLOCK - else if (msg->bio) - iter_bio_next(&msg->bio_iter, &msg->bio_seg); -#endif - } +out_msg_pos_next (con, page, len, (size_t ) ret, in_trail); }dout ("write_partial_msg_pages %p msg %p done\n" , con, msg);/* prepare and queue up footer, too */ if (!do_datacrc) - con->out_msg->footer.flags |=CEPH_MSG_FOOTER_NOCRC ; + msg->footer.flags |=CEPH_MSG_FOOTER_NOCRC ;con_out_kvec_reset (con);prepare_write_message_footer (con); ret =1 ;
Greg Kroah-Hartman
maintainerPATCH 120/171 libceph: dont mark footer complete before it is
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit fd154f3c75465abd83b7a395033e3755908a1e6e)
This is a nit, but prepare_write_message() sets the FOOTER_COMPLETE flag before the CRC for the data portion (recorded in the footer) has been completely computed. Hold off setting the complete flag until we've decided it's ready to send.
--- net/ceph/messenger.c | 4 +++- 1 file changed, 3 insertions(+), 1 deletion(-)
net/ceph/messenger.c +3 -1
@@ -592,6 +592,8 @@ static void prepare_write_message_footerstruct ceph_msg *m = con->out_msg;int v = con->out_kvec_left; + m->footer.flags |=CEPH_MSG_FOOTER_COMPLETE ; +dout ("prepare_write_message_footer %p\n" , con); con->out_kvec_is_msg = true; con->out_kvec[v].iov_base = &m->footer;
@@ -665,7 +667,7 @@ static void prepare_write_message(struct/* fill in crc (except data pages), footer */ crc =crc32c (0 , &m->hdr, offsetof(struct ceph_msg_header , crc)); con->out_msg->hdr.crc =cpu_to_le32 (crc); - con->out_msg->footer.flags =CEPH_MSG_FOOTER_COMPLETE ; + con->out_msg->footer.flags =0 ; crc =crc32c (0 , m->front.iov_base, m->front.iov_len); con->out_msg->footer.front_crc =cpu_to_le32 (crc);
Greg Kroah-Hartman
maintainerPATCH 121/171 libceph: move init_bio_*() functions up
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit df6ad1f97342ebc4270128222e896541405eecdb)
Move init_bio_iter() and iter_bio_next() up in their source file so the'll be defined before they're needed.
--- net/ceph/messenger.c | 50 +++++++++++++++++++++++++------------------------- 1 file changed, 25 insertions(+), 25 deletions(-)
net/ceph/messenger.c +25 -25
@@ -565,6 +565,31 @@ static void con_out_kvec_add(struct ceph con->out_kvec_bytes += size; } +#ifdef CONFIG_BLOCK +static void init_bio_iter (struct bio *bio,struct bio **iter,int *seg) +{ +if (!bio) { + *iter =NULL ; + *seg =0 ; +return ; + } + *iter = bio; + *seg = bio->bi_idx; +} + +static void iter_bio_next (struct bio **bio_iter,int *seg) +{ +if (*bio_iter ==NULL ) +return ; + +BUG_ON (*seg >= (*bio_iter)->bi_vcnt); + + (*seg)++; +if (*seg == (*bio_iter)->bi_vcnt) +init_bio_iter ((*bio_iter)->bi_next, bio_iter, seg); +} +#endif +static void prepare_write_message_data (struct ceph_connection *con) {struct ceph_msg *msg = con->out_msg;
@@ -868,31 +893,6 @@ out:return ret;/* done! */ } -#ifdef CONFIG_BLOCK -static void init_bio_iter (struct bio *bio,struct bio **iter,int *seg) -{ -if (!bio) { - *iter =NULL ; - *seg =0 ; -return ; - } - *iter = bio; - *seg = bio->bi_idx; -} - -static void iter_bio_next (struct bio **bio_iter,int *seg) -{ -if (*bio_iter ==NULL ) -return ; - -BUG_ON (*seg >= (*bio_iter)->bi_vcnt); - - (*seg)++; -if (*seg == (*bio_iter)->bi_vcnt) -init_bio_iter ((*bio_iter)->bi_next, bio_iter, seg); -} -#endif -static void out_msg_pos_next (struct ceph_connection *con,struct page *page,size_t len,size_t sent,bool in_trail) {
Greg Kroah-Hartman
maintainerPATCH 122/171 libceph: move init of bio_iter
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 572c588edadaa3da3992bd8a0fed830bbcc861f8)
If a message has a non-null bio pointer, its bio_iter field is initialized in write_partial_msg_pages() if this has not been done already. This is really a one-time setup operation for sending a message's (bio) data, so move that initialization code into prepare_write_message_data() which serves that purpose.
--- net/ceph/messenger.c | 9 ++++----- 1 file changed, 4 insertions(+), 5 deletions(-)
net/ceph/messenger.c +4 -5
@@ -603,6 +603,10 @@ static void prepare_write_message_data(s con->out_msg_pos.page_pos = msg->page_alignment; else con->out_msg_pos.page_pos = 0; +#ifdef CONFIG_BLOCK +if (msg->bio && !msg->bio_iter) +init_bio_iter (msg->bio, &msg->bio_iter, &msg->bio_seg); +#endif con->out_msg_pos.data_pos =0 ; con->out_msg_pos.did_page_crc = false; con->out_more =1 ;/* data + footer will follow */
@@ -942,11 +946,6 @@ static int write_partial_msg_pages(struc con, msg, con->out_msg_pos.page, msg->nr_pages, con->out_msg_pos.page_pos); -#ifdef CONFIG_BLOCK -if (msg->bio && !msg->bio_iter) -init_bio_iter (msg->bio, &msg->bio_iter, &msg->bio_seg); -#endif -while (data_len > con->out_msg_pos.data_pos) {struct page *page =NULL ;int max_write =PAGE_SIZE ;
Greg Kroah-Hartman
maintainerPATCH 123/171 libceph: dont use bio_iter as a flag
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit abdaa6a849af1d63153682c11f5bbb22dacb1f6b)
Recently a bug was fixed in which the bio_iter field in a ceph message was not being properly re-initialized when a message got re-transmitted:
commit 43643528cce60ca184fe8197efa8e8da7c89a037
Author: Yan, Zheng <[email protected]>
rbd: Clear ceph_msg->bio_iter for retransmitted messageWe are now only initializing the bio_iter field when we are about to start to write message data (in prepare_write_message_data()), rather than every time we are attempting to write any portion of the message data (in write_partial_msg_pages()). This means we no longer need to use the msg->bio_iter field as a flag.
So just don't do that any more. Trust prepare_write_message_data() to ensure msg->bio_iter is properly initialized, every time we are about to begin writing (or re-writing) a message's bio data.
--- net/ceph/messenger.c | 6 +----- 1 file changed, 1 insertion(+), 5 deletions(-)
net/ceph/messenger.c +1 -5
@@ -604,7 +604,7 @@ static void prepare_write_message_data(selse con->out_msg_pos.page_pos =0 ;#ifdef CONFIG_BLOCK -if (msg->bio && !msg->bio_iter) +if (msg->bio)init_bio_iter (msg->bio, &msg->bio_iter, &msg->bio_seg);#endif con->out_msg_pos.data_pos =0 ;
@@ -672,10 +672,6 @@ static void prepare_write_message(struct m->hdr.seq =cpu_to_le64 (++con->out_seq); m->needs_out_seq = false; } -#ifdef CONFIG_BLOCK - else - m->bio_iter = NULL; -#endif dout("prepare_write_message %p seq %lld type %d len %d+%d+%d %d pgs\n", m, con->out_seq, le16_to_cpu(m->hdr.type),
Greg Kroah-Hartman
maintainerPATCH 124/171 libceph: SOCK_CLOSED is a flag, not a state
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit a8d00e3cdef4c1c4f194414b72b24cd995439a05)
The following commit changed it so SOCK_CLOSED bit was stored in a connection's new "flags" field rather than its "state" field.
libceph: start separating connection flags from state commit 928443cd
That bit is used in con_close_socket() to protect against setting an error message more than once in the socket event handler function.
Unfortunately, the field being operated on in that function was not updated to be "flags" as it should have been. This fixes that error.
--- net/ceph/messenger.c | 4 ++-- 1 file changed, 2 insertions(+), 2 deletions(-)
net/ceph/messenger.c +2 -2
@@ -397,11 +397,11 @@ static int con_close_socket(struct ceph_dout ("con_close_socket on %p sock %p\n" , con, con->sock);if (!con->sock)return 0 ; -set_bit (SOCK_CLOSED , &con->state); +set_bit (SOCK_CLOSED , &con->flags); rc = con->sock->ops->shutdown (con->sock,SHUT_RDWR );sock_release (con->sock); con->sock =NULL ; -clear_bit (SOCK_CLOSED , &con->state); +clear_bit (SOCK_CLOSED , &con->flags);con_sock_state_closed (con);return rc; }
Greg Kroah-Hartman
maintainerPATCH 125/171 libceph: dont change socket state on sock event
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 188048bce311ee41e5178bc3255415d0eae28423)
Currently the socket state change event handler records an error message on a connection to distinguish a close while connecting from a close while a connection was already established.
Changing connection information during handling of a socket event is not very clean, so instead move this assignment inside con_work(), where it can be done during normal connection-level processing (and under protection of the connection mutex as well).
Move the handling of a socket closed event up to the top of the processing loop in con_work(); there's no point in handling backoff etc. if we have a newly-closed socket to take care of.
--- net/ceph/messenger.c | 18 +++++++++--------- 1 file changed, 9 insertions(+), 9 deletions(-)
net/ceph/messenger.c +9 -9
@@ -261,13 +261,8 @@ static void ceph_sock_state_change(struccase TCP_CLOSE_WAIT :dout ("%s TCP_CLOSE_WAIT\n" , __func__);con_sock_state_closing (con); -if (test_and_set_bit (SOCK_CLOSED , &con->flags) ==0 ) { -if (test_bit (CONNECTING , &con->state)) - con->error_msg ="connection failed" ; -else - con->error_msg ="socket closed" ; +if (!test_and_set_bit (SOCK_CLOSED , &con->flags))queue_con (con); - }break ;case TCP_ESTABLISHED :dout ("%s TCP_ESTABLISHED\n" , __func__);
@@ -2187,6 +2182,14 @@ static void con_work(struct work_structmutex_lock (&con->mutex); restart: +if (test_and_clear_bit (SOCK_CLOSED , &con->flags)) { +if (test_bit (CONNECTING , &con->state)) + con->error_msg ="connection failed" ; +else + con->error_msg ="socket closed" ; + goto fault; + } +if (test_and_clear_bit (BACKOFF , &con->flags)) {dout ("con_work %p backing off\n" , con); if (queue_delayed_work(ceph_msgr_wq, &con->work,
@@ -2216,9 +2219,6 @@ restart:con_close_socket (con); } -if (test_and_clear_bit (SOCK_CLOSED , &con->flags)) - goto fault; - ret =try_read (con);if (ret == -EAGAIN ) goto restart;
Greg Kroah-Hartman
maintainerPATCH 126/171 libceph: just set SOCK_CLOSED when state changes
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit d65c9e0b9eb43d14ece9dd843506ccba06162ee7)
When a TCP_CLOSE or TCP_CLOSE_WAIT event occurs, the SOCK_CLOSED connection flag bit is set, and if it had not been previously set queue_con() is called to ensure con_work() will get a chance to handle the changed state.
con_work() atomically checks--and if set, clears--the SOCK_CLOSED bit if it was set. This means that even if the bit were set repeatedly, the related processing in con_work() only gets called once per transition of the bit from 0 to 1.
What's important then is that we ensure con_work() gets called *at least* once when a socket close event occurs, not that it gets called *exactly* once.
The work queue mechanism already takes care of queueing work only if it is not already queued, so there's no need for us to call queue_con() conditionally.
So this patch just makes it so the SOCK_CLOSED flag gets set unconditionally in ceph_sock_state_change().
--- net/ceph/messenger.c | 4 ++-- 1 file changed, 2 insertions(+), 2 deletions(-)
net/ceph/messenger.c +2 -2
@@ -261,8 +261,8 @@ static void ceph_sock_state_change(struccase TCP_CLOSE_WAIT :dout ("%s TCP_CLOSE_WAIT\n" , __func__);con_sock_state_closing (con); -if (!test_and_set_bit (SOCK_CLOSED , &con->flags)) -queue_con (con); +set_bit (SOCK_CLOSED , &con->flags); +queue_con (con);break ;case TCP_ESTABLISHED :dout ("%s TCP_ESTABLISHED\n" , __func__);
Greg Kroah-Hartman
maintainerPATCH 127/171 libceph: dont touch con state in con_close_socket()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 456ea46865787283088b23a8a7f69244513b95f0)
In con_close_socket(), a connection's SOCK_CLOSED flag gets set and then cleared while its shutdown method is called and its reference gets dropped.
Previously, that flag got set only if it had not already been set, so setting it in con_close_socket() might have prevented additional processing being done on a socket being shut down. We no longer set SOCK_CLOSED in the socket event routine conditionally, so setting that bit here no longer provides whatever benefit it might have provided before.
A race condition could still leave the SOCK_CLOSED bit set even after we've issued the call to con_close_socket(), so we still clear that bit after shutting the socket down. Add a comment explaining the reason for this.
--- net/ceph/messenger.c | 8 +++++++- 1 file changed, 7 insertions(+), 1 deletion(-)
net/ceph/messenger.c +7 -1
@@ -392,10 +392,16 @@ static int con_close_socket(struct ceph_dout ("con_close_socket on %p sock %p\n" , con, con->sock);if (!con->sock)return 0 ; -set_bit (SOCK_CLOSED , &con->flags); rc = con->sock->ops->shutdown (con->sock,SHUT_RDWR );sock_release (con->sock); con->sock =NULL ; + +/* +* Forcibly clear the SOCK_CLOSE flag. It gets set +* independent of the connection mutex, and we could have +* received a socket close event before we had the chance to +* shut the socket down. +*/ clear_bit (SOCK_CLOSED , &con->flags);con_sock_state_closed (con);return rc;
Greg Kroah-Hartman
maintainerPATCH 128/171 libceph: clear CONNECTING in ceph_con_close()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit bb9e6bba5d8b85b631390f8dbe8a24ae1ff5b48a)
A connection that is closed will no longer be connecting. So clear the CONNECTING state bit in ceph_con_close(). Similarly, if the socket has been closed we no longer are in connecting state (a new connect sequence will need to be initiated).
--- net/ceph/messenger.c | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)
net/ceph/messenger.c +2 -1
@@ -462,6 +462,7 @@ void ceph_con_close(struct ceph_connectidout ("con_close %p peer %s\n" , con,ceph_pr_addr (&con->peer_addr.in_addr));clear_bit (NEGOTIATING , &con->state); +clear_bit (CONNECTING , &con->state);clear_bit (STANDBY , &con->state);/* avoid connect_seq bump */ set_bit (CLOSED , &con->state);
@@ -2189,7 +2190,7 @@ static void con_work(struct work_structmutex_lock (&con->mutex); restart:if (test_and_clear_bit (SOCK_CLOSED , &con->flags)) { -if (test_bit (CONNECTING , &con->state)) +if (test_and_clear_bit (CONNECTING , &con->state)) con->error_msg ="connection failed" ;else con->error_msg ="socket closed" ;
Greg Kroah-Hartman
maintainerPATCH 129/171 libceph: clear NEGOTIATING when done
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 3ec50d1868a9e0493046400bb1fdd054c7f64ebd)
A connection state's NEGOTIATING bit gets set while in CONNECTING state after we have successfully exchanged a ceph banner and IP addresses with the connection's peer (the server). But that bit is not cleared again--at least not until another connection attempt is initiated.
Instead, clear it as soon as the connection is fully established. Also, clear it when a socket connection gets prematurely closed in the midst of establishing a ceph connection (in case we had reached the point where it was set).
--- net/ceph/messenger.c | 8 +++++--- 1 file changed, 5 insertions(+), 3 deletions(-)
net/ceph/messenger.c +5 -3
@@ -1562,6 +1562,7 @@ static int process_connect(struct ceph_cfail_protocol (con);return -1 ; } +clear_bit (NEGOTIATING , &con->state);clear_bit (CONNECTING , &con->state); con->peer_global_seq =le32_to_cpu (con->in_reply.global_seq); con->connect_seq++;
@@ -1951,7 +1952,6 @@ more:/* open the socket first? */ if (con->sock ==NULL ) { -clear_bit (NEGOTIATING , &con->state);set_bit (CONNECTING , &con->state);con_out_kvec_reset (con);
@@ -2190,10 +2190,12 @@ static void con_work(struct work_structmutex_lock (&con->mutex); restart:if (test_and_clear_bit (SOCK_CLOSED , &con->flags)) { -if (test_and_clear_bit (CONNECTING , &con->state)) +if (test_and_clear_bit (CONNECTING , &con->state)) { +clear_bit (NEGOTIATING , &con->state); con->error_msg ="connection failed" ; -else + }else { con->error_msg ="socket closed" ; + } goto fault; }
Greg Kroah-Hartman
maintainerPATCH 130/171 libceph: define and use an explicit CONNECTED state
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit e27947c767f5bed15048f4e4dad3e2eb69133697)
There is no state explicitly defined when a ceph connection is fully operational. So define one.
It's set when the connection sequence completes successfully, and is cleared when the connection gets closed.
Be a little more careful when examining the old state when a socket disconnect event is reported.
--- include/linux/ceph/messenger.h | 1 + net/ceph/messenger.c | 9 +++++++-- 2 files changed, 8 insertions(+), 2 deletions(-)
include/linux/ceph/messenger.h +1 -0
@@ -120,6 +120,7 @@ struct ceph_msg_pos {*/ #define CONNECTING 1#define NEGOTIATING 2 +#define CONNECTED 5#define STANDBY 8/* no outgoing messages, socket closed. we keep * the ceph_connection around to maintain shared * state with the peer. */
net/ceph/messenger.c +7 -2
@@ -463,6 +463,7 @@ void ceph_con_close(struct ceph_connecti ceph_pr_addr(&con->peer_addr.in_addr));clear_bit (NEGOTIATING , &con->state);clear_bit (CONNECTING , &con->state); +clear_bit (CONNECTED , &con->state);clear_bit (STANDBY , &con->state);/* avoid connect_seq bump */ set_bit (CLOSED , &con->state);
@@ -1564,6 +1565,7 @@ static int process_connect(struct ceph_c }clear_bit (NEGOTIATING , &con->state);clear_bit (CONNECTING , &con->state); +set_bit (CONNECTED , &con->state); con->peer_global_seq =le32_to_cpu (con->in_reply.global_seq); con->connect_seq++; con->peer_features = server_feat;
@@ -2114,6 +2116,7 @@ more:prepare_read_ack (con);break ;case CEPH_MSGR_TAG_CLOSE : +clear_bit (CONNECTED , &con->state);set_bit (CLOSED , &con->state);/* fixme */ goto out;default :
@@ -2190,11 +2193,13 @@ static void con_work(struct work_structmutex_lock (&con->mutex); restart:if (test_and_clear_bit (SOCK_CLOSED , &con->flags)) { -if (test_and_clear_bit (CONNECTING , &con->state)) { +if (test_and_clear_bit (CONNECTED , &con->state)) + con->error_msg ="socket closed" ; +else if (test_and_clear_bit (CONNECTING , &con->state)) {clear_bit (NEGOTIATING , &con->state); con->error_msg ="connection failed" ; }else { - con->error_msg ="socket closed" ; + con->error_msg ="unrecognized con state" ; } goto fault; }
Greg Kroah-Hartman
maintainerPATCH 131/171 libceph: separate banner and connect writes
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit ab166d5aa3bc036fba7efaca6e4e43a7e9510acf)
There are two phases in the process of linking together the two ends of a ceph connection. The first involves exchanging a banner and IP addresses, and if that is successful a second phase exchanges some detail about each side's connection capabilities.
When initiating a connection, the client side now queues to send its information for both phases of this process at the same time. This is probably a bit more efficient, but it is slightly messier from a layering perspective in the code.
So rearrange things so that the client doesn't send the connection information until it has received and processed the response in the initial banner phase (in process_banner()).
Move the code (in the (con->sock == NULL) case in try_write()) that prepares for writing the connection information, delaying doing that until the banner exchange has completed. Move the code that begins the transition to this second "NEGOTIATING" phase out of process_banner() and into its caller, so preparing to write the connection information and preparing to read the response are adjacent to each other.
Finally, preparing to write the connection information now requires the output kvec to be reset in all cases, so move that into the prepare_write_connect() and delete it from all callers.
--- net/ceph/messenger.c | 20 +++++++++++--------- 1 file changed, 11 insertions(+), 9 deletions(-)
net/ceph/messenger.c +11 -9
@@ -841,6 +841,7 @@ static int prepare_write_connect(struct con->out_connect.authorizer_len = auth ?cpu_to_le32 (auth->authorizer_buf_len) :0 ; +con_out_kvec_reset (con);con_out_kvec_add (con,sizeof (con->out_connect), &con->out_connect);if (auth && auth->authorizer_buf_len)
@@ -1430,8 +1431,6 @@ static int process_banner(struct ceph_co ceph_pr_addr(&con->msgr->inst.addr.in_addr)); } -set_bit (NEGOTIATING , &con->state); -prepare_read_connect (con);return 0 ; }
@@ -1481,7 +1480,6 @@ static int process_connect(struct ceph_creturn -1 ; } con->auth_retry =1 ; -con_out_kvec_reset (con); ret =prepare_write_connect (con);if (ret <0 )return ret;
@@ -1502,7 +1500,6 @@ static int process_connect(struct ceph_cENTITY_NAME (con->peer_name), ceph_pr_addr(&con->peer_addr.in_addr));reset_connection (con); -con_out_kvec_reset (con); ret =prepare_write_connect (con);if (ret <0 )return ret;
@@ -1528,7 +1525,6 @@ static int process_connect(struct ceph_cle32_to_cpu (con->out_connect.connect_seq), le32_to_cpu(con->in_reply.connect_seq)); con->connect_seq =le32_to_cpu (con->in_reply.connect_seq); -con_out_kvec_reset (con); ret =prepare_write_connect (con);if (ret <0 )return ret;
@@ -1545,7 +1541,6 @@ static int process_connect(struct ceph_c le32_to_cpu(con->in_reply.global_seq));get_global_seq (con->msgr,le32_to_cpu (con->in_reply.global_seq)); -con_out_kvec_reset (con); ret =prepare_write_connect (con);if (ret <0 )return ret;
@@ -1958,9 +1953,6 @@ more:con_out_kvec_reset (con);prepare_write_banner (con); - ret =prepare_write_connect (con); -if (ret <0 ) - goto out;prepare_read_banner (con);BUG_ON (con->in_msg);
@@ -2073,6 +2065,16 @@ more: ret =process_banner (con);if (ret <0 ) goto out; + +/* Banner is good, exchange connection info */ + ret =prepare_write_connect (con); +if (ret <0 ) + goto out; +prepare_read_connect (con); +set_bit (NEGOTIATING , &con->state); + +/* Send connection info before awaiting response */ + goto out; } ret =read_partial_connect (con);if (ret <=0 )
Greg Kroah-Hartman
maintainerPATCH 132/171 libceph: distinguish two phases of connect sequence
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 7593af920baac37752190a0db703d2732bed4a3b)
Currently a ceph connection enters a "CONNECTING" state when it begins the process of (re-)connecting with its peer. Once the two ends have successfully exchanged their banner and addresses, an additional NEGOTIATING bit is set in the ceph connection's state to indicate the connection information exhange has begun. The CONNECTING bit/state continues to be set during this phase.
Rather than have the CONNECTING state continue while the NEGOTIATING bit is set, interpret these two phases as distinct states. In other words, when NEGOTIATING is set, clear CONNECTING. That way only one of them will be active at a time.
--- net/ceph/messenger.c | 50 +++++++++++++++++++++++++++----------------------- 1 file changed, 27 insertions(+), 23 deletions(-)
net/ceph/messenger.c +27 -23
@@ -1559,7 +1559,6 @@ static int process_connect(struct ceph_creturn -1 ; }clear_bit (NEGOTIATING , &con->state); -clear_bit (CONNECTING , &con->state);set_bit (CONNECTED , &con->state); con->peer_global_seq =le32_to_cpu (con->in_reply.global_seq); con->connect_seq++;
@@ -2000,7 +1999,8 @@ more_kvec: } do_next: -if (!test_bit (CONNECTING , &con->state)) { +if (!test_bit (CONNECTING , &con->state) && + !test_bit (NEGOTIATING , &con->state)) {/* is anything else pending? */ if (!list_empty (&con->out_queue)) {prepare_write_message (con);
@@ -2057,25 +2057,29 @@ more: }if (test_bit (CONNECTING , &con->state)) { -if (!test_bit (NEGOTIATING , &con->state)) { -dout ("try_read connecting\n" ); - ret =read_partial_banner (con); -if (ret <=0 ) - goto out; - ret =process_banner (con); -if (ret <0 ) - goto out; - -/* Banner is good, exchange connection info */ - ret =prepare_write_connect (con); -if (ret <0 ) - goto out; -prepare_read_connect (con); -set_bit (NEGOTIATING , &con->state); +dout ("try_read connecting\n" ); + ret =read_partial_banner (con); +if (ret <=0 ) + goto out; + ret =process_banner (con); +if (ret <0 ) + goto out; + +clear_bit (CONNECTING , &con->state); +set_bit (NEGOTIATING , &con->state); -/* Send connection info before awaiting response */ +/* Banner is good, exchange connection info */ + ret =prepare_write_connect (con); +if (ret <0 ) goto out; - } +prepare_read_connect (con); + +/* Send connection info before awaiting response */ + goto out; + } + +if (test_bit (NEGOTIATING , &con->state)) { +dout ("try_read negotiating\n" ); ret =read_partial_connect (con);if (ret <=0 ) goto out;
@@ -2197,12 +2201,12 @@ restart:if (test_and_clear_bit (SOCK_CLOSED , &con->flags)) {if (test_and_clear_bit (CONNECTED , &con->state)) con->error_msg ="socket closed" ; -else if (test_and_clear_bit (CONNECTING , &con->state)) { -clear_bit (NEGOTIATING , &con->state); +else if (test_and_clear_bit (NEGOTIATING , &con->state)) + con->error_msg ="negotiation failed" ; +else if (test_and_clear_bit (CONNECTING , &con->state)) con->error_msg ="connection failed" ; - }else { +else con->error_msg ="unrecognized con state" ; - } goto fault; }
Greg Kroah-Hartman
maintainerPATCH 133/171 libceph: small changes to messenger.c
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit 5821bd8ccdf5d17ab2c391c773756538603838c3)
This patch gathers a few small changes in "net/ceph/messenger.c":
out_msg_pos_next()
- small logic change that mostly affects indentation
write_partial_msg_pages().
- use a local variable trail_off to represent the offset into a message of the trail portion of the data (if present)
- once we are in the trail portion we will always be there, so we don't always need to check against our data position
- avoid computing len twice after we've reached the trail
- get rid of the variable tmpcrc, which is not needed
- trail_off and trail_len never change so mark them const
- update some comments
read_partial_message_bio()
- bio_iovec_idx() will never return an error, so don't bother checking for it
--- net/ceph/messenger.c | 63 +++++++++++++++++++++++++-------------------------- 1 file changed, 31 insertions(+), 32 deletions(-)
net/ceph/messenger.c +31 -32
@@ -907,21 +907,23 @@ static void out_msg_pos_next(struct ceph con->out_msg_pos.data_pos += sent; con->out_msg_pos.page_pos += sent; -if (sent == len) { - con->out_msg_pos.page_pos =0 ; - con->out_msg_pos.page++; - con->out_msg_pos.did_page_crc = false; -if (in_trail) -list_move_tail (&page->lru, - &msg->trail->head); -else if (msg->pagelist) -list_move_tail (&page->lru, - &msg->pagelist->head); +if (sent < len) +return ; + +BUG_ON (sent != len); + con->out_msg_pos.page_pos =0 ; + con->out_msg_pos.page++; + con->out_msg_pos.did_page_crc = false; +if (in_trail) +list_move_tail (&page->lru, + &msg->trail->head); +else if (msg->pagelist) +list_move_tail (&page->lru, + &msg->pagelist->head);#ifdef CONFIG_BLOCK - else if (msg->bio) - iter_bio_next(&msg->bio_iter, &msg->bio_seg); + else if (msg->bio) + iter_bio_next(&msg->bio_iter, &msg->bio_seg);#endif - } }/*
@@ -940,30 +942,31 @@ static int write_partial_msg_pages(strucint ret;int total_max_write;bool in_trail = false; -size_t trail_len = (msg->trail ? msg->trail->length :0 ); +const size_t trail_len = (msg->trail ? msg->trail->length :0 ); +const size_t trail_off = data_len - trail_len;dout ("write_partial_msg_pages %p msg %p page %d/%d offset %d\n" , con, msg, con->out_msg_pos.page, msg->nr_pages, con->out_msg_pos.page_pos); +/* +* Iterate through each page that contains data to be +* written, and send as much as possible for each. +* +* If we are calculating the data crc (the default), we will +* need to map the page. If we have no pages, they have +* been revoked, so use the zero page. +*/ while (data_len > con->out_msg_pos.data_pos) {struct page *page =NULL ;int max_write =PAGE_SIZE ;int bio_offset =0 ; - total_max_write = data_len - trail_len - - con->out_msg_pos.data_pos; - -/* -* if we are calculating the data crc (the default), we need -* to map the page. if our pages[] has been revoked, use the -* zero page. -*/ - -/* have we reached the trail part of the data? */ -if (con->out_msg_pos.data_pos >= data_len - trail_len) { - in_trail = true; + in_trail = in_trail || con->out_msg_pos.data_pos >= trail_off; +if (!in_trail) + total_max_write = trail_off - con->out_msg_pos.data_pos; +if (in_trail) { total_max_write = data_len - con->out_msg_pos.data_pos; page = list_first_entry(&msg->trail->head,
@@ -990,14 +993,13 @@ static int write_partial_msg_pages(strucif (do_datacrc && !con->out_msg_pos.did_page_crc) {void *base; -u32 crc; -u32 tmpcrc =le32_to_cpu (msg->footer.data_crc); +u32 crc =le32_to_cpu (msg->footer.data_crc);char *kaddr; kaddr =kmap (page);BUG_ON (kaddr ==NULL ); base = kaddr + con->out_msg_pos.page_pos + bio_offset; - crc =crc32c (tmpcrc, base, len); + crc =crc32c (crc, base, len); msg->footer.data_crc =cpu_to_le32 (crc); con->out_msg_pos.did_page_crc = true; }
@@ -1702,9 +1704,6 @@ static int read_partial_message_bio(struvoid *p;int ret, left; -if (IS_ERR (bv)) -return PTR_ERR (bv); - left =min ((int )(data_len - con->in_msg_pos.data_pos), (int )(bv->bv_len - con->in_msg_pos.page_pos));
Greg Kroah-Hartman
maintainerPATCH 134/171 libceph: add some fine ASCII art
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Alex Elder <[email protected]>
(cherry picked from commit bc18f4b1c850ab355e38373fbb60fd28568d84b5)
Sage liked the state diagram I put in my commit description so I'm putting it in with the code.
--- net/ceph/messenger.c | 42 +++++++++++++++++++++++++++++++++++++++++- 1 file changed, 41 insertions(+), 1 deletion(-)
net/ceph/messenger.c +41 -1
@@ -29,7 +29,47 @@* the sender. */ -/* State values for ceph_connection->sock_state; NEW is assumed to be 0 */ +/* +* We track the state of the socket on a given connection using +* values defined below. The transition to a new socket state is +* handled by a function which verifies we aren't coming from an +* unexpected state. +* +* -------- +* | NEW* | transient initial state +* -------- +* | con_sock_state_init() +* v +* ---------- +* | CLOSED | initialized, but no socket (and no +* ---------- TCP connection) +* ^ \ +* | \ con_sock_state_connecting() +* | ---------------------- +* | \ +* + con_sock_state_closed() \ +* |\ \ +* | \ \ +* | ----------- \ +* | | CLOSING | socket event; \ +* | ----------- await close \ +* | ^ | +* | | | +* | + con_sock_state_closing() | +* | / \ | +* | / --------------- | +* | / \ v +* | / -------------- +* | / -----------------| CONNECTING | socket created, TCP +* | | / -------------- connect initiated +* | | | con_sock_state_connected() +* | | v +* ------------- +* | CONNECTED | TCP connection established +* ------------- +* +* State values for ceph_connection->sock_state; NEW is assumed to be 0. +*/ #define CON_SOCK_STATE_NEW 0/* -> CLOSED */ #define CON_SOCK_STATE_CLOSED 1/* -> CONNECTING */
Greg Kroah-Hartman
maintainerPATCH 135/171 libceph: set peer name on con_open, not init
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit b7a9e5dd40f17a48a72f249b8bbc989b63bae5fd)
The peer name may change on each open attempt, even when the connection is reused.
--- fs/ceph/mds_client.c | 7 ++++--- include/linux/ceph/messenger.h | 4 ++-- net/ceph/messenger.c | 12 +++++++----- net/ceph/mon_client.c | 4 ++-- net/ceph/osd_client.c | 10 ++++++---- 5 files changed, 21 insertions(+), 16 deletions(-)
fs/ceph/mds_client.c +4 -3
@@ -394,8 +394,7 @@ static struct ceph_mds_session *register s->s_seq =0 ;mutex_init (&s->s_mutex); -ceph_con_init (&s->s_con, s, &mds_con_ops, &mdsc->fsc->client->msgr, -CEPH_ENTITY_TYPE_MDS , mds); +ceph_con_init (&s->s_con, s, &mds_con_ops, &mdsc->fsc->client->msgr);spin_lock_init (&s->s_gen_ttl_lock); s->s_cap_gen =0 ;
@@ -437,7 +436,8 @@ static struct ceph_mds_session *register mdsc->sessions[mds] = s;atomic_inc (&s->s_ref);/* one ref to sessions[], one to caller */ -ceph_con_open (&s->s_con,ceph_mdsmap_get_addr (mdsc->mdsmap, mds)); +ceph_con_open (&s->s_con,CEPH_ENTITY_TYPE_MDS , mds, +ceph_mdsmap_get_addr (mdsc->mdsmap, mds));return s;
@@ -2529,6 +2529,7 @@ static void send_mds_reconnect(struct ce session->s_seq =0 ;ceph_con_open (&session->s_con, +CEPH_ENTITY_TYPE_MDS , mds,ceph_mdsmap_get_addr (mdsc->mdsmap, mds));/* replay unsafe requests */
include/linux/ceph/messenger.h +2 -2
@@ -224,9 +224,9 @@ extern void ceph_messenger_init(struct cextern void ceph_con_init (struct ceph_connection *con,void *private,const struct ceph_connection_operations *ops, -struct ceph_messenger *msgr,__u8 entity_type, -__u64 entity_num); +struct ceph_messenger *msgr);extern void ceph_con_open (struct ceph_connection *con, +__u8 entity_type,__u64 entity_num,struct ceph_entity_addr *addr);extern bool ceph_con_opened (struct ceph_connection *con);extern void ceph_con_close (struct ceph_connection *con);
net/ceph/messenger.c +7 -5
@@ -523,12 +523,17 @@ EXPORT_SYMBOL(ceph_con_close);/* * Reopen a closed connection, with a new peer address. */ -void ceph_con_open (struct ceph_connection *con,struct ceph_entity_addr *addr) +void ceph_con_open (struct ceph_connection *con, +__u8 entity_type,__u64 entity_num, +struct ceph_entity_addr *addr) {dout ("con_open %p %s\n" , con,ceph_pr_addr (&addr->in_addr));set_bit (OPENING , &con->state);WARN_ON (!test_and_clear_bit (CLOSED , &con->state)); + con->peer_name.type = (__u8 ) entity_type; + con->peer_name.num =cpu_to_le64 (entity_num); +memcpy (&con->peer_addr, addr,sizeof (*addr)); con->delay =0 ;/* reset backoff memory */ queue_con (con);
@@ -548,7 +553,7 @@ bool ceph_con_opened(struct ceph_connect*/ void ceph_con_init (struct ceph_connection *con,void *private,const struct ceph_connection_operations *ops, -struct ceph_messenger *msgr,__u8 entity_type,__u64 entity_num) +struct ceph_messenger *msgr) {dout ("con_init %p\n" , con);memset (con,0 ,sizeof (*con));
@@ -558,9 +563,6 @@ void ceph_con_init(struct ceph_connectiocon_sock_state_init (con); - con->peer_name.type = (__u8 ) entity_type; - con->peer_name.num =cpu_to_le64 (entity_num); -mutex_init (&con->mutex);INIT_LIST_HEAD (&con->out_queue);INIT_LIST_HEAD (&con->out_sent);
net/ceph/mon_client.c +2 -2
@@ -143,11 +143,11 @@ static int __open_session(struct ceph_mo monc->want_next_osdmap = !!monc->want_next_osdmap;ceph_con_init (&monc->con, monc, &mon_con_ops, - &monc->client->msgr, -CEPH_ENTITY_TYPE_MON , monc->cur_mon); + &monc->client->msgr);dout ("open_session mon%d opening\n" , monc->cur_mon);ceph_con_open (&monc->con, +CEPH_ENTITY_TYPE_MON , monc->cur_mon, &monc->monmap->mon_inst[monc->cur_mon].addr);/* initiatiate authentication handshake */
net/ceph/osd_client.c +6 -4
@@ -639,8 +639,7 @@ static struct ceph_osd *create_osd(strucINIT_LIST_HEAD (&osd->o_osd_lru); osd->o_incarnation =1 ; -ceph_con_init (&osd->o_con, osd, &osd_con_ops, &osdc->client->msgr, -CEPH_ENTITY_TYPE_OSD , onum); +ceph_con_init (&osd->o_con, osd, &osd_con_ops, &osdc->client->msgr);INIT_LIST_HEAD (&osd->o_keepalive_item);return osd;
@@ -750,7 +749,8 @@ static int __reset_osd(struct ceph_osd_c ret = -EAGAIN ; }else {ceph_con_close (&osd->o_con); -ceph_con_open (&osd->o_con, &osdc->osdmap->osd_addr[osd->o_osd]); +ceph_con_open (&osd->o_con,CEPH_ENTITY_TYPE_OSD , osd->o_osd, + &osdc->osdmap->osd_addr[osd->o_osd]); osd->o_incarnation++; }return ret;
@@ -1005,7 +1005,9 @@ static int __map_request(struct ceph_osddout ("map_request osd %p is osd%d\n" , req->r_osd, o);__insert_osd (osdc, req->r_osd); -ceph_con_open (&req->r_osd->o_con, &osdc->osdmap->osd_addr[o]); +ceph_con_open (&req->r_osd->o_con, +CEPH_ENTITY_TYPE_OSD , o, + &osdc->osdmap->osd_addr[o]); }if (req->r_osd) {
Greg Kroah-Hartman
maintainerPATCH 136/171 libceph: initialize mon_client con only once
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 735a72ef952d42a256f79ae3e6dc1c17a45c041b)
Do not re-initialize the con on every connection attempt. When we ceph_con_close, there may still be work queued on the socket (e.g., to close it), and re-initializing will clobber the work_struct state.
--- net/ceph/mon_client.c | 7 +++---- 1 file changed, 3 insertions(+), 4 deletions(-)
net/ceph/mon_client.c +3 -4
@@ -119,7 +119,6 @@ static void __close_session(struct ceph_dout ("__close_session closing mon%d\n" , monc->cur_mon);ceph_msg_revoke (monc->m_auth);ceph_con_close (&monc->con); - monc->con.private =NULL ; monc->cur_mon =-1 ; monc->pending_auth =0 ;ceph_auth_reset (monc->auth);
@@ -142,9 +141,6 @@ static int __open_session(struct ceph_mo monc->sub_renew_after = jiffies;/* i.e., expired */ monc->want_next_osdmap = !!monc->want_next_osdmap; -ceph_con_init (&monc->con, monc, &mon_con_ops, - &monc->client->msgr); -dout ("open_session mon%d opening\n" , monc->cur_mon); ceph_con_open(&monc->con, CEPH_ENTITY_TYPE_MON, monc->cur_mon,
@@ -798,6 +794,9 @@ int ceph_monc_init(struct ceph_mon_clienif (!monc->m_auth) goto out_auth_reply; +ceph_con_init (&monc->con, monc, &mon_con_ops, + &monc->client->msgr); + monc->cur_mon =-1 ; monc->hunting = true; monc->sub_renew_after = jiffies;
Greg Kroah-Hartman
maintainerPATCH 137/171 libceph: allow sock transition from CONNECTING to CLOSED
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit fbb85a478f6d4cce6942f1c25c6a68ec5b1e7e7f)
It is possible to close a socket that is in the OPENING state. For example, it can happen if ceph_con_close() is called on the con before the TCP connection is established. con_work() will come around and shut down the socket.
--- net/ceph/messenger.c | 25 +++++++++++++------------ 1 file changed, 13 insertions(+), 12 deletions(-)
net/ceph/messenger.c +13 -12
@@ -48,17 +48,17 @@* | ---------------------- * | \ * + con_sock_state_closed() \ -* |\ \ -* | \ \ -* | ----------- \ -* | | CLOSING | socket event; \ -* | ----------- await close \ -* | ^ | -* | | | -* | + con_sock_state_closing() | -* | / \ | -* | / --------------- | -* | / \ v +* |+--------------------------- \ +* | \ \ \ +* | ----------- \ \ +* | | CLOSING | socket event; \ \ +* | ----------- await close \ \ +* | ^ \ | +* | | \ | +* | + con_sock_state_closing() \ | +* | / \ | | +* | / --------------- | | +* | / \ v v * | / -------------- * | / -----------------| CONNECTING | socket created, TCP * | | / -------------- connect initiated
@@ -241,7 +241,8 @@ static void con_sock_state_closed(struct old_state =atomic_xchg (&con->sock_state,CON_SOCK_STATE_CLOSED );if (WARN_ON (old_state !=CON_SOCK_STATE_CONNECTED && - old_state !=CON_SOCK_STATE_CLOSING )) + old_state !=CON_SOCK_STATE_CLOSING && + old_state !=CON_SOCK_STATE_CONNECTING ))printk ("%s: unexpected old state %d\n" , __func__, old_state); }
Greg Kroah-Hartman
maintainerPATCH 138/171 libceph: initialize msgpool message types
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit d50b409fb8698571d8209e5adfe122e287e31290)
Initialize the type field for messages in a msgpool. The caller was doing this for osd ops, but not for the reply messages.
--- include/linux/ceph/msgpool.h | 3 ++- net/ceph/msgpool.c | 7 ++++--- net/ceph/osd_client.c | 7 ++++--- 3 files changed, 10 insertions(+), 7 deletions(-)
include/linux/ceph/msgpool.h +2 -1
@@ -11,10 +11,11 @@struct ceph_msgpool {const char *name;mempool_t *pool; +int type;/* preallocated message type */ int front_len;/* preallocated payload size */ }; -extern int ceph_msgpool_init (struct ceph_msgpool *pool, +extern int ceph_msgpool_init (struct ceph_msgpool *pool,int type,int front_len,int size,bool blocking,const char *name);extern void ceph_msgpool_destroy (struct ceph_msgpool *pool);
net/ceph/msgpool.c +4 -3
@@ -12,7 +12,7 @@ static void *msgpool_alloc(gfp_t gfp_masstruct ceph_msgpool *pool = arg;struct ceph_msg *msg; - msg =ceph_msg_new (0 , pool->front_len, gfp_mask, true); + msg =ceph_msg_new (pool->type, pool->front_len, gfp_mask, true);if (!msg) {dout ("msgpool_alloc %s failed\n" , pool->name); }else {
@@ -32,10 +32,11 @@ static void msgpool_free(void *element,ceph_msg_put (msg); } -int ceph_msgpool_init (struct ceph_msgpool *pool, +int ceph_msgpool_init (struct ceph_msgpool *pool,int type,int front_len,int size,bool blocking,const char *name) {dout ("msgpool %s init\n" , name); + pool->type = type; pool->front_len = front_len; pool->pool =mempool_create (size, msgpool_alloc, msgpool_free, pool);if (!pool->pool)
@@ -61,7 +62,7 @@ struct ceph_msg *ceph_msgpool_get(structWARN_ON (1 );/* try to alloc a fresh message */ -return ceph_msg_new (0 , front_len,GFP_NOFS , false); +return ceph_msg_new (pool->type, front_len,GFP_NOFS , false); } msg =mempool_alloc (pool->pool,GFP_NOFS );
net/ceph/osd_client.c +4 -3
@@ -242,6 +242,7 @@ struct ceph_osd_request *ceph_osdc_alloc }ceph_pagelist_init (req->r_trail); } +/* create request message; allow space for oid */ msg_size +=MAX_OBJ_NAME_SIZE ;if (snapc)
@@ -255,7 +256,6 @@ struct ceph_osd_request *ceph_osdc_allocreturn NULL ; } - msg->hdr.type =cpu_to_le16 (CEPH_MSG_OSD_OP );memset (msg->front.iov_base,0 , msg->front.iov_len); req->r_request = msg;
@@ -1837,11 +1837,12 @@ int ceph_osdc_init(struct ceph_osd_clienif (!osdc->req_mempool) goto out; - err =ceph_msgpool_init (&osdc->msgpool_op,OSD_OP_FRONT_LEN ,10 , true, + err =ceph_msgpool_init (&osdc->msgpool_op,CEPH_MSG_OSD_OP , +OSD_OP_FRONT_LEN ,10 , true,"osd_op" );if (err <0 ) goto out_mempool; - err =ceph_msgpool_init (&osdc->msgpool_op_reply, + err =ceph_msgpool_init (&osdc->msgpool_op_reply,CEPH_MSG_OSD_OPREPLY ,OSD_OPREPLY_FRONT_LEN ,10 , true,"osd_op_reply" );if (err <0 )
Greg Kroah-Hartman
maintainerPATCH 139/171 libceph: prevent the race of incoming work during teardown
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Guanjun He <[email protected]>
(cherry picked from commit a2a3258417eb6a1799cf893350771428875a8287)
Add an atomic variable 'stopping' as flag in struct ceph_messenger, set this flag to 1 in function ceph_destroy_client(), and add the condition code in function ceph_data_ready() to test the flag value, if true(1), just return.
--- include/linux/ceph/messenger.h | 1 + net/ceph/ceph_common.c | 2 ++ net/ceph/messenger.c | 5 +++++ 3 files changed, 8 insertions(+)
include/linux/ceph/messenger.h +1 -0
@@ -50,6 +50,7 @@ struct ceph_messenger {struct ceph_entity_inst inst;/* my name+address */ struct ceph_entity_addr my_enc_addr; +atomic_t stopping;bool nocrc;/*
net/ceph/ceph_common.c +2 -0
@@ -495,6 +495,8 @@ void ceph_destroy_client(struct ceph_cli {dout ("destroy_client %p\n" , client); +atomic_set (&client->msgr.stopping,1 ); +/* unmount */ ceph_osdc_stop (&client->osdc);
net/ceph/messenger.c +5 -0
@@ -254,6 +254,9 @@ static void con_sock_state_closed(structstatic void ceph_sock_data_ready (struct sock *sk,int count_unused) {struct ceph_connection *con = sk->sk_user_data; +if (atomic_read (&con->msgr->stopping)) { +return ; + }if (sk->sk_state !=TCP_CLOSE_WAIT ) { dout("%s on %p state = %lu, queueing work\n", __func__,
@@ -2413,6 +2416,8 @@ void ceph_messenger_init(struct ceph_mesencode_my_addr (msgr); msgr->nocrc = nocrc; +atomic_set (&msgr->stopping,0 ); +dout ("%s %p\n" , __func__, msgr); }EXPORT_SYMBOL (ceph_messenger_init);
Greg Kroah-Hartman
maintainerPATCH 140/171 libceph: report socket read/write error message
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 3a140a0d5c4b9e35373b016e41dfc85f1e526bdb)
We need to set error_msg to something useful before calling ceph_fault(); do so here for try_{read,write}(). This is more informative than
libceph: osd0 192.168.106.220:6801 (null)
--- net/ceph/messenger.c | 8 ++++++-- 1 file changed, 6 insertions(+), 2 deletions(-)
net/ceph/messenger.c +6 -2
@@ -2287,14 +2287,18 @@ restart: ret =try_read (con);if (ret == -EAGAIN ) goto restart; -if (ret <0 ) +if (ret <0 ) { + con->error_msg ="socket error on read" ; goto fault; + } ret =try_write (con);if (ret == -EAGAIN ) goto restart; -if (ret <0 ) +if (ret <0 ) { + con->error_msg ="socket error on write" ; goto fault; + } done:mutex_unlock (&con->mutex);
Greg Kroah-Hartman
maintainerPATCH 141/171 libceph: fix mutex coverage for ceph_con_close
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 8c50c817566dfa4581f82373aac39f3e608a7dc8)
Hold the mutex while twiddling all of the state bits to avoid possible races. While we're here, make not of why we cannot close the socket directly.
--- net/ceph/messenger.c | 8 +++++++- 1 file changed, 7 insertions(+), 1 deletion(-)
net/ceph/messenger.c +7 -1
@@ -503,6 +503,7 @@ static void reset_connection(struct ceph*/ void ceph_con_close (struct ceph_connection *con) { +mutex_lock (&con->mutex);dout ("con_close %p peer %s\n" , con,ceph_pr_addr (&con->peer_addr.in_addr));clear_bit (NEGOTIATING , &con->state);
@@ -515,11 +516,16 @@ void ceph_con_close(struct ceph_connecticlear_bit (KEEPALIVE_PENDING , &con->flags);clear_bit (WRITE_PENDING , &con->flags); -mutex_lock (&con->mutex);reset_connection (con); con->peer_global_seq =0 ;cancel_delayed_work (&con->work);mutex_unlock (&con->mutex); + +/* +* We cannot close the socket directly from here because the +* work threads use it without holding the mutex. Instead, let +* con_work() do it. +*/ queue_con (con); }EXPORT_SYMBOL (ceph_con_close);
Greg Kroah-Hartman
maintainerPATCH 142/171 libceph: resubmit linger ops when pg mapping changes
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 6194ea895e447fdf4adfd23f67873a32bf4f15ae)
The linger op registration (i.e., watch) modifies the object state. As such, the OSD will reply with success if it has already applied without doing the associated side-effects (setting up the watch session state). If we lose the ACK and resubmit, we will see success but the watch will not be correctly registered and we won't get notifies.
To fix this, always resubmit the linger op with a new tid. We accomplish this by re-registering as a linger (i.e., 'registered') if we are not yet registered. Then the second loop will treat this just like a normal case of re-registering.
This mirrors a similar fix on the userland ceph.git, commit 5dd68b95, and ceph bug #2796.
--- net/ceph/osd_client.c | 26 +++++++++++++++++++++----- 1 file changed, 21 insertions(+), 5 deletions(-)
net/ceph/osd_client.c +21 -5
@@ -888,7 +888,9 @@ static void __register_linger_request(st {dout ("__register_linger_request %p\n" , req);list_add_tail (&req->r_linger_item, &osdc->req_linger); -list_add_tail (&req->r_linger_osd, &req->r_osd->o_linger_requests); +if (req->r_osd) +list_add_tail (&req->r_linger_osd, + &req->r_osd->o_linger_requests); } static void __unregister_linger_request(struct ceph_osd_client *osdc,
@@ -1302,8 +1304,9 @@ static void kick_requests(struct ceph_osdout ("kick_requests %s\n" , force_resend ?" (force resend)" :"" );mutex_lock (&osdc->request_mutex); -for (p =rb_first (&osdc->requests); p; p =rb_next (p)) { +for (p =rb_first (&osdc->requests); p; ) { req = rb_entry(p, struct ceph_osd_request, r_node); + p =rb_next (p); err =__map_request (osdc, req, force_resend);if (err <0 )continue ;/* error */
@@ -1311,10 +1314,23 @@ static void kick_requests(struct ceph_osdout ("%p tid %llu maps to no osd\n" , req, req->r_tid); needmap++;/* request a newer map */ }else if (err >0 ) { -dout ("%p tid %llu requeued on osd%d\n" , req, req->r_tid, - req->r_osd ? req->r_osd->o_osd :-1 ); -if (!req->r_linger) +if (!req->r_linger) { +dout ("%p tid %llu requeued on osd%d\n" , req, + req->r_tid, + req->r_osd ? req->r_osd->o_osd :-1 ); req->r_flags |=CEPH_OSD_FLAG_RETRY ; + } + } +if (req->r_linger &&list_empty (&req->r_linger_item)) { +/* +* register as a linger so that we will +* re-submit below and get a new tid +*/ +dout ("%p tid %llu restart on osd%d\n" , + req, req->r_tid, + req->r_osd ? req->r_osd->o_osd :-1 ); +__register_linger_request (osdc, req); +__unregister_request (osdc, req); } }
Greg Kroah-Hartman
maintainerPATCH 143/171 libceph: (re)initialize bio_iter on start of message receive
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit a4107026976f06c9a6ce8cc84a763564ee39d901)
Previously, we were opportunistically initializing the bio_iter if it appeared to be uninitialized in the middle of the read path. The problem is that a sequence like:
- start reading message
- initialize bio_iter
- read half a message
- messenger fault, reconnect
- restart reading message
- ** bio_iter now non-NULL, not reinitialized **
- read past end of bio, crash
Instead, initialize the bio_iter unconditionally when we allocate/claim the message for read.
--- net/ceph/messenger.c | 11 ++++++----- 1 file changed, 6 insertions(+), 5 deletions(-)
net/ceph/messenger.c +6 -5
@@ -1872,6 +1872,11 @@ static int read_partial_message(struct celse con->in_msg_pos.page_pos =0 ; con->in_msg_pos.data_pos =0 ; + +#ifdef CONFIG_BLOCK +if (m->bio) +init_bio_iter (m->bio, &m->bio_iter, &m->bio_seg); +#endif }/* front */
@@ -1888,10 +1893,6 @@ static int read_partial_message(struct cif (ret <=0 )return ret; } -#ifdef CONFIG_BLOCK -if (m->bio && !m->bio_iter) -init_bio_iter (m->bio, &m->bio_iter, &m->bio_seg); -#endif /* (page) data */ while (con->in_msg_pos.data_pos < data_len) {
@@ -1902,7 +1903,7 @@ static int read_partial_message(struct creturn ret; #ifdef CONFIG_BLOCK }else if (m->bio) { - +BUG_ON (!m->bio_iter); ret =read_partial_message_bio (con, &m->bio_iter, &m->bio_seg, data_len, do_datacrc);
Greg Kroah-Hartman
maintainerPATCH 144/171 libceph: protect ceph_con_open() with mutex
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 5469155f2bc83bb2c88b0a0370c3d54d87eed06e)
Take the con mutex while we are initiating a ceph open. This is necessary because the may have previously been in use and then closed, which could result in a racing workqueue running con_work().
--- net/ceph/messenger.c | 2 ++ 1 file changed, 2 insertions(+)
net/ceph/messenger.c +2 -0
@@ -537,6 +537,7 @@ void ceph_con_open(struct ceph_connectio __u8 entity_type, __u64 entity_num, struct ceph_entity_addr *addr) { + mutex_lock(&con->mutex);dout ("con_open %p %s\n" , con,ceph_pr_addr (&addr->in_addr));set_bit (OPENING , &con->state);WARN_ON (!test_and_clear_bit (CLOSED , &con->state));
@@ -546,6 +547,7 @@ void ceph_con_open(struct ceph_connectiomemcpy (&con->peer_addr, addr,sizeof (*addr)); con->delay =0 ;/* reset backoff memory */ +mutex_unlock (&con->mutex);queue_con (con); }EXPORT_SYMBOL (ceph_con_open);
Greg Kroah-Hartman
maintainerPATCH 145/171 libceph: reset connection retry on successfully negotiation
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 85effe183dd45854d1ad1a370b88cddb403c4c91)
We exponentially back off when we encounter connection errors. If several errors accumulate, we will eventually wait ages before even trying to reconnect.
Fix this by resetting the backoff counter after a successful negotiation/ connection with the remote node. Fixes ceph issue #2802.
--- net/ceph/messenger.c | 2 ++ 1 file changed, 2 insertions(+)
net/ceph/messenger.c +2 -0
@@ -1629,6 +1629,8 @@ static int process_connect(struct ceph_cif (con->in_reply.flags &CEPH_MSG_CONNECT_LOSSY )set_bit (LOSSYTX , &con->flags); + con->delay =0 ;/* reset backoff memory */ +prepare_read_tag (con);break ;
Greg Kroah-Hartman
maintainerPATCH 146/171 libceph: fix fault locking; close socket on lossy fault
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 3b5ede07b55b52c3be27749d183d87257d032065)
If we fault on a lossy connection, we should still close the socket immediately, and do so under the con mutex.
We should also take the con mutex before printing out the state bits in the debug output.
--- net/ceph/messenger.c | 14 +++++++------- 1 file changed, 7 insertions(+), 7 deletions(-)
net/ceph/messenger.c +7 -7
@@ -2330,22 +2330,23 @@ fault:*/ static void ceph_fault (struct ceph_connection *con) { +mutex_lock (&con->mutex); +pr_err ("%s%lld %s %s\n" ,ENTITY_NAME (con->peer_name),ceph_pr_addr (&con->peer_addr.in_addr), con->error_msg);dout ("fault %p state %lu to peer %s\n" , con, con->state,ceph_pr_addr (&con->peer_addr.in_addr)); -if (test_bit (LOSSYTX , &con->flags)) { -dout ("fault on LOSSYTX channel\n" ); - goto out; - } - -mutex_lock (&con->mutex);if (test_bit (CLOSED , &con->state)) goto out_unlock;con_close_socket (con); +if (test_bit (LOSSYTX , &con->flags)) { +dout ("fault on LOSSYTX channel\n" ); + goto out_unlock; + } +if (con->in_msg) {BUG_ON (con->in_msg->con != con); con->in_msg->con =NULL ;
@@ -2392,7 +2393,6 @@ static void ceph_fault(struct ceph_conne out_unlock:mutex_unlock (&con->mutex); -out:/* * in case we faulted due to authentication, invalidate our * current tickets so that we can get new ones.
Greg Kroah-Hartman
maintainerPATCH 147/171 libceph: move msgr clear_standby under con mutex protection
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 00650931e52e97fe64096bec167f5a6780dfd94a)
Avoid dropping and retaking con->mutex in the ceph_con_send() case by leaving locking up to the caller.
--- net/ceph/messenger.c | 7 ++++--- 1 file changed, 4 insertions(+), 3 deletions(-)
net/ceph/messenger.c +4 -3
@@ -2441,12 +2441,10 @@ static void clear_standby(struct ceph_co {/* come back from STANDBY? */ if (test_and_clear_bit (STANDBY , &con->state)) { -mutex_lock (&con->mutex);dout ("clear_standby %p and ++connect_seq\n" , con); con->connect_seq++;WARN_ON (test_bit (WRITE_PENDING , &con->flags));WARN_ON (test_bit (KEEPALIVE_PENDING , &con->flags)); -mutex_unlock (&con->mutex); } }
@@ -2483,11 +2481,12 @@ void ceph_con_send(struct ceph_connectiole32_to_cpu (msg->hdr.front_len),le32_to_cpu (msg->hdr.middle_len), le32_to_cpu(msg->hdr.data_len)); + +clear_standby (con);mutex_unlock (&con->mutex);/* if there wasn't anything waiting to send before, queue * new work */ -clear_standby (con);if (test_and_set_bit (WRITE_PENDING , &con->flags) ==0 )queue_con (con); }
@@ -2574,7 +2573,9 @@ void ceph_msg_revoke_incoming(struct cepvoid ceph_con_keepalive (struct ceph_connection *con) {dout ("con_keepalive %p\n" , con); +mutex_lock (&con->mutex);clear_standby (con); +mutex_unlock (&con->mutex);if (test_and_set_bit (KEEPALIVE_PENDING , &con->flags) ==0 &&test_and_set_bit (WRITE_PENDING , &con->flags) ==0 )queue_con (con);
Greg Kroah-Hartman
maintainerPATCH 148/171 libceph: move ceph_con_send() closed check under the con mutex
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit a59b55a602b6c741052d79c1e3643f8440cddd27)
Take the con mutex before checking whether the connection is closed to avoid racing with someone else closing it.
--- net/ceph/messenger.c | 16 +++++++--------- 1 file changed, 7 insertions(+), 9 deletions(-)
net/ceph/messenger.c +7 -9
@@ -2453,22 +2453,20 @@ static void clear_standby(struct ceph_co*/ void ceph_con_send (struct ceph_connection *con,struct ceph_msg *msg) { -if (test_bit (CLOSED , &con->state)) { -dout ("con_send %p closed, dropping %p\n" , con, msg); -ceph_msg_put (msg); -return ; - } -/* set src+dst */ msg->hdr.src = con->msgr->inst.name; -BUG_ON (msg->front.iov_len !=le32_to_cpu (msg->hdr.front_len)); - msg->needs_out_seq = true; -/* queue */ mutex_lock (&con->mutex); +if (test_bit (CLOSED , &con->state)) { +dout ("con_send %p closed, dropping %p\n" , con, msg); +ceph_msg_put (msg); +mutex_unlock (&con->mutex); +return ; + } +BUG_ON (msg->con !=NULL ); msg->con = con->ops->get (con);BUG_ON (msg->con ==NULL );
Greg Kroah-Hartman
maintainerPATCH 149/171 libceph: drop gratuitous socket close calls in con_work
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 2e8cb10063820af7ed7638e3fd9013eee21266e7)
If the state is CLOSED or OPENING, we shouldn't have a socket.
--- net/ceph/messenger.c | 8 ++++---- 1 file changed, 4 insertions(+), 4 deletions(-)
net/ceph/messenger.c +4 -4
@@ -2284,15 +2284,15 @@ restart:dout ("con_work %p STANDBY\n" , con); goto done; } -if (test_bit (CLOSED , &con->state)) {/* e.g. if we are replaced */ -dout ("con_work CLOSED\n" ); -con_close_socket (con); +if (test_bit (CLOSED , &con->state)) { +dout ("con_work %p CLOSED\n" , con); +BUG_ON (con->sock); goto done; }if (test_and_clear_bit (OPENING , &con->state)) {/* reopen w/ new peer */ dout ("con_work OPENING\n" ); -con_close_socket (con); +BUG_ON (con->sock); } ret =try_read (con);
Greg Kroah-Hartman
maintainerPATCH 150/171 libceph: close socket directly from ceph_con_close()
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit ee76e0736db8455e3b11827d6899bd2a4e1d0584)
It is simpler to do this immediately, since we already hold the con mutex. It also avoids the need to deal with a not-quite-CLOSED socket in con_work.
--- net/ceph/messenger.c | 8 +------- 1 file changed, 1 insertion(+), 7 deletions(-)
net/ceph/messenger.c +1 -7
@@ -519,14 +519,8 @@ void ceph_con_close(struct ceph_connectireset_connection (con); con->peer_global_seq =0 ;cancel_delayed_work (&con->work); +con_close_socket (con);mutex_unlock (&con->mutex); - -/* -* We cannot close the socket directly from here because the -* work threads use it without holding the mutex. Instead, let -* con_work() do it. -*/ -queue_con (con); }EXPORT_SYMBOL (ceph_con_close);
Greg Kroah-Hartman
maintainerPATCH 151/171 libceph: drop unnecessary CLOSED check in socket state change callback
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
(cherry picked from commit d7353dd5aaf22ed611fbcd0d4a4a12fb30659290)
If we are CLOSED, the socket is closed and we won't get these.
--- net/ceph/messenger.c | 3 --- 1 file changed, 3 deletions(-)
net/ceph/messenger.c +0 -3
@@ -296,9 +296,6 @@ static void ceph_sock_state_change(strucdout ("%s %p state = %lu sk_state = %u\n" , __func__, con, con->state, sk->sk_state); -if (test_bit (CLOSED , &con->state)) -return ; -switch (sk->sk_state) {case TCP_CLOSE :dout ("%s TCP_CLOSE\n" , __func__);
Greg Kroah-Hartman
maintainerPATCH 152/171 libceph: replace connection state bits with states
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 8dacc7da69a491c515851e68de6036f21b5663ce)
Use a simple set of 6 enumerated values for the socket states (CON_STATE_*) and use those instead of the state bits. All of the con->state checks are now under the protection of the con mutex, so this is safe. It also simplifies many of the state checks because we can check for anything other than the expected state instead of various bits for races we can think of.
This appears to hold up well to stress testing both with and without socket failure injection on the server side.
--- include/linux/ceph/messenger.h | 12 --- net/ceph/messenger.c | 130 +++++++++++++++++++++-------------------- 2 files changed, 68 insertions(+), 74 deletions(-)
include/linux/ceph/messenger.h +0 -12
@@ -117,18 +117,6 @@ struct ceph_msg_pos {#define BACKOFF 15/* -* ceph_connection states -*/ -#define CONNECTING 1 -#define NEGOTIATING 2 -#define CONNECTED 5 -#define STANDBY 8/* no outgoing messages, socket closed. we keep -* the ceph_connection around to maintain shared -* state with the peer. */ -#define CLOSED 10/* we've closed the connection */ -#define OPENING 13/* open connection w/ (possibly new) peer */ - -/* * A single connection with another host. * * We maintain a queue of outgoing messages, and some session state to
net/ceph/messenger.c +68 -62
292 lines not on this page · raw message
Greg Kroah-Hartman
maintainerPATCH 153/171 libceph: clean up con flags
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 4a8616920860920abaa51193146fe36b38ef09aa)
Rename flags with CON_FLAG prefix, move the definitions into the c file, and (better) document their meaning.
--- include/linux/ceph/messenger.h | 10 ------ net/ceph/messenger.c | 62 +++++++++++++++++++++++------------------ 2 files changed, 36 insertions(+), 36 deletions(-)
include/linux/ceph/messenger.h +0 -10
@@ -107,16 +107,6 @@ struct ceph_msg_pos {#define MAX_DELAY_INTERVAL (5 * 60 * HZ)/* -* ceph_connection flag bits -*/ - -#define LOSSYTX 0/* we can close channel or drop messages on errors */ -#define KEEPALIVE_PENDING 3 -#define WRITE_PENDING 4/* we have data ready to send */ -#define SOCK_CLOSED 11/* socket state changed to closed */ -#define BACKOFF 15 - -/* * A single connection with another host. * * We maintain a queue of outgoing messages, and some session state to
net/ceph/messenger.c +36 -26
193 lines not on this page · raw message
Greg Kroah-Hartman
maintainerPATCH 154/171 libceph: clear all flags on con_close
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
--- net/ceph/messenger.c | 2 ++ 1 file changed, 2 insertions(+)
net/ceph/messenger.c +2 -0
@@ -528,6 +528,8 @@ void ceph_con_close(struct ceph_connecticlear_bit (CON_FLAG_LOSSYTX , &con->flags);/* so we retry next connect */ clear_bit (CON_FLAG_KEEPALIVE_PENDING , &con->flags);clear_bit (CON_FLAG_WRITE_PENDING , &con->flags); +clear_bit (CON_FLAG_KEEPALIVE_PENDING , &con->flags); +clear_bit (CON_FLAG_BACKOFF , &con->flags);reset_connection (con); con->peer_global_seq =0 ;
Greg Kroah-Hartman
maintainerPATCH 155/171 libceph: fix handling of immediate socket connect failure
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 8007b8d626b49c34fb146ec16dc639d8b10c862f)
If the connect() call immediately fails such that sock == NULL, we still need con_close_socket() to reset our socket state to CLOSED.
--- net/ceph/messenger.c | 26 +++++++++++++++++++------- 1 file changed, 19 insertions(+), 7 deletions(-)
net/ceph/messenger.c +19 -7
@@ -224,6 +224,8 @@ static void con_sock_state_init(struct c old_state =atomic_xchg (&con->sock_state,CON_SOCK_STATE_CLOSED );if (WARN_ON (old_state !=CON_SOCK_STATE_NEW ))printk ("%s: unexpected old state %d\n" , __func__, old_state); +dout ("%s con %p sock %d -> %d\n" , __func__, con, old_state, +CON_SOCK_STATE_CLOSED ); }static void con_sock_state_connecting (struct ceph_connection *con)
@@ -233,6 +235,8 @@ static void con_sock_state_connecting(st old_state =atomic_xchg (&con->sock_state,CON_SOCK_STATE_CONNECTING );if (WARN_ON (old_state !=CON_SOCK_STATE_CLOSED ))printk ("%s: unexpected old state %d\n" , __func__, old_state); +dout ("%s con %p sock %d -> %d\n" , __func__, con, old_state, +CON_SOCK_STATE_CONNECTING ); }static void con_sock_state_connected (struct ceph_connection *con)
@@ -242,6 +246,8 @@ static void con_sock_state_connected(str old_state =atomic_xchg (&con->sock_state,CON_SOCK_STATE_CONNECTED );if (WARN_ON (old_state !=CON_SOCK_STATE_CONNECTING ))printk ("%s: unexpected old state %d\n" , __func__, old_state); +dout ("%s con %p sock %d -> %d\n" , __func__, con, old_state, +CON_SOCK_STATE_CONNECTED ); }static void con_sock_state_closing (struct ceph_connection *con)
@@ -253,6 +259,8 @@ static void con_sock_state_closing(struc old_state != CON_SOCK_STATE_CONNECTED && old_state != CON_SOCK_STATE_CLOSING))printk ("%s: unexpected old state %d\n" , __func__, old_state); +dout ("%s con %p sock %d -> %d\n" , __func__, con, old_state, +CON_SOCK_STATE_CLOSING ); }static void con_sock_state_closed (struct ceph_connection *con)
@@ -262,8 +270,11 @@ static void con_sock_state_closed(struct old_state =atomic_xchg (&con->sock_state,CON_SOCK_STATE_CLOSED );if (WARN_ON (old_state !=CON_SOCK_STATE_CONNECTED && old_state !=CON_SOCK_STATE_CLOSING && - old_state !=CON_SOCK_STATE_CONNECTING )) + old_state !=CON_SOCK_STATE_CONNECTING && + old_state !=CON_SOCK_STATE_CLOSED ))printk ("%s: unexpected old state %d\n" , __func__, old_state); +dout ("%s con %p sock %d -> %d\n" , __func__, con, old_state, +CON_SOCK_STATE_CLOSED ); }/*
@@ -448,14 +459,14 @@ static int ceph_tcp_sendpage(struct sock*/ static int con_close_socket (struct ceph_connection *con) { -int rc; +int rc =0 ;dout ("con_close_socket on %p sock %p\n" , con, con->sock); -if (!con->sock) -return 0 ; - rc = con->sock->ops->shutdown (con->sock,SHUT_RDWR ); -sock_release (con->sock); - con->sock =NULL ; +if (con->sock) { + rc = con->sock->ops->shutdown (con->sock,SHUT_RDWR ); +sock_release (con->sock); + con->sock =NULL ; + }/* * Forcibly clear the SOCK_CLOSED flag. It gets set
@@ -464,6 +475,7 @@ static int con_close_socket(struct ceph_* shut the socket down. */ clear_bit (CON_FLAG_SOCK_CLOSED , &con->flags); +con_sock_state_closed (con);return rc; }
Greg Kroah-Hartman
maintainerPATCH 156/171 libceph: revoke mon_client messages on session restart
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 4f471e4a9c7db0256834e1b376ea50c82e345c3c)
Revoke all mon_client messages when we shut down the old connection. This is mostly moot since we are re-using the same ceph_connection, but it is cleaner.
--- net/ceph/mon_client.c | 4 ++++ 1 file changed, 4 insertions(+)
net/ceph/mon_client.c +4 -0
@@ -118,6 +118,9 @@ static void __close_session(struct ceph_ {dout ("__close_session closing mon%d\n" , monc->cur_mon);ceph_msg_revoke (monc->m_auth); +ceph_msg_revoke_incoming (monc->m_auth_reply); +ceph_msg_revoke (monc->m_subscribe); +ceph_msg_revoke_incoming (monc->m_subscribe_ack);ceph_con_close (&monc->con); monc->cur_mon =-1 ; monc->pending_auth =0 ;
@@ -685,6 +688,7 @@ static void __resend_generic_request(strfor (p =rb_first (&monc->generic_request_tree); p; p =rb_next (p)) { req = rb_entry(p, struct ceph_mon_generic_request, node);ceph_msg_revoke (req->request); +ceph_msg_revoke_incoming (req->reply);ceph_con_send (&monc->con,ceph_msg_get (req->request)); } }
Greg Kroah-Hartman
maintainerPATCH 157/171 libceph: verify state after retaking con lock after dispatch
In reply to Greg Kroah-Hartman3.4-stable review patch. If anyone has any objections, please let me know.
------------------
From: Sage Weil <[email protected]>
(cherry picked from commit 7b862e07b1a4d5c963d19027f10ea78085f27f9b)
We drop the con mutex when delivering a message. When we retake the lock, we need to verify we are still in the OPEN state before preparing to read the next tag, or else we risk stepping on a connection that has been closed.
--- net/ceph/messenger.c | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)
net/ceph/messenger.c +2 -1
@@ -2003,7 +2003,6 @@ static void process_message(struct ceph_ con->ops->dispatch (con, msg);mutex_lock (&con->mutex); -prepare_read_tag (con); }
@@ -2213,6 +2212,8 @@ more:if (con->in_tag ==CEPH_MSGR_TAG_READY ) goto more;process_message (con); +if (con->state ==CON_STATE_OPEN ) +prepare_read_tag (con); goto more; }if (con->in_tag ==CEPH_MSGR_TAG_ACK ) {