lru_lock scalability and SMP list functions
Subsystems (12)
v2 cover lru_lock scalability and SMP list functions
Hi,
This is a work-in-progress of what I presented at LSF/MM this year[0] to greatly reduce contention on lru_lock, allowing it to scale on large systems.
This is completely different from the lru_lock series posted last January[1].
I'm hoping for feedback on the overall design and general direction as I do more real-world performance testing and polish the code. Is this a workable approach?
Thanks,
Daniel
---
Summary: lru_lock can be one of the hottest locks in the kernel on big systems. It guards too much state, so introduce new SMP-safe list functions to allow multiple threads to operate on the LRUs at once. The SMP list functions are provided in a standalone API that can be used in other parts of the kernel. When lru_lock and zone->lock are both fixed, the kernel can do up to 73.8% more page faults per second on a 44-core machine.
---
On large systems, lru_lock can become heavily contended in memory-intensive workloads such as decision support, applications that manage their memory manually by allocating and freeing pages directly from the kernel, and workloads with short-lived processes that force many munmap and exit operations. lru_lock also inhibits scalability in many of the MM paths that could be parallelized, such as freeing pages during exit/munmap and inode eviction.
The problem is that lru_lock is too big of a hammer. It guards all the LRUs in a pgdat's lruvec, needlessly serializing add-to-front, add-to-tail, and delete operations that are done on disjoint parts of an LRU, or even completely different LRUs.
This RFC series, developed in collaboration with Yossi Lev and Dave Dice, offers a two-part solution to this problem.
First, three new list functions are introduced to allow multiple threads to operate on the same linked list simultaneously under certain conditions, which are spelled out in more detail in code comments and changelogs. The functions are smp_list_del, smp_list_splice, and smp_list_add, and do the same things as their non-SMP-safe counterparts. These primitives may be used elsewhere in the kernel as the need arises; for example, in the page allocator free lists to scale zone->lock[2], or in file system LRUs[3].
Second, lru_lock is converted from a spinlock to a rwlock. The idea is to repurpose rwlock as a two-mode lock, where callers take the lock in shared (i.e. read) mode for code using the SMP list functions, and exclusive (i.e. write) mode for existing code that expects exclusive access to the LRUs. Multiple threads are allowed in under the read lock, of course, and they use the SMP list functions to synchronize amongst themselves.
The rwlock is scaffolding to facilitate the transition from big-hammer lru_lock as it exists today to just using the list locking primitives and getting rid of lru_lock entirely. Such an approach allows incremental conversion of lru_lock writers until everything uses the SMP list functions and takes the lock in shared mode, at which point lru_lock can just go away.
This RFC series is incomplete. More, and more realistic, performance numbers are needed; for now, I show only will-it-scale/page_fault1. Also, there are extensions I'd like to make to the locking scheme to handle certain lru_lock paths--in particular, those where multiple threads may delete the same node from an LRU. The SMP list functions now handle only removal of _adjacent_ nodes from an LRU. Finally, the diffstat should become more supportive after I remove some of the code duplication in patch 6 by converting the rest of the per-CPU pagevec code in mm/swap.c to use the SMP list functions.
Series based on 4.17.
Performance Numbers
-------------------
In the artificial benchmark will-it-scale/page_fault1, N tasks mmap, touch each 4K page in, and munmap an anonymous 128M memory region. The test is run in process and thread modes on a 44-core Xeon E5-2699 v4 with 503G memory and using a 4.16 baseline kernel. The table of results below is also graphed at:
https://raw.githubusercontent.com/danieljordan10/lru_lock-scalability/master/rfc-v2/graph.png
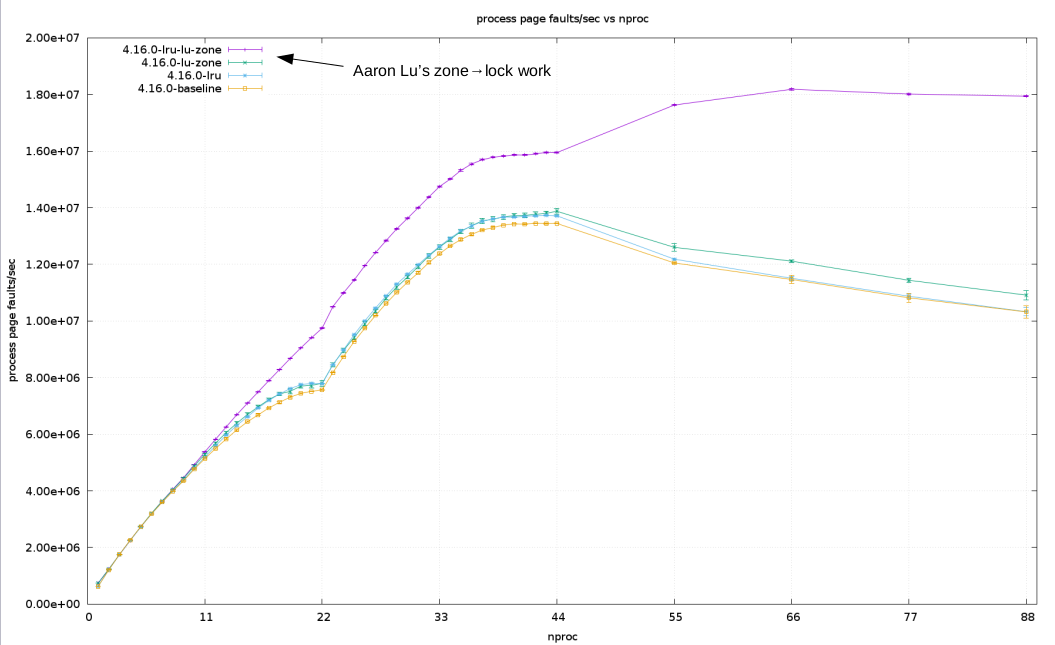
The lu-zone kernel refers to Aaron Lu's work from [4], the lru kernel is this work, and the lru-lu-zone kernel contains both.
kernel (#) ntask proc thr proc stdev thr stdev
speedup speedup pgf/s pgf/s
   baseline (1)      1                       626,944      910    625,509     756
    lu-zone (2)      1    18.0%    17.6%     739,659    2,038    735,896   2,139
        lru (3)      1     0.1%    -0.1%     627,490      878    625,162     770
lru-lu-zone (4)      1    17.4%    17.2%     735,983    2,349    732,936   2,640
baseline (1) 2 1,206,238 4,012 1,083,497 4,571
lu-zone (2) 2 2.4% 1.3% 1,235,318 3,158 1,097,745 8,919
lru (3) 2 0.1% 0.4% 1,207,246 4,988 1,087,846 5,700
lru-lu-zone (4) 2 2.4% 0.0% 1,235,271 3,005 1,083,578 6,915 baseline (1) 3 1,751,889 5,887 1,443,610 11,049
lu-zone (2) 3 -0.0% 1.9% 1,751,247 5,646 1,470,561 13,407
lru (3) 3 -0.4% 0.5% 1,744,999 7,040 1,451,507 13,186
lru-lu-zone (4) 3 -0.3% 0.2% 1,747,431 4,420 1,447,024 9,847 baseline (1) 4 2,260,201 11,482 1,769,095 16,576
lu-zone (2) 4 -0.5% 2.7% 2,249,463 14,628 1,816,409 10,988
lru (3) 4 -0.5% -0.8% 2,248,302 7,457 1,754,936 13,288
lru-lu-zone (4) 4 -0.8% 1.2% 2,243,240 10,386 1,790,833 11,186 baseline (1) 5 2,735,351 9,731 2,022,303 18,199
lu-zone (2) 5 -0.0% 3.1% 2,734,270 13,779 2,084,468 11,230
lru (3) 5 -0.5% -2.6% 2,721,069 8,417 1,970,701 14,747
lru-lu-zone (4) 5 0.0% -0.3% 2,736,317 11,533 2,016,043 10,324 baseline (1) 6 3,186,435 13,939 2,241,910 22,103
lu-zone (2) 6 0.7% 3.1% 3,207,879 17,603 2,311,070 12,345
lru (3) 6 -0.1% -1.6% 3,183,244 9,285 2,205,632 22,457
lru-lu-zone (4) 6 0.2% -0.2% 3,191,478 10,418 2,236,722 10,814 baseline (1) 7 3,596,306 17,419 2,374,538 29,782
lu-zone (2) 7 1.1% 5.6% 3,637,085 21,485 2,506,351 11,448
lru (3) 7 0.1% -1.2% 3,600,797 9,867 2,346,063 22,613
lru-lu-zone (4) 7 1.1% 1.6% 3,635,861 12,439 2,413,326 15,745 baseline (1) 8 3,986,712 15,947 2,519,189 30,129
lu-zone (2) 8 1.3% 3.7% 4,038,783 30,921 2,613,556 8,244
lru (3) 8 0.3% -0.8% 3,997,520 11,823 2,499,498 28,395
lru-lu-zone (4) 8 1.7% 4.3% 4,054,638 11,798 2,626,450 9,534 baseline (1) 11 5,138,494 17,634 2,932,708 31,765
lu-zone (2) 11 3.0% 6.6% 5,292,452 40,896 3,126,170 21,254
lru (3) 11 1.1% -1.1% 5,193,843 11,302 2,900,615 24,055
lru-lu-zone (4) 11 4.6% 2.4% 5,374,562 10,654 3,002,084 24,255 baseline (1) 22 7,569,187 13,649 3,134,116 58,149
lu-zone (2) 22 3.0% 9.6% 7,799,567 97,785 3,436,117 33,450
lru (3) 22 2.9% -0.8% 7,785,212 15,388 3,109,155 41,575
lru-lu-zone (4) 22 28.8% 7.6% 9,747,634 17,156 3,372,679 38,762 baseline (1) 33 12,375,135 30,387 2,180,328 56,529
lu-zone (2) 33 1.9% 8.9% 12,613,466 77,903 2,373,756 30,706
lru (3) 33 2.1% 3.1% 12,637,508 22,712 2,248,516 42,622
lru-lu-zone (4) 33 19.2% 9.1% 14,749,004 25,344 2,378,286 29,552 baseline (1) 44 13,446,153 14,539 2,365,487 53,966
lu-zone (2) 44 3.2% 7.8% 13,876,101 112,976 2,549,351 50,656
lru (3) 44 2.0% -8.1% 13,717,051 16,931 2,173,398 46,818
lru-lu-zone (4) 44 18.6% 7.4% 15,947,859 26,001 2,540,516 56,259 baseline (1) 55 12,050,977 30,210 2,372,251 58,151
lu-zone (2) 55 4.6% 3.2% 12,602,426 132,027 2,448,653 74,321
lru (3) 55 1.1% 1.5% 12,184,481 34,199 2,408,744 76,854
lru-lu-zone (4) 55 46.3% 3.1% 17,628,736 25,595 2,446,613 60,293 baseline (1) 66 11,464,526 146,140 2,389,751 55,417
lu-zone (2) 66 5.7% 17.5% 12,114,164 41,711 2,806,805 38,868
lru (3) 66 0.4% 13.2% 11,510,009 74,300 2,704,305 46,038
lru-lu-zone (4) 66 58.6% 17.0% 18,185,360 27,496 2,796,004 96,458 baseline (1) 77 10,818,432 149,865 2,634,568 49,631
lu-zone (2) 77 5.7% 4.9% 11,438,010 82,363 2,764,441 42,014
lru (3) 77 0.5% 3.5% 10,874,888 80,922 2,727,729 66,843
lru-lu-zone (4) 77 66.5% 1.4% 18,016,393 23,742 2,670,715 36,931 baseline (1) 88 10,321,790 214,000 2,815,546 40,597
lu-zone (2) 88 5.7% 8.3% 10,913,729 168,111 3,048,392 51,833
lru (3) 88 0.1% -3.6% 10,328,335 142,255 2,715,226 46,835
lru-lu-zone (4) 88 73.8% -3.6% 17,942,799 22,720 2,715,442 33,006The lru-lu-zone kernel containing both lru_lock and zone->lock enhancements outperforms kernels with either enhancement on its own. From this it's clear that, no matter how each lock is scaled, both locks must be fixed to get rid of this scalability issue in page allocation and freeing.
The thread case doesn't show much improvement because mmap_sem, not lru_lock or zone->lock, is the limiting factor.
Low task counts show slight regressions but are mostly in the noise.
There's a significant speedup in the zone->lock kernels for the 1-task case, possibly because the pages aren't merged when they're returned to the free lists and so the cache is more likely to be warm on the next allocation.
Apart from this artificial microbenchmark, I'm experimenting with an extended version of the SMP list locking functions (not shown here, still working on these) that has allowed a commercial database using 4K pages to exit 6.3x faster. This is with only lru_lock modified, no other kernel changes. The speedup comes from the SMP list functions allowing the many database processes to make concurrent mark_page_accessed calls from zap_pte_range while the shared memory region is being freed. I'll post more about this later.
[0] https://lwn.net/Articles/753058/
[1] http://lkml.kernel.org/r/[email protected]
[2] http://lkml.kernel.org/r/[email protected]
[3] http://lkml.kernel.org/r/[email protected]
[4] http://lkml.kernel.org/r/[email protected]
Daniel Jordan (8):
mm, memcontrol.c: make memcg lru stats thread-safe without lru_lock
mm: make zone_reclaim_stat updates thread-safe
mm: convert lru_lock from a spinlock_t to a rwlock_t
mm: introduce smp_list_del for concurrent list entry removals
mm: enable concurrent LRU removals
mm: splice local lists onto the front of the LRU
mm: introduce smp_list_splice to prepare for concurrent LRU adds
mm: enable concurrent LRU adds
 include/linux/list.h       |   3 +
 include/linux/memcontrol.h |  43 ++++++--
 include/linux/mm_inline.h  |  28 +++++
 include/linux/mmzone.h     |  54 +++++++++-
 init/main.c                |   1 +
 lib/Makefile               |   2 +-
 lib/list.c                 | 204 +++++++++++++++++++++++++++++++++++++
 mm/compaction.c            |  99 +++++++++---------
 mm/huge_memory.c           |   6 +-
 mm/memcontrol.c            |  53 ++++------
 mm/memory_hotplug.c        |   1 +
 mm/mlock.c                 |  10 +-
 mm/mmzone.c                |  14 +++
 mm/page_alloc.c            |   2 +-
 mm/page_idle.c             |   4 +-
 mm/swap.c                  | 183 ++++++++++++++++++++++++++++-----
 mm/vmscan.c                |  84 ++++++++-------
 17 files changed, 620 insertions(+), 171 deletions(-)
 create mode 100644 lib/list.c
Signature · 1 line
2.18.0
RFC PATCH v2 1/8 mm, memcontrol.c: make memcg lru stats thread-safe without lru_lock
lru_lock needs to be held to update memcg LRU statistics. This requirement arises fairly naturally based on when the stats are updated because callers are holding lru_lock already.
In preparation for allowing concurrent adds and removes from the LRU, however, make concurrent updates to these statistics safe without lru_lock. The lock continues to be held until later in the series, when it is replaced with a rwlock that also disables preemption, maintaining the assumption of __mod_lru_zone_size, which is introduced here.
Follow the existing pattern for statistics in memcontrol.h by using a combination of per-cpu counters and atomics.
Remove the negative statistics warning from ca707239e8a7 ("mm:update_lru_size warn and reset bad lru_size"). Although an earlier version of this patch updated the warning to account for the error introduced by the per-cpu counters, Hugh says this warning has not been seen in the wild and that for simplicity's sake it should probably just be removed.
---
 include/linux/memcontrol.h | 43 +++++++++++++++++++++++++++++---------
 mm/memcontrol.c            | 29 +++++++------------------
 2 files changed, 40 insertions(+), 32 deletions(-)
include/linux/memcontrol.h +33 -10
@@ -99,7 +99,8 @@ struct mem_cgroup_reclaim_iter { };struct lruvec_stat { -long count[NR_VM_NODE_STAT_ITEMS ]; +long node[NR_VM_NODE_STAT_ITEMS ]; +long lru_zone_size[MAX_NR_ZONES ][NR_LRU_LISTS ]; };/*
@@ -109,9 +110,8 @@ struct mem_cgroup_per_node {struct lruvec lruvec;struct lruvec_stat __percpu *lruvec_stat_cpu; -atomic_long_t lruvec_stat[NR_VM_NODE_STAT_ITEMS ]; - -unsigned long lru_zone_size[MAX_NR_ZONES ][NR_LRU_LISTS ]; +atomic_long_t node_stat[NR_VM_NODE_STAT_ITEMS ]; +atomic_long_t lru_zone_size[MAX_NR_ZONES ][NR_LRU_LISTS ];struct mem_cgroup_reclaim_iter iter[DEF_PRIORITY +1 ];
@@ -446,7 +446,7 @@ unsigned long mem_cgroup_get_lru_size(struct lruvec *lruvec, enum lru_list lru) mz = container_of(lruvec, struct mem_cgroup_per_node, lruvec);for (zid =0 ; zid <MAX_NR_ZONES ; zid++) - nr_pages += mz->lru_zone_size[zid][lru]; + nr_pages +=atomic64_read (&mz->lru_zone_size[zid][lru]);return nr_pages; }
@@ -457,7 +457,7 @@ unsigned long mem_cgroup_get_zone_lru_size(struct lruvec *lruvec,struct mem_cgroup_per_node *mz; mz = container_of(lruvec, struct mem_cgroup_per_node, lruvec); -return mz->lru_zone_size[zone_idx][lru]; +return atomic64_read (&mz->lru_zone_size[zone_idx][lru]); }void mem_cgroup_handle_over_high (void );
@@ -575,7 +575,7 @@ static inline unsigned long lruvec_page_state(struct lruvec *lruvec,return node_page_state (lruvec_pgdat (lruvec), idx); pn = container_of(lruvec, struct mem_cgroup_per_node, lruvec); - x =atomic_long_read (&pn->lruvec_stat[idx]); + x =atomic_long_read (&pn->node_stat[idx]);#ifdef CONFIG_SMP if (x <0 ) x =0 ;
@@ -601,12 +601,12 @@ static inline void __mod_lruvec_state(struct lruvec *lruvec,__mod_memcg_state (pn->memcg, idx, val);/* Update lruvec */ - x = val +__this_cpu_read (pn->lruvec_stat_cpu->count[idx]); + x = val +__this_cpu_read (pn->lruvec_stat_cpu->node[idx]);if (unlikely (abs (x) >MEMCG_CHARGE_BATCH )) { -atomic_long_add (x, &pn->lruvec_stat[idx]); +atomic_long_add (x, &pn->node_stat[idx]); x =0 ; } -__this_cpu_write (pn->lruvec_stat_cpu->count[idx], x); +__this_cpu_write (pn->lruvec_stat_cpu->node[idx], x); } static inline void mod_lruvec_state(struct lruvec *lruvec,
@@ -619,6 +619,29 @@ static inline void mod_lruvec_state(struct lruvec *lruvec,local_irq_restore (flags); } +/** +* __mod_lru_zone_size - update memcg lru statistics in batches +* +* Updates memcg lru statistics using per-cpu counters that spill into atomics +* above a threshold. +* +* Assumes that the caller has disabled preemption. IRQs may be enabled +* because this function is not called from irq context. +*/ +static inline void __mod_lru_zone_size (struct mem_cgroup_per_node *pn, +enum lru_list lru,int zid,int val) +{ +long x; +struct lruvec_stat __percpu *lruvec_stat_cpu = pn->lruvec_stat_cpu; + + x = val +__this_cpu_read (lruvec_stat_cpu->lru_zone_size[zid][lru]); +if (unlikely (abs (x) >MEMCG_CHARGE_BATCH )) { +atomic_long_add (x, &pn->lru_zone_size[zid][lru]); + x =0 ; + } +__this_cpu_write (lruvec_stat_cpu->lru_zone_size[zid][lru], x); +} +static inline void __mod_lruvec_page_state (struct page *page,enum node_stat_item idx,int val) {
mm/memcontrol.c +7 -22
@@ -962,36 +962,20 @@ struct lruvec *mem_cgroup_page_lruvec(struct page *page, struct pglist_data *pgd* @zid: zone id of the accounted pages * @nr_pages: positive when adding or negative when removing * -* This function must be called under lru_lock, just before a page is added -* to or just after a page is removed from an lru list (that ordering being -* so as to allow it to check that lru_size 0 is consistent with list_empty). +* This function must be called just before a page is added to, or just after a +* page is removed from, an lru list. Callers aren't required to hold lru_lock +* because these statistics use per-cpu counters and atomics. */ void mem_cgroup_update_lru_size (struct lruvec *lruvec,enum lru_list lru,int zid,int nr_pages) {struct mem_cgroup_per_node *mz; -unsigned long *lru_size; -long size;if (mem_cgroup_disabled ())return ; mz = container_of(lruvec, struct mem_cgroup_per_node, lruvec); - lru_size = &mz->lru_zone_size[zid][lru]; - -if (nr_pages <0 ) - *lru_size += nr_pages; - - size = *lru_size; -if (WARN_ONCE (size <0 , -"%s(%p, %d, %d): lru_size %ld\n" , - __func__, lruvec, lru, nr_pages, size)) { -VM_BUG_ON (1 ); - *lru_size =0 ; - } - -if (nr_pages >0 ) - *lru_size += nr_pages; +__mod_lru_zone_size (mz, lru, zid, nr_pages); }bool task_in_mem_cgroup (struct task_struct *task,struct mem_cgroup *memcg)
@@ -1833,9 +1817,10 @@ static int memcg_hotplug_cpu_dead(unsigned int cpu)struct mem_cgroup_per_node *pn; pn =mem_cgroup_nodeinfo (memcg, nid); - x =this_cpu_xchg (pn->lruvec_stat_cpu->count[i],0 ); + x =this_cpu_xchg (pn->lruvec_stat_cpu->node[i], +0 );if (x) -atomic_long_add (x, &pn->lruvec_stat[i]); +atomic_long_add (x, &pn->node_stat[i]); } }
Signature · 1 line
2.18.0
Re: [RFC PATCH v2 1/8] mm, memcontrol.c: make memcg lru stats thread-safe without lru_lock
Quoted 31 lines · Daniel Jordan
lru_lockneeds to be held to update memcg LRU statistics. This requirement arises fairly naturally based on when the stats are updated because callers are holdinglru_lockalready.In preparation for allowing concurrent adds and removes from the LRU, however, make concurrent updates to these statistics safe without
lru_lock. The lock continues to be held until later in the series, when it is replaced with a rwlock that also disables preemption, maintaining the assumption of__mod_lru_zone_size, which is introduced here.Follow the existing pattern for statistics in
memcontrol.hby using a combination of per-cpu counters and atomics.Remove the negative statistics warning from
ca707239e8a7("mm:update_lru_sizewarn and reset badlru_size"). Although an earlier version of this patch updated the warning to account for the error introduced by the per-cpu counters, Hugh says this warning has not been seen in the wild and that for simplicity's sake it should probably just be removed.Signed-off-by Daniel Jordan <[email protected]>--- include/linux/memcontrol.h | 43 +++++++++++++++++++++++++++++--------- mm/memcontrol.c | 29 +++++++------------------ 2 files changed, 40 insertions(+), 32 deletions(-)include/linux/memcontrol.h +0
-0
include/linux/memcontrol.h struct mem_cgroup_reclaim_iter { · line 103
Quoted 6 lines
include/linux/memcontrol.h +2
-1@@ -99,7 +99,8 @@ struct mem_cgroup_reclaim_iter { };struct lruvec_stat { -long count[NR_VM_NODE_STAT_ITEMS ]; +long node[NR_VM_NODE_STAT_ITEMS ]; +long lru_zone_size[MAX_NR_ZONES ][NR_LRU_LISTS ];
It might be better to use different name for the lru_zone_size field to distinguish it from the one in the mem_cgroup_per_node structure.
Quoted 146 lines
include/linux/memcontrol.h +31
-9};/* @@ -109,9 +110,8 @@ struct mem_cgroup_per_node {struct lruvec lruvec;struct lruvec_stat __percpu *lruvec_stat_cpu; -atomic_long_t lruvec_stat[NR_VM_NODE_STAT_ITEMS ]; - -unsigned long lru_zone_size[MAX_NR_ZONES ][NR_LRU_LISTS ]; +atomic_long_t node_stat[NR_VM_NODE_STAT_ITEMS ]; +atomic_long_t lru_zone_size[MAX_NR_ZONES ][NR_LRU_LISTS ];struct mem_cgroup_reclaim_iter iter[DEF_PRIORITY +1 ];@@ -446,7 +446,7 @@ unsigned long mem_cgroup_get_lru_size(struct lruvec *lruvec, enum lru_list lru) mz = container_of(lruvec, struct mem_cgroup_per_node, lruvec);for (zid =0 ; zid <MAX_NR_ZONES ; zid++) - nr_pages += mz->lru_zone_size[zid][lru]; + nr_pages +=atomic64_read (&mz->lru_zone_size[zid][lru]);return nr_pages; }@@ -457,7 +457,7 @@ unsigned long mem_cgroup_get_zone_lru_size(struct lruvec *lruvec,struct mem_cgroup_per_node *mz; mz = container_of(lruvec, struct mem_cgroup_per_node, lruvec); -return mz->lru_zone_size[zone_idx][lru]; +return atomic64_read (&mz->lru_zone_size[zone_idx][lru]); }void mem_cgroup_handle_over_high (void );@@ -575,7 +575,7 @@ static inline unsigned long lruvec_page_state(struct lruvec *lruvec,return node_page_state (lruvec_pgdat (lruvec), idx); pn = container_of(lruvec, struct mem_cgroup_per_node, lruvec); - x =atomic_long_read (&pn->lruvec_stat[idx]); + x =atomic_long_read (&pn->node_stat[idx]);#ifdef CONFIG_SMP if (x <0 ) x =0 ;@@ -601,12 +601,12 @@ static inline void __mod_lruvec_state(struct lruvec *lruvec,__mod_memcg_state (pn->memcg, idx, val);/* Update lruvec */ - x = val +__this_cpu_read (pn->lruvec_stat_cpu->count[idx]); + x = val +__this_cpu_read (pn->lruvec_stat_cpu->node[idx]);if (unlikely (abs (x) >MEMCG_CHARGE_BATCH )) { -atomic_long_add (x, &pn->lruvec_stat[idx]); +atomic_long_add (x, &pn->node_stat[idx]); x =0 ; } -__this_cpu_write (pn->lruvec_stat_cpu->count[idx], x); +__this_cpu_write (pn->lruvec_stat_cpu->node[idx], x); } static inline void mod_lruvec_state(struct lruvec *lruvec,@@ -619,6 +619,29 @@ static inline void mod_lruvec_state(struct lruvec *lruvec,local_irq_restore (flags); } +/** +* __mod_lru_zone_size - update memcg lru statistics in batches +* +* Updates memcg lru statistics using per-cpu counters that spill into atomics +* above a threshold. +* +* Assumes that the caller has disabled preemption. IRQs may be enabled +* because this function is not called from irq context. +*/ +static inline void __mod_lru_zone_size (struct mem_cgroup_per_node *pn, +enum lru_list lru,int zid,int val) +{ +long x; +struct lruvec_stat __percpu *lruvec_stat_cpu = pn->lruvec_stat_cpu; + + x = val +__this_cpu_read (lruvec_stat_cpu->lru_zone_size[zid][lru]); +if (unlikely (abs (x) >MEMCG_CHARGE_BATCH )) { +atomic_long_add (x, &pn->lru_zone_size[zid][lru]); + x =0 ; + } +__this_cpu_write (lruvec_stat_cpu->lru_zone_size[zid][lru], x); +} +static inline void __mod_lruvec_page_state (struct page *page,enum node_stat_item idx,int val) {mm/memcontrol.c +7
-22@@ -962,36 +962,20 @@ struct lruvec *mem_cgroup_page_lruvec(struct page *page, struct pglist_data *pgd* @zid: zone id of the accounted pages * @nr_pages: positive when adding or negative when removing * -* This function must be called under lru_lock, just before a page is added -* to or just after a page is removed from an lru list (that ordering being -* so as to allow it to check that lru_size 0 is consistent with list_empty). +* This function must be called just before a page is added to, or just after a +* page is removed from, an lru list. Callers aren't required to hold lru_lock +* because these statistics use per-cpu counters and atomics. */ void mem_cgroup_update_lru_size (struct lruvec *lruvec,enum lru_list lru,int zid,int nr_pages) {struct mem_cgroup_per_node *mz; -unsigned long *lru_size; -long size;if (mem_cgroup_disabled ())return ; mz = container_of(lruvec, struct mem_cgroup_per_node, lruvec); - lru_size = &mz->lru_zone_size[zid][lru]; - -if (nr_pages <0 ) - *lru_size += nr_pages; - - size = *lru_size; -if (WARN_ONCE (size <0 , -"%s(%p, %d, %d): lru_size %ld\n" , - __func__, lruvec, lru, nr_pages, size)) { -VM_BUG_ON (1 ); - *lru_size =0 ; - } - -if (nr_pages >0 ) - *lru_size += nr_pages; +__mod_lru_zone_size (mz, lru, zid, nr_pages); }bool task_in_mem_cgroup (struct task_struct *task,struct mem_cgroup *memcg)@@ -1833,9 +1817,10 @@ static int memcg_hotplug_cpu_dead(unsigned int cpu)struct mem_cgroup_per_node *pn; pn =mem_cgroup_nodeinfo (memcg, nid); - x =this_cpu_xchg (pn->lruvec_stat_cpu->count[i],0 ); + x =this_cpu_xchg (pn->lruvec_stat_cpu->node[i], +0 );if (x) -atomic_long_add (x, &pn->lruvec_stat[i]); +atomic_long_add (x, &pn->node_stat[i]); } }
Re: [RFC PATCH v2 1/8] mm, memcontrol.c: make memcg lru stats thread-safe without lru_lock
Quoted 8 lines · Laurent Dufour
Quoted 7 lines · Daniel Jordan
include/linux/memcontrol.h +0
-0@@ -99,7 +99,8 @@ struct mem_cgroup_reclaim_iter { };
Quoted 7 lines
include/linux/memcontrol.h struct mem_cgroup_reclaim_iter { · line 103
Quoted 4 lines
include/linux/memcontrol.h +2
-1struct lruvec_stat { -long count[NR_VM_NODE_STAT_ITEMS ]; +long node[NR_VM_NODE_STAT_ITEMS ]; +long lru_zone_size[MAX_NR_ZONES ][NR_LRU_LISTS ];It might be better to use different name for the
lru_zone_sizefield to distinguish it from the one in themem_cgroup_per_nodestructure.
Yes, not very grep-friendly. I'll change it to this:
struct lruvec_stat {
	long node_stat_cpu[NR_VM_NODE_STAT_ITEMS];
	long lru_zone_size_cpu[MAX_NR_ZONES][NR_LRU_LISTS];
};
So the fields are named like the corresponding fields in the mem_cgroup_per_node structure, plus _cpu. And I'm certainly open to other ideas.
RFC PATCH v2 2/8 mm: make zone_reclaim_stat updates thread-safe
In reply to Daniel Jordanlru_lock needs to be held to update the zone_reclaim_stat statistics. Similar to the previous patch, this requirement again arises fairly naturally because callers are holding lru_lock already.
In preparation for allowing concurrent adds and removes from the LRU, however, make concurrent updates to these statistics safe without lru_lock. The lock continues to be held until later in the series, when it is replaced with a rwlock that also disables preemption, maintaining the assumption in the comment above __update_page_reclaim_stat, which is introduced here.
Use a combination of per-cpu counters and atomics.
---
 include/linux/mmzone.h | 50 ++++++++++++++++++++++++++++++++++++++++++
 init/main.c            |  1 +
 mm/memcontrol.c        | 20 ++++++++---------
 mm/memory_hotplug.c    |  1 +
 mm/mmzone.c            | 14 ++++++++++++
 mm/swap.c              | 14 ++++++++----
 mm/vmscan.c            | 42 ++++++++++++++++++++---------------
 7 files changed, 110 insertions(+), 32 deletions(-)
include/linux/mmzone.h +50 -0
@@ -229,6 +229,12 @@ struct zone_reclaim_stat {* * The anon LRU stats live in [0], file LRU stats in [1] */ +atomic_long_t recent_rotated[2 ]; +atomic_long_t recent_scanned[2 ]; +}; + +/* These spill into the counters in struct zone_reclaim_stat beyond a cutoff. */ +struct zone_reclaim_stat_cpu {unsigned long recent_rotated[2 ];unsigned long recent_scanned[2 ]; };
@@ -236,6 +242,7 @@ struct zone_reclaim_stat {struct lruvec {struct list_head lists[NR_LRU_LISTS ];struct zone_reclaim_stat reclaim_stat; +struct zone_reclaim_stat_cpu __percpu *reclaim_stat_cpu;/* Evictions & activations on the inactive file list */ atomic_long_t inactive_age;/* Refaults at the time of last reclaim cycle */
@@ -245,6 +252,47 @@ struct lruvec {#endif }; +#define RECLAIM_STAT_BATCH 32U/* From SWAP_CLUSTER_MAX */ + +/* +* Callers of the below three functions that update reclaim stats must hold +* lru_lock and have preemption disabled. Use percpu counters that spill into +* atomics to allow concurrent updates when multiple readers hold lru_lock. +*/ + +static inline void __update_page_reclaim_stat (unsigned long count, +unsigned long *percpu_stat, +atomic_long_t *stat) +{ +unsigned long val = *percpu_stat + count; + +if (unlikely (val >RECLAIM_STAT_BATCH )) { +atomic_long_add (val, stat); + val =0 ; + } + *percpu_stat = val; +} + +static inline void update_reclaim_stat_scanned (struct lruvec *lruvec,int file, +unsigned long count) +{ +struct zone_reclaim_stat_cpu __percpu *percpu_stat = +this_cpu_ptr (lruvec->reclaim_stat_cpu); + +__update_page_reclaim_stat (count, &percpu_stat->recent_scanned[file], + &lruvec->reclaim_stat.recent_scanned[file]); +} + +static inline void update_reclaim_stat_rotated (struct lruvec *lruvec,int file, +unsigned long count) +{ +struct zone_reclaim_stat_cpu __percpu *percpu_stat = +this_cpu_ptr (lruvec->reclaim_stat_cpu); + +__update_page_reclaim_stat (count, &percpu_stat->recent_rotated[file], + &lruvec->reclaim_stat.recent_rotated[file]); +} +/* Mask used at gathering information at once (see memcontrol.c) */ #define LRU_ALL_FILE (BIT(LRU_INACTIVE_FILE) | BIT(LRU_ACTIVE_FILE))#define LRU_ALL_ANON (BIT(LRU_INACTIVE_ANON) | BIT(LRU_ACTIVE_ANON))
@@ -795,6 +843,8 @@ extern void init_currently_empty_zone(struct zone *zone, unsigned long start_pfn unsigned long size);extern void lruvec_init (struct lruvec *lruvec); +extern void lruvec_init_late (struct lruvec *lruvec); +extern void lruvecs_init_late (void );static inline struct pglist_data *lruvec_pgdat (struct lruvec *lruvec) {
init/main.c +1 -0
@@ -526,6 +526,7 @@ static void __init mm_init(void)init_espfix_bsp ();/* Should be run after espfix64 is set up. */ pti_init (); +lruvecs_init_late (); } asmlinkage __visible void __init start_kernel(void)
mm/memcontrol.c +10 -10
@@ -3152,22 +3152,22 @@ static int memcg_stat_show(struct seq_file *m, void *v)pg_data_t *pgdat;struct mem_cgroup_per_node *mz;struct zone_reclaim_stat *rstat; -unsigned long recent_rotated[2 ] = {0 ,0 }; -unsigned long recent_scanned[2 ] = {0 ,0 }; +unsigned long rota[2 ] = {0 ,0 }; +unsigned long scan[2 ] = {0 ,0 };for_each_online_pgdat (pgdat) { mz =mem_cgroup_nodeinfo (memcg, pgdat->node_id); rstat = &mz->lruvec.reclaim_stat; - recent_rotated[0 ] += rstat->recent_rotated[0 ]; - recent_rotated[1 ] += rstat->recent_rotated[1 ]; - recent_scanned[0 ] += rstat->recent_scanned[0 ]; - recent_scanned[1 ] += rstat->recent_scanned[1 ]; + rota[0 ] +=atomic_long_read (&rstat->recent_rotated[0 ]); + rota[1 ] +=atomic_long_read (&rstat->recent_rotated[1 ]); + scan[0 ] +=atomic_long_read (&rstat->recent_scanned[0 ]); + scan[1 ] +=atomic_long_read (&rstat->recent_scanned[1 ]); } -seq_printf (m,"recent_rotated_anon %lu\n" , recent_rotated[0 ]); -seq_printf (m,"recent_rotated_file %lu\n" , recent_rotated[1 ]); -seq_printf (m,"recent_scanned_anon %lu\n" , recent_scanned[0 ]); - seq_printf(m, "recent_scanned_file %lu\n", recent_scanned[1]); +seq_printf (m,"recent_rotated_anon %lu\n" , rota[0 ]); +seq_printf (m,"recent_rotated_file %lu\n" , rota[1 ]); +seq_printf (m,"recent_scanned_anon %lu\n" , scan[0 ]); + seq_printf(m, "recent_scanned_file %lu\n", scan[1]); }#endif
mm/memory_hotplug.c +1 -0
@@ -1009,6 +1009,7 @@ static pg_data_t __ref *hotadd_new_pgdat(int nid, u64 start)/* init node's zones as empty zones, we don't have any present pages.*/ free_area_init_node (nid, zones_size, start_pfn, zholes_size); pgdat->per_cpu_nodestats = alloc_percpu(struct per_cpu_nodestat); +lruvec_init_late (node_lruvec (pgdat));/* * The node we allocated has no zone fallback lists. For avoiding
mm/mmzone.c +14 -0
@@ -9,6 +9,7 @@#include <linux/stddef.h> #include <linux/mm.h> #include <linux/mmzone.h> +#include <linux/percpu.h> struct pglist_data *first_online_pgdat (void ) {
@@ -96,6 +97,19 @@ void lruvec_init(struct lruvec *lruvec)INIT_LIST_HEAD (&lruvec->lists[lru]); } +void lruvec_init_late (struct lruvec *lruvec) +{ + lruvec->reclaim_stat_cpu = alloc_percpu(struct zone_reclaim_stat_cpu); +} + +void lruvecs_init_late (void ) +{ +pg_data_t *pgdat; + +for_each_online_pgdat (pgdat) +lruvec_init_late (node_lruvec (pgdat)); +} +#if defined(CONFIG_NUMA_BALANCING ) && !defined(LAST_CPUPID_NOT_IN_PAGE_FLAGS )int page_cpupid_xchg_last (struct page *page,int cpupid) {
mm/swap.c +10 -4
@@ -34,6 +34,7 @@#include <linux/uio.h> #include <linux/hugetlb.h> #include <linux/page_idle.h> +#include <linux/mmzone.h> #include "internal.h"
@@ -260,14 +261,19 @@ void rotate_reclaimable_page(struct page *page) } } +/* +* Updates page reclaim statistics using per-cpu counters that spill into +* atomics above a threshold. +* +* Assumes that the caller has disabled preemption. IRQs may be enabled +* because this function is not called from irq context. +*/ static void update_page_reclaim_stat (struct lruvec *lruvec,int file,int rotated) { -struct zone_reclaim_stat *reclaim_stat = &lruvec->reclaim_stat; - - reclaim_stat->recent_scanned[file]++; +update_reclaim_stat_scanned (lruvec, file,1 );if (rotated) - reclaim_stat->recent_rotated[file]++; +update_reclaim_stat_rotated (lruvec, file,1 ); } static void __activate_page(struct page *page, struct lruvec *lruvec,
mm/vmscan.c +24 -18
111 lines not on this page · raw message
Signature · 1 line
2.18.0
Re: [RFC PATCH v2 2/8] mm: make zone_reclaim_stat updates thread-safe
Quoted 29 lines · Daniel Jordan
lru_lockneeds to be held to update thezone_reclaim_statstatistics. Similar to the previous patch, this requirement again arises fairly naturally because callers are holdinglru_lockalready.In preparation for allowing concurrent adds and removes from the LRU, however, make concurrent updates to these statistics safe without
lru_lock. The lock continues to be held until later in the series, when it is replaced with a rwlock that also disables preemption, maintaining the assumption in the comment above__update_page_reclaim_stat, which is introduced here.Use a combination of per-cpu counters and atomics.
Signed-off-by Daniel Jordan <[email protected]>--- include/linux/mmzone.h | 50 ++++++++++++++++++++++++++++++++++++++++++ init/main.c | 1 + mm/memcontrol.c | 20 ++++++++--------- mm/memory_hotplug.c | 1 + mm/mmzone.c | 14 ++++++++++++ mm/swap.c | 14 ++++++++---- mm/vmscan.c | 42 ++++++++++++++++++++--------------- 7 files changed, 110 insertions(+), 32 deletions(-)include/linux/mmzone.h +0
-0
include/linux/mmzone.h struct zone_reclaim_stat { · line 233
Quoted 5 lines
include/linux/mmzone.h +2
-0@@ -229,6 +229,12 @@ struct zone_reclaim_stat {* * The anon LRU stats live in [0], file LRU stats in [1] */ +atomic_long_t recent_rotated[2 ]; +atomic_long_t recent_scanned[2 ];
It might be better to use a slightly different name for these fields to distinguish them from the ones in the zone_reclaim_stat_cpu structure.
Quoted 328 lines
include/linux/mmzone.h +48
-0+}; + +/* These spill into the counters in struct zone_reclaim_stat beyond a cutoff. */ +struct zone_reclaim_stat_cpu {unsigned long recent_rotated[2 ];unsigned long recent_scanned[2 ]; };@@ -236,6 +242,7 @@ struct zone_reclaim_stat {struct lruvec {struct list_head lists[NR_LRU_LISTS ];struct zone_reclaim_stat reclaim_stat; +struct zone_reclaim_stat_cpu __percpu *reclaim_stat_cpu;/* Evictions & activations on the inactive file list */ atomic_long_t inactive_age;/* Refaults at the time of last reclaim cycle */ @@ -245,6 +252,47 @@ struct lruvec {#endif }; +#define RECLAIM_STAT_BATCH 32U/* From SWAP_CLUSTER_MAX */ + +/* +* Callers of the below three functions that update reclaim stats must hold +* lru_lock and have preemption disabled. Use percpu counters that spill into +* atomics to allow concurrent updates when multiple readers hold lru_lock. +*/ + +static inline void __update_page_reclaim_stat (unsigned long count, +unsigned long *percpu_stat, +atomic_long_t *stat) +{ +unsigned long val = *percpu_stat + count; + +if (unlikely (val >RECLAIM_STAT_BATCH )) { +atomic_long_add (val, stat); + val =0 ; + } + *percpu_stat = val; +} + +static inline void update_reclaim_stat_scanned (struct lruvec *lruvec,int file, +unsigned long count) +{ +struct zone_reclaim_stat_cpu __percpu *percpu_stat = +this_cpu_ptr (lruvec->reclaim_stat_cpu); + +__update_page_reclaim_stat (count, &percpu_stat->recent_scanned[file], + &lruvec->reclaim_stat.recent_scanned[file]); +} + +static inline void update_reclaim_stat_rotated (struct lruvec *lruvec,int file, +unsigned long count) +{ +struct zone_reclaim_stat_cpu __percpu *percpu_stat = +this_cpu_ptr (lruvec->reclaim_stat_cpu); + +__update_page_reclaim_stat (count, &percpu_stat->recent_rotated[file], + &lruvec->reclaim_stat.recent_rotated[file]); +} +/* Mask used at gathering information at once (see memcontrol.c) */ #define LRU_ALL_FILE (BIT(LRU_INACTIVE_FILE) | BIT(LRU_ACTIVE_FILE))#define LRU_ALL_ANON (BIT(LRU_INACTIVE_ANON) | BIT(LRU_ACTIVE_ANON))@@ -795,6 +843,8 @@ extern void init_currently_empty_zone(struct zone *zone, unsigned long start_pfn unsigned long size);extern void lruvec_init (struct lruvec *lruvec); +extern void lruvec_init_late (struct lruvec *lruvec); +extern void lruvecs_init_late (void );static inline struct pglist_data *lruvec_pgdat (struct lruvec *lruvec) {init/main.c +1
-0@@ -526,6 +526,7 @@ static void __init mm_init(void)init_espfix_bsp ();/* Should be run after espfix64 is set up. */ pti_init (); +lruvecs_init_late (); } asmlinkage __visible void __init start_kernel(void)mm/memcontrol.c +10
-10@@ -3152,22 +3152,22 @@ static int memcg_stat_show(struct seq_file *m, void *v)pg_data_t *pgdat;struct mem_cgroup_per_node *mz;struct zone_reclaim_stat *rstat; -unsigned long recent_rotated[2 ] = {0 ,0 }; -unsigned long recent_scanned[2 ] = {0 ,0 }; +unsigned long rota[2 ] = {0 ,0 }; +unsigned long scan[2 ] = {0 ,0 };for_each_online_pgdat (pgdat) { mz =mem_cgroup_nodeinfo (memcg, pgdat->node_id); rstat = &mz->lruvec.reclaim_stat; - recent_rotated[0 ] += rstat->recent_rotated[0 ]; - recent_rotated[1 ] += rstat->recent_rotated[1 ]; - recent_scanned[0 ] += rstat->recent_scanned[0 ]; - recent_scanned[1 ] += rstat->recent_scanned[1 ]; + rota[0 ] +=atomic_long_read (&rstat->recent_rotated[0 ]); + rota[1 ] +=atomic_long_read (&rstat->recent_rotated[1 ]); + scan[0 ] +=atomic_long_read (&rstat->recent_scanned[0 ]); + scan[1 ] +=atomic_long_read (&rstat->recent_scanned[1 ]); } -seq_printf (m,"recent_rotated_anon %lu\n" , recent_rotated[0 ]); -seq_printf (m,"recent_rotated_file %lu\n" , recent_rotated[1 ]); -seq_printf (m,"recent_scanned_anon %lu\n" , recent_scanned[0 ]); - seq_printf(m, "recent_scanned_file %lu\n", recent_scanned[1]); +seq_printf (m,"recent_rotated_anon %lu\n" , rota[0 ]); +seq_printf (m,"recent_rotated_file %lu\n" , rota[1 ]); +seq_printf (m,"recent_scanned_anon %lu\n" , scan[0 ]); + seq_printf(m, "recent_scanned_file %lu\n", scan[1]); }#endif mm/memory_hotplug.c +1
-0@@ -1009,6 +1009,7 @@ static pg_data_t __ref *hotadd_new_pgdat(int nid, u64 start)/* init node's zones as empty zones, we don't have any present pages.*/ free_area_init_node (nid, zones_size, start_pfn, zholes_size); pgdat->per_cpu_nodestats = alloc_percpu(struct per_cpu_nodestat); +lruvec_init_late (node_lruvec (pgdat));/* * The node we allocated has no zone fallback lists. For avoiding mm/mmzone.c +14
-0@@ -9,6 +9,7 @@#include <linux/stddef.h> #include <linux/mm.h> #include <linux/mmzone.h> +#include <linux/percpu.h> struct pglist_data *first_online_pgdat (void ) {@@ -96,6 +97,19 @@ void lruvec_init(struct lruvec *lruvec)INIT_LIST_HEAD (&lruvec->lists[lru]); } +void lruvec_init_late (struct lruvec *lruvec) +{ + lruvec->reclaim_stat_cpu = alloc_percpu(struct zone_reclaim_stat_cpu); +} + +void lruvecs_init_late (void ) +{ +pg_data_t *pgdat; + +for_each_online_pgdat (pgdat) +lruvec_init_late (node_lruvec (pgdat)); +} +#if defined(CONFIG_NUMA_BALANCING ) && !defined(LAST_CPUPID_NOT_IN_PAGE_FLAGS )int page_cpupid_xchg_last (struct page *page,int cpupid) {mm/swap.c +10
-4@@ -34,6 +34,7 @@#include <linux/uio.h> #include <linux/hugetlb.h> #include <linux/page_idle.h> +#include <linux/mmzone.h> #include "internal.h" @@ -260,14 +261,19 @@ void rotate_reclaimable_page(struct page *page) } } +/* +* Updates page reclaim statistics using per-cpu counters that spill into +* atomics above a threshold. +* +* Assumes that the caller has disabled preemption. IRQs may be enabled +* because this function is not called from irq context. +*/ static void update_page_reclaim_stat (struct lruvec *lruvec,int file,int rotated) { -struct zone_reclaim_stat *reclaim_stat = &lruvec->reclaim_stat; - - reclaim_stat->recent_scanned[file]++; +update_reclaim_stat_scanned (lruvec, file,1 );if (rotated) - reclaim_stat->recent_rotated[file]++; +update_reclaim_stat_rotated (lruvec, file,1 ); } static void __activate_page(struct page *page, struct lruvec *lruvec,mm/vmscan.c +24
-18@@ -1655,7 +1655,6 @@ static int too_many_isolated(struct pglist_data *pgdat, int file, static noinline_for_stack voidputback_inactive_pages (struct lruvec *lruvec,struct list_head *page_list) { -struct zone_reclaim_stat *reclaim_stat = &lruvec->reclaim_stat;struct pglist_data *pgdat =lruvec_pgdat (lruvec);LIST_HEAD (pages_to_free);@@ -1684,7 +1683,7 @@ putback_inactive_pages(struct lruvec *lruvec, struct list_head *page_list)if (is_active_lru (lru)) {int file =is_file_lru (lru);int numpages =hpage_nr_pages (page); - reclaim_stat->recent_rotated[file] += numpages; +update_reclaim_stat_rotated (lruvec, file, numpages); }if (put_page_testzero (page)) {__ClearPageLRU (page);@@ -1736,7 +1735,6 @@ shrink_inactive_list(unsigned long nr_to_scan, struct lruvec *lruvec,isolate_mode_t isolate_mode =0 ;int file =is_file_lru (lru);struct pglist_data *pgdat =lruvec_pgdat (lruvec); -struct zone_reclaim_stat *reclaim_stat = &lruvec->reclaim_stat;bool stalled = false;while (unlikely (too_many_isolated (pgdat, file, sc))) {@@ -1763,7 +1761,7 @@ shrink_inactive_list(unsigned long nr_to_scan, struct lruvec *lruvec, &nr_scanned, sc, isolate_mode, lru);__mod_node_page_state (pgdat,NR_ISOLATED_ANON + file, nr_taken); - reclaim_stat->recent_scanned[file] += nr_taken; +update_reclaim_stat_scanned (lruvec, file, nr_taken);if (current_is_kswapd ()) {if (global_reclaim (sc))@@ -1914,7 +1912,6 @@ static void shrink_active_list(unsigned long nr_to_scan,LIST_HEAD (l_active);LIST_HEAD (l_inactive);struct page *page; -struct zone_reclaim_stat *reclaim_stat = &lruvec->reclaim_stat;unsigned nr_deactivate, nr_activate;unsigned nr_rotated =0 ;isolate_mode_t isolate_mode =0 ;@@ -1932,7 +1929,7 @@ static void shrink_active_list(unsigned long nr_to_scan, &nr_scanned, sc, isolate_mode, lru);__mod_node_page_state (pgdat,NR_ISOLATED_ANON + file, nr_taken); - reclaim_stat->recent_scanned[file] += nr_taken; +update_reclaim_stat_scanned (lruvec, file, nr_taken);__count_vm_events (PGREFILL , nr_scanned);count_memcg_events (lruvec_memcg (lruvec),PGREFILL , nr_scanned);@@ -1989,7 +1986,7 @@ static void shrink_active_list(unsigned long nr_to_scan,* helps balance scan pressure between file and anonymous pages in * get_scan_count. */ - reclaim_stat->recent_rotated[file] += nr_rotated; +update_reclaim_stat_rotated (lruvec, file, nr_rotated); nr_activate =move_active_pages_to_lru (lruvec, &l_active, &l_hold, lru); nr_deactivate =move_active_pages_to_lru (lruvec, &l_inactive, &l_hold, lru -LRU_ACTIVE );@@ -2116,7 +2113,7 @@ static void get_scan_count(struct lruvec *lruvec, struct mem_cgroup *memcg, unsigned long *lru_pages) {int swappiness =mem_cgroup_swappiness (memcg); -struct zone_reclaim_stat *reclaim_stat = &lruvec->reclaim_stat; +struct zone_reclaim_stat *rstat = &lruvec->reclaim_stat;u64 fraction[2 ];u64 denominator =0 ;/* gcc */ struct pglist_data *pgdat =lruvec_pgdat (lruvec);@@ -2125,6 +2122,7 @@ static void get_scan_count(struct lruvec *lruvec, struct mem_cgroup *memcg,unsigned long anon, file;unsigned long ap, fp;enum lru_list lru; +long recent_scanned[2 ], recent_rotated[2 ];/* If we have no swap space, do not bother scanning anon pages. */ if (!sc->may_swap ||mem_cgroup_get_nr_swap_pages (memcg) <=0 ) {@@ -2238,14 +2236,22 @@ static void get_scan_count(struct lruvec *lruvec, struct mem_cgroup *memcg,lruvec_lru_size (lruvec,LRU_INACTIVE_FILE ,MAX_NR_ZONES );spin_lock_irq (&pgdat->lru_lock); -if (unlikely (reclaim_stat->recent_scanned[0 ] > anon /4 )) { - reclaim_stat->recent_scanned[0 ] /=2 ; - reclaim_stat->recent_rotated[0 ] /=2 ; + recent_scanned[0 ] =atomic_long_read (&rstat->recent_scanned[0 ]); + recent_rotated[0 ] =atomic_long_read (&rstat->recent_rotated[0 ]); +if (unlikely (recent_scanned[0 ] > anon /4 )) { + recent_scanned[0 ] /=2 ; + recent_rotated[0 ] /=2 ; +atomic_long_set (&rstat->recent_scanned[0 ], recent_scanned[0 ]); +atomic_long_set (&rstat->recent_rotated[0 ], recent_rotated[0 ]); } -if (unlikely (reclaim_stat->recent_scanned[1 ] > file /4 )) { - reclaim_stat->recent_scanned[1 ] /=2 ; - reclaim_stat->recent_rotated[1 ] /=2 ; + recent_scanned[1 ] =atomic_long_read (&rstat->recent_scanned[1 ]); + recent_rotated[1 ] =atomic_long_read (&rstat->recent_rotated[1 ]); +if (unlikely (recent_scanned[1 ] > file /4 )) { + recent_scanned[1 ] /=2 ; + recent_rotated[1 ] /=2 ; +atomic_long_set (&rstat->recent_scanned[1 ], recent_scanned[1 ]); +atomic_long_set (&rstat->recent_rotated[1 ], recent_rotated[1 ]); }/* @@ -2253,11 +2259,11 @@ static void get_scan_count(struct lruvec *lruvec, struct mem_cgroup *memcg,* proportional to the fraction of recently scanned pages on * each list that were recently referenced and in active use. */ - ap = anon_prio * (reclaim_stat->recent_scanned[0 ] +1 ); - ap /= reclaim_stat->recent_rotated[0 ] +1 ; + ap = anon_prio * (recent_scanned[0 ] +1 ); + ap /= recent_rotated[0 ] +1 ; - fp = file_prio * (reclaim_stat->recent_scanned[1 ] +1 ); - fp /= reclaim_stat->recent_rotated[1 ] +1 ; + fp = file_prio * (recent_scanned[1 ] +1 ); + fp /= recent_rotated[1 ] +1 ;spin_unlock_irq (&pgdat->lru_lock); fraction[0 ] = ap;
Re: [RFC PATCH v2 2/8] mm: make zone_reclaim_stat updates thread-safe
Quoted 14 lines · Laurent Dufour
include/linux/mmzone.h struct zone_reclaim_stat { · line 233
Quoted 10 lines · Daniel Jordan
include/linux/mmzone.h +2
-0@@ -229,6 +229,12 @@ struct zone_reclaim_stat {* * The anon LRU stats live in [0], file LRU stats in [1] */ +atomic_long_t recent_rotated[2 ]; +atomic_long_t recent_scanned[2 ];It might be better to use a slightly different name for these fields to distinguish them from the ones in the
zone_reclaim_stat_cpustructure.
Sure, these are now named recent_rotated_cpu and recent_scanned_cpu, absent better names.
Thanks for your comments.
RFC PATCH v2 3/8 mm: convert lru_lock from a spinlock_t to a rwlock_t
In reply to Daniel Jordanlru_lock is currently a spinlock, which allows only one task at a time to add or remove pages from any of a node's LRU lists, even if the pages are in different parts of the same LRU or on different LRUs altogether. This bottleneck shows up in memory-intensive database workloads such as decision support and data warehousing. In the artificial benchmark will-it-scale/page_fault1, the lock contributes to system anti-scaling, so that adding more processes causes less work to be done.
To prepare for better lru_lock scalability, change lru_lock into a rwlock_t. For now, just make all users take the lock as writers. Later, to allow concurrent operations, change some users to acquire as readers, which will synchronize amongst themselves in a fine-grained, per-page way. This is explained more later.
RW locks are slower than spinlocks. However, our results show that low task counts do not significantly regress, even in the stress test page_fault1, and high task counts enjoy much better scalability.
zone->lock is often taken around the same times as lru_lock and contributes to this bottleneck. For the full performance benefits of this work to be realized, both locks must be fixed, but changing lru_lock in isolation still allows modest performance improvements and is one step toward fixing the larger problem.
Remove the spin_is_locked check in lru_add_page_tail. Unfortunately, rwlock_t lacks an equivalent and adding one would require 17 new arch_write_is_locked functions, a heavy price for a single debugging check.
Yosef Lev had the idea to use a reader-writer lock to split up the code that lru_lock protects, a form of room synchronization.
---
 include/linux/mmzone.h |  4 +-
 mm/compaction.c        | 99 ++++++++++++++++++++++--------------------
 mm/huge_memory.c       |  6 +--
 mm/memcontrol.c        |  4 +-
 mm/mlock.c             | 10 ++---
 mm/page_alloc.c        |  2 +-
 mm/page_idle.c         |  4 +-
 mm/swap.c              | 44 +++++++++++--------
 mm/vmscan.c            | 42 +++++++++---------
 9 files changed, 112 insertions(+), 103 deletions(-)
include/linux/mmzone.h +2 -2
@@ -742,7 +742,7 @@ typedef struct pglist_data {/* Write-intensive fields used by page reclaim */ ZONE_PADDING (_pad1_) - spinlock_t lru_lock; + rwlock_t lru_lock;#ifdef CONFIG_DEFERRED_STRUCT_PAGE_INIT /*
@@ -783,7 +783,7 @@ typedef struct pglist_data {#define node_start_pfn (nid) (NODE_DATA(nid)->node_start_pfn)#define node_end_pfn (nid) pgdat_end_pfn(NODE_DATA(nid)) -static inline spinlock_t *zone_lru_lock (struct zone *zone) +static inline rwlock_t *zone_lru_lock (struct zone *zone) {return &zone->zone_pgdat->lru_lock; }
mm/compaction.c +51 -48
153 lines not on this page · raw message
mm/huge_memory.c +3 -3
@@ -2453,7 +2453,7 @@ static void __split_huge_page(struct page *page, struct list_head *list,xa_unlock (&head->mapping->i_pages); } -spin_unlock_irqrestore (zone_lru_lock (page_zone (head)), flags); +write_unlock_irqrestore (zone_lru_lock (page_zone (head)), flags);unfreeze_page (head);
@@ -2653,7 +2653,7 @@ int split_huge_page_to_list(struct page *page, struct list_head *list)lru_add_drain ();/* prevent PageLRU to go away from under us, and freeze lru stats */ -spin_lock_irqsave (zone_lru_lock (page_zone (head)), flags); +write_lock_irqsave (zone_lru_lock (page_zone (head)), flags);if (mapping) {void **pslot;
@@ -2701,7 +2701,7 @@ int split_huge_page_to_list(struct page *page, struct list_head *list)spin_unlock (&pgdata->split_queue_lock); fail:if (mapping)xa_unlock (&mapping->i_pages); -spin_unlock_irqrestore (zone_lru_lock (page_zone (head)), flags); +write_unlock_irqrestore (zone_lru_lock (page_zone (head)), flags);unfreeze_page (head); ret = -EBUSY ; }
mm/memcontrol.c +2 -2
@@ -2043,7 +2043,7 @@ static void lock_page_lru(struct page *page, int *isolated) {struct zone *zone =page_zone (page); -spin_lock_irq (zone_lru_lock (zone)); +write_lock_irq (zone_lru_lock (zone));if (PageLRU (page)) {struct lruvec *lruvec;
@@ -2067,7 +2067,7 @@ static void unlock_page_lru(struct page *page, int isolated)SetPageLRU (page);add_page_to_lru_list (page, lruvec,page_lru (page)); } -spin_unlock_irq (zone_lru_lock (zone)); +write_unlock_irq (zone_lru_lock (zone)); } static void commit_charge(struct page *page, struct mem_cgroup *memcg,
mm/mlock.c +5 -5
@@ -194,7 +194,7 @@ unsigned int munlock_vma_page(struct page *page)* might otherwise copy PageMlocked to part of the tail pages before * we clear it in the head page. It also stabilizes hpage_nr_pages(). */ -spin_lock_irq (zone_lru_lock (zone)); +write_lock_irq (zone_lru_lock (zone));if (!TestClearPageMlocked (page)) {/* Potentially, PTE-mapped THP: do not skip the rest PTEs */
@@ -206,14 +206,14 @@ unsigned int munlock_vma_page(struct page *page)__mod_zone_page_state (zone,NR_MLOCK , -nr_pages);if (__munlock_isolate_lru_page (page, true)) { -spin_unlock_irq (zone_lru_lock (zone)); +write_unlock_irq (zone_lru_lock (zone));__munlock_isolated_page (page); goto out; }__munlock_isolation_failed (page); unlock_out: -spin_unlock_irq (zone_lru_lock (zone)); +write_unlock_irq (zone_lru_lock (zone)); out:return nr_pages -1 ;
@@ -298,7 +298,7 @@ static void __munlock_pagevec(struct pagevec *pvec, struct zone *zone)pagevec_init (&pvec_putback);/* Phase 1: page isolation */ -spin_lock_irq (zone_lru_lock (zone)); +write_lock_irq (zone_lru_lock (zone));for (i =0 ; i < nr; i++) {struct page *page = pvec->pages[i];
@@ -325,7 +325,7 @@ static void __munlock_pagevec(struct pagevec *pvec, struct zone *zone) pvec->pages[i] =NULL ; }__mod_zone_page_state (zone,NR_MLOCK , delta_munlocked); -spin_unlock_irq (zone_lru_lock (zone)); +write_unlock_irq (zone_lru_lock (zone));/* Now we can release pins of pages that we are not munlocking */ pagevec_release (&pvec_putback);
mm/page_alloc.c +1 -1
@@ -6222,7 +6222,7 @@ static void __paginginit free_area_init_core(struct pglist_data *pgdat)init_waitqueue_head (&pgdat->kcompactd_wait);#endif pgdat_page_ext_init (pgdat); -spin_lock_init (&pgdat->lru_lock); +rwlock_init (&pgdat->lru_lock);lruvec_init (node_lruvec (pgdat)); pgdat->per_cpu_nodestats = &boot_nodestats;
mm/page_idle.c +2 -2
@@ -42,12 +42,12 @@ static struct page *page_idle_get_page(unsigned long pfn)return NULL ; zone =page_zone (page); -spin_lock_irq (zone_lru_lock (zone)); +write_lock_irq (zone_lru_lock (zone));if (unlikely (!PageLRU (page))) {put_page (page); page =NULL ; } -spin_unlock_irq (zone_lru_lock (zone)); +write_unlock_irq (zone_lru_lock (zone));return page; }
mm/swap.c +25 -19
112 lines not on this page · raw message
mm/vmscan.c +21 -21
150 lines not on this page · raw message
Signature · 1 line
2.18.0
RFC PATCH v2 4/8 mm: introduce smp_list_del for concurrent list entry removals
In reply to Daniel JordanNow that the LRU lock is a RW lock, lay the groundwork for fine-grained synchronization so that multiple threads holding the lock as reader can safely remove pages from an LRU at the same time.
Add a thread-safe variant of list_del called smp_list_del that allows multiple threads to delete nodes from a list, and wrap this new list API in smp_del_page_from_lru to get the LRU statistics updates right.
For bisectability's sake, call the new function only when holding lru_lock as writer. In the next patch, switch to taking it as reader.
The algorithm is explained in detail in the comments. Yosef Lev conceived of the algorithm, and this patch is heavily based on an earlier version from him. Thanks to Dave Dice for suggesting the prefetch.
---
 include/linux/list.h      |   2 +
 include/linux/mm_inline.h |  28 +++++++
 lib/Makefile              |   2 +-
 lib/list.c                | 158 ++++++++++++++++++++++++++++++++++++++
 mm/swap.c                 |   3 +-
 5 files changed, 191 insertions(+), 2 deletions(-)
 create mode 100644 lib/list.c
include/linux/list.h +2 -0
@@ -47,6 +47,8 @@ static inline bool __list_del_entry_valid(struct list_head *entry) }#endif +extern void smp_list_del (struct list_head *entry); +/* * Insert a new entry between two known consecutive entries. *
include/linux/mm_inline.h +28 -0
@@ -4,6 +4,7 @@#include <linux/huge_mm.h> #include <linux/swap.h> +#include <linux/list.h> /** * page_is_file_cache - should the page be on a file LRU or anon LRU?
@@ -65,6 +66,33 @@ static __always_inline void del_page_from_lru_list(struct page *page,update_lru_size (lruvec, lru,page_zonenum (page), -hpage_nr_pages (page)); } +/** +* smp_del_page_from_lru_list - thread-safe del_page_from_lru_list +* @page: page to delete from the LRU +* @lruvec: vector of LRUs +* @lru: type of LRU list to delete from within the lruvec +* +* Requires lru_lock to be held, preferably as reader for greater concurrency +* with other LRU operations but writers are also correct. +* +* Holding lru_lock as reader, the only unprotected shared state is @page's +* lru links, which smp_list_del safely handles. lru_lock excludes other +* writers, and the atomics and per-cpu counters in update_lru_size serialize +* racing stat updates. +* +* Concurrent removal of adjacent pages is expected to be rare. In +* will-it-scale/page_fault1, the ratio of iterations of any while loop in +* smp_list_del to calls to that function was less than 0.009% (and 0.009% was +* an outlier on an oversubscribed 44 core system). +*/ +static __always_inline void smp_del_page_from_lru_list(struct page *page, +struct lruvec *lruvec, +enum lru_list lru) +{ +smp_list_del (&page->lru); +update_lru_size (lruvec, lru,page_zonenum (page), -hpage_nr_pages (page)); +} +/** * page_lru_base_type - which LRU list type should a page be on? * @page: the page to test
lib/Makefile +1 -1
@@ -40,7 +40,7 @@ obj-y += bcd.o div64.o sort.o parser.o debug_locks.o random32.o \ gcd.o lcm.o list_sort.o uuid.o flex_array.o iov_iter.o clz_ctz.o \ bsearch.o find_bit.o llist.o memweight.o kfifo.o \ percpu-refcount.o percpu_ida.o rhashtable.o reciprocal_div.o \ - once.o refcount.o usercopy.o errseq.o bucket_locks.o + once.o refcount.o usercopy.o errseq.o bucket_locks.o list.o obj-$(CONFIG_STRING_SELFTEST) += test_string.o obj-y += string_helpers.o obj-$(CONFIG_TEST_STRING_HELPERS) += test-string_helpers.o
lib/list.c new file +158 -0
158 lines not on this page · raw message
mm/swap.c +2 -1
@@ -789,7 +789,8 @@ void release_pages(struct page **pages, int nr) lruvec =mem_cgroup_page_lruvec (page, locked_pgdat);VM_BUG_ON_PAGE (!PageLRU (page), page);__ClearPageLRU (page); -del_page_from_lru_list (page, lruvec,page_off_lru (page)); +smp_del_page_from_lru_list (page, lruvec, +page_off_lru (page)); }/* Clear Active bit in case of parallel mark_page_accessed */
Signature · 1 line
2.18.0
RFC PATCH v2 5/8 mm: enable concurrent LRU removals
In reply to Daniel JordanThe previous patch used the concurrent algorithm serially to see that it was stable for one task. Now in release_pages, take lru_lock as reader instead of writer to allow concurrent removals from one or more LRUs.
---
 mm/swap.c | 28 +++++++++++++---------------
 1 file changed, 13 insertions(+), 15 deletions(-)
mm/swap.c +13 -15
@@ -737,8 +737,8 @@ void release_pages(struct page **pages, int nr)* same pgdat. The lock is held only if pgdat != NULL. */ if (locked_pgdat && ++lock_batch ==SWAP_CLUSTER_MAX ) { -write_unlock_irqrestore (&locked_pgdat->lru_lock, - flags); +read_unlock_irqrestore (&locked_pgdat->lru_lock, + flags); locked_pgdat =NULL ; }
@@ -748,9 +748,8 @@ void release_pages(struct page **pages, int nr)/* Device public page can not be huge page */ if (is_device_public_page (page)) {if (locked_pgdat) { -write_unlock_irqrestore ( - &locked_pgdat->lru_lock, - flags); +read_unlock_irqrestore (&locked_pgdat->lru_lock, + flags); locked_pgdat =NULL ; }put_zone_device_private_or_public_page (page);
@@ -763,9 +762,8 @@ void release_pages(struct page **pages, int nr)if (PageCompound (page)) {if (locked_pgdat) { -write_unlock_irqrestore ( - &locked_pgdat->lru_lock, - flags); +read_unlock_irqrestore (&locked_pgdat->lru_lock, + flags); locked_pgdat =NULL ; }__put_compound_page (page);
@@ -776,14 +774,14 @@ void release_pages(struct page **pages, int nr)struct pglist_data *pgdat =page_pgdat (page);if (pgdat != locked_pgdat) { -if (locked_pgdat) { -write_unlock_irqrestore ( - &locked_pgdat->lru_lock, flags); - } +if (locked_pgdat) +read_unlock_irqrestore ( + &locked_pgdat->lru_lock, + flags); lock_batch =0 ; locked_pgdat = pgdat; -write_lock_irqsave (&locked_pgdat->lru_lock, - flags); +read_lock_irqsave (&locked_pgdat->lru_lock, + flags); } lruvec =mem_cgroup_page_lruvec (page, locked_pgdat);
@@ -800,7 +798,7 @@ void release_pages(struct page **pages, int nr)list_add (&page->lru, &pages_to_free); }if (locked_pgdat) -write_unlock_irqrestore (&locked_pgdat->lru_lock, flags); +read_unlock_irqrestore (&locked_pgdat->lru_lock, flags);mem_cgroup_uncharge_list (&pages_to_free);free_unref_page_list (&pages_to_free);
Signature · 1 line
2.18.0
RFC PATCH v2 6/8 mm: splice local lists onto the front of the LRU
In reply to Daniel JordanThe add-to-front LRU path currently adds one page at a time to the front of an LRU. This is slow when using the concurrent algorithm described in the next patch because the LRU head node will be locked for every page that's added.
Instead, prepare local lists of pages, grouped by LRU, to be added to a given LRU in a single splice operation. The batching effect will reduce the amount of time that the LRU head is locked per page added.
---
 mm/swap.c | 123 ++++++++++++++++++++++++++++++++++++++++++++++++++++--
 1 file changed, 119 insertions(+), 4 deletions(-)
mm/swap.c +119 -4
@@ -865,8 +865,52 @@ void lru_add_page_tail(struct page *page, struct page *page_tail, }#endif /* CONFIG_TRANSPARENT_HUGEPAGE */ -static void __pagevec_lru_add_fn (struct page *page,struct lruvec *lruvec, -void *arg) +#define MAX_LRU_SPLICES 4 + +struct lru_splice { +struct list_head list; +struct list_head *lru; +struct pglist_data *pgdat; +}; + +/* +* Adds a page to a local list for splicing, or else to the singletons +* list for individual processing. +* +* Returns the new number of splices in the splices list. +*/ +static size_t add_page_to_splice (struct page *page,struct pglist_data *pgdat, +struct lru_splice *splices,size_t nr_splices, +struct list_head *singletons, +struct list_head *lru) +{ +int i; + +for (i =0 ; i < nr_splices; ++i) { +if (splices[i].lru == lru) { +list_add (&page->lru, &splices[i].list); +return nr_splices; + } + } + +if (nr_splices <MAX_LRU_SPLICES ) { +INIT_LIST_HEAD (&splices[nr_splices].list); + splices[nr_splices].lru = lru; + splices[nr_splices].pgdat = pgdat; +list_add (&page->lru, &splices[nr_splices].list); + ++nr_splices; + }else { +list_add (&page->lru, singletons); + } + +return nr_splices; +} + +static size_t pagevec_lru_add_splice (struct page *page,struct lruvec *lruvec, +struct pglist_data *pgdat, +struct lru_splice *splices, +size_t nr_splices, +struct list_head *singletons) {enum lru_list lru;int was_unevictable =TestClearPageUnevictable (page);
@@ -916,8 +960,12 @@ static void __pagevec_lru_add_fn(struct page *page, struct lruvec *lruvec,count_vm_event (UNEVICTABLE_PGCULLED ); } -add_page_to_lru_list (page, lruvec, lru); + nr_splices =add_page_to_splice (page, pgdat, splices, nr_splices, + singletons, &lruvec->lists[lru]); +update_lru_size (lruvec, lru,page_zonenum (page),hpage_nr_pages (page));trace_mm_lru_insertion (page, lru); + +return nr_splices; }/*
@@ -926,7 +974,74 @@ static void __pagevec_lru_add_fn(struct page *page, struct lruvec *lruvec,*/ void __pagevec_lru_add (struct pagevec *pvec) { -pagevec_lru_move_fn (pvec, __pagevec_lru_add_fn,NULL ); +int i; +struct pglist_data *pagepgdat, *pgdat =NULL ; +unsigned long flags =0 ; +struct lru_splice splices[MAX_LRU_SPLICES ]; +size_t nr_splices =0 ; +LIST_HEAD (singletons); +struct page *page; +struct lruvec *lruvec; +enum lru_list lru; + +/* +* Sort the pages into local lists to splice onto the LRU. In the +* common case there should be few of these local lists. +*/ +for (i =0 ; i <pagevec_count (pvec); ++i) { + page = pvec->pages[i]; + pagepgdat =page_pgdat (page); + +/* +* Take lru_lock now so that setting PageLRU and setting the +* local list's links appear to happen atomically. +*/ +if (pagepgdat != pgdat) { +if (pgdat) +write_unlock_irqrestore (&pgdat->lru_lock, flags); + pgdat = pagepgdat; +write_lock_irqsave (&pgdat->lru_lock, flags); + } + + lruvec =mem_cgroup_page_lruvec (page, pagepgdat); + + nr_splices =pagevec_lru_add_splice (page, lruvec, pagepgdat, + splices, nr_splices, + &singletons); + } + +for (i =0 ; i < nr_splices; ++i) { +struct lru_splice *splice = &splices[i]; + +if (splice->pgdat != pgdat) { +if (pgdat) +write_unlock_irqrestore (&pgdat->lru_lock, flags); + pgdat = splice->pgdat; +write_lock_irqsave (&pgdat->lru_lock, flags); + } +list_splice (&splice->list, splice->lru); + } + +while (!list_empty (&singletons)) { + page = list_first_entry(&singletons, struct page, lru); +list_del (singletons.next); + pagepgdat =page_pgdat (page); + +if (pagepgdat != pgdat) { +if (pgdat) +write_unlock_irqrestore (&pgdat->lru_lock, flags); + pgdat = pagepgdat; +write_lock_irqsave (&pgdat->lru_lock, flags); + } + + lruvec =mem_cgroup_page_lruvec (page, pgdat); + lru =page_lru (page); +list_add (&page->lru, &lruvec->lists[lru]); + } +if (pgdat) +write_unlock_irqrestore (&pgdat->lru_lock, flags); +release_pages (pvec->pages, pvec->nr); +pagevec_reinit (pvec); }EXPORT_SYMBOL (__pagevec_lru_add);
Signature · 1 line
2.18.0
RFC PATCH v2 7/8 mm: introduce smp_list_splice to prepare for concurrent LRU adds
In reply to Daniel JordanNow that we splice a local list onto the LRU, prepare for multiple tasks doing this concurrently by adding a variant of the kernel's list splicing API, list_splice, that's designed to work with multiple tasks.
Although there is naturally less parallelism to be gained from locking the LRU head this way, the main benefit of doing this is to allow removals to happen concurrently. The way lru_lock is today, an add needlessly blocks removal of any page but the first in the LRU.
For now, hold lru_lock as writer to serialize the adds to ensure the function is correct for a single thread at a time.
Yosef Lev came up with this algorithm.
---
 include/linux/list.h |  1 +
 lib/list.c           | 60 ++++++++++++++++++++++++++++++++++++++------
 mm/swap.c            |  3 ++-
 3 files changed, 56 insertions(+), 8 deletions(-)
include/linux/list.h +1 -0
@@ -48,6 +48,7 @@ static inline bool __list_del_entry_valid(struct list_head *entry)#endif extern void smp_list_del (struct list_head *entry); +extern void smp_list_splice (struct list_head *list,struct list_head *head);/* * Insert a new entry between two known consecutive entries.
lib/list.c +53 -7
73 lines not on this page · raw message
mm/swap.c +2 -1
@@ -35,6 +35,7 @@#include <linux/hugetlb.h> #include <linux/page_idle.h> #include <linux/mmzone.h> +#include <linux/list.h> #include "internal.h"
@@ -1019,7 +1020,7 @@ void __pagevec_lru_add(struct pagevec *pvec) pgdat = splice->pgdat;write_lock_irqsave (&pgdat->lru_lock, flags); } -list_splice (&splice->list, splice->lru); +smp_list_splice (&splice->list, splice->lru); }while (!list_empty (&singletons)) {
Signature · 1 line
2.18.0
RFC PATCH v2 8/8 mm: enable concurrent LRU adds
In reply to Daniel JordanSwitch over to holding lru_lock as reader when splicing pages onto the front of an LRU. The main benefit of doing this is to allow LRU adds and removes to happen concurrently. Before this patch, an add blocks all removing threads.
---
 mm/swap.c | 12 ++++++++----
 1 file changed, 8 insertions(+), 4 deletions(-)
mm/swap.c +8 -4
@@ -999,9 +999,9 @@ void __pagevec_lru_add(struct pagevec *pvec)*/ if (pagepgdat != pgdat) {if (pgdat) -write_unlock_irqrestore (&pgdat->lru_lock, flags); +read_unlock_irqrestore (&pgdat->lru_lock, flags); pgdat = pagepgdat; -write_lock_irqsave (&pgdat->lru_lock, flags); +read_lock_irqsave (&pgdat->lru_lock, flags); } lruvec =mem_cgroup_page_lruvec (page, pagepgdat);
@@ -1016,12 +1016,16 @@ void __pagevec_lru_add(struct pagevec *pvec)if (splice->pgdat != pgdat) {if (pgdat) -write_unlock_irqrestore (&pgdat->lru_lock, flags); +read_unlock_irqrestore (&pgdat->lru_lock, flags); pgdat = splice->pgdat; -write_lock_irqsave (&pgdat->lru_lock, flags); +read_lock_irqsave (&pgdat->lru_lock, flags); }smp_list_splice (&splice->list, splice->lru); } +if (pgdat) { +read_unlock_irqrestore (&pgdat->lru_lock, flags); + pgdat =NULL ; + }while (!list_empty (&singletons)) { page = list_first_entry(&singletons, struct page, lru);
Signature · 1 line
2.18.0
Quoted 25 lines · Daniel Jordan
Hi,
This is a work-in-progress of what I presented at LSF/MM this year[0] to greatly reduce contention on
lru_lock, allowing it to scale on large systems.This is completely different from the
lru_lockseries posted last January[1].I'm hoping for feedback on the overall design and general direction as I do more real-world performance testing and polish the code. Is this a workable approach?
Thanks,
Daniel---
Summary:
lru_lockcan be one of the hottest locks in the kernel on big systems. It guards too much state, so introduce new SMP-safe list functions to allow multiple threads to operate on the LRUs at once. The SMP list functions are provided in a standalone API that can be used in other parts of the kernel. Whenlru_lockandzone->lockare both fixed, the kernel can do up to 73.8% more page faults per second on a 44-core machine.---
Quoted 7 lines
On large systems,
lru_lockcan become heavily contended in memory-intensive workloads such as decision support, applications that manage their memory manually by allocating and freeing pages directly from the kernel, and workloads with short-lived processes that force many munmap and exit operations.lru_lockalso inhibits scalability in many of the MM paths that could be parallelized, such as freeing pages during exit/munmap and inode eviction.
Interesting, I would have expected isolate_lru_pages() to be the main culprit, as the comment says:
* For pagecache intensive workloads, this function is the hottest
* spot in the kernel (apart from copy_*_user functions).
It also says "Some of the functions that shrink the lists perform better by taking out a batch of pages and working on them outside the LRU lock." Makes me wonder why isolate_lru_pages() also doesn't cut the list first instead of doing per-page list_move() (and perhaps also prefetch batch of struct pages outside the lock first? Could be doable with some care hopefully).
Quoted 23 lines
The problem is that
lru_lockis too big of a hammer. It guards all the LRUs in a pgdat's lruvec, needlessly serializing add-to-front, add-to-tail, and delete operations that are done on disjoint parts of an LRU, or even completely different LRUs.This RFC series, developed in collaboration with Yossi Lev and Dave Dice, offers a two-part solution to this problem.
First, three new list functions are introduced to allow multiple threads to operate on the same linked list simultaneously under certain conditions, which are spelled out in more detail in code comments and changelogs. The functions are
smp_list_del,smp_list_splice, andsmp_list_add, and do the same things as their non-SMP-safe counterparts. These primitives may be used elsewhere in the kernel as the need arises; for example, in the page allocator free lists to scale zone->lock[2], or in file system LRUs[3].Second,
lru_lockis converted from a spinlock to a rwlock. The idea is to repurpose rwlock as a two-mode lock, where callers take the lock in shared (i.e. read) mode for code using the SMP list functions, and exclusive (i.e. write) mode for existing code that expects exclusive access to the LRUs. Multiple threads are allowed in under the read lock, of course, and they use the SMP list functions to synchronize amongst themselves.
Quoted 5 lines
The rwlock is scaffolding to facilitate the transition from big-hammer
lru_lockas it exists today to just using the list locking primitives and getting rid oflru_lockentirely. Such an approach allows incremental conversion oflru_lockwriters until everything uses the SMP list functions and takes the lock in shared mode, at which pointlru_lockcan just go away.
Yeah I guess that will need more care, e.g. I think smp_list_del() can break any thread doing just a read-only traversal as it can end up with an entry that's been deleted and its next/prev poisoned. It's a bit counterintuitive that "read lock" is now enough for selected modify operations, while read-only traversal would need a write lock.
Quoted 9 lines
This RFC series is incomplete. More, and more realistic, performance numbers are needed; for now, I show only will-it-scale/page_fault1. Also, there are extensions I'd like to make to the locking scheme to handle certain
lru_lockpaths--in particular, those where multiple threads may delete the same node from an LRU. The SMP list functions now handle only removal of _adjacent_ nodes from an LRU. Finally, the diffstat should become more supportive after I remove some of the code duplication in patch 6 by converting the rest of the per-CPU pagevec code inmm/swap.cto use the SMP list functions.
Quoted 9 lines · Vlastimil Babka
Quoted 7 lines · Daniel Jordan
On large systems,
lru_lockcan become heavily contended in memory-intensive workloads such as decision support, applications that manage their memory manually by allocating and freeing pages directly from the kernel, and workloads with short-lived processes that force many munmap and exit operations.lru_lockalso inhibits scalability in many of the MM paths that could be parallelized, such as freeing pages during exit/munmap and inode eviction.
Quoted 5 lines
Interesting, I would have expected
isolate_lru_pages()to be the main culprit, as the comment says:* For pagecache intensive workloads, this function is the hottest
* spot in the kernel (apart from copy_*_user functions).
Yes, I'm planning to stress reclaim to see how lru_lock responds. I've experimented some with using dd on lots of nvme drives to keep kswapd busy, but I'm always looking for more realistic stuff. Suggestions welcome :)
Quoted 6 lines
It also says "Some of the functions that shrink the lists perform better by taking out a batch of pages and working on them outside the LRU lock." Makes me wonder why
isolate_lru_pages()also doesn't cut the list first instead of doing per-pagelist_move()(and perhaps also prefetch batch of struct pages outside the lock first? Could be doable with some care hopefully).
Seems like the batch prefetching and list cutting would go hand in hand, since cutting requires walking the LRU to find where to cut, which could miss on all the page list nodes along the way.
I'll experiment with this.
Quoted 13 lines
Quoted 7 lines
Second,
lru_lockis converted from a spinlock to a rwlock. The idea is to repurpose rwlock as a two-mode lock, where callers take the lock in shared (i.e. read) mode for code using the SMP list functions, and exclusive (i.e. write) mode for existing code that expects exclusive access to the LRUs. Multiple threads are allowed in under the read lock, of course, and they use the SMP list functions to synchronize amongst themselves.Quoted 5 lines
The rwlock is scaffolding to facilitate the transition from big-hammer
lru_lockas it exists today to just using the list locking primitives and getting rid oflru_lockentirely. Such an approach allows incremental conversion oflru_lockwriters until everything uses the SMP list functions and takes the lock in shared mode, at which pointlru_lockcan just go away.
Quoted 3 lines
Yeah I guess that will need more care, e.g. I think
smp_list_del()can break any thread doing just a read-only traversal as it can end up with an entry that's been deleted and its next/prev poisoned.
As far as I can see from checking everywhere the kernel takes lru_lock, nothing currently walks the LRUs. LRU-using code just deletes a page from anywhere, or adds one page at a time from the head or tail, so it seems safe to use smp_list_* for all LRU paths.
This RFC doesn't handle adding and removing from list tails yet, but that seems doable.
Quoted 3 lines
It's a bit
counterintuitive that "read lock" is now enough for selected modify operations, while read-only traversal would need a write lock.
Yes, I considered introducing wrappers to clarify this, e.g. an inline function exclusive_lock_irqsave that just calls write_lock_irqsave, to let people know the locks are being used specially. Would be happy to add these in.
Thanks for taking a look, Vlastimil, and for your comments!