discard storm on idle since v6.1-rc8-59-g63a7cb130718 discard=async
Subsystems (2)
I can also confirm the issue occurred on and after kernel 6.2, and confirm the workaround setting btrfs discard iops_limit works for my device:
08:00.0 Non-Volatile memory controller: Samsung Electronics Co Ltd NVMe SSD Controller PM9A1/PM9A3/9
80PRO
I had to use ~6000 for my device, instead of 1000. I'm currently on kernel 6.2.1.
I am also interested to know what if this is expected.
Quoted 5 lines · Christopher Price
I can also confirm the issue occurred on and after kernel 6.2, and confirm the workaround setting btrfs discard
iops_limitworks for my device:
Quoted 8 lines
08:00.0 Non-Volatile memory controller: Samsung Electronics Co Ltd NVMe SSD Controller PM9A1/PM9A3/9
80PROI had to use ~6000 for my device, instead of 1000. I'm currently on kernel 6.2.1.
I am also interested to know what if this is expected.
We got the defaults based on our testing with our workloads inside of FB. Clearly this isn't representative of a normal desktop usage, but we've also got a lot of workloads so figured if it made the whole fleet happy it would probably be fine everywhere.
That being said this is tunable for a reason, your workload seems to generate a lot of free'd extents and discards. We can probably mess with the async stuff to maybe pause discarding if there's no other activity happening on the device at the moment, but tuning it to let more discards through at a time is also completely valid. Thanks,
Josef
Quoted 10 lines · Josef Bacik
We got the defaults based on our testing with our workloads inside of FB. Clearly this isn't representative of a normal desktop usage, but we've also got a lot of workloads so figured if it made the whole fleet happy it would probably be fine everywhere.
That being said this is tunable for a reason, your workload seems to generate a lot of free'd extents and discards. We can probably mess with the async stuff to maybe pause discarding if there's no other activity happening on the device at the moment, but tuning it to let more discards through at a time is also completely valid. Thanks,
FYI, discard performance differs a lot between different SSDs. It used to be pretty horrible for most devices early on, and then a certain hyperscaler started requiring decent performance for enterprise drives, so many of them are good now. A lot less so for the typical consumer drive, especially at the lower end of the spectrum.
And that jut NVMe, the still shipping SATA SSDs are another different story. Not helped by the fact that we don't even support ranged discards for them in Linux.
Quoted 18 lines · On Wed, 22 Mar 2023 01:38:42 -0700 Christoph Hellwig <[email protected]> wrote:
Quoted 10 lines · Josef Bacik
We got the defaults based on our testing with our workloads inside of FB. Clearly this isn't representative of a normal desktop usage, but we've also got a lot of workloads so figured if it made the whole fleet happy it would probably be fine everywhere.
That being said this is tunable for a reason, your workload seems to generate a lot of free'd extents and discards. We can probably mess with the async stuff to maybe pause discarding if there's no other activity happening on the device at the moment, but tuning it to let more discards through at a time is also completely valid. Thanks,
FYI, discard performance differs a lot between different SSDs. It used to be pretty horrible for most devices early on, and then a certain hyperscaler started requiring decent performance for enterprise drives, so many of them are good now. A lot less so for the typical consumer drive, especially at the lower end of the spectrum.
Quoted 3 lines
And that jut NVMe, the still shipping SATA SSDs are another different story. Not helped by the fact that we don't even support ranged discards for them in Linux.
Josef, what did you use as a signal to detect what value was good enough? Did you crank up the number until discard backlog clears up in a reasonable time?
I still don't understand what I should take into account to change the default and whether I should change it at all. Is it fine if the discard backlog takes a week to get through it? (Or a day? An hour? A minute?)
Is it fine to send discards as fast as device allows instead of doing 10 IOPS? Does IOPS limit consider a device wearing tradeoff? Then low IOPS makes sense. Or IOPS limit is just a way to reserve most bandwidth to non-discard workloads? Then I would say unlimited IOPS as a default would make more sense for btrfs.
Signature · 1 line
Sergei
Quoted 9 lines · Sergei Trofimovich
Quoted 6 lines · On Wed, 22 Mar 2023 01:38:42 -0700 Christoph Hellwig <[email protected]> wrote:
Quoted 5 lines · Josef Bacik
We got the defaults based on our testing with our workloads inside of FB. Clearly this isn't representative of a normal desktop usage, but we've also got a lot of workloads so figured if it made the whole fleet happy it would probably be fine everywhere.
Quoted 5 lines
Quoted 5 lines
Quoted 5 lines
That being said this is tunable for a reason, your workload seems to generate a lot of free'd extents and discards. We can probably mess with the async stuff to maybe pause discarding if there's no other activity happening on the device at the moment, but tuning it to let more discards through at a time is also completely valid. Thanks,
BTW, there is another report about this issue here:
https://bugzilla.redhat.com/show_bug.cgi?id=2182228
/me wonders if there is a opensuse report as well, but a quick search didn't find one
And as fun fact or for completeness, the issue even made it to reddit, too:
https://www.reddit.com/r/archlinux/comments/121htxn/btrfs_discard_storm_on_62x_kernel/
Quoted 9 lines
Quoted 9 lines
FYI, discard performance differs a lot between different SSDs. It used to be pretty horrible for most devices early on, and then a certain hyperscaler started requiring decent performance for enterprise drives, so many of them are good now. A lot less so for the typical consumer drive, especially at the lower end of the spectrum.
And that jut NVMe, the still shipping SATA SSDs are another different story. Not helped by the fact that we don't even support ranged discards for them in Linux.
Thx for your comments Christoph. Quick question, just to be sure I understand things properly:
I assume on some of those problematic devices these discard storms will lead to a performance regression?
I also heard people saying these discard storms might reduce the life time of some devices - is that true?
If the answer to at least one of these is "yes" I'd say we it might be best to revert 63a7cb130718 for now.
Quoted 8 lines
Josef, what did you use as a signal to detect what value was good enough? Did you crank up the number until discard backlog clears up in a reasonable time?
I still don't understand what I should take into account to change the default and whether I should change it at all. Is it fine if the discard backlog takes a week to get through it? (Or a day? An hour? A minute?)
Quoted 5 lines
Is it fine to send discards as fast as device allows instead of doing 10 IOPS? Does IOPS limit consider a device wearing tradeoff? Then low IOPS makes sense. Or IOPS limit is just a way to reserve most bandwidth to non-discard workloads? Then I would say unlimited IOPS as a default would make more sense for btrfs.
/me would be interested in answers to these questions as well
Ciao, Thorsten (wearing his 'the Linux kernel's regression tracker' hat) --
Everything you wanna know about Linux kernel regression tracking:
https://linux-regtracking.leemhuis.info/about/#tldr
If I did something stupid, please tell me, as explained on that page.
Quoted 9 lines · Linux regression tracking (Thorsten Leemhuis)
Quoted 3 lines
Quoted 3 lines
And that jut NVMe, the still shipping SATA SSDs are another different story. Not helped by the fact that we don't even support ranged discards for them in Linux.
Thx for your comments Christoph. Quick question, just to be sure I understand things properly:
I assume on some of those problematic devices these discard storms will lead to a performance regression?
Probably.
Quoted 2 lines
I also heard people saying these discard storms might reduce the life time of some devices - is that true?
Also very much possible. There are various SSDs that treat a discard as a write zeroes and always return zeroes from all discarded blocks. If the discards are smaller than or not aligned to the internal erase (super)blocks, this will actually cause additional writes.
Quoted 2 lines
If the answer to at least one of these is "yes" I'd say we it might be best to revert
63a7cb130718for now.
I don't think enabling it is a very a smart idea for most consumer devices.
Quoted 7 lines · On Tue, 4 Apr 2023 09:04:03 -0700 Christoph Hellwig <[email protected]> wrote:
Quoted 2 lines
I also heard people saying these discard storms might reduce the life time of some devices - is that true?
Also very much possible. There are various SSDs that treat a discard as a write zeroes and always return zeroes from all discarded blocks. If the discards are smaller than or not aligned to the internal erase (super)blocks, this will actually cause additional writes.
SSDs do not physically erase blocks on discard, that would be very slow.
Instead they nuke corresponding records in the Flash translation layer (FTL) tables, so that the discarded areas point "nowhere" instead of the actual stored blocks. And when facing such pointers on trying to resolve read requests, the controller knows to just return zeroes.
Of course there can be varying behaviors per SSD, e.g. I know of some that return random garbage instead of zeroes, and some which for a puzzling reason prefer to return the byte FF instead. But I think the 1st point above should be universal, pretty certain there are none where a discard/TRIM would take comparable time to "dd if=/dev/zero of=/dev/ssd" (making it unusable in practice).
Signature · 2 lines
With respect,
Roman
Quoted 6 lines · Roman Mamedov
SSDs do not physically erase blocks on discard, that would be very slow.
Instead they nuke corresponding records in the Flash translation layer (FTL) tables, so that the discarded areas point "nowhere" instead of the actual stored blocks. And when facing such pointers on trying to resolve read requests, the controller knows to just return zeroes.
Of course they don't erase blocks on every discard (although if you look long enough you'll probably find a worst case implementation that does this anyway). But you still need to persist your FTL changes, and the zeroing if any was done by the time your get a FLUSH command, because without that you'd return different data when reading a block after a powerfail (i.e. the old data) than before (zeros or a pattern), which is a no-go.
Quoted 3 lines
Of course there can be varying behaviors per SSD, e.g. I know of some that return random garbage instead of zeroes, and some which for a puzzling reason prefer to return the byte FF instead.
All of that is valid behavior per the relevant standards.
Quoted 4 lines
But I think the 1st point above should
be universal, pretty certain there are none where a discard/TRIM would take comparable time to "dd if=/dev/zero of=/dev/ssd" (making it unusable in practice).
This is wishful thinking :) SSDs generall optimize the fast path very heavily, so slow path command even when they should in theory be faster due to the underlying optimizations might not be, as they are processed in software instead of hardware offloads, moved to slower cores, etc.
For discard things have gotten a lot better in the last years, but for many older devices performance can be outright horrible.
For SATA SSDs the fact that classic TRIM isn't a queued command adds insult to injury as it always means draining the queue first and not issuing any I/O until the TRIM command is done. There is a FPDMA version not, but I don't think it ws all that widely implemented before SATA SSDs fell out of favour.
Quoted 32 lines · Christoph Hellwig
Quoted 6 lines · Roman Mamedov
SSDs do not physically erase blocks on discard, that would be very slow.
Instead they nuke corresponding records in the Flash translation layer (FTL) tables, so that the discarded areas point "nowhere" instead of the actual stored blocks. And when facing such pointers on trying to resolve read requests, the controller knows to just return zeroes.
Of course they don't erase blocks on every discard (although if you look long enough you'll probably find a worst case implementation that does this anyway). But you still need to persist your FTL changes, and the zeroing if any was done by the time your get a FLUSH command, because without that you'd return different data when reading a block after a powerfail (i.e. the old data) than before (zeros or a pattern), which is a no-go.
Quoted 3 lines
Of course there can be varying behaviors per SSD, e.g. I know of some that return random garbage instead of zeroes, and some which for a puzzling reason prefer to return the byte FF instead.
All of that is valid behavior per the relevant standards.
Quoted 4 lines
But I think the 1st point above should
be universal, pretty certain there are none where a discard/TRIM would take comparable time to "dd if=/dev/zero of=/dev/ssd" (making it unusable in practice).This is wishful thinking :) SSDs generall optimize the fast path very heavily, so slow path command even when they should in theory be faster due to the underlying optimizations might not be, as they are processed in software instead of hardware offloads, moved to slower cores, etc.
Quoted 8 lines
For discard things have gotten a lot better in the last years, but for many older devices performance can be outright horrible.
For SATA SSDs the fact that classic TRIM isn't a queued command adds insult to injury as it always means draining the queue first and not issuing any I/O until the TRIM command is done. There is a FPDMA version not, but I don't think it ws all that widely implemented before SATA SSDs fell out of favour.
Not to mention that many of the SATA SSDs actually implementing queued trim are buggy. See ATA horkage flag ATA_HORKAGE_NO_NCQ_TRIM and the many consumer SSDs that need that flag.
Quoted 10 lines · Christoph Hellwig
Quoted 9 lines · Linux regression tracking (Thorsten Leemhuis)
Quoted 3 lines
Quoted 3 lines
And that jut NVMe, the still shipping SATA SSDs are another different story. Not helped by the fact that we don't even support ranged discards for them in Linux.
Thx for your comments Christoph. Quick question, just to be sure I understand things properly:
I assume on some of those problematic devices these discard storms will lead to a performance regression?
I'm searching through the various threads, but I don't think I've seen the discard storm quantified?
Boris sent me this:
https://lore.kernel.org/linux-btrfs/ZCxP%[email protected]/T/#m65851e5b8b0caa5320d2b7e322805dd200686f01
Which seems to match the 10 discards per second setting? We should be doing more of a dribble than a storm, so I'd like to understand if this is a separate bug that should be fixed.
Quoted 11 lines
Probably.
Quoted 2 lines
I also heard people saying these discard storms might reduce the life time of some devices - is that true?
Also very much possible. There are various SSDs that treat a discard as a write zeroes and always return zeroes from all discarded blocks. If the discards are smaller than or not aligned to the internal erase (super)blocks, this will actually cause additional writes.
Quoted 5 lines
Quoted 2 lines
If the answer to at least one of these is "yes" I'd say we it might be best to revert
63a7cb130718for now.I don't think enabling it is a very a smart idea for most consumer devices.
It seems like a good time to talk through a variations of discard usage in fb data centers. We run a pretty wide variety of hardware from consumer grade ssds to enterprise ssds, and we've run these on ext4/btrfs/xfs.
(Christoph knows most of this already, so I'm only partially replying to him here)
First, there was synchronous discard. These were pretty dark times because all three of our filesystems would build a batch of synchronous discards and then wait for them during filesystem commit. There were long tail latencies across all of our workloads, and so workload owners would turn off discard and declare victory over terrible latencies.
Of course this predictably ends up with GC on the drives leading to terrible latencies because we weren't discarding anymore, and nightly trims are the obvious answer. Different workloads would gyrate through the variations and the only consistent result was unhappiness.
Some places in the fleet still do this, and it can be a pretty simple tradeoff between the IO impacts of full drive trims vs the latency impact of built up GC vs over-provisioning. It works for consistent workloads, but honestly there aren't many of those.
Along the way both btrfs and xfs have grown variations of async discard.
The XFS one (sorry if I'm out of date here), didn't include any kind of
rate limiting, so if you were bulk deleting a lot of data, XFS would effectively queue up so many discards that it actually saturated the device for a long time, starving reads and writes. If your workload did a constant stream of allocation and deletion, the async discards would just saturate the drive forever.
The workloads that care about latencies on XFS ended up going back to synchronous discards, and they do a slow-rm hack that nibbles away at the ends of files with periodic fsyncs mixed in until the file is zero length. They love this and it makes me cry.
The btrfs async discard feature was meant to address both of these cases. The primary features:
- Get rid of the transaction commit latency
- Enable allocations to steal from discards, reducing discard IO
- Avoid saturating the devices with discards by metering them out
Christoph mentions that modern enterprise drives are much better at discarding, and we see this in production too. But, we still have workloads that switched from XFS to Btrfs because the async discard feature did a better job of reducing drive write-amp and latencies.
So, honestly from my POV the async discard is best suited to consumer devices. Our defaults are probably wrong because no matter what you choose there's a drive out there that makes it look bad. Also, laptops probably don't want the slow dribble.
I know Boris has some ideas on how to make the defaults better, so I'll let him chime in there.
-chris
Quoted 93 lines · Chris Mason
Quoted 10 lines · Christoph Hellwig
Quoted 9 lines · Linux regression tracking (Thorsten Leemhuis)
Quoted 3 lines
Quoted 3 lines
And that jut NVMe, the still shipping SATA SSDs are another different story. Not helped by the fact that we don't even support ranged discards for them in Linux.
Thx for your comments Christoph. Quick question, just to be sure I understand things properly:
I assume on some of those problematic devices these discard storms will lead to a performance regression?
I'm searching through the various threads, but I don't think I've seen the discard storm quantified?
Boris sent me this:
https://lore.kernel.org/linux-btrfs/ZCxP%[email protected]/T/#m65851e5b8b0caa5320d2b7e322805dd200686f01Which seems to match the 10 discards per second setting? We should be doing more of a dribble than a storm, so I'd like to understand if this is a separate bug that should be fixed.
Quoted 11 lines
Probably.
Quoted 2 lines
I also heard people saying these discard storms might reduce the life time of some devices - is that true?
Also very much possible. There are various SSDs that treat a discard as a write zeroes and always return zeroes from all discarded blocks. If the discards are smaller than or not aligned to the internal erase (super)blocks, this will actually cause additional writes.
Quoted 5 lines
Quoted 2 lines
If the answer to at least one of these is "yes" I'd say we it might be best to revert
63a7cb130718for now.I don't think enabling it is a very a smart idea for most consumer devices.
It seems like a good time to talk through a variations of discard usage in fb data centers. We run a pretty wide variety of hardware from consumer grade ssds to enterprise ssds, and we've run these on ext4/btrfs/xfs.
(Christoph knows most of this already, so I'm only partially replying to him here)
First, there was synchronous discard. These were pretty dark times because all three of our filesystems would build a batch of synchronous discards and then wait for them during filesystem commit. There were long tail latencies across all of our workloads, and so workload owners would turn off discard and declare victory over terrible latencies.
Of course this predictably ends up with GC on the drives leading to terrible latencies because we weren't discarding anymore, and nightly trims are the obvious answer. Different workloads would gyrate through the variations and the only consistent result was unhappiness.
Some places in the fleet still do this, and it can be a pretty simple tradeoff between the IO impacts of full drive trims vs the latency impact of built up GC vs over-provisioning. It works for consistent workloads, but honestly there aren't many of those.
Along the way both btrfs and xfs have grown variations of async discard.
The XFS one (sorry if I'm out of date here), didn't include any kind of
rate limiting, so if you were bulk deleting a lot of data, XFS would effectively queue up so many discards that it actually saturated the device for a long time, starving reads and writes. If your workload did a constant stream of allocation and deletion, the async discards would just saturate the drive forever.The workloads that care about latencies on XFS ended up going back to synchronous discards, and they do a slow-rm hack that nibbles away at the ends of files with periodic fsyncs mixed in until the file is zero length. They love this and it makes me cry.
The btrfs async discard feature was meant to address both of these cases. The primary features:
- Get rid of the transaction commit latency
- Enable allocations to steal from discards, reducing discard IO
- Avoid saturating the devices with discards by metering them outChristoph mentions that modern enterprise drives are much better at discarding, and we see this in production too. But, we still have workloads that switched from XFS to Btrfs because the async discard feature did a better job of reducing drive write-amp and latencies.
So, honestly from my POV the async discard is best suited to consumer devices. Our defaults are probably wrong because no matter what you choose there's a drive out there that makes it look bad. Also, laptops probably don't want the slow dribble.
Quoted 5 lines
I know Boris has some ideas on how to make the defaults better, so I'll let him chime in there.
-chris
Our reasonable options, as I see them:
- back to nodiscard, rely on periodic trims from the OS.
- leave low iops_limit, drives stay busy unexpectedly long, conclude that that's OK, and communicate the tuning/measurement options better.
- set a high iops_limit (e.g. 1000) drives will get back to idle faster.
- change an unset iops_limit to mean truly unlimited async discard, set that as the default, and anyone who cares to meter it can set an iops_limit.
The regression here is in drive idle time due to modest discard getting metered out over minutes rather than dealt with relatively quickly. So I would favor the unlimited async discard mode and will send a patch to that effect which we can discuss.
IMO, the periodic discard cron screwing up your box once a week or once a day or whatever is a pretty bad user experience as well, as is randomly hitting bad latencies because you haven't been discarding often enough.
Boris
Quoted 2 lines · Boris Burkov
Our reasonable options, as I see them:
- back to nodiscard, rely on periodic trims from the OS.
We had that before and it's a fallback in case we can't fix it but still the problem would persist for anyone enabling async discard so it's only limiting the impact.
Quoted 2 lines
- leave low
iops_limit, drives stay busy unexpectedly long, conclude that that's OK, and communicate the tuning/measurement options better.
This does not sound user friendly, tuning should be possible but not required by default. We already have enough other things that users need to decide and in this case I don't know if there's enough information to even make a good decision upfront.
Quoted 9 lines
- set a high
iops_limit(e.g. 1000) drives will get back to idle faster.
- change an unsetiops_limitto mean truly unlimited async discard, set that as the default, and anyone who cares to meter it can set aniops_limit.The regression here is in drive idle time due to modest discard getting metered out over minutes rather than dealt with relatively quickly. So I would favor the unlimited async discard mode and will send a patch to that effect which we can discuss.
Can we do options 3 and 4, i.e. set a high iops so that the batch gets processed faster and (4) that there's the manual override to drop the limit completely?
Quoted 21 lines · David Sterba
Quoted 2 lines · Boris Burkov
Our reasonable options, as I see them:
- back to nodiscard, rely on periodic trims from the OS.We had that before and it's a fallback in case we can't fix it but still the problem would persist for anyone enabling async discard so it's only limiting the impact.
Quoted 2 lines
- leave low
iops_limit, drives stay busy unexpectedly long, conclude that that's OK, and communicate the tuning/measurement options better.This does not sound user friendly, tuning should be possible but not required by default. We already have enough other things that users need to decide and in this case I don't know if there's enough information to even make a good decision upfront.
Quoted 5 lines
- set a high
iops_limit(e.g. 1000) drives will get back to idle faster.
- change an unsetiops_limitto mean truly unlimited async discard, set that as the default, and anyone who cares to meter it can set aniops_limit.
Quoted 8 lines
Quoted 4 lines
The regression here is in drive idle time due to modest discard getting metered out over minutes rather than dealt with relatively quickly. So I would favor the unlimited async discard mode and will send a patch to that effect which we can discuss.
Can we do options 3 and 4, i.e. set a high iops so that the batch gets processed faster and (4) that there's the manual override to drop the limit completely?
Yup, I'm on it.
Chris also had a good idea for a "time since commit" check to further limit how long async discard would crank for.
This would look something like "go as fast as I'm allowed for 5s after every transaction". It could lead to a big buildup that requires a periodic trim to clear.
I'm playing with adding that as an additional tunable which would apply if set.
Boris
Quoted 27 lines · Boris Burkov
Quoted 26 lines · David Sterba
Quoted 2 lines · Boris Burkov
Our reasonable options, as I see them:
- back to nodiscard, rely on periodic trims from the OS.We had that before and it's a fallback in case we can't fix it but still the problem would persist for anyone enabling async discard so it's only limiting the impact.
Quoted 2 lines
- leave low
iops_limit, drives stay busy unexpectedly long, conclude that that's OK, and communicate the tuning/measurement options better.This does not sound user friendly, tuning should be possible but not required by default. We already have enough other things that users need to decide and in this case I don't know if there's enough information to even make a good decision upfront.
Quoted 9 lines
- set a high
iops_limit(e.g. 1000) drives will get back to idle faster.
- change an unsetiops_limitto mean truly unlimited async discard, set that as the default, and anyone who cares to meter it can set aniops_limit.The regression here is in drive idle time due to modest discard getting metered out over minutes rather than dealt with relatively quickly. So I would favor the unlimited async discard mode and will send a patch to that effect which we can discuss.
Quoted 6 lines
Quoted 3 lines
Can we do options 3 and 4, i.e. set a high iops so that the batch gets processed faster and (4) that there's the manual override to drop the limit completely?
Yup, I'm on it.
[...]
Thx everyone for looking into this and the fruitful discussion yesterday, much appreciated.
/me will now get back to watching this only from afar and leave things to the experts
Ciao, Thorsten (wearing his 'the Linux kernel's regression tracker' hat) --
Everything you wanna know about Linux kernel regression tracking:
https://linux-regtracking.leemhuis.info/about/#tldr
If I did something stupid, please tell me, as explained on that page.
Quoted 15 lines · Boris Burkov
Quoted 4 lines · Chris Mason
So, honestly from my POV the async discard is best suited to consumer devices. Our defaults are probably wrong because no matter what you choose there's a drive out there that makes it look bad. Also, laptops probably don't want the slow dribble.
Our reasonable options, as I see them:
- back to nodiscard, rely on periodic trims from the OS.
- leave lowiops_limit, drives stay busy unexpectedly long, conclude that that's OK, and communicate the tuning/measurement options better.
- set a highiops_limit(e.g. 1000) drives will get back to idle faster.
- change an unsetiops_limitto mean truly unlimited async discard, set that as the default, and anyone who cares to meter it can set aniops_limit.
Quoted 4 lines
The regression here is in drive idle time due to modest discard getting metered out over minutes rather than dealt with relatively quickly. So I would favor the unlimited async discard mode and will send a patch to that effect which we can discuss.
Will power usage be taken into consideration? I only noticed this regression myself when my laptop started to draw a constant extra ~10W from the constant drive activity, so I imagine other laptop users would also prefer a default which avoids this if possible. If "relatively quickly" means anything more than a few seconds I could see that causing rather significant battery life reductions.
- Michael
Quoted 21 lines · Michael Bromilow
Quoted 15 lines · Boris Burkov
Quoted 4 lines · Chris Mason
So, honestly from my POV the async discard is best suited to consumer devices. Our defaults are probably wrong because no matter what you choose there's a drive out there that makes it look bad. Also, laptops probably don't want the slow dribble.
Our reasonable options, as I see them:
- back to nodiscard, rely on periodic trims from the OS.
- leave lowiops_limit, drives stay busy unexpectedly long, conclude that that's OK, and communicate the tuning/measurement options better.
- set a highiops_limit(e.g. 1000) drives will get back to idle faster.
- change an unsetiops_limitto mean truly unlimited async discard, set that as the default, and anyone who cares to meter it can set aniops_limit.Quoted 4 lines
The regression here is in drive idle time due to modest discard getting metered out over minutes rather than dealt with relatively quickly. So I would favor the unlimited async discard mode and will send a patch to that effect which we can discuss.
Quoted 6 lines
Will power usage be taken into consideration? I only noticed this regression myself when my laptop started to draw a constant extra ~10W from the constant drive activity, so I imagine other laptop users would also prefer a default which avoids this if possible. If "relatively quickly" means anything more than a few seconds I could see that causing rather significant battery life reductions.
This may need to be configured from userspace, e.g. from laptop-mode-tools, I'm not sure if any of the power usage info is available from kernel.
Quoted 29 lines · David Sterba
Quoted 21 lines · Michael Bromilow
Quoted 15 lines · Boris Burkov
Quoted 4 lines · Chris Mason
So, honestly from my POV the async discard is best suited to consumer devices. Our defaults are probably wrong because no matter what you choose there's a drive out there that makes it look bad. Also, laptops probably don't want the slow dribble.
Our reasonable options, as I see them:
- back to nodiscard, rely on periodic trims from the OS.
- leave lowiops_limit, drives stay busy unexpectedly long, conclude that that's OK, and communicate the tuning/measurement options better.
- set a highiops_limit(e.g. 1000) drives will get back to idle faster.
- change an unsetiops_limitto mean truly unlimited async discard, set that as the default, and anyone who cares to meter it can set aniops_limit.Quoted 4 lines
The regression here is in drive idle time due to modest discard getting metered out over minutes rather than dealt with relatively quickly. So I would favor the unlimited async discard mode and will send a patch to that effect which we can discuss.
Quoted 6 lines
Will power usage be taken into consideration? I only noticed this regression myself when my laptop started to draw a constant extra ~10W from the constant drive activity, so I imagine other laptop users would also prefer a default which avoids this if possible. If "relatively quickly" means anything more than a few seconds I could see that causing rather significant battery life reductions.
Quoted 3 lines
This may need to be configured from userspace, e.g. from laptop-mode-tools, I'm not sure if any of the power usage info is available from kernel.
Well, from the point of the regression tracker this looks a bit
different: if a system after a kernel updates draw a constant extra ~10W, it's a regression that needs to be fixed. But in the end it's of course Linus option that matters.
But whatever, Boris afaics is looking for an improved solution that hopefully avoids the extra power consumption and at the same time does the right thing on modern enterprise storage devices, so that the defaults work for the majority of the users. Hopefully this will work out. :-D
Ciao, Thorsten
Quoted 15 lines · On Tue, 4 Apr 2023 14:15:38 -0400 Chris Mason <[email protected]> wrote:
Quoted 10 lines · Christoph Hellwig
Quoted 9 lines · Linux regression tracking (Thorsten Leemhuis)
Quoted 3 lines
Quoted 3 lines
And that jut NVMe, the still shipping SATA SSDs are another different story. Not helped by the fact that we don't even support ranged discards for them in Linux.
Thx for your comments Christoph. Quick question, just to be sure I understand things properly:
I assume on some of those problematic devices these discard storms will lead to a performance regression?
I'm searching through the various threads, but I don't think I've seen the discard storm quantified?
Quoted 6 lines
Boris sent me this:
https://lore.kernel.org/linux-btrfs/ZCxP%[email protected]/T/#m65851e5b8b0caa5320d2b7e322805dd200686f01Which seems to match the 10 discards per second setting? We should be doing more of a dribble than a storm, so I'd like to understand if this is a separate bug that should be fixed.
I called it a storm based on the following LED behaviour:
https://trofi.github.io/posts.data/281-a-signal-from-the-stars/01-shimmer.gif
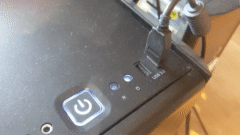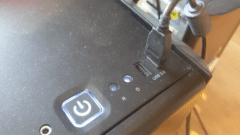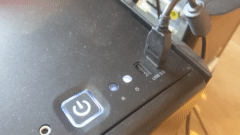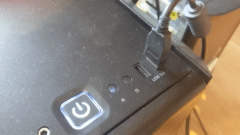
It's not a saturated device (as you can see the flashes on and off). But it's not idle either. "storm" was an exaggeration. Note that it takes linux 3-4 days to go through a backlog of 300GB of deleted files.
Is 3-4 days expected? Or my setup is somehow unusual? Maybe compress=zstd makes things disproportionally problematic?
Quoted 65 lines
Quoted 10 lines
Probably.
Quoted 2 lines
I also heard people saying these discard storms might reduce the life time of some devices - is that true?
Also very much possible. There are various SSDs that treat a discard as a write zeroes and always return zeroes from all discarded blocks. If the discards are smaller than or not aligned to the internal erase (super)blocks, this will actually cause additional writes.
Quoted 5 lines
Quoted 2 lines
If the answer to at least one of these is "yes" I'd say we it might be best to revert
63a7cb130718for now.I don't think enabling it is a very a smart idea for most consumer devices.
It seems like a good time to talk through a variations of discard usage in fb data centers. We run a pretty wide variety of hardware from consumer grade ssds to enterprise ssds, and we've run these on ext4/btrfs/xfs.
(Christoph knows most of this already, so I'm only partially replying to him here)
First, there was synchronous discard. These were pretty dark times because all three of our filesystems would build a batch of synchronous discards and then wait for them during filesystem commit. There were long tail latencies across all of our workloads, and so workload owners would turn off discard and declare victory over terrible latencies.
Of course this predictably ends up with GC on the drives leading to terrible latencies because we weren't discarding anymore, and nightly trims are the obvious answer. Different workloads would gyrate through the variations and the only consistent result was unhappiness.
Some places in the fleet still do this, and it can be a pretty simple tradeoff between the IO impacts of full drive trims vs the latency impact of built up GC vs over-provisioning. It works for consistent workloads, but honestly there aren't many of those.
Along the way both btrfs and xfs have grown variations of async discard.
The XFS one (sorry if I'm out of date here), didn't include any kind of
rate limiting, so if you were bulk deleting a lot of data, XFS would effectively queue up so many discards that it actually saturated the device for a long time, starving reads and writes. If your workload did a constant stream of allocation and deletion, the async discards would just saturate the drive forever.The workloads that care about latencies on XFS ended up going back to synchronous discards, and they do a slow-rm hack that nibbles away at the ends of files with periodic fsyncs mixed in until the file is zero length. They love this and it makes me cry.
The btrfs async discard feature was meant to address both of these cases. The primary features:
- Get rid of the transaction commit latency
- Enable allocations to steal from discards, reducing discard IO
- Avoid saturating the devices with discards by metering them outChristoph mentions that modern enterprise drives are much better at discarding, and we see this in production too. But, we still have workloads that switched from XFS to Btrfs because the async discard feature did a better job of reducing drive write-amp and latencies.
Quoted 7 lines
So, honestly from my POV the async discard is best suited to consumer devices. Our defaults are probably wrong because no matter what you choose there's a drive out there that makes it look bad. Also, laptops probably don't want the slow dribble.
I know Boris has some ideas on how to make the defaults better, so I'll let him chime in there.
That makes sense. Thank you!
Signature · 1 line
Sergei
Quoted 4 lines · Chris Mason
It seems like a good time to talk through a variations of discard usage in fb data centers. We run a pretty wide variety of hardware from consumer grade ssds to enterprise ssds, and we've run these on ext4/btrfs/xfs.
Remember what you guys call consumer grade is the top of the shelve consumer grade SSDs, or in fact low-end enterprise ones that are based on the latest and greatest top shelve SSDs with firmware specifically tweaked for you. That is a whole differnet level from random crappy no-name SSD from 5 years ago.
Quoted 6 lines · Christoph Hellwig
Quoted 4 lines · Chris Mason
It seems like a good time to talk through a variations of discard usage in fb data centers. We run a pretty wide variety of hardware from consumer grade ssds to enterprise ssds, and we've run these on ext4/btrfs/xfs.
Quoted 6 lines
Remember what you guys call consumer grade is the top of the shelve consumer grade SSDs, or in fact low-end enterprise ones that are based on the latest and greatest top shelve SSDs with firmware specifically tweaked for you. That is a whole differnet level from random crappy no-name SSD from 5 years ago.
This is definitely true, our providers are reliable and support the products well. But, you also have to factor in the write cycles, drive lifetimes, and just the constant threat of statistics at scale. Drives might come in off something close to the top shelf, but datacenters are pretty hard on storage.
Going back to the fedora thread, we've definitely had ssds with reliability issues caused by trims, but we haven't had any I can think of where mount -o discard was fundamentally less reliable than periodic full device trimming.
-chris
Quoted 16 lines · Linux regression tracking (Thorsten Leemhuis)
Quoted 9 lines · Sergei Trofimovich
Quoted 6 lines · On Wed, 22 Mar 2023 01:38:42 -0700 Christoph Hellwig <[email protected]> wrote:
Quoted 5 lines · Josef Bacik
We got the defaults based on our testing with our workloads inside of FB. Clearly this isn't representative of a normal desktop usage, but we've also got a lot of workloads so figured if it made the whole fleet happy it would probably be fine everywhere.
Quoted 5 lines
Quoted 5 lines
Quoted 5 lines
That being said this is tunable for a reason, your workload seems to generate a lot of free'd extents and discards. We can probably mess with the async stuff to maybe pause discarding if there's no other activity happening on the device at the moment, but tuning it to let more discards through at a time is also completely valid. Thanks,
Quoted 8 lines
BTW, there is another report about this issue here:
https://bugzilla.redhat.com/show_bug.cgi?id=2182228/me wonders if there is a opensuse report as well, but a quick search didn't find one
And as fun fact or for completeness, the issue even made it to reddit, too:
https://www.reddit.com/r/archlinux/comments/121htxn/btrfs_discard_storm_on_62x_kernel/
Good find, but also:
https://www.reddit.com/r/Fedora/comments/vjfpkv/periodic_trim_freezes_ssd/
So without harder data, there is a bit of bias inherent in cherrypicking negative impressions from the internet.
Quoted 14 lines
Quoted 10 lines
Quoted 10 lines
FYI, discard performance differs a lot between different SSDs. It used to be pretty horrible for most devices early on, and then a certain hyperscaler started requiring decent performance for enterprise drives, so many of them are good now. A lot less so for the typical consumer drive, especially at the lower end of the spectrum.
And that jut NVMe, the still shipping SATA SSDs are another different story. Not helped by the fact that we don't even support ranged discards for them in Linux.
Thx for your comments Christoph. Quick question, just to be sure I understand things properly:
Quoted 12 lines
I assume on some of those problematic devices these discard storms will lead to a performance regression?
I also heard people saying these discard storms might reduce the life time of some devices - is that true?
If the answer to at least one of these is "yes" I'd say we it might be best to revert
63a7cb130718for now.Quoted 3 lines
Josef, what did you use as a signal to detect what value was good enough? Did you crank up the number until discard backlog clears up in a reasonable time?
Josef is OOO, so I'll try to clarify some things around async discard, hopefully it's helpful to anyone wondering how to tune it.
Like you guessed, our tuning basically consists of looking at the discardable_extents/discardable_bytes metric in the fleet and ensuring it looks sane, and that we see an improvement in I/O tail latencies or fix some concrete instances of bad tail latencies. e.g. with iops_limit=10, we see concrete cases of bad latency go away and don't see a steady buildup of discardable_extents.
Quoted 4 lines
Quoted 4 lines
I still don't understand what I should take into account to change the default and whether I should change it at all. Is it fine if the discard backlog takes a week to get through it? (Or a day? An hour? A minute?)
I believe the relevant metrics are:
- number of trims issued/bytes trimmed (you would measure this by tracing and by looking at discard_extent_bytes and discard_bitmap_bytes)
- bytes "wrongly" trimmed. (extents that were reallocated without getting trimmed are exposed in discard_bytes_saved, so if that drops, you are maybe trimming things that you may have not needed to)
- discardable_extents/discardable_bytes (in sysfs; the outstanding work)
- tail latency of file system operations
- disk idle time
By doing periodic trim you tradeoff better bytes_saved and better disk idle time (big trim once a week, vs. "trim all the time" against worse tail latency during the trim itself, and risking trimming too infrequently, leading to worse latency on a drive that needs a trim.
Quoted 6 lines
Quoted 6 lines
Is it fine to send discards as fast as device allows instead of doing 10 IOPS? Does IOPS limit consider a device wearing tradeoff? Then low IOPS makes sense. Or IOPS limit is just a way to reserve most bandwidth to non-discard workloads? Then I would say unlimited IOPS as a default would make more sense for btrfs.
Unfortunately, btrfs currently doesn't have a "fully unlimited" async discard no matter how you tune it. Ignoring kbps_limit, which only serves to increase the delay, iops_limit has an effective range between 1 and 1000. The basic premise of btrfs async discard is to meter out the discards at a steady rate, asynchronously from file system operations, so the effect of the tunables is to set that delay between discard operations. The delay is clamped between 1ms and 1000ms, so iops_limit > 1000 is the same as iops_limit = 1000. iops_limit=0 does not lead to unmetered discards, but rather hits a hardcoded case of metering them out over 6 hours. (no clue why, I don't personally love that...)
Hope that's somewhat helpful,
Boris
Quoted 8 lines
/me would be interested in answers to these questions as well
Ciao, Thorsten (wearing his 'the Linux kernel's regression tracker' hat) --
Everything you wanna know about Linux kernel regression tracking:
https://linux-regtracking.leemhuis.info/about/#tldr
If I did something stupid, please tell me, as explained on that page.
Quoted 108 lines · On Tue, 4 Apr 2023 11:23:12 -0700 Boris Burkov <[email protected]> wrote:
Quoted 16 lines · Linux regression tracking (Thorsten Leemhuis)
Quoted 9 lines · Sergei Trofimovich
Quoted 6 lines · On Wed, 22 Mar 2023 01:38:42 -0700 Christoph Hellwig <[email protected]> wrote:
Quoted 5 lines · Josef Bacik
We got the defaults based on our testing with our workloads inside of FB. Clearly this isn't representative of a normal desktop usage, but we've also got a lot of workloads so figured if it made the whole fleet happy it would probably be fine everywhere.
Quoted 5 lines
Quoted 5 lines
Quoted 5 lines
That being said this is tunable for a reason, your workload seems to generate a lot of free'd extents and discards. We can probably mess with the async stuff to maybe pause discarding if there's no other activity happening on the device at the moment, but tuning it to let more discards through at a time is also completely valid. Thanks,
Quoted 8 lines
BTW, there is another report about this issue here:
https://bugzilla.redhat.com/show_bug.cgi?id=2182228/me wonders if there is a opensuse report as well, but a quick search didn't find one
And as fun fact or for completeness, the issue even made it to reddit, too:
https://www.reddit.com/r/archlinux/comments/121htxn/btrfs_discard_storm_on_62x_kernel/Good find, but also:
https://www.reddit.com/r/Fedora/comments/vjfpkv/periodic_trim_freezes_ssd/
So without harder data, there is a bit of bias inherent in cherrypicking negative impressions from the internet.Quoted 14 lines
Quoted 10 lines
Quoted 10 lines
FYI, discard performance differs a lot between different SSDs. It used to be pretty horrible for most devices early on, and then a certain hyperscaler started requiring decent performance for enterprise drives, so many of them are good now. A lot less so for the typical consumer drive, especially at the lower end of the spectrum.
And that jut NVMe, the still shipping SATA SSDs are another different story. Not helped by the fact that we don't even support ranged discards for them in Linux.
Thx for your comments Christoph. Quick question, just to be sure I understand things properly:
Quoted 12 lines
I assume on some of those problematic devices these discard storms will lead to a performance regression?
I also heard people saying these discard storms might reduce the life time of some devices - is that true?
If the answer to at least one of these is "yes" I'd say we it might be best to revert
63a7cb130718for now.Quoted 3 lines
Josef, what did you use as a signal to detect what value was good enough? Did you crank up the number until discard backlog clears up in a reasonable time?
Josef is OOO, so I'll try to clarify some things around async discard, hopefully it's helpful to anyone wondering how to tune it.
Like you guessed, our tuning basically consists of looking at the discardable_extents/discardable_bytes metric in the fleet and ensuring it looks sane, and that we see an improvement in I/O tail latencies or fix some concrete instances of bad tail latencies. e.g. with iops_limit=10, we see concrete cases of bad latency go away and don't see a steady buildup of
discardable_extents.Quoted 4 lines
Quoted 4 lines
I still don't understand what I should take into account to change the default and whether I should change it at all. Is it fine if the discard backlog takes a week to get through it? (Or a day? An hour? A minute?)
I believe the relevant metrics are:
- number of trims issued/bytes trimmed (you would measure this by tracing and by looking at
discard_extent_bytesanddiscard_bitmap_bytes)
- bytes "wrongly" trimmed. (extents that were reallocated without getting trimmed are exposed indiscard_bytes_saved, so if that drops, you are maybe trimming things that you may have not needed to)
- discardable_extents/discardable_bytes (in sysfs; the outstanding work)
- tail latency of file system operations
- disk idle timeBy doing periodic trim you tradeoff better
bytes_savedand better disk idle time (big trim once a week, vs. "trim all the time" against worse tail latency during the trim itself, and risking trimming too infrequently, leading to worse latency on a drive that needs a trim.Quoted 6 lines
Quoted 6 lines
Is it fine to send discards as fast as device allows instead of doing 10 IOPS? Does IOPS limit consider a device wearing tradeoff? Then low IOPS makes sense. Or IOPS limit is just a way to reserve most bandwidth to non-discard workloads? Then I would say unlimited IOPS as a default would make more sense for btrfs.
Unfortunately, btrfs currently doesn't have a "fully unlimited" async discard no matter how you tune it. Ignoring
kbps_limit, which only serves to increase the delay,iops_limithas an effective range between 1 and 1000. The basic premise of btrfs async discard is to meter out the discards at a steady rate, asynchronously from file system operations, so the effect of the tunables is to set that delay between discard operations. The delay is clamped between 1ms and 1000ms, soiops_limit> 1000 is the same asiops_limit= 1000. iops_limit=0 does not lead to unmetered discards, but rather hits a hardcoded case of metering them out over 6 hours. (no clue why, I don't personally love that...)
Quoted 1 line
Hope that's somewhat helpful,
Thank you, Boris! That is very helpful. discard_bytes_saved is a good (and not very obvious to understand!) signal.
Quoted 10 lines
Boris
Quoted 8 lines
/me would be interested in answers to these questions as well
Ciao, Thorsten (wearing his 'the Linux kernel's regression tracker' hat) --
Everything you wanna know about Linux kernel regression tracking:
https://linux-regtracking.leemhuis.info/about/#tldr
If I did something stupid, please tell me, as explained on that page.
Signature · 1 line
Sergei