net: ovs: fix return type of ndo_start_xmit function
Subsystems (41)
Sasha Levin
maintainerPATCH 3/209 ARM: dts: dra7: Enable workaround for errata i870 in PCIe host mode
In reply to Sasha LevinFrom: Vignesh R <[email protected]>
[ Upstream commit b830526f304764753fcb8b4a563a94080e982a6c ]
Add ti,syscon-unaligned-access property to PCIe RC nodes to set appropriate bits in CTRL_CORE_SMA_SW_7 register to enable workaround for errata i870.
---
 arch/arm/boot/dts/dra7.dtsi | 2 ++
 1 file changed, 2 insertions(+)
arch/arm/boot/dts/dra7.dtsi +2 -0
@@ -336,6 +336,7 @@ <0 0 0 2 &pcie1_intc 2>, <0 0 0 3 &pcie1_intc 3>, <0 0 0 4 &pcie1_intc 4>; + ti,syscon-unaligned-access = <&scm_conf1 0x14 1>; status = "disabled"; pcie1_intc: interrupt-controller { interrupt-controller;
@@ -387,6 +388,7 @@
 						<0 0 0 2 &pcie2_intc 2>,
 						<0 0 0 3 &pcie2_intc 3>,
 						<0 0 0 4 &pcie2_intc 4>;
+				ti,syscon-unaligned-access = <&scm_conf1 0x14 2>;
 				pcie2_intc: interrupt-controller {
 					interrupt-controller;
 					#address-cells = <0>;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 4/209 ARM: dts: omap5: enable OTG role for DWC3 controller
In reply to Sasha LevinFrom: "H. Nikolaus Schaller" <[email protected]>
[ Upstream commit 656c1a65ab555ee5c7cd0d6aee8ab82ca3c1795f ]
Since SMPS10 and OTG cable detection extcon are described here, and work to enable OTG power when an OTG cable is plugged in, we can define OTG mode in the controller (which is disabled by default in omap5.dtsi).
Tested on OMAP5EVM and Pyra.
---
 arch/arm/boot/dts/omap5-board-common.dtsi | 4 ++++
 1 file changed, 4 insertions(+)
arch/arm/boot/dts/omap5-board-common.dtsi +4 -0
@@ -703,6 +703,10 @@ vbus-supply = <&smps10_out1_reg>; }; +&dwc3 { + dr_mode = "otg"; +}; + &mcspi1 { };
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 42/209 KVM: PPC: Inform the userspace about TCE update failures
In reply to Sasha LevinFrom: Alexey Kardashevskiy <[email protected]>
[ Upstream commit f7960e299f13f069d6f3d4e157d91bfca2669677 ]
We return H_TOO_HARD from TCE update handlers when we think that the next handler (realmode -> virtual mode -> user mode) has a chance to handle the request; H_HARDWARE/H_CLOSED otherwise.
This changes the handlers to return H_TOO_HARD on every error giving the userspace an opportunity to handle any request or at least log them all.
---
 arch/powerpc/kvm/book3s_64_vio.c    | 8 ++++----
 arch/powerpc/kvm/book3s_64_vio_hv.c | 6 +++---
 2 files changed, 7 insertions(+), 7 deletions(-)
arch/powerpc/kvm/book3s_64_vio.c +4 -4
@@ -401,7 +401,7 @@ static long kvmppc_tce_iommu_do_unmap(struct kvm *kvm,long ret;if (WARN_ON_ONCE (iommu_tce_xchg (tbl, entry, &hpa, &dir))) -return H_HARDWARE ; +return H_TOO_HARD ;if (dir =DMA_NONE )return H_SUCCESS ;
@@ -449,15 +449,15 @@ long kvmppc_tce_iommu_do_map(struct kvm *kvm, struct iommu_table *tbl,return H_TOO_HARD ;if (WARN_ON_ONCE (mm_iommu_ua_to_hpa (mem, ua, tbl->it_page_shift, &hpa))) -return H_HARDWARE ; +return H_TOO_HARD ;if (mm_iommu_mapped_inc (mem)) -return H_CLOSED ; +return H_TOO_HARD ; ret =iommu_tce_xchg (tbl, entry, &hpa, &dir);if (WARN_ON_ONCE (ret)) {mm_iommu_mapped_dec (mem); -return H_HARDWARE ; +return H_TOO_HARD ; }if (dir !=DMA_NONE )
arch/powerpc/kvm/book3s_64_vio_hv.c +3 -3
@@ -300,10 +300,10 @@ static long kvmppc_rm_tce_iommu_do_map(struct kvm *kvm, struct iommu_table *tbl,if (WARN_ON_ONCE_RM (mm_iommu_ua_to_hpa_rm (mem, ua, tbl->it_page_shift, &hpa))) -return H_HARDWARE ; +return H_TOO_HARD ;if (WARN_ON_ONCE_RM (mm_iommu_mapped_inc (mem))) -return H_CLOSED ; +return H_TOO_HARD ; ret =iommu_tce_xchg_rm (kvm->mm, tbl, entry, &hpa, &dir);if (ret) {
@@ -501,7 +501,7 @@ long kvmppc_rm_h_put_tce_indirect(struct kvm_vcpu *vcpu, rmap = (void *)vmalloc_to_phys (rmap);if (WARN_ON_ONCE_RM (!rmap)) -return H_HARDWARE ; +return H_TOO_HARD ;/* * Synchronize with the MMU notifier callbacks in
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 67/209 md: allow metadata updates while suspending an array - fix
In reply to Sasha LevinFrom: NeilBrown <[email protected]>
[ Upstream commit 059421e041eb461fb2b3e81c9adaec18ef03ca3c ]
Commit 35bfc52187f6 ("md: allow metadata update while suspending.") added support for allowing md_check_recovery() to still perform metadata updates while the array is entering the 'suspended' state. This is needed to allow the processes of entering the state to complete.
Unfortunately, the patch doesn't really work. The test for "mddev->suspended" at the start of md_check_recovery() means that the function doesn't try to do anything at all while entering suspend.
This patch moves the code of updating the metadata while suspending to *before* the test on mddev->suspended.
---
 drivers/md/md.c | 22 ++++++++++++----------
 1 file changed, 12 insertions(+), 10 deletions(-)
drivers/md/md.c +12 -10
@@ -8778,6 +8778,18 @@ static void md_start_sync(struct work_struct *ws)*/ void md_check_recovery (struct mddev *mddev) { +if (test_bit (MD_ALLOW_SB_UPDATE , &mddev->flags) && mddev->sb_flags) { +/* Write superblock - thread that called mddev_suspend() +* holds reconfig_mutex for us. +*/ +set_bit (MD_UPDATING_SB , &mddev->flags); +smp_mb__after_atomic (); +if (test_bit (MD_ALLOW_SB_UPDATE , &mddev->flags)) +md_update_sb (mddev,0 ); +clear_bit_unlock (MD_UPDATING_SB , &mddev->flags); +wake_up (&mddev->sb_wait); + } +if (mddev->suspended)return ;
@@ -8938,16 +8950,6 @@ void md_check_recovery(struct mddev *mddev) unlock:wake_up (&mddev->sb_wait);mddev_unlock (mddev); - }else if (test_bit (MD_ALLOW_SB_UPDATE , &mddev->flags) && mddev->sb_flags) { -/* Write superblock - thread that called mddev_suspend() -* holds reconfig_mutex for us. -*/ -set_bit (MD_UPDATING_SB , &mddev->flags); -smp_mb__after_atomic (); -if (test_bit (MD_ALLOW_SB_UPDATE , &mddev->flags)) -md_update_sb (mddev,0 ); -clear_bit_unlock (MD_UPDATING_SB , &mddev->flags); -wake_up (&mddev->sb_wait); } }EXPORT_SYMBOL (md_check_recovery);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 79/209 msm/gpu/a6xx: Force of_dma_configure to setup DMA for GMU
In reply to Sasha LevinFrom: Jordan Crouse <[email protected]>
[ Upstream commit 32aa27e15c28d3898ed6f9b3c98f95f34a81eab2 ]
The point of the 'force_dma' parameter for of_dma_configure is to force the device to be set up even if DMA capability is not described by the firmware which is exactly the use case
we have for GMU - we need SMMU to get set up but we have no
other dma capabilities since memory is managed by the GPU driver. Currently we pass false so of_dma_configure() fails and subsequently GMU and GPU probe does as well.
---
 drivers/gpu/drm/msm/adreno/a6xx_gmu.c | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/gpu/drm/msm/adreno/a6xx_gmu.c +1 -1
@@ -1140,7 +1140,7 @@ int a6xx_gmu_probe(struct a6xx_gpu *a6xx_gpu, struct device_node *node) gmu->dev = &pdev->dev; -of_dma_configure (gmu->dev, node, false); +of_dma_configure (gmu->dev, node, true);/* Fow now, don't do anything fancy until we get our feet under us */ gmu->idle_level =GMU_IDLE_STATE_ACTIVE ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 95/209 KVM: PPC: Book3S PR: Exiting split hack mode needs to fixup both PC and LR
In reply to Sasha LevinFrom: Cameron Kaiser <[email protected]>
[ Upstream commit 1006284c5e411872333967b1970c2ca46a9e225f ]
When an OS (currently only classic Mac OS) is running in KVM-PR and makes a linked jump from code with split hack addressing enabled into code that does not, LR is not correctly updated and reflects the previously munged PC.
To fix this, this patch undoes the address munge when exiting split hack mode so that code relying on LR being a proper address will now execute. This does not affect OS X or other operating systems running on KVM-PR.
---
 arch/powerpc/kvm/book3s.c | 3 +++
 1 file changed, 3 insertions(+)
arch/powerpc/kvm/book3s.c +3 -0
@@ -78,8 +78,11 @@ void kvmppc_unfixup_split_real(struct kvm_vcpu *vcpu) {if (vcpu->arch.hflags &BOOK3S_HFLAG_SPLIT_HACK ) {ulong pc =kvmppc_get_pc (vcpu); +ulong lr =kvmppc_get_lr (vcpu);if ((pc &SPLIT_HACK_MASK ) =SPLIT_HACK_OFFS )kvmppc_set_pc (vcpu, pc & ~SPLIT_HACK_MASK ); +if ((lr &SPLIT_HACK_MASK ) =SPLIT_HACK_OFFS ) +kvmppc_set_lr (vcpu, lr & ~SPLIT_HACK_MASK ); vcpu->arch.hflags &= ~BOOK3S_HFLAG_SPLIT_HACK ; } }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 109/209 i2c: brcmstb: Allow enabling the driver on DSL SoCs
In reply to Sasha LevinFrom: Florian Fainelli <[email protected]>
[ Upstream commit e1eba2ea54a2de0e4c58d87270d25706bb77b844 ]
ARCH_BCM_63XX which is used by ARM-based DSL SoCs from Broadcom uses the same controller, make it possible to select the STB driver and update the Kconfig and help text a bit.
---
 drivers/i2c/busses/Kconfig | 7 ++++---
 1 file changed, 4 insertions(+), 3 deletions(-)
drivers/i2c/busses/Kconfig +4 -3
@@ -433,12 +433,13 @@ config I2C_BCM_KONA If you do not need KONA I2C interface, say N. config I2C_BRCMSTB - tristate "BRCM Settop I2C controller" - depends on ARCH_BRCMSTB || BMIPS_GENERIC || COMPILE_TEST + tristate "BRCM Settop/DSL I2C controller" + depends on ARCH_BRCMSTB || BMIPS_GENERIC || ARCH_BCM_63XX || \ + COMPILE_TEST default y help If you say yes to this option, support will be included for the - I2C interface on the Broadcom Settop SoCs. + I2C interface on the Broadcom Settop/DSL SoCs. If you do not need I2C interface, say N.
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 116/209 i2c: omap: use core to detect 'no zero length' quirk
In reply to Sasha LevinFrom: Wolfram Sang <[email protected]>
[ Upstream commit f37b2bb6ac3e6ebf855d9d4f05cc6932a8e5b463 ]
And don't reimplement in the driver.
---
 drivers/i2c/busses/i2c-omap.c | 8 +++++---
 1 file changed, 5 insertions(+), 3 deletions(-)
drivers/i2c/busses/i2c-omap.c +5 -3
@@ -661,9 +661,6 @@ static int omap_i2c_xfer_msg(struct i2c_adapter *adap,dev_dbg (omap->dev,"addr: 0x%04x, len: %d, flags: 0x%x, stop: %d\n" , msg->addr, msg->len, msg->flags, stop); -if (msg->len ==0 ) -return -EINVAL ; - omap->receiver = !!(msg->flags &I2C_M_RD );omap_i2c_resize_fifo (omap, msg->len, omap->receiver);
@@ -1179,6 +1176,10 @@ static const struct i2c_algorithm omap_i2c_algo = { .functionality = omap_i2c_func, }; +static const struct i2c_adapter_quirks omap_i2c_quirks = { + .flags =I2C_AQ_NO_ZERO_LEN , +}; +#ifdef CONFIG_OF static struct omap_i2c_bus_platform_data omap2420_pdata = { .rev = OMAP_I2C_IP_VERSION_1,
@@ -1453,6 +1454,7 @@ omap_i2c_probe(struct platform_device *pdev) adap->class =I2C_CLASS_DEPRECATED ;strlcpy (adap->name,"OMAP I2C adapter" ,sizeof (adap->name)); adap->algo = &omap_i2c_algo; + adap->quirks = &omap_i2c_quirks; adap->dev.parent = &pdev->dev; adap->dev.of_node = pdev->dev.of_node; adap->bus_recovery_info = &omap_i2c_bus_recovery_info;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 117/209 i2c: qup: use core to detect 'no zero length' quirk
In reply to Sasha LevinFrom: Wolfram Sang <[email protected]>
[ Upstream commit de82bb431855580ad659bfed3e858bd9dd12efd0 ]
And don't reimplement in the driver.
---
 drivers/i2c/busses/i2c-qup.c | 14 ++++++--------
 1 file changed, 6 insertions(+), 8 deletions(-)
drivers/i2c/busses/i2c-qup.c +6 -8
@@ -1088,11 +1088,6 @@ static int qup_i2c_xfer(struct i2c_adapter *adap,writel (I2C_MINI_CORE |I2C_N_VAL , qup->base +QUP_CONFIG );for (idx =0 ; idx < num; idx++) { -if (msgs[idx].len ==0 ) { - ret = -EINVAL ; - goto out; - } -if (qup_i2c_poll_state_i2c_master (qup)) { ret = -EIO ; goto out;
@@ -1520,9 +1515,6 @@ qup_i2c_determine_mode_v2(struct qup_i2c_dev *qup,/* All i2c_msgs should be transferred using either dma or cpu */ for (idx =0 ; idx < num; idx++) { -if (msgs[idx].len ==0 ) -return -EINVAL ; -if (msgs[idx].flags &I2C_M_RD ) max_rx_len = max_t(unsigned int, max_rx_len, msgs[idx].len);
@@ -1636,9 +1628,14 @@ static const struct i2c_algorithm qup_i2c_algo_v2 = {* which limits the possible read to 256 (QUP_READ_LIMIT) bytes. */ static const struct i2c_adapter_quirks qup_i2c_quirks = { + .flags =I2C_AQ_NO_ZERO_LEN , .max_read_len =QUP_READ_LIMIT , }; +static const struct i2c_adapter_quirks qup_i2c_quirks_v2 = { + .flags =I2C_AQ_NO_ZERO_LEN , +}; +static void qup_i2c_enable_clocks (struct qup_i2c_dev *qup) {clk_prepare_enable (qup->clk);
@@ -1701,6 +1698,7 @@ static int qup_i2c_probe(struct platform_device *pdev) is_qup_v1 = true; }else { qup->adap.algo = &qup_i2c_algo_v2; + qup->adap.quirks = &qup_i2c_quirks_v2; is_qup_v1 = false;if (acpi_match_device (qup_i2c_acpi_match, qup->dev)) goto nodma;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 118/209 i2c: tegra: use core to detect 'no zero length' quirk
In reply to Sasha LevinFrom: Wolfram Sang <[email protected]>
[ Upstream commit c96c0f2683804b710531e7b754dcd02b5ded6d4a ]
And don't reimplement in the driver.
---
 drivers/i2c/busses/i2c-tegra.c | 4 +---
 1 file changed, 1 insertion(+), 3 deletions(-)
drivers/i2c/busses/i2c-tegra.c +1 -3
@@ -684,9 +684,6 @@ static int tegra_i2c_xfer_msg(struct tegra_i2c_dev *i2c_dev,tegra_i2c_flush_fifos (i2c_dev); -if (msg->len ==0 ) -return -EINVAL ; - i2c_dev->msg_buf = msg->buf; i2c_dev->msg_buf_remaining = msg->len; i2c_dev->msg_err =I2C_ERR_NONE ;
@@ -831,6 +828,7 @@ static const struct i2c_algorithm tegra_i2c_algo = {/* payload size is only 12 bit */ static const struct i2c_adapter_quirks tegra_i2c_quirks = { + .flags =I2C_AQ_NO_ZERO_LEN , .max_read_len =4096 , .max_write_len =4096 -12 , };
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 119/209 i2c: zx2967: use core to detect 'no zero length' quirk
In reply to Sasha LevinFrom: Wolfram Sang <[email protected]>
[ Upstream commit e2115ace4196bcd2126446fb874bcfc90cba79be ]
And don't reimplement in the driver.
---
 drivers/i2c/busses/i2c-zx2967.c | 8 +++++---
 1 file changed, 5 insertions(+), 3 deletions(-)
drivers/i2c/busses/i2c-zx2967.c +5 -3
@@ -281,9 +281,6 @@ static int zx2967_i2c_xfer_msg(struct zx2967_i2c *i2c,int ret;int i; -if (msg->len ==0 ) -return -EINVAL ; -zx2967_i2c_flush_fifos (i2c); i2c->cur_trans = msg->buf;
@@ -498,6 +495,10 @@ static const struct i2c_algorithm zx2967_i2c_algo = { .functionality = zx2967_i2c_func, }; +static const struct i2c_adapter_quirks zx2967_i2c_quirks = { + .flags =I2C_AQ_NO_ZERO_LEN , +}; +static const struct of_device_id zx2967_i2c_of_match[] = { { .compatible ="zte,zx296718-i2c" , }, { },
@@ -568,6 +569,7 @@ static int zx2967_i2c_probe(struct platform_device *pdev)strlcpy (i2c->adap.name,"zx2967 i2c adapter" ,sizeof (i2c->adap.name)); i2c->adap.algo = &zx2967_i2c_algo; + i2c->adap.quirks = &zx2967_i2c_quirks; i2c->adap.nr = pdev->id; i2c->adap.dev.parent = &pdev->dev; i2c->adap.dev.of_node = pdev->dev.of_node;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 121/209 Input: silead - try firmware reload after unsuccessful resume
In reply to Sasha LevinFrom: Julian Sax <[email protected]>
[ Upstream commit dde27443211062e841806feaf690674b7c3a599f ]
A certain silead controller (Chip ID: 0x56810000) loses its firmware after suspend, causing the resume to fail. This patch tries to load the firmware, should a resume error occur and retries the resuming.
---
 drivers/input/touchscreen/silead.c | 13 +++++++++++++
 1 file changed, 13 insertions(+)
drivers/input/touchscreen/silead.c +13 -0
@@ -558,20 +558,33 @@ static int __maybe_unused silead_ts_suspend(struct device *dev)static int __maybe_unused silead_ts_resume (struct device *dev) {struct i2c_client *client =to_i2c_client (dev); +bool second_try = false;int error, status;silead_ts_set_power (client,SILEAD_POWER_ON ); + retry: error =silead_ts_reset (client);if (error)return error; +if (second_try) { + error =silead_ts_load_fw (client); +if (error) +return error; + } + error =silead_ts_startup (client);if (error)return error; status =silead_ts_get_status (client);if (status !=SILEAD_STATUS_OK ) { +if (!second_try) { + second_try = true; +dev_dbg (dev,"Reloading firmware after unsuccessful resume\n" ); + goto retry; + }dev_err (dev,"Resume error, status: 0x%02x\n" , status);return -ENODEV ; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 137/209 mmc: renesas_sdhi_internal_dmac: Whitelist r8a774a1
In reply to Sasha LevinFrom: Fabrizio Castro <[email protected]>
[ Upstream commit 2e1501a8bdd49eaa0e967c0ad00e9dcd68d0b30f ]
We need r8a774a1 to be whitelisted for SDHI to work on the RZ/G2M, but we don't care about the revision of the SoC, so just whitelist the generic part number.
---
 drivers/mmc/host/renesas_sdhi_internal_dmac.c | 1 +
 1 file changed, 1 insertion(+)
drivers/mmc/host/renesas_sdhi_internal_dmac.c +1 -0
@@ -298,6 +298,7 @@ static const struct soc_device_attribute gen3_soc_whitelist[] = { { .soc_id = "r8a7796", .revision = "ES1.0", .data = (void *)BIT(SDHI_INTERNAL_DMAC_ONE_RX_ONLY) }, /* generic ones */ + { .soc_id = "r8a774a1" }, { .soc_id = "r8a7795" }, { .soc_id = "r8a7796" }, { .soc_id = "r8a77965" },
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 138/209 mmc: tmio: Fix SCC error detection
In reply to Sasha LevinFrom: Masaharu Hayakawa <[email protected]>
[ Upstream commit b85fb0a1c8aeaaa40d08945d51a6656b512173f0 ]
SDR104, HS200 and HS400 need to check for SCC error. If SCC error is detected, retuning is necessary.
---
 drivers/mmc/host/tmio_mmc_core.c | 4 ++--
 1 file changed, 2 insertions(+), 2 deletions(-)
drivers/mmc/host/tmio_mmc_core.c +2 -2
@@ -926,8 +926,8 @@ static void tmio_mmc_finish_request(struct tmio_mmc_host *host)if (mrq->cmd->error || (mrq->data && mrq->data->error))tmio_mmc_abort_dma (host); -if (host->check_scc_error) - host->check_scc_error (host); +if (host->check_scc_error && host->check_scc_error (host)) + mrq->cmd->error = -EILSEQ ;/* If SET_BLOCK_COUNT, continue with main command */ if (host->mrq && !mrq->cmd->error) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 139/209 mmc: renesas_sdhi_internal_dmac: set scatter/gather max segment size
In reply to Sasha LevinFrom: Niklas Söderlund <[email protected]>
[ Upstream commit 54541815b43f4e49c82628bf28bbb31d86d2f58a ]
Fix warning when running with CONFIG_DMA_API_DEBUG_SG=y by allocating a device_dma_parameters structure and filling in the max segment size. The size used is the result of a discussion with Renesas hardware engineers and unfortunately not found in the datasheet.
renesas_sdhi_internal_dmac ee140000.sd: DMA-API: mapping sg segment longer than device claims to support [len=126976] [max=65536]
[wsa: simplified some logic after validating intended dma_parms life cycle
and added comment]
---
 drivers/mmc/host/renesas_sdhi_internal_dmac.c | 8 ++++++++
 1 file changed, 8 insertions(+)
drivers/mmc/host/renesas_sdhi_internal_dmac.c +8 -0
@@ -310,12 +310,20 @@ static const struct soc_device_attribute gen3_soc_whitelist[] = {static int renesas_sdhi_internal_dmac_probe (struct platform_device *pdev) {const struct soc_device_attribute *soc =soc_device_match (gen3_soc_whitelist); +struct device *dev = &pdev->dev;if (!soc)return -ENODEV ; global_flags |= (unsigned long )soc->data; + dev->dma_parms =devm_kzalloc (dev,sizeof (*dev->dma_parms),GFP_KERNEL ); +if (!dev->dma_parms) +return -ENOMEM ; + +/* value is max of SD_SECCNT. Confirmed by HW engineers */ +dma_set_max_seg_size (dev,0xffffffff ); +return renesas_sdhi_probe (pdev, &renesas_sdhi_internal_dmac_dma_ops); }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 140/209 atmel_lcdfb: support native-mode display-timings
In reply to Sasha LevinFrom: Sam Ravnborg <[email protected]>
[ Upstream commit 60e5e48dba72c6b59a7a9c7686ba320766913368 ]
When a device tree set a display-timing using native-mode then according to the bindings doc this should:
native-mode:
The native mode for the display, in case multiple modes are provided.
When omitted, assume the first node is the native.
The atmel_lcdfb used the last timing subnode and did not respect the timing mode specified with native-mode.
Introduce use of of_get_videomode() which allowed
a nice simplification of the code while also
added support for native-mode.
As a nice side-effect this fixes a memory leak where the data used for timings and the display_np was not freed.
---
 drivers/video/fbdev/atmel_lcdfb.c | 43 +++++++------------------------
 1 file changed, 9 insertions(+), 34 deletions(-)
drivers/video/fbdev/atmel_lcdfb.c +9 -34
@@ -22,6 +22,7 @@#include <linux/module.h> #include <linux/of.h> #include <linux/of_device.h> +#include <video/of_videomode.h> #include <video/of_display_timing.h> #include <linux/regulator/consumer.h> #include <video/videomode.h>
@@ -1028,11 +1029,11 @@ static int atmel_lcdfb_of_init(struct atmel_lcdfb_info *sinfo)struct device *dev = &sinfo->pdev->dev;struct device_node *np =dev->of_node;struct device_node *display_np; -struct device_node *timings_np; -struct display_timings *timings;struct atmel_lcdfb_power_ctrl_gpio *og;bool is_gpio_power = false; +struct fb_videomode fb_vm;struct gpio_desc *gpiod; +struct videomode vm;int ret = -ENOENT ;int i;
@@ -1105,44 +1106,18 @@ static int atmel_lcdfb_of_init(struct atmel_lcdfb_info *sinfo) pdata->lcdcon_is_backlight =of_property_read_bool (display_np,"atmel,lcdcon-backlight" ); pdata->lcdcon_pol_negative =of_property_read_bool (display_np,"atmel,lcdcon-backlight-inverted" ); - timings =of_get_display_timings (display_np); -if (!timings) { -dev_err (dev,"failed to get display timings\n" ); - ret = -EINVAL ; + ret =of_get_videomode (display_np, &vm,OF_USE_NATIVE_MODE ); +if (ret) { +dev_err (dev,"failed to get videomode from DT\n" ); goto put_display_node; } - timings_np =of_get_child_by_name (display_np,"display-timings" ); -if (!timings_np) { -dev_err (dev,"failed to find display-timings node\n" ); - ret = -ENODEV ; + ret =fb_videomode_from_videomode (&vm, &fb_vm); +if (ret <0 ) goto put_display_node; - } -for (i =0 ; i <of_get_child_count (timings_np); i++) { -struct videomode vm; -struct fb_videomode fb_vm; - - ret =videomode_from_timings (timings, &vm, i); -if (ret <0 ) - goto put_timings_node; - ret =fb_videomode_from_videomode (&vm, &fb_vm); -if (ret <0 ) - goto put_timings_node; - -fb_add_videomode (&fb_vm, &info->modelist); - } - -/* -* FIXME: Make sure we are not referencing any fields in display_np -* and timings_np and drop our references to them before returning to -* avoid leaking the nodes on probe deferral and driver unbind. -*/ - -return 0 ; +fb_add_videomode (&fb_vm, &info->modelist); -put_timings_node: -of_node_put (timings_np); put_display_node:of_node_put (display_np);return ret;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 141/209 fbdev: sbuslib: use checked version of put_user()
In reply to Sasha LevinFrom: Dan Carpenter <[email protected]>
[ Upstream commit d8bad911e5e55e228d59c0606ff7e6b8131ca7bf ]
I'm not sure why the code assumes that only the first put_user() needs an access_ok() check. I have made all the put_user() and get_user() calls checked.
---
 drivers/video/fbdev/sbuslib.c | 26 +++++++++++++-------------
 1 file changed, 13 insertions(+), 13 deletions(-)
drivers/video/fbdev/sbuslib.c +13 -13
@@ -106,11 +106,11 @@ int sbusfb_ioctl_helper(unsigned long cmd, unsigned long arg,struct fbtype __user *f = (struct fbtype __user *) arg;if (put_user (type, &f->fb_type) || -__put_user (info->var.yres, &f->fb_height) || -__put_user (info->var.xres, &f->fb_width) || -__put_user (fb_depth, &f->fb_depth) || -__put_user (0 , &f->fb_cmsize) || -__put_user (fb_size, &f->fb_cmsize)) +put_user (info->var.yres, &f->fb_height) || +put_user (info->var.xres, &f->fb_width) || +put_user (fb_depth, &f->fb_depth) || +put_user (0 , &f->fb_cmsize) || +put_user (fb_size, &f->fb_cmsize))return -EFAULT ;return 0 ; }
@@ -125,10 +125,10 @@ int sbusfb_ioctl_helper(unsigned long cmd, unsigned long arg,unsigned int index, count, i;if (get_user (index, &c->index) || -__get_user (count, &c->count) || -__get_user (ured, &c->red) || -__get_user (ugreen, &c->green) || -__get_user (ublue, &c->blue)) +get_user (count, &c->count) || +get_user (ured, &c->red) || +get_user (ugreen, &c->green) || +get_user (ublue, &c->blue))return -EFAULT ; cmap.len =1 ;
@@ -165,10 +165,10 @@ int sbusfb_ioctl_helper(unsigned long cmd, unsigned long arg,u8 red, green, blue;if (get_user (index, &c->index) || -__get_user (count, &c->count) || -__get_user (ured, &c->red) || -__get_user (ugreen, &c->green) || -__get_user (ublue, &c->blue)) +get_user (count, &c->count) || +get_user (ured, &c->red) || +get_user (ugreen, &c->green) || +get_user (ublue, &c->blue))return -EFAULT ;if (index + count > cmap->len)
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 142/209 fbdev: sbuslib: integer overflow in sbusfb_ioctl_helper()
In reply to Sasha LevinFrom: Dan Carpenter <[email protected]>
[ Upstream commit e5017716adb8aa5c01c52386c1b7470101ffe9c5 ]
The "index + count" addition can overflow. Both come directly from the user. This bug leads to an information leak.
---
 drivers/video/fbdev/sbuslib.c | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/video/fbdev/sbuslib.c +1 -1
@@ -171,7 +171,7 @@ int sbusfb_ioctl_helper(unsigned long cmd, unsigned long arg, get_user(ublue, &c->blue))return -EFAULT ; -if (index + count > cmap->len) +if (index > cmap->len || count > cmap->len - index)return -EINVAL ;for (i =0 ; i < count; i++) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 143/209 fbdev: fix broken menu dependencies
In reply to Sasha LevinFrom: Randy Dunlap <[email protected]>
[ Upstream commit aae3394ef0ef90cf00a21133357448385f13a5d4 ]
The framebuffer options and devices menu is unintentionally split or broken because some items in it do not depend on FB (including several under omap and mmp).
Fix this by moving FB_CMDLINE, FB_NOTIFY, and FB_CLPS711X_OLD to just before the FB Kconfig symbol definition and by moving the omap, omap2, and mmp menus to last, following FB_SM712.
Also, the FB_VIA dependencies are duplicated by both being inside an "if FB_VIA/endif" block and "depends on FB_VIA", so drop the "depends on FB_VIA" lines since they are redundant.
---
 drivers/video/fbdev/Kconfig | 34 ++++++++++++++++------------------
 1 file changed, 16 insertions(+), 18 deletions(-)
drivers/video/fbdev/Kconfig +16 -18
@@ -2,6 +2,18 @@ # fbdev configuration # +config FB_CMDLINE + bool + +config FB_NOTIFY + bool + +config FB_CLPS711X_OLD + tristate + select FB_CFB_FILLRECT + select FB_CFB_COPYAREA + select FB_CFB_IMAGEBLIT + menuconfig FB tristate "Support for frame buffer devices" select FB_CMDLINE
@@ -54,12 +66,6 @@ config FIRMWARE_EDID
 	 combination with certain motherboards and monitors are known to
 	 suffer from this problem.

-config FB_CMDLINE
-	bool
-
-config FB_NOTIFY
-	bool
-
 config FB_DDC
        tristate
        depends on FB
@@ -329,12 +335,6 @@ config FB_ACORN
 	  hardware found in Acorn RISC PCs and other ARM-based machines.  If
 	  unsure, say N.

-config FB_CLPS711X_OLD
-	tristate
-	select FB_CFB_FILLRECT
-	select FB_CFB_COPYAREA
-	select FB_CFB_IMAGEBLIT
-
 config FB_CLPS711X
 	tristate "CLPS711X LCD support"
 	depends on FB && (ARCH_CLPS711X || COMPILE_TEST)
@@ -1456,7 +1456,6 @@ if FB_VIA

 config FB_VIA_DIRECT_PROCFS
 	bool "direct hardware access via procfs (DEPRECATED)(DANGEROUS)"
-	depends on FB_VIA
 	default n
 	help
 	  Allow direct hardware access to some output registers via procfs.
@@ -1466,7 +1465,6 @@ config FB_VIA_DIRECT_PROCFS

 config FB_VIA_X_COMPATIBILITY
 	bool "X server compatibility"
-	depends on FB_VIA
 	default n
 	help
 	  This option reduces the functionality (power saving, ...) of the
@@ -2308,10 +2306,6 @@ config FB_SIMPLE
 	  Configuration re: surface address, size, and format must be provided
 	  through device tree, or plain old platform data.

-source "drivers/video/fbdev/omap/Kconfig"
-source "drivers/video/fbdev/omap2/Kconfig"
-source "drivers/video/fbdev/mmp/Kconfig"
-
 config FB_SSD1307
 	tristate "Solomon SSD1307 framebuffer support"
 	depends on FB && I2C
@@ -2341,3 +2335,7 @@ config FB_SM712
 	  This driver is also available as a module. The module will be
 	  called sm712fb. If you want to compile it as a module, say M
 	  here and read <file:Documentation/kbuild/modules.txt>.
+
+source "drivers/video/fbdev/omap/Kconfig"
+source "drivers/video/fbdev/omap2/Kconfig"
+source "drivers/video/fbdev/mmp/Kconfig"
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 145/209 bcache: account size of buckets used in uuid write to ca->meta_sectors_written
In reply to Sasha LevinFrom: Shenghui Wang <[email protected]>
[ Upstream commit 7a55948d38eb9b274cbbdd56dc1dd4b96ebfbe04 ]
UUIDs are considered as metadata. __uuid_write should add the number of buckets (in sectors) written to disk to ca->meta_sectors_written. Currently only 1 bucket is used in uuid write.
Steps to test:
1) create a fresh backing device and a fresh cache device separately. The backing device didn't attach to any cache set.
2) cd /sys/block/<cache device>/bcache
cat metadata_written // record the output value
cat bucket_size
3) attach the backing device to cache set
4) cat metadata_written
The output value is almost the same as the value in step 2 before the change.
After the change, the value is bigger about 1 bucket size.
---
 drivers/md/bcache/super.c | 5 +++++
 1 file changed, 5 insertions(+)
drivers/md/bcache/super.c +5 -0
@@ -418,6 +418,7 @@ static int __uuid_write(struct cache_set *c) {BKEY_PADDED (key) k;struct closure cl; +struct cache *ca;closure_init_stack (&cl);lockdep_assert_held (&bch_register_lock);
@@ -429,6 +430,10 @@ static int __uuid_write(struct cache_set *c)uuid_io (c,REQ_OP_WRITE ,0 , &k.key, &cl);closure_sync (&cl); +/* Only one bucket used for uuid write */ + ca =PTR_CACHE (c, &k.key,0 ); +atomic_long_add (ca->sb.bucket_size, &ca->meta_sectors_written); +bkey_copy (&c->uuid_bucket, &k.key);bkey_put (c, &k.key);return 0 ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 146/209 bcache: recal cached_dev_sectors on detach
In reply to Sasha LevinFrom: Shenghui Wang <[email protected]>
[ Upstream commit 46010141da6677b81cc77f9b47f8ac62bd1cbfd3 ]
Recal cached_dev_sectors on cached_dev detached, as recal done on cached_dev attached.
Update the cached_dev_sectors before bcache_device_detach called as bcache_device_detach will set bcache_device->c to NULL.
---
 drivers/md/bcache/super.c | 1 +
 1 file changed, 1 insertion(+)
drivers/md/bcache/super.c +1 -0
@@ -1009,6 +1009,7 @@ static void cached_dev_detach_finish(struct work_struct *w)bch_write_bdev_super (dc, &cl);closure_sync (&cl); +calc_cached_dev_sectors (dc->disk.c);bcache_device_detach (&dc->disk);list_move (&dc->list, &uncached_devices);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 147/209 platform/x86: mlx-platform: Properly use mlxplat_mlxcpld_msn201x_items
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit 8289c4b6f2e53750de78bd38cecb6bce4d7a988c ]
Clang warns that mlxplat_mlxcpld_msn201x_items is not going to be emitted in the final assembly because it's only used in ARRAY_SIZE right now, which is a compile time evaluation since the array's size is known.
drivers/platform/x86/mlx-platform.c:555:32: warning: variable 'mlxplat_mlxcpld_msn201x_items' is not needed and will not be emitted [-Wunneeded-internal-declaration]
static struct mlxreg_core_item mlxplat_mlxcpld_msn201x_items[] = {
                               ^
1 warning generated.
It appears this was a copy and paste mistake from when this item was first added. Use the definition in mlxplat_mlxcpld_msn201x_data so that Clang no longer warns.
---
 drivers/platform/x86/mlx-platform.c | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/platform/x86/mlx-platform.c +1 -1
@@ -575,7 +575,7 @@ static struct mlxreg_core_item mlxplat_mlxcpld_msn201x_items[] = {static struct mlxreg_core_hotplug_platform_data mlxplat_mlxcpld_msn201x_data = { - .items = mlxplat_mlxcpld_msn21xx_items, + .items = mlxplat_mlxcpld_msn201x_items, .counter =ARRAY_SIZE (mlxplat_mlxcpld_msn201x_items), .cell =MLXPLAT_CPLD_LPC_REG_AGGR_OFFSET , .mask =MLXPLAT_CPLD_AGGR_MASK_DEF ,
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 155/209 mmc: mmci: expand startbiterr to irqmask and error check
In reply to Sasha LevinFrom: Ludovic Barre <[email protected]>
[ Upstream commit daf9713c5ef8c3ffb0bdf7de11b53b2b2756c4f1 ]
All variants don't pretend to have a startbiterr.
-While data error check, if status register return an error (like MCI_DATACRCFAIL) we must avoid to check MCI_STARTBITERR (if not desired).
-expand start_err to MCI_IRQENABLE to avoid to set this bit by default.
---
 drivers/mmc/host/mmci.c | 27 ++++++++++++++++-----------
 drivers/mmc/host/mmci.h |  6 +++---
 2 files changed, 19 insertions(+), 14 deletions(-)
drivers/mmc/host/mmci.c +16 -11
@@ -895,14 +895,18 @@ static void mmci_data_irq(struct mmci_host *host, struct mmc_data *data, unsigned int status) { + unsigned int status_err; +/* Make sure we have data to handle */ if (!data)return ;/* First check for errors */ -if (status & (MCI_DATACRCFAIL |MCI_DATATIMEOUT | - host->variant->start_err | -MCI_TXUNDERRUN |MCI_RXOVERRUN )) { + status_err = status & (host->variant->start_err | +MCI_DATACRCFAIL |MCI_DATATIMEOUT | +MCI_TXUNDERRUN |MCI_RXOVERRUN ); + +if (status_err) {u32 remain, success;/* Terminate the DMA transfer */
@@ -922,18 +926,18 @@ mmci_data_irq(struct mmci_host *host, struct mmc_data *data, success = data->blksz * data->blocks - remain;dev_dbg (mmc_dev (host->mmc),"MCI ERROR IRQ, status 0x%08x at 0x%08x\n" , - status, success); -if (status &MCI_DATACRCFAIL ) { + status_err, success); +if (status_err &MCI_DATACRCFAIL ) {/* Last block was not successful */ success -=1 ; data->error = -EILSEQ ; - }else if (status &MCI_DATATIMEOUT ) { + }else if (status_err &MCI_DATATIMEOUT ) { data->error = -ETIMEDOUT ; - }else if (status &MCI_STARTBITERR ) { + }else if (status_err &MCI_STARTBITERR ) { data->error = -ECOMM ; - }else if (status &MCI_TXUNDERRUN ) { + }else if (status_err &MCI_TXUNDERRUN ) { data->error = -EIO ; - }else if (status &MCI_RXOVERRUN ) { + }else if (status_err &MCI_RXOVERRUN ) {if (success > host->variant->fifosize) success -= host->variant->fifosize;else
@@ -1790,7 +1794,7 @@ static int mmci_probe(struct amba_device *dev, goto clk_disable; } -writel (MCI_IRQENABLE , host->base +MMCIMASK0 ); +writel (MCI_IRQENABLE | variant->start_err, host->base +MMCIMASK0 );amba_set_drvdata (dev, mmc);
@@ -1877,7 +1881,8 @@ static void mmci_restore(struct mmci_host *host)writel (host->datactrl_reg, host->base +MMCIDATACTRL );writel (host->pwr_reg, host->base +MMCIPOWER ); } -writel (MCI_IRQENABLE , host->base +MMCIMASK0 ); +writel (MCI_IRQENABLE | host->variant->start_err, + host->base +MMCIMASK0 );mmci_reg_delay (host);spin_unlock_irqrestore (&host->lock, flags);
drivers/mmc/host/mmci.h +3 -3
@@ -181,9 +181,9 @@#define MMCIFIFO 0x080/* to 0x0bc */ #define MCI_IRQENABLE \ - (MCI_CMDCRCFAILMASK|MCI_DATACRCFAILMASK|MCI_CMDTIMEOUTMASK| \ - MCI_DATATIMEOUTMASK|MCI_TXUNDERRUNMASK|MCI_RXOVERRUNMASK| \ - MCI_CMDRESPENDMASK|MCI_CMDSENTMASK|MCI_STARTBITERRMASK) + (MCI_CMDCRCFAILMASK | MCI_DATACRCFAILMASK | MCI_CMDTIMEOUTMASK | \ + MCI_DATATIMEOUTMASK | MCI_TXUNDERRUNMASK | MCI_RXOVERRUNMASK | \ + MCI_CMDRESPENDMASK | MCI_CMDSENTMASK)/* These interrupts are directed to IRQ1 when two IRQ lines are available */ #define MCI_IRQ1MASK \
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 160/209 backlight: lm3639: Unconditionally call led_classdev_unregister
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit 7cea645ae9c5a54aa7904fddb2cdf250acd63a6c ]
Clang warns that the address of a pointer will always evaluated as true in a boolean context.
drivers/video/backlight/lm3639_bl.c:403:14: warning: address of 'pchip->cdev_torch' will always evaluate to 'true' [-Wpointer-bool-conversion]
        if (&pchip->cdev_torch)
        ~~   ~~~~~~~^~~~~~~~~~
drivers/video/backlight/lm3639_bl.c:405:14: warning: address of
'pchip->cdev_flash' will always evaluate to 'true'
[-Wpointer-bool-conversion]
        if (&pchip->cdev_flash)
        ~~   ~~~~~~~^~~~~~~~~~
2 warnings generated.
These statements have been present since 2012, introduced by commit 0f59858d5119 ("backlight: add new lm3639 backlight driver"). Given that they have been called unconditionally since then presumably without any issues, removing the always true if statements to fix the warnings without any real world changes.
---
 drivers/video/backlight/lm3639_bl.c | 6 ++----
 1 file changed, 2 insertions(+), 4 deletions(-)
drivers/video/backlight/lm3639_bl.c +2 -4
@@ -400,10 +400,8 @@ static int lm3639_remove(struct i2c_client *client)regmap_write (pchip->regmap,REG_ENABLE ,0x00 ); -if (&pchip->cdev_torch) -led_classdev_unregister (&pchip->cdev_torch); -if (&pchip->cdev_flash) -led_classdev_unregister (&pchip->cdev_flash); +led_classdev_unregister (&pchip->cdev_torch); +led_classdev_unregister (&pchip->cdev_flash);if (pchip->bled)device_remove_file (&(pchip->bled->dev), &dev_attr_bled_mode);return 0 ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 180/209 spi: fsl-lpspi: Prevent FIFO under/overrun by default
In reply to Sasha LevinFrom: Hieu Tran Dang <[email protected]>
[ Upstream commit de8978c388c66b8fca192213ec9f0727e964c652 ]
Certain devices don't work well when a transmit FIFO underrun or receive FIFO overrun occurs. Example is the SAF400x radio chip when running at high speed which leads to garbage being sent to/received from the chip. In which case, it should stall waiting for further data to be available before proceeding. This patch unset the NOSTALL bit in CFGR1 by default to prevent this issue.
---
 drivers/spi/spi-fsl-lpspi.c | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/spi/spi-fsl-lpspi.c +1 -1
@@ -276,7 +276,7 @@ static int fsl_lpspi_config(struct fsl_lpspi_data *fsl_lpspi)fsl_lpspi_set_watermark (fsl_lpspi); - temp =CFGR1_PCSCFG |CFGR1_MASTER |CFGR1_NOSTALL ; + temp =CFGR1_PCSCFG |CFGR1_MASTER ;if (fsl_lpspi->config.mode &SPI_CS_HIGH ) temp |=CFGR1_PCSPOL ;writel (temp, fsl_lpspi->base +IMX7ULP_CFGR1 );
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 182/209 spi: spidev: Fix OF tree warning logic
In reply to Sasha LevinFrom: Trent Piepho <[email protected]>
[ Upstream commit 605b3bec73cbd74b4ac937b580cd0b47d1300484 ]
spidev will make a big fuss if a device tree node binds a device by using "spidev" as the node's compatible property.
However, the logic for this isn't looking for "spidev" in the compatible, but rather checking that the device is NOT compatible with spidev's list of devices.
This causes a false positive if a device not named "rohm,dh2228fv", etc. binds to spidev, even if a means other than putting "spidev" in the device tree was used. E.g., the sysfs driver_override attribute.
---
 drivers/spi/spidev.c | 8 +++-----
 1 file changed, 3 insertions(+), 5 deletions(-)
drivers/spi/spidev.c +3 -5
@@ -724,11 +724,9 @@ static int spidev_probe(struct spi_device *spi)* compatible string, it is a Linux implementation thing * rather than a description of the hardware. */ -if (spi->dev.of_node && !of_match_device (spidev_dt_ids, &spi->dev)) { -dev_err (&spi->dev,"buggy DT: spidev listed directly in DT\n" ); -WARN_ON (spi->dev.of_node && - !of_match_device (spidev_dt_ids, &spi->dev)); - } +WARN (spi->dev.of_node && +of_device_is_compatible (spi->dev.of_node,"spidev" ), +"%pOF: buggy DT: spidev listed directly in DT\n" , spi->dev.of_node);spidev_probe_acpi (spi);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 200/209 spi: rockchip: initialize dma_slave_config properly
In reply to Sasha LevinFrom: Huibin Hong <[email protected]>
[ Upstream commit dd8fd2cbc73f8650f651da71fc61a6e4f30c1566 ]
The rxconf and txconf structs are allocated on the stack, so make sure we zero them before filling out the relevant fields.
---
 drivers/spi/spi-rockchip.c | 3 +++
 1 file changed, 3 insertions(+)
drivers/spi/spi-rockchip.c +3 -0
@@ -445,6 +445,9 @@ static int rockchip_spi_prepare_dma(struct rockchip_spi *rs)struct dma_slave_config rxconf, txconf;struct dma_async_tx_descriptor *rxdesc, *txdesc; +memset (&rxconf,0 ,sizeof (rxconf)); +memset (&txconf,0 ,sizeof (txconf)); +spin_lock_irqsave (&rs->lock, flags); rs->state &= ~RXBUSY ; rs->state &= ~TXBUSY ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 202/209 ARM: dts: omap5: Fix dual-role mode on Super-Speed port
In reply to Sasha LevinFrom: Roger Quadros <[email protected]>
[ Upstream commit a763ecc15d0e37c3a15ff6825183061209832685 ]
OMAP5's Super-Speed USB port has a software mailbox register that needs to be fed with VBUS and ID events from an external VBUS/ID comparator.
Without this, Host role will not work correctly.
---
 arch/arm/boot/dts/omap5-board-common.dtsi | 1 +
 1 file changed, 1 insertion(+)
arch/arm/boot/dts/omap5-board-common.dtsi +1 -0
@@ -704,6 +704,7 @@ }; &dwc3 { + extcon = <&extcon_usb3>; dr_mode = "otg"; };
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 208/209 mmc: tmio: fix SCC error handling to avoid false positive CRC error
In reply to Sasha LevinFrom: Takeshi Saito <[email protected]>
[ Upstream commit 51b72656bb39fdcb8f3174f4007bcc83ad1d275f ]
If an SCC error occurs during a read/write command execution, a false positive CRC error message is output.
mmcblk0: response CRC error sending r/w cmd command, card status 0x900
check_scc_error() checks SCC_RVSREQ.RVSERR bit. RVSERR detects a correction error in the next (up or down) delay tap position. However, since the command is successful, only retuning needs to be executed. This has been confirmed by HW engineers.
Thus, on SCC error, set retuning flag instead of setting an error code.
---
 drivers/mmc/host/tmio_mmc_core.c | 3 ++-
 1 file changed, 2 insertions(+), 1 deletion(-)
drivers/mmc/host/tmio_mmc_core.c +2 -1
@@ -926,8 +926,9 @@ static void tmio_mmc_finish_request(struct tmio_mmc_host *host)if (mrq->cmd->error || (mrq->data && mrq->data->error))tmio_mmc_abort_dma (host); +/* SCC error means retune, but executed command was still successful */ if (host->check_scc_error && host->check_scc_error (host)) - mrq->cmd->error = -EILSEQ ; +mmc_retune_needed (host->mmc);/* If SET_BLOCK_COUNT, continue with main command */ if (host->mrq && !mrq->cmd->error) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 1/209 net: ovs: fix return type of ndo_start_xmit function
From: YueHaibing <[email protected]>
[ Upstream commit eddf11e18dff0e8671e06ce54e64cfc843303ab9 ]
The method ndo_start_xmit() is defined as returning an 'netdev_tx_t', which is a typedef for an enum type, so make sure the implementation in this driver has returns 'netdev_tx_t' value, and change the function return type to netdev_tx_t.
Found by coccinelle.
---
 net/openvswitch/vport-internal_dev.c | 5 +++--
 1 file changed, 3 insertions(+), 2 deletions(-)
net/openvswitch/vport-internal_dev.c +3 -2
@@ -43,7 +43,8 @@ static struct internal_dev *internal_dev_priv(struct net_device *netdev) }/* Called with rcu_read_lock_bh. */ -static int internal_dev_xmit (struct sk_buff *skb,struct net_device *netdev) +static netdev_tx_t +internal_dev_xmit (struct sk_buff *skb,struct net_device *netdev) {int len, err;
@@ -62,7 +63,7 @@ static int internal_dev_xmit(struct sk_buff *skb, struct net_device *netdev) }else { netdev->stats.tx_errors++; } -return 0 ; +return NETDEV_TX_OK ; }static int internal_dev_open (struct net_device *netdev)
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 5/209 net: hns3: Fix for netdev not up problem when setting mtu
From: Yunsheng Lin <[email protected]>
[ Upstream commit 93d8daf460183871a965dae339839d9e35d44309 ]
Currently hns3_nic_change_mtu will try to down the netdev before setting mtu, and it does not up the netdev when the setting fails, which causes netdev not up problem.
This patch fixes it by not returning when the setting fails.
---
 drivers/net/ethernet/hisilicon/hns3/hns3_enet.c | 8 +++-----
 1 file changed, 3 insertions(+), 5 deletions(-)
drivers/net/ethernet/hisilicon/hns3/hns3_enet.c +3 -5
@@ -1447,13 +1447,11 @@ static int hns3_nic_change_mtu(struct net_device *netdev, int new_mtu) } ret = h->ae_algo->ops->set_mtu (h, new_mtu); -if (ret) { +if (ret)netdev_err (netdev,"failed to change MTU in hardware %d\n" , ret); -return ret; - } - - netdev->mtu = new_mtu; +else + netdev->mtu = new_mtu;/* if the netdev was running earlier, bring it up again */ if (if_running &&hns3_nic_net_open (netdev))
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 6/209 net: hns3: Fix loss of coal configuration while doing reset
In reply to Sasha LevinFrom: Huazhong Tan <[email protected]>
[ Upstream commit e4fd75022c24eb28cc1034e97e60cecc24f325f3 ]
The user's coal configuration will be lost after reset, so the tx_coal and rx_coal fields are added to the struct hns_nic_priv to save the coal configuration and used to restore the user's configuration after the reset is complete.
---
 .../net/ethernet/hisilicon/hns3/hns3_enet.c   | 71 +++++++++----------
 .../net/ethernet/hisilicon/hns3/hns3_enet.h   |  2 +
 2 files changed, 36 insertions(+), 37 deletions(-)
drivers/net/ethernet/hisilicon/hns3/hns3_enet.c +34 -37
@@ -195,8 +195,6 @@ void hns3_set_vector_coalesce_tx_gl(struct hns3_enet_tqp_vector *tqp_vector,static void hns3_vector_gl_rl_init (struct hns3_enet_tqp_vector *tqp_vector,struct hns3_nic_priv *priv) { -struct hnae3_handle *h = priv->ae_handle; -/* initialize the configuration for interrupt coalescing. * 1. GL (Interrupt Gap Limiter) * 2. RL (Interrupt Rate Limiter)
@@ -209,9 +207,6 @@ static void hns3_vector_gl_rl_init(struct hns3_enet_tqp_vector *tqp_vector, tqp_vector->tx_group.coal.int_gl =HNS3_INT_GL_50K ; tqp_vector->rx_group.coal.int_gl =HNS3_INT_GL_50K ; -/* Default: disable RL */ - h->kinfo.int_rl_setting =0 ; - tqp_vector->int_adapt_down =HNS3_INT_ADAPT_DOWN_START ; tqp_vector->rx_group.coal.flow_level =HNS3_FLOW_LOW ; tqp_vector->tx_group.coal.flow_level =HNS3_FLOW_LOW ;
@@ -3423,6 +3418,31 @@ int hns3_nic_reset_all_ring(struct hnae3_handle *h)return 0 ; } +static void hns3_store_coal (struct hns3_nic_priv *priv) +{ +/* ethtool only support setting and querying one coal +* configuation for now, so save the vector 0' coal +* configuation here in order to restore it. +*/ +memcpy (&priv->tx_coal, &priv->tqp_vector[0 ].tx_group.coal, +sizeof (struct hns3_enet_coalesce )); +memcpy (&priv->rx_coal, &priv->tqp_vector[0 ].rx_group.coal, +sizeof (struct hns3_enet_coalesce )); +} + +static void hns3_restore_coal (struct hns3_nic_priv *priv) +{ +u16 vector_num = priv->vector_num; +int i; + +for (i =0 ; i < vector_num; i++) { +memcpy (&priv->tqp_vector[i].tx_group.coal, &priv->tx_coal, +sizeof (struct hns3_enet_coalesce )); +memcpy (&priv->tqp_vector[i].rx_group.coal, &priv->rx_coal, +sizeof (struct hns3_enet_coalesce )); + } +} +static int hns3_reset_notify_down_enet (struct hnae3_handle *handle) {struct hnae3_knic_private_info *kinfo = &handle->kinfo;
@@ -3469,6 +3489,8 @@ static int hns3_reset_notify_init_enet(struct hnae3_handle *handle)/* Carrier off reporting is important to ethtool even BEFORE open */ netif_carrier_off (netdev); +hns3_restore_coal (priv); + ret =hns3_nic_init_vector_data (priv);if (ret)return ret;
@@ -3496,6 +3518,8 @@ static int hns3_reset_notify_uninit_enet(struct hnae3_handle *handle)return ret; } +hns3_store_coal (priv); + ret =hns3_uninit_all_ring (priv);if (ret)netdev_err (netdev,"uninit ring error\n" );
@@ -3530,24 +3554,7 @@ static int hns3_reset_notify(struct hnae3_handle *handle,return ret; } -static void hns3_restore_coal (struct hns3_nic_priv *priv, -struct hns3_enet_coalesce *tx, -struct hns3_enet_coalesce *rx) -{ -u16 vector_num = priv->vector_num; -int i; - -for (i =0 ; i < vector_num; i++) { -memcpy (&priv->tqp_vector[i].tx_group.coal, tx, -sizeof (struct hns3_enet_coalesce )); -memcpy (&priv->tqp_vector[i].rx_group.coal, rx, -sizeof (struct hns3_enet_coalesce )); - } -} - -static int hns3_modify_tqp_num (struct net_device *netdev,u16 new_tqp_num, -struct hns3_enet_coalesce *tx, -struct hns3_enet_coalesce *rx) +static int hns3_modify_tqp_num (struct net_device *netdev,u16 new_tqp_num) {struct hns3_nic_priv *priv =netdev_priv (netdev);struct hnae3_handle *h =hns3_get_handle (netdev);
@@ -3565,7 +3572,7 @@ static int hns3_modify_tqp_num(struct net_device *netdev, u16 new_tqp_num,if (ret) goto err_alloc_vector; -hns3_restore_coal (priv, tx, rx); +hns3_restore_coal (priv); ret =hns3_nic_init_vector_data (priv);if (ret)
@@ -3597,7 +3604,6 @@ int hns3_set_channels(struct net_device *netdev,struct hns3_nic_priv *priv =netdev_priv (netdev);struct hnae3_handle *h =hns3_get_handle (netdev);struct hnae3_knic_private_info *kinfo = &h->kinfo; -struct hns3_enet_coalesce tx_coal, rx_coal;bool if_running =netif_running (netdev);u32 new_tqp_num = ch->combined_count;u16 org_tqp_num;
@@ -3629,15 +3635,7 @@ int hns3_set_channels(struct net_device *netdev, goto open_netdev; } -/* Changing the tqp num may also change the vector num, -* ethtool only support setting and querying one coal -* configuation for now, so save the vector 0' coal -* configuation here in order to restore it. -*/ -memcpy (&tx_coal, &priv->tqp_vector[0 ].tx_group.coal, -sizeof (struct hns3_enet_coalesce )); -memcpy (&rx_coal, &priv->tqp_vector[0 ].rx_group.coal, -sizeof (struct hns3_enet_coalesce )); +hns3_store_coal (priv);hns3_nic_dealloc_vector_data (priv);
@@ -3645,10 +3643,9 @@ int hns3_set_channels(struct net_device *netdev,hns3_put_ring_config (priv); org_tqp_num = h->kinfo.num_tqps; - ret =hns3_modify_tqp_num (netdev, new_tqp_num, &tx_coal, &rx_coal); + ret =hns3_modify_tqp_num (netdev, new_tqp_num);if (ret) { - ret =hns3_modify_tqp_num (netdev, org_tqp_num, - &tx_coal, &rx_coal); + ret =hns3_modify_tqp_num (netdev, org_tqp_num);if (ret) {/* If revert to old tqp failed, fatal error occurred */ dev_err(&netdev->dev,
drivers/net/ethernet/hisilicon/hns3/hns3_enet.h +2 -0
@@ -541,6 +541,8 @@ struct hns3_nic_priv {/* Vxlan/Geneve information */ struct hns3_udp_tunnel udp_tnl[HNS3_UDP_TNL_MAX ];unsigned long active_vlans[BITS_TO_LONGS (VLAN_N_VID )]; +struct hns3_enet_coalesce tx_coal; +struct hns3_enet_coalesce rx_coal; };union l3_hdr_info {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 8/209 ARM: dts: sun8i: h3-h5: ir register size should be the whole memory block
In reply to Sasha LevinFrom: Philipp Rossak <[email protected]>
[ Upstream commit 6c700289a3e84d5d3f2a95cf27732a7f7fce105b ]
The size of the register should be the size of the whole memory block, not just the registers, that are needed.
---
 arch/arm/boot/dts/sunxi-h3-h5.dtsi | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
arch/arm/boot/dts/sunxi-h3-h5.dtsi +1 -1
@@ -816,7 +816,7 @@ clock-names = "apb", "ir"; resets = <&r_ccu RST_APB0_IR>; interrupts = <GIC_SPI 37 IRQ_TYPE_LEVEL_HIGH>; - reg = <0x01f02000 0x40>; + reg = <0x01f02000 0x400>; status = "disabled"; };
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 7/209 f2fs: return correct errno in f2fs_gc
In reply to Sasha LevinFrom: Jaegeuk Kim <[email protected]>
[ Upstream commit 61f7725aa148ee870436a29d3a24d5c00ab7e9af ]
This fixes overriding error number in f2fs_gc.
---
 fs/f2fs/gc.c | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
fs/f2fs/gc.c +1 -1
@@ -1244,7 +1244,7 @@ int f2fs_gc(struct f2fs_sb_info *sbi, bool sync,put_gc_inode (&gc_list); -if (sync) +if (sync && !ret) ret = sec_freed ?0 : -EAGAIN ;return ret; }
Signature · 8 lines
2.20.1


_______________________________________________
Linux-f2fs-devel mailing list
[email protected]
https://lists.sourceforge.net/lists/listinfo/linux-f2fs-devel
Sasha Levin
maintainerPATCH 10/209 tcp: up initial rmem to 128KB and SYN rwin to around 64KB
In reply to Sasha LevinFrom: Yuchung Cheng <[email protected]>
[ Upstream commit a337531b942bd8a03e7052444d7e36972aac2d92 ]
Previously TCP initial receive buffer is ~87KB by default and the initial receive window is ~29KB (20 MSS). This patch changes the two numbers to 128KB and ~64KB (rounding down to the multiples of MSS) respectively. The patch also simplifies the calculations s.t. the two numbers are directly controlled by sysctl tcp_rmem[1]:
1) Initial receiver buffer budget (sk_rcvbuf): while this should be configured via sysctl tcp_rmem[1], previously tcp_fixup_rcvbuf() always override and set a larger size when a new connection establishes.
2) Initial receive window in SYN: previously it is set to 20 packets if MSS <= 1460. The number 20 was based on the initial congestion window of 10: the receiver needs twice amount to avoid being limited by the receive window upon out-of-order delivery in the first window burst. But since this only applies if the receiving MSS <= 1460, connection using large MTU (e.g. to utilize receiver zero-copy) may be limited by the receive window.
With this patch TCP memory configuration is more straight-forward and more properly sized to modern high-speed networks by default. Several popular stacks have been announcing 64KB rwin in SYNs as well.
---
 net/ipv4/tcp.c        |  4 ++--
 net/ipv4/tcp_input.c  | 25 ++-----------------------
 net/ipv4/tcp_output.c | 25 ++++---------------------
 3 files changed, 8 insertions(+), 46 deletions(-)
net/ipv4/tcp.c +2 -2
@@ -3910,8 +3910,8 @@ void __init tcp_init(void) init_net.ipv4.sysctl_tcp_wmem[2 ] =max (64 *1024 , max_wshare); init_net.ipv4.sysctl_tcp_rmem[0 ] =SK_MEM_QUANTUM ; - init_net.ipv4.sysctl_tcp_rmem[1 ] =87380 ; - init_net.ipv4.sysctl_tcp_rmem[2 ] =max (87380 , max_rshare); + init_net.ipv4.sysctl_tcp_rmem[1 ] =131072 ; + init_net.ipv4.sysctl_tcp_rmem[2 ] =max (131072 , max_rshare);pr_info ("Hash tables configured (established %u bind %u)\n" , tcp_hashinfo.ehash_mask +1 , tcp_hashinfo.bhash_size);
net/ipv4/tcp_input.c +2 -23
@@ -426,26 +426,7 @@ static void tcp_grow_window(struct sock *sk, const struct sk_buff *skb) } } -/* 3. Tuning rcvbuf, when connection enters established state. */ -static void tcp_fixup_rcvbuf (struct sock *sk) -{ -u32 mss =tcp_sk (sk)->advmss; -int rcvmem; - - rcvmem =2 *SKB_TRUESIZE (mss +MAX_TCP_HEADER ) * -tcp_default_init_rwnd (mss); - -/* Dynamic Right Sizing (DRS) has 2 to 3 RTT latency -* Allow enough cushion so that sender is not limited by our window -*/ -if (sock_net (sk)->ipv4.sysctl_tcp_moderate_rcvbuf) - rcvmem <<=2 ; - -if (sk->sk_rcvbuf < rcvmem) - sk->sk_rcvbuf =min (rcvmem,sock_net (sk)->ipv4.sysctl_tcp_rmem[2 ]); -} - -/* 4. Try to fixup all. It is made immediately after connection enters +/* 3. Try to fixup all. It is made immediately after connection enters * established state. */ void tcp_init_buffer_space (struct sock *sk)
@@ -454,8 +435,6 @@ void tcp_init_buffer_space(struct sock *sk)struct tcp_sock *tp =tcp_sk (sk);int maxwin; -if (!(sk->sk_userlocks &SOCK_RCVBUF_LOCK )) -tcp_fixup_rcvbuf (sk);if (!(sk->sk_userlocks &SOCK_SNDBUF_LOCK ))tcp_sndbuf_expand (sk);
@@ -485,7 +464,7 @@ void tcp_init_buffer_space(struct sock *sk) tp->snd_cwnd_stamp = tcp_jiffies32; } -/* 5. Recalculate window clamp after socket hit its memory bounds. */ +/* 4. Recalculate window clamp after socket hit its memory bounds. */ static void tcp_clamp_window (struct sock *sk) {struct tcp_sock *tp =tcp_sk (sk);
net/ipv4/tcp_output.c +4 -21
@@ -179,21 +179,6 @@ static inline void tcp_event_ack_sent(struct sock *sk, unsigned int pkts,inet_csk_clear_xmit_timer (sk,ICSK_TIME_DACK ); } - -u32 tcp_default_init_rwnd (u32 mss) -{ -/* Initial receive window should be twice of TCP_INIT_CWND to -* enable proper sending of new unsent data during fast recovery -* (RFC 3517, Section 4, NextSeg() rule (2)). Further place a -* limit when mss is larger than 1460. -*/ -u32 init_rwnd =TCP_INIT_CWND *2 ; - -if (mss >1460 ) - init_rwnd =max ((1460 * init_rwnd) / mss,2U ); -return init_rwnd; -} -/* Determine a window scaling and initial window to offer. * Based on the assumption that the given amount of space * will be offered. Store the results in the tp structure.
@@ -228,7 +213,10 @@ void tcp_select_initial_window(const struct sock *sk, int __space, __u32 mss,if (sock_net (sk)->ipv4.sysctl_tcp_workaround_signed_windows) (*rcv_wnd) =min (space,MAX_TCP_WINDOW );else - (*rcv_wnd) = space; + (*rcv_wnd) =min_t (u32, space,U16_MAX ); + +if (init_rcv_wnd) + *rcv_wnd =min (*rcv_wnd, init_rcv_wnd * mss); (*rcv_wscale) =0 ;if (wscale_ok) {
@@ -241,11 +229,6 @@ void tcp_select_initial_window(const struct sock *sk, int __space, __u32 mss, (*rcv_wscale)++; } } - -if (!init_rcv_wnd)/* Use default unless specified otherwise */ - init_rcv_wnd =tcp_default_init_rwnd (mss); - *rcv_wnd =min (*rcv_wnd, init_rcv_wnd * mss); -/* Set the clamp no higher than max representable value */ (*window_clamp) =min_t (__u32,U16_MAX << (*rcv_wscale), *window_clamp); }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 9/209 ARM: dts: sun8i: h3: bpi-m2-plus: Fix address for external RGMII Ethernet PHY
In reply to Sasha LevinFrom: Chen-Yu Tsai <[email protected]>
[ Upstream commit db9fd9d13e30fc67737ac9893a82e6b095e85a64 ]
The external RTL8211E RGMII Ethernet PHY is configured via external resistors to use the address 0x1. The 0x0 address is a broadcast address for this family of PHYs, and should not be used explicitly.
---
 arch/arm/boot/dts/sun8i-h3-bananapi-m2-plus.dts | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
arch/arm/boot/dts/sun8i-h3-bananapi-m2-plus.dts +1 -1
@@ -140,7 +140,7 @@ &external_mdio { ext_rgmii_phy: ethernet-phy@1 { compatible = "ethernet-phy-ieee802.3-c22"; - reg = <0>; + reg = <1>; }; };
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 15/209 f2fs: keep lazytime on remount
In reply to Sasha LevinFrom: Jaegeuk Kim <[email protected]>
[ Upstream commit 095680f24f2673d860fd1d3d2f54f40f330b4c63 ]
This patch fixes losing lazytime when remounting f2fs.
---
 fs/f2fs/super.c | 1 +
 1 file changed, 1 insertion(+)
fs/f2fs/super.c +1 -0
@@ -1555,6 +1555,7 @@ static int f2fs_remount(struct super_block *sb, int *flags, char *data) (test_opt (sbi,POSIX_ACL ) ?SB_POSIXACL :0 );limit_reserve_root (sbi); + *flags = (*flags & ~SB_LAZYTIME ) | (sb->s_flags &SB_LAZYTIME );return 0 ; restore_gc:if (need_restart_gc) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 17/209 IB/hfi1: Ensure ucast_dlid access doesnt exceed bounds
In reply to Sasha LevinFrom: Dennis Dalessandro <[email protected]>
[ Upstream commit 3144533bf667c8e53bb20656b78295960073e57b ]
The dlid assignment made by looking into the u_ucast_dlid array does not do an explicit check for the size of the array. The code path to arrive at def_port, the index value is long and complicated so its best to just have an explicit check here.
---
 drivers/infiniband/ulp/opa_vnic/opa_vnic_encap.c | 3 ++-
 1 file changed, 2 insertions(+), 1 deletion(-)
drivers/infiniband/ulp/opa_vnic/opa_vnic_encap.c +2 -1
@@ -351,7 +351,8 @@ static uint32_t opa_vnic_get_dlid(struct opa_vnic_adapter *adapter,if (unlikely (!dlid))v_warn ("Null dlid in MAC address\n" ); }else if (def_port !=OPA_VNIC_INVALID_PORT ) { - dlid = info->vesw.u_ucast_dlid[def_port]; +if (def_port <OPA_VESW_MAX_NUM_DEF_PORT ) + dlid = info->vesw.u_ucast_dlid[def_port]; } }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 21/209 iommu/io-pgtable-arm: Fix race handling in split_blk_unmap()
In reply to Sasha LevinFrom: Robin Murphy <[email protected]>
[ Upstream commit 85c7a0f1ef624ef58173ef52ea77780257bdfe04 ]
In removing the pagetable-wide lock, we gained the possibility of the vanishingly unlikely case where we have a race between two concurrent unmappers splitting the same block entry. The logic to handle this is fairly straightforward - whoever loses the race frees their partial next-level table and instead dereferences the winner's newly-installed entry in order to fall back to a regular unmap, which intentionally echoes the pre-existing case of recursively splitting a 1GB block down to 4KB pages by installing a full table of 2MB blocks first.
Unfortunately, the chump who implemented that logic failed to update the condition check for that fallback, meaning that if said race occurs at the last level (where the loser's unmap_idx is valid) then the unmap won't actually happen. Fix that to properly account for both the race and recursive cases.
---
 drivers/iommu/io-pgtable-arm.c | 9 ++++-----
 1 file changed, 4 insertions(+), 5 deletions(-)
drivers/iommu/io-pgtable-arm.c +4 -5
@@ -574,13 +574,12 @@ static size_t arm_lpae_split_blk_unmap(struct arm_lpae_io_pgtable *data,return 0 ; tablep =iopte_deref (pte, data); + }else if (unmap_idx >=0 ) { +io_pgtable_tlb_add_flush (&data->iop, iova, size, size, true); +return size; } -if (unmap_idx <0 ) -return __arm_lpae_unmap (data, iova, size, lvl, tablep); - -io_pgtable_tlb_add_flush (&data->iop, iova, size, size, true); -return size; +return __arm_lpae_unmap (data, iova, size, lvl, tablep); } static size_t __arm_lpae_unmap(struct arm_lpae_io_pgtable *data,
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 16/209 IB/hfi1: Error path MAD response size is incorrect
In reply to Sasha LevinFrom: "Michael J. Ruhl" <[email protected]>
[ Upstream commit 935c84ac649a147e1aad2c48ee5c5a1a9176b2d0 ]
If a MAD packet has incorrect header information, the logic uses the reply path to report the error. The reply path expects *resp_len to be set prior to return. Unfortunately, *resp_len is set to 0 for this path. This causes an incorrect response packet.
Fix by ensuring that the *resp_len is defaulted to the incoming packet size (wc->bytes_len - sizeof(GRH)).
---
 drivers/infiniband/hw/hfi1/mad.c | 4 ++--
 1 file changed, 2 insertions(+), 2 deletions(-)
drivers/infiniband/hw/hfi1/mad.c +2 -2
@@ -1,5 +1,5 @@/* -* Copyright(c) 2015-2017 Intel Corporation. +* Copyright(c) 2015-2018 Intel Corporation. * * This file is provided under a dual BSD/GPLv2 license. When using or * redistributing this file, you may do so under either license.
@@ -4829,7 +4829,7 @@ static int hfi1_process_opa_mad(struct ib_device *ibdev, int mad_flags,int ret;int pkey_idx;int local_mad =0 ; -u32 resp_len =0 ; +u32 resp_len = in_wc->byte_len -sizeof (*in_grh);struct hfi1_ibport *ibp =to_iport (ibdev, port); pkey_idx =hfi1_lookup_pkey_idx (ibp,LIM_MGMT_P_KEY );
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 23/209 kvm: arm/arm64: Fix stage2_flush_memslot for 4 level page table
In reply to Sasha LevinFrom: Suzuki K Poulose <[email protected]>
[ Upstream commit d2db7773ba864df6b4e19643dfc54838550d8049 ]
So far we have only supported 3 level page table with fixed IPA of 40bits, where PUD is folded. With 4 level page tables, we need to check if the PUD entry is valid or not. Fix stage2_flush_memslot() to do this check, before walking down the table.
---
 virt/kvm/arm/mmu.c | 3 ++-
 1 file changed, 2 insertions(+), 1 deletion(-)
virt/kvm/arm/mmu.c +2 -1
@@ -412,7 +412,8 @@ static void stage2_flush_memslot(struct kvm *kvm, pgd = kvm->arch.pgd +stage2_pgd_index (addr);do { next =stage2_pgd_addr_end (addr, end); -stage2_flush_puds (kvm, pgd, addr, next); +if (!stage2_pgd_none (*pgd)) +stage2_flush_puds (kvm, pgd, addr, next); }while (pgd++, addr = next, addr != end); }
Signature · 6 lines
2.20.1

_______________________________________________
kvmarm mailing list
[email protected]
https://lists.cs.columbia.edu/mailman/listinfo/kvmarm
Sasha Levin
maintainerPATCH 25/209 ath10k: fix vdev-start timeout on error
In reply to Sasha LevinFrom: Ben Greear <[email protected]>
[ Upstream commit 833fd34d743c728afe6d127ef7bee67e7d9199a8 ]
The vdev-start-response message should cause the completion to fire, even in the error case. Otherwise, the user still gets no useful information and everything is blocked until the timeout period.
Add some warning text to print out the invalid status code to aid debugging, and propagate failure code.
---
 drivers/net/wireless/ath/ath10k/core.h |  1 +
 drivers/net/wireless/ath/ath10k/mac.c  |  2 +-
 drivers/net/wireless/ath/ath10k/wmi.c  | 19 ++++++++++++++++---
 drivers/net/wireless/ath/ath10k/wmi.h  |  8 +++++++-
 4 files changed, 25 insertions(+), 5 deletions(-)
drivers/net/wireless/ath/ath10k/core.h +1 -0
@@ -1003,6 +1003,7 @@ struct ath10k {struct completion install_key_done; +int last_wmi_vdev_start_status;struct completion vdev_setup_done;struct workqueue_struct *workqueue;
drivers/net/wireless/ath/ath10k/mac.c +1 -1
@@ -967,7 +967,7 @@ static inline int ath10k_vdev_setup_sync(struct ath10k *ar)if (time_left ==0 )return -ETIMEDOUT ; -return 0 ; +return ar->last_wmi_vdev_start_status; }static int ath10k_monitor_vdev_start (struct ath10k *ar,int vdev_id)
drivers/net/wireless/ath/ath10k/wmi.c +16 -3
@@ -3247,18 +3247,31 @@ void ath10k_wmi_event_vdev_start_resp(struct ath10k *ar, struct sk_buff *skb) {struct wmi_vdev_start_ev_arg arg = {};int ret; +u32 status;ath10k_dbg (ar,ATH10K_DBG_WMI ,"WMI_VDEV_START_RESP_EVENTID\n" ); + ar->last_wmi_vdev_start_status =0 ; + ret =ath10k_wmi_pull_vdev_start (ar, skb, &arg);if (ret) {ath10k_warn (ar,"failed to parse vdev start event: %d\n" , ret); -return ; + ar->last_wmi_vdev_start_status = ret; + goto out; } -if (WARN_ON (__le32_to_cpu (arg.status))) -return ; + status =__le32_to_cpu (arg.status); +if (WARN_ON_ONCE (status)) { +ath10k_warn (ar,"vdev-start-response reports status error: %d (%s)\n" , + status, (status ==WMI_VDEV_START_CHAN_INVALID ) ? +"chan-invalid" :"unknown" ); +/* Setup is done one way or another though, so we should still +* do the completion, so don't return here. +*/ + ar->last_wmi_vdev_start_status = -EINVAL ; + } +out:complete (&ar->vdev_setup_done); }
drivers/net/wireless/ath/ath10k/wmi.h +7 -1
@@ -6642,11 +6642,17 @@ struct wmi_ch_info_ev_arg {__le32 rx_frame_count; }; +/* From 10.4 firmware, not sure all have the same values. */ +enum wmi_vdev_start_status { +WMI_VDEV_START_OK =0 , +WMI_VDEV_START_CHAN_INVALID , +}; +struct wmi_vdev_start_ev_arg {__le32 vdev_id;__le32 req_id;__le32 resp_type;/* %WMI_VDEV_RESP_ */ -__le32 status; +__le32 status;/* See wmi_vdev_start_status enum above */ };struct wmi_peer_kick_ev_arg {
Signature · 7 lines
2.20.1


_______________________________________________
ath10k mailing list
[email protected]
http://lists.infradead.org/mailman/listinfo/ath10k
Sasha Levin
maintainerPATCH 30/209 PM / devfreq: Fix handling of min/max_freq == 0
In reply to Sasha LevinFrom: Matthias Kaehlcke <[email protected]>
[ Upstream commit df5cf4a36178c5d4f2b8b9469cb2f722e64cd102 ]
Commit ab8f58ad72c4 ("PM / devfreq: Set min/max_freq when adding the devfreq device") initializes df->min/max_freq with the min/max OPP when the device is added. Later commit f1d981eaecf8 ("PM / devfreq: Use the available min/max frequency") adds df->scaling_min/max_freq and the following to the frequency adjustment code:
max_freq = MIN(devfreq->scaling_max_freq, devfreq->max_freq);
With the current handling of min/max_freq this is incorrect:
Even though df->max_freq is now initialized to a value != 0 user space can still set it to 0, in this case max_freq would be 0 instead of df->scaling_max_freq as intended. In consequence the frequency adjustment is not performed:
  if (max_freq && freq > max_freq) {
	freq = max_freq;
To fix this set df->min/max freq to the min/max OPP in max/max_freq_store, when the user passes a value of 0. This also prevents df->max_freq from being set below the min OPP when df->min_freq is 0, and similar for min_freq. Since it is now guaranteed that df->min/max_freq can't be 0 the checks for this case can be removed.
---
 drivers/devfreq/devfreq.c | 42 ++++++++++++++++++++++++++++-----------
 1 file changed, 30 insertions(+), 12 deletions(-)
drivers/devfreq/devfreq.c +30 -12
@@ -327,11 +327,11 @@ int update_devfreq(struct devfreq *devfreq) max_freq =MIN (devfreq->scaling_max_freq, devfreq->max_freq); min_freq =MAX (devfreq->scaling_min_freq, devfreq->min_freq); -if (min_freq && freq < min_freq) { +if (freq < min_freq) { freq = min_freq; flags &= ~DEVFREQ_FLAG_LEAST_UPPER_BOUND ;/* Use GLB */ } -if (max_freq && freq > max_freq) { +if (freq > max_freq) { freq = max_freq; flags |=DEVFREQ_FLAG_LEAST_UPPER_BOUND ;/* Use LUB */ }
@@ -1171,17 +1171,26 @@ static ssize_t min_freq_store(struct device *dev, struct device_attribute *attr,struct devfreq *df =to_devfreq (dev);unsigned long value;int ret; -unsigned long max; ret =sscanf (buf,"%lu" , &value);if (ret !=1 )return -EINVAL ;mutex_lock (&df->lock); - max = df->max_freq; -if (value && max && value > max) { - ret = -EINVAL ; - goto unlock; + +if (value) { +if (value > df->max_freq) { + ret = -EINVAL ; + goto unlock; + } + }else { +unsigned long *freq_table = df->profile->freq_table; + +/* Get minimum frequency according to sorting order */ +if (freq_table[0 ] < freq_table[df->profile->max_state -1 ]) + value = freq_table[0 ]; +else + value = freq_table[df->profile->max_state -1 ]; } df->min_freq = value;
@@ -1206,17 +1215,26 @@ static ssize_t max_freq_store(struct device *dev, struct device_attribute *attr,struct devfreq *df =to_devfreq (dev);unsigned long value;int ret; -unsigned long min; ret =sscanf (buf,"%lu" , &value);if (ret !=1 )return -EINVAL ;mutex_lock (&df->lock); - min = df->min_freq; -if (value && min && value < min) { - ret = -EINVAL ; - goto unlock; + +if (value) { +if (value < df->min_freq) { + ret = -EINVAL ; + goto unlock; + } + }else { +unsigned long *freq_table = df->profile->freq_table; + +/* Get maximum frequency according to sorting order */ +if (freq_table[0 ] < freq_table[df->profile->max_state -1 ]) + value = freq_table[df->profile->max_state -1 ]; +else + value = freq_table[0 ]; } df->max_freq = value;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 31/209 PM / devfreq: stopping the governor before device_unregister()
In reply to Sasha LevinFrom: Vincent Donnefort <[email protected]>
[ Upstream commit 2f061fd0c2d852e32e03a903fccd810663c5c31e ]
device_release() is freeing the resources before calling the device specific release callback which is, in the case of devfreq, stopping the governor.
It is a problem as some governors are using the device resources. e.g. simpleondemand which is using the devfreq deferrable monitoring work. If it is not stopped before the resources are freed, it might lead to a use after free.
---
 drivers/devfreq/devfreq.c | 9 ++++-----
 1 file changed, 4 insertions(+), 5 deletions(-)
drivers/devfreq/devfreq.c +4 -5
@@ -578,10 +578,6 @@ static void devfreq_dev_release(struct device *dev)list_del (&devfreq->node);mutex_unlock (&devfreq_list_lock); -if (devfreq->governor) - devfreq->governor->event_handler (devfreq, -DEVFREQ_GOV_STOP ,NULL ); -if (devfreq->profile->exit) devfreq->profile->exit (devfreq->dev.parent);
@@ -717,7 +713,7 @@ struct devfreq *devfreq_add_device(struct device *dev, err_init:mutex_unlock (&devfreq_list_lock); -device_unregister (&devfreq->dev); +devfreq_remove_device (devfreq); devfreq =NULL ; err_dev:if (devfreq)
@@ -738,6 +734,9 @@ int devfreq_remove_device(struct devfreq *devfreq)if (!devfreq)return -EINVAL ; +if (devfreq->governor) + devfreq->governor->event_handler (devfreq, +DEVFREQ_GOV_STOP ,NULL );device_unregister (&devfreq->dev);return 0 ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 33/209 selftests/tls: Fix recv(MSG_PEEK) & splice() test cases
In reply to Sasha LevinFrom: Vakul Garg <[email protected]>
[ Upstream commit 0ed3015c9964dab7a1693b3e40650f329c16691e ]
TLS test cases splice_from_pipe, send_and_splice & recv_peek_multiple_records expect to receive a given nummber of bytes and then compare them against the number of bytes which were sent. Therefore, system call recv() must not return before receiving the requested number of bytes, otherwise the subsequent memcmp() fails. This patch passes MSG_WAITALL flag to recv() so that it does not return prematurely before requested number of bytes are copied to receive buffer.
---
 tools/testing/selftests/net/tls.c | 20 ++++++++++----------
 1 file changed, 10 insertions(+), 10 deletions(-)
tools/testing/selftests/net/tls.c +10 -10
@@ -288,7 +288,7 @@ TEST_F(tls, splice_from_pipe)ASSERT_GE (pipe (p),0 );EXPECT_GE (write (p[1 ], mem_send, send_len),0 );EXPECT_GE (splice (p[0 ],NULL , self->fd,NULL , send_len,0 ),0 ); -EXPECT_GE (recv (self->cfd, mem_recv, send_len,0 ),0 ); +EXPECT_EQ (recv (self->cfd, mem_recv, send_len,MSG_WAITALL ), send_len);EXPECT_EQ (memcmp (mem_send, mem_recv, send_len),0 ); }
@@ -322,13 +322,13 @@ TEST_F(tls, send_and_splice)ASSERT_GE (pipe (p),0 );EXPECT_EQ (send (self->fd, test_str, send_len2,0 ), send_len2); -EXPECT_NE (recv (self->cfd, buf, send_len2,0 ),-1 ); +EXPECT_EQ (recv (self->cfd, buf, send_len2,MSG_WAITALL ), send_len2);EXPECT_EQ (memcmp (test_str, buf, send_len2),0 );EXPECT_GE (write (p[1 ], mem_send, send_len), send_len);EXPECT_GE (splice (p[0 ],NULL , self->fd,NULL , send_len,0 ), send_len); -EXPECT_GE (recv (self->cfd, mem_recv, send_len,0 ),0 ); +EXPECT_EQ (recv (self->cfd, mem_recv, send_len,MSG_WAITALL ), send_len);EXPECT_EQ (memcmp (mem_send, mem_recv, send_len),0 ); }
@@ -516,17 +516,17 @@ TEST_F(tls, recv_peek_multiple_records) len =strlen (test_str_second) +1 ;EXPECT_EQ (send (self->fd, test_str_second, len,0 ), len); - len =sizeof (buf); + len =strlen (test_str_first);memset (buf,0 , len); -EXPECT_NE (recv (self->cfd, buf, len,MSG_PEEK ),-1 ); +EXPECT_EQ (recv (self->cfd, buf, len,MSG_PEEK |MSG_WAITALL ), len);/* MSG_PEEK can only peek into the current record. */ - len =strlen (test_str_first) +1 ; + len =strlen (test_str_first);EXPECT_EQ (memcmp (test_str_first, buf, len),0 ); - len =sizeof (buf); + len =strlen (test_str) +1 ;memset (buf,0 , len); -EXPECT_NE (recv (self->cfd, buf, len,0 ),-1 ); +EXPECT_EQ (recv (self->cfd, buf, len,MSG_WAITALL ), len);/* Non-MSG_PEEK will advance strparser (and therefore record) * however.
@@ -543,9 +543,9 @@ TEST_F(tls, recv_peek_multiple_records) len =strlen (test_str_second) +1 ;EXPECT_EQ (send (self->fd, test_str_second, len,0 ), len); - len =sizeof (buf); + len =strlen (test_str) +1 ;memset (buf,0 , len); -EXPECT_NE (recv (self->cfd, buf, len,MSG_PEEK ),-1 ); +EXPECT_EQ (recv (self->cfd, buf, len,MSG_PEEK |MSG_WAITALL ), len); len =strlen (test_str) +1 ;EXPECT_EQ (memcmp (test_str, buf, len),0 );
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 28/209 ata: ahci_brcm: Allow using driver or DSL SoCs
In reply to Sasha LevinFrom: Florian Fainelli <[email protected]>
[ Upstream commit 7fb44929cb0e5cdcde143e1ca3ca57b5b8247db0 ]
The Broadcom STB AHCI controller is the same as the one found on DSL SoCs, so we will utilize the same driver on these systems as well.
---
 drivers/ata/Kconfig | 3 ++-
 1 file changed, 2 insertions(+), 1 deletion(-)
drivers/ata/Kconfig +2 -1
@@ -121,7 +121,8 @@ config SATA_AHCI_PLATFORM config AHCI_BRCM tristate "Broadcom AHCI SATA support" - depends on ARCH_BRCMSTB || BMIPS_GENERIC || ARCH_BCM_NSP + depends on ARCH_BRCMSTB || BMIPS_GENERIC || ARCH_BCM_NSP || \ + ARCH_BCM_63XX help This option enables support for the AHCI SATA3 controller found on Broadcom SoC's.
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 35/209 usb: dwc3: gadget: Check ENBLSLPM before sending ep command
In reply to Sasha LevinFrom: Thinh Nguyen <[email protected]>
[ Upstream commit 87dd96111b0bb8e616fcbd74dbf4bb4182f2c596 ]
When operating in USB 2.0 speeds (HS/FS), if GUSB2PHYCFG.ENBLSLPM or GUSB2PHYCFG.SUSPHY is set, it must be cleared before issuing an endpoint command.
Current implementation only save and restore GUSB2PHYCFG.SUSPHY configuration. We must save and clear both GUSB2PHYCFG.ENBLSLPM and GUSB2PHYCFG.SUSPHY settings. Restore them after the command is completed.
DWC_usb3 3.30a and DWC_usb31 1.90a programming guide section 3.2.2
---
 drivers/usb/dwc3/gadget.c | 29 +++++++++++++++++++----------
 1 file changed, 19 insertions(+), 10 deletions(-)
drivers/usb/dwc3/gadget.c +19 -10
@@ -271,27 +271,36 @@ int dwc3_send_gadget_ep_cmd(struct dwc3_ep *dep, unsigned cmd,const struct usb_endpoint_descriptor *desc = dep->endpoint.desc;struct dwc3 *dwc = dep->dwc;u32 timeout =1000 ; +u32 saved_config =0 ;u32 reg;int cmd_status =0 ; -int susphy = false;int ret = -EINVAL ;/* -* Synopsys Databook 2.60a states, on section 6.3.2.5.[1-8], that if -* we're issuing an endpoint command, we must check if -* GUSB2PHYCFG.SUSPHY bit is set. If it is, then we need to clear it. +* When operating in USB 2.0 speeds (HS/FS), if GUSB2PHYCFG.ENBLSLPM or +* GUSB2PHYCFG.SUSPHY is set, it must be cleared before issuing an +* endpoint command. * -* We will also set SUSPHY bit to what it was before returning as stated -* by the same section on Synopsys databook. +* Save and clear both GUSB2PHYCFG.ENBLSLPM and GUSB2PHYCFG.SUSPHY +* settings. Restore them after the command is completed. +* +* DWC_usb3 3.30a and DWC_usb31 1.90a programming guide section 3.2.2 */ if (dwc->gadget.speed <=USB_SPEED_HIGH ) { reg =dwc3_readl (dwc->regs,DWC3_GUSB2PHYCFG (0 ));if (unlikely (reg &DWC3_GUSB2PHYCFG_SUSPHY )) { - susphy = true; + saved_config |=DWC3_GUSB2PHYCFG_SUSPHY ; reg &= ~DWC3_GUSB2PHYCFG_SUSPHY ; -dwc3_writel (dwc->regs,DWC3_GUSB2PHYCFG (0 ), reg); } + +if (reg &DWC3_GUSB2PHYCFG_ENBLSLPM ) { + saved_config |=DWC3_GUSB2PHYCFG_ENBLSLPM ; + reg &= ~DWC3_GUSB2PHYCFG_ENBLSLPM ; + } + +if (saved_config) +dwc3_writel (dwc->regs,DWC3_GUSB2PHYCFG (0 ), reg); }if (DWC3_DEPCMD_CMD (cmd) ==DWC3_DEPCMD_STARTTRANSFER ) {
@@ -380,9 +389,9 @@ int dwc3_send_gadget_ep_cmd(struct dwc3_ep *dep, unsigned cmd,dwc3_gadget_ep_get_transfer_index (dep); } -if (unlikely (susphy)) { +if (saved_config) { reg =dwc3_readl (dwc->regs,DWC3_GUSB2PHYCFG (0 )); - reg |=DWC3_GUSB2PHYCFG_SUSPHY ; + reg |= saved_config;dwc3_writel (dwc->regs,DWC3_GUSB2PHYCFG (0 ), reg); }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 40/209 watchdog: sama5d4: fix timeout-sec usage
In reply to Sasha LevinFrom: Romain Izard <[email protected]>
[ Upstream commit 2e0432f8f8ad11b4bd208445360220efa5b37d82 ]
When using watchdog_init_timeout to update the default timeout value, an error means that there is no "timeout-sec" in the relevant device tree node.
This should not prevent binding of the driver to the device.
---
 drivers/watchdog/sama5d4_wdt.c | 6 +-----
 1 file changed, 1 insertion(+), 5 deletions(-)
drivers/watchdog/sama5d4_wdt.c +1 -5
@@ -247,11 +247,7 @@ static int sama5d4_wdt_probe(struct platform_device *pdev) } } - ret =watchdog_init_timeout (wdd, wdt_timeout, &pdev->dev); -if (ret) { -dev_err (&pdev->dev,"unable to set timeout value\n" ); -return ret; - } +watchdog_init_timeout (wdd, wdt_timeout, &pdev->dev); timeout =WDT_SEC2TICKS (wdd->timeout);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 32/209 ath9k: fix reporting calculated new FFT upper max
In reply to Sasha LevinFrom: Simon Wunderlich <[email protected]>
[ Upstream commit 4fb5837ac2bd46a85620b297002c704e9958f64d ]
Since the debug print code is outside of the loop, it shouldn't use the loop iterator anymore but instead print the found maximum index.
---
 drivers/net/wireless/ath/ath9k/common-spectral.c | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/net/wireless/ath/ath9k/common-spectral.c +1 -1
@@ -411,7 +411,7 @@ ath_cmn_process_ht20_40_fft(struct ath_rx_status *rs,ath_dbg (common,SPECTRAL_SCAN ,"Calculated new upper max 0x%X at %i\n" , - tmp_mag, i); + tmp_mag, fft_sample_40.upper_max_index); }else for (i = dc_pos; i <SPECTRAL_HT20_40_NUM_BINS ; i++) {if (fft_sample_40.data[i] == (upper_mag >> max_exp))
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 41/209 watchdog: w83627hf_wdt: Support NCT6796D, NCT6797D, NCT6798D
In reply to Sasha LevinFrom: Guenter Roeck <[email protected]>
[ Upstream commit 57cbf0e3a0fd48e5ad8f3884562e8dde4827c1c8 ]
The watchdog controller on NCT6796D, NCT6797D, and NCT6798D is compatible with the wtachdog controller on other Nuvoton chips.
---
 drivers/watchdog/w83627hf_wdt.c | 8 +++++++-
 1 file changed, 7 insertions(+), 1 deletion(-)
drivers/watchdog/w83627hf_wdt.c +7 -1
@@ -50,7 +50,7 @@ static int cr_wdt_csr; /* WDT control & status register */enum chips { w83627hf, w83627s, w83697hf, w83697ug, w83637hf, w83627thf, w83687thf, w83627ehf, w83627dhg, w83627uhg, w83667hg, w83627dhg_p, w83667hg_b, nct6775, nct6776, nct6779, nct6791, nct6792, nct6793, - nct6795, nct6102 }; + nct6795, nct6796, nct6102 };static int timeout;/* in seconds */ module_param (timeout, int,0 );
@@ -100,6 +100,7 @@ MODULE_PARM_DESC(early_disable, "Disable watchdog at boot time (default=0)");#define NCT6792_ID 0xc9#define NCT6793_ID 0xd1#define NCT6795_ID 0xd3 +#define NCT6796_ID 0xd4/* also NCT9697D, NCT9698D */ #define W83627HF_WDT_TIMEOUT 0xf6#define W83697HF_WDT_TIMEOUT 0xf4
@@ -209,6 +210,7 @@ static int w83627hf_init(struct watchdog_device *wdog, enum chips chip)case nct6792:case nct6793:case nct6795: +case nct6796:case nct6102:/* * These chips have a fixed WDTO# output pin (W83627UHG),
@@ -407,6 +409,9 @@ static int wdt_find(int addr)case NCT6795_ID : ret = nct6795;break ; +case NCT6796_ID : + ret = nct6796; +break ;case NCT6102_ID : ret = nct6102; cr_wdt_timeout =NCT6102D_WDT_TIMEOUT ;
@@ -450,6 +455,7 @@ static int __init wdt_init(void)"NCT6792" ,"NCT6793" ,"NCT6795" , +"NCT6796" , "NCT6102", };
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 22/209 iommu/arm-smmu-v3: Fix unexpected CMD_SYNC timeout
In reply to Sasha LevinFrom: Zhen Lei <[email protected]>
[ Upstream commit 0f02477d16980938a84aba8688a4e3a303306116 ]
The condition break condition of:
(int)(VAL - sync_idx) >= 0
in the __arm_smmu_sync_poll_msi() polling loop requires that sync_idx must be increased monotonically according to the sequence of the CMDs in the cmdq.
However, since the msidata is populated using atomic_inc_return_relaxed() before taking the command-queue spinlock, then the following scenario can occur:
CPU0 CPU1
msidata=0
msidata=1
insert cmd1
insert cmd0
smmu execute cmd1
smmu execute cmd0
			poll timeout, because msidata=1 is overridden by
			cmd0, that means VAL=0, sync_idx=1.
This is not a functional problem, since the caller will eventually either timeout or exit due to another CMD_SYNC, however it's clearly not what the code is supposed to be doing. Fix it, by incrementing the sequence count with the command-queue lock held, allowing us to drop the atomic operations altogether.
---
 drivers/iommu/arm-smmu-v3.c | 8 +++-----
 1 file changed, 3 insertions(+), 5 deletions(-)
drivers/iommu/arm-smmu-v3.c +3 -5
@@ -567,7 +567,7 @@ struct arm_smmu_device {int gerr_irq;int combined_irq; -atomic_t sync_nr; +u32 sync_nr;unsigned long ias;/* IPA */ unsigned long oas;/* PA */
@@ -964,14 +964,13 @@ static int __arm_smmu_cmdq_issue_sync_msi(struct arm_smmu_device *smmu)struct arm_smmu_cmdq_ent ent = { .opcode =CMDQ_OP_CMD_SYNC , .sync = { - .msidata =atomic_inc_return_relaxed (&smmu->sync_nr), .msiaddr =virt_to_phys (&smmu->sync_count), }, }; -arm_smmu_cmdq_build_cmd (cmd, &ent); -spin_lock_irqsave (&smmu->cmdq.lock, flags); + ent.sync.msidata = ++smmu->sync_nr; +arm_smmu_cmdq_build_cmd (cmd, &ent);arm_smmu_cmdq_insert_cmd (smmu, cmd);spin_unlock_irqrestore (&smmu->cmdq.lock, flags);
@@ -2196,7 +2195,6 @@ static int arm_smmu_init_structures(struct arm_smmu_device *smmu) {int ret; -atomic_set (&smmu->sync_nr,0 ); ret =arm_smmu_init_queues (smmu);if (ret)return ret;
Signature · 6 lines
2.20.1

_______________________________________________
iommu mailing list
[email protected]
https://lists.linuxfoundation.org/mailman/listinfo/iommu
Sasha Levin
maintainerPATCH 44/209 printk: CON_PRINTBUFFER console registration is a bit racy
In reply to Sasha LevinFrom: Sergey Senozhatsky <[email protected]>
[ Upstream commit 884e370ea88c109a3b982f4eb9ecd82510a3a1fe ]
CON_PRINTBUFFER console registration requires us to do several preparation steps:
- Rollback console_seq to replay logbuf messages which were already seen on other consoles;
- Set exclusive_console flag so console_unlock() will ->write() logbuf messages only to the exclusive_console driver.
The way we do it, however, is a bit racy
	logbuf_lock_irqsave(flags);
	console_seq = syslog_seq;
	console_idx = syslog_idx;
	logbuf_unlock_irqrestore(flags);
						<< preemption enabled
						<< irqs enabled
	exclusive_console = newcon;
	console_unlock();
We rollback console_seq under logbuf_lock with IRQs disabled, but we set exclusive_console with local IRQs enabled and logbuf unlocked. If the system oops-es or panic-s before we set exclusive_console - and given that we have IRQs and preemption enabled there is such a possibility - we will re-play all logbuf messages to every registered console, which may be a bit annoying and time consuming.
Move exclusive_console assignment to the same IRQs-disabled and logbuf_lock-protected section where we rollback console_seq.
To: Steven Rostedt <[email protected]>
---
 kernel/printk/printk.c | 6 +++++-
 1 file changed, 5 insertions(+), 1 deletion(-)
kernel/printk/printk.c +5 -1
@@ -2708,14 +2708,18 @@ void register_console(struct console *newcon)logbuf_lock_irqsave (flags); console_seq = syslog_seq; console_idx = syslog_idx; -logbuf_unlock_irqrestore (flags);/* * We're about to replay the log buffer. Only do this to the * just-registered console to avoid excessive message spam to * the already-registered consoles. +* +* Set exclusive_console with disabled interrupts to reduce +* race window with eventual console_flush_on_panic() that +* ignores console_lock. */ exclusive_console = newcon; exclusive_console_stop_seq = console_seq; +logbuf_unlock_irqrestore (flags); }console_unlock ();console_sysfs_notify ();
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 49/209 clk: keystone: Enable TISCI clocks if K3_ARCH
In reply to Sasha LevinFrom: Nishanth Menon <[email protected]>
[ Upstream commit 2f149e6e14bcb5e581e49307b54aafcd6f74a74f ]
K3_ARCH uses TISCI for clocks as well. Enable the same for the driver support.
---
 drivers/clk/Makefile         | 1 +
 drivers/clk/keystone/Kconfig | 2 +-
 2 files changed, 2 insertions(+), 1 deletion(-)
drivers/clk/Makefile +1 -0
@@ -73,6 +73,7 @@ obj-$(CONFIG_ARCH_HISI) += hisilicon/ obj-y += imgtec/ obj-$(CONFIG_ARCH_MXC) += imx/ obj-$(CONFIG_MACH_INGENIC) += ingenic/ +obj-$(CONFIG_ARCH_K3) += keystone/ obj-$(CONFIG_ARCH_KEYSTONE) += keystone/ obj-$(CONFIG_MACH_LOONGSON32) += loongson1/ obj-y += mediatek/
drivers/clk/keystone/Kconfig +1 -1
@@ -7,7 +7,7 @@ config COMMON_CLK_KEYSTONE config TI_SCI_CLK tristate "TI System Control Interface clock drivers" - depends on (ARCH_KEYSTONE || COMPILE_TEST) && OF + depends on (ARCH_KEYSTONE || ARCH_K3 || COMPILE_TEST) && OF depends on TI_SCI_PROTOCOL default ARCH_KEYSTONE ---help---
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 51/209 x86/PCI: Apply VMD's AERSID fixup generically
In reply to Sasha LevinFrom: Jon Derrick <[email protected]>
[ Upstream commit 4f475e8e0a6d4f5d430350d1f74f7e4899fb1692 ]
A root port Device ID changed between simulation and production. Rather than match Device IDs which may not be future-proof if left unmaintained, match all root ports which exist in a VMD domain.
---
 arch/x86/pci/fixup.c | 12 +++---------
 1 file changed, 3 insertions(+), 9 deletions(-)
arch/x86/pci/fixup.c +3 -9
@@ -629,17 +629,11 @@ DECLARE_PCI_FIXUP_HEADER(PCI_VENDOR_ID_INTEL, 0x8c10, quirk_apple_mbp_poweroff);static void quirk_no_aersid (struct pci_dev *pdev) {/* VMD Domain */ -if (is_vmd (pdev->bus)) +if (is_vmd (pdev->bus) &&pci_is_root_bus (pdev->bus)) pdev->bus->bus_flags |=PCI_BUS_FLAGS_NO_AERSID ; } -DECLARE_PCI_FIXUP_EARLY (PCI_VENDOR_ID_INTEL ,0x2030 , quirk_no_aersid); -DECLARE_PCI_FIXUP_EARLY (PCI_VENDOR_ID_INTEL ,0x2031 , quirk_no_aersid); -DECLARE_PCI_FIXUP_EARLY (PCI_VENDOR_ID_INTEL ,0x2032 , quirk_no_aersid); -DECLARE_PCI_FIXUP_EARLY (PCI_VENDOR_ID_INTEL ,0x2033 , quirk_no_aersid); -DECLARE_PCI_FIXUP_EARLY (PCI_VENDOR_ID_INTEL ,0x334a , quirk_no_aersid); -DECLARE_PCI_FIXUP_EARLY (PCI_VENDOR_ID_INTEL ,0x334b , quirk_no_aersid); -DECLARE_PCI_FIXUP_EARLY (PCI_VENDOR_ID_INTEL ,0x334c , quirk_no_aersid); -DECLARE_PCI_FIXUP_EARLY (PCI_VENDOR_ID_INTEL ,0x334d , quirk_no_aersid); +DECLARE_PCI_FIXUP_CLASS_EARLY (PCI_VENDOR_ID_INTEL ,PCI_ANY_ID , +PCI_CLASS_BRIDGE_PCI ,8 , quirk_no_aersid);static void quirk_intel_th_dnv (struct pci_dev *dev) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 53/209 cxgb4: Use proper enum in cxgb4_dcb_handle_fw_update
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit 3b0b8f0d9a259f6a428af63e7a77547325f8e081 ]
Clang warns when one enumerated type is implicitly converted to another.
drivers/net/ethernet/chelsio/cxgb4/cxgb4_dcb.c:303:7: warning: implicit conversion from enumeration type 'enum cxgb4_dcb_state' to different enumeration type 'enum cxgb4_dcb_state_input' [-Wenum-conversion]
                         ? CXGB4_DCB_STATE_FW_ALLSYNCED
                           ^~~~~~~~~~~~~~~~~~~~~~~~~~~~
drivers/net/ethernet/chelsio/cxgb4/cxgb4_dcb.c:304:7: warning: implicit
conversion from enumeration type 'enum cxgb4_dcb_state' to different
enumeration type 'enum cxgb4_dcb_state_input' [-Wenum-conversion]
                         : CXGB4_DCB_STATE_FW_INCOMPLETE);
                           ^~~~~~~~~~~~~~~~~~~~~~~~~~~~~
2 warnings generated.
Use the equivalent value of the expected type to silence Clang while resulting in no functional change.
CXGB4_DCB_STATE_FW_INCOMPLETE = CXGB4_DCB_INPUT_FW_INCOMPLETE = 2 CXGB4_DCB_STATE_FW_ALLSYNCED = CXGB4_DCB_INPUT_FW_ALLSYNCED = 3
---
 drivers/net/ethernet/chelsio/cxgb4/cxgb4_dcb.c | 4 ++--
 1 file changed, 2 insertions(+), 2 deletions(-)
drivers/net/ethernet/chelsio/cxgb4/cxgb4_dcb.c +2 -2
@@ -273,8 +273,8 @@ void cxgb4_dcb_handle_fw_update(struct adapter *adap,enum cxgb4_dcb_state_input input = ((pcmd->u.dcb.control.all_syncd_pkd &FW_PORT_CMD_ALL_SYNCD_F ) - ?CXGB4_DCB_STATE_FW_ALLSYNCED - :CXGB4_DCB_STATE_FW_INCOMPLETE ); + ?CXGB4_DCB_INPUT_FW_ALLSYNCED + :CXGB4_DCB_INPUT_FW_INCOMPLETE );if (dcb->dcb_version !=FW_PORT_DCB_VER_UNKNOWN ) { dcb_running_version = FW_PORT_CMD_DCB_VERSION_G(
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 54/209 cxgb4: Use proper enum in IEEE_FAUX_SYNC
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit 258b6d141878530ba1f8fc44db683822389de914 ]
Clang warns when one enumerated type is implicitly converted to another.
drivers/net/ethernet/chelsio/cxgb4/cxgb4_dcb.c:390:4: warning: implicit conversion from enumeration type 'enum cxgb4_dcb_state' to different enumeration type 'enum cxgb4_dcb_state_input' [-Wenum-conversion]
                        IEEE_FAUX_SYNC(dev, dcb);
                        ^~~~~~~~~~~~~~~~~~~~~~~~
drivers/net/ethernet/chelsio/cxgb4/cxgb4_dcb.h:70:10: note: expanded
from macro 'IEEE_FAUX_SYNC'
                                            CXGB4_DCB_STATE_FW_ALLSYNCED);
                                            ^~~~~~~~~~~~~~~~~~~~~~~~~~~~
Use the equivalent value of the expected type to silence Clang while resulting in no functional change.
CXGB4_DCB_STATE_FW_ALLSYNCED = CXGB4_DCB_INPUT_FW_ALLSYNCED = 3
---
 drivers/net/ethernet/chelsio/cxgb4/cxgb4_dcb.h | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/net/ethernet/chelsio/cxgb4/cxgb4_dcb.h +1 -1
@@ -67,7 +67,7 @@do { \if ((__dcb)->dcb_version ==FW_PORT_DCB_VER_IEEE ) \cxgb4_dcb_state_fsm ((__dev), \ -CXGB4_DCB_STATE_FW_ALLSYNCED ); \ +CXGB4_DCB_INPUT_FW_ALLSYNCED ); \ }while (0 )/* States we can be in for a port's Data Center Bridging.
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 55/209 powerpc/pseries: Fix DTL buffer registration
In reply to Sasha LevinFrom: "Naveen N. Rao" <[email protected]>
[ Upstream commit db787af1b8a6b4be428ee2ea7d409dafcaa4a43c ]
When CONFIG_VIRT_CPU_ACCOUNTING_NATIVE is not set, we register the DTL buffer for a cpu when the associated file under powerpc/dtl in debugfs is opened. When doing so, we need to set the size of the buffer being registered in the second u32 word of the buffer. This needs to be in big endian, but we are not doing the conversion resulting in the below error showing up in dmesg:
dtl_start: DTL registration for cpu 0 (hw 0) failed with -4
Fix this in the obvious manner.
---
 arch/powerpc/platforms/pseries/dtl.c | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
arch/powerpc/platforms/pseries/dtl.c +1 -1
@@ -149,7 +149,7 @@ static int dtl_start(struct dtl *dtl)/* Register our dtl buffer with the hypervisor. The HV expects the * buffer size to be passed in the second word of the buffer */ - ((u32 *)dtl->buf)[1 ] =DISPATCH_LOG_BYTES ; + ((u32 *)dtl->buf)[1 ] =cpu_to_be32 (DISPATCH_LOG_BYTES ); hwcpu =get_hard_smp_processor_id (dtl->cpu); addr =__pa (dtl->buf);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 56/209 powerpc/pseries: Fix how we iterate over the DTL entries
In reply to Sasha LevinFrom: "Naveen N. Rao" <[email protected]>
[ Upstream commit 9258227e9dd1da8feddb07ad9702845546a581c9 ]
When CONFIG_VIRT_CPU_ACCOUNTING_NATIVE is not set, we look up dtl_idx in the lppaca to determine the number of entries in the buffer. Since lppaca is in big endian, we need to do an endian conversion before using this in our calculation to determine the number of entries in the buffer. Without this, we do not iterate over the existing entries in the DTL buffer properly.
---
 arch/powerpc/platforms/pseries/dtl.c | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
arch/powerpc/platforms/pseries/dtl.c +1 -1
@@ -184,7 +184,7 @@ static void dtl_stop(struct dtl *dtl)static u64 dtl_current_index (struct dtl *dtl) { -return lppaca_of (dtl->cpu).dtl_idx; +return be64_to_cpu (lppaca_of (dtl->cpu).dtl_idx); }#endif /* CONFIG_VIRT_CPU_ACCOUNTING_NATIVE */
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 59/209 ARM: dts: at91: at91sam9x5cm: fix addressable nand flash size
In reply to Sasha LevinFrom: Tudor Ambarus <[email protected]>
[ Upstream commit 6f270d88a0c4a11725afd8fd2001ae408733afbf ]
at91sam9x5cm comes with a 2Gb NAND flash. Fix the rootfs size to match this limit.
---
 arch/arm/boot/dts/at91sam9x5cm.dtsi | 2 +-
 1 file changed, 1 insertion(+), 1 deletion(-)
arch/arm/boot/dts/at91sam9x5cm.dtsi +1 -1
@@ -100,7 +100,7 @@ rootfs@800000 { label = "rootfs"; - reg = <0x800000 0x1f800000>; + reg = <0x800000 0x0f800000>; }; }; };
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 61/209 mtd: rawnand: sh_flctl: Use proper enum for flctl_dma_fifo0_transfer
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit e2bfa4ca23d9b5a7bdfcf21319fad9b59e38a05c ]
Clang warns when one enumerated type is converted implicitly to another:
drivers/mtd/nand/raw/sh_flctl.c:483:46: warning: implicit conversion from enumeration type 'enum dma_transfer_direction' to different enumeration type 'enum dma_data_direction' [-Wenum-conversion]
flctl_dma_fifo0_transfer(flctl, buf, rlen, DMA_DEV_TO_MEM) > 0) ~~~~~~~~~~~~~~~~~~~~~~~~^~~~~~~~~~~~~~drivers/mtd/nand/raw/sh_flctl.c:542:46: warning: implicit conversion from enumeration type 'enum dma_transfer_direction' to different enumeration type 'enum dma_data_direction' [-Wenum-conversion]
flctl_dma_fifo0_transfer(flctl, buf, rlen, DMA_MEM_TO_DEV) > 0) ~~~~~~~~~~~~~~~~~~~~~~~~^~~~~~~~~~~~~~
2 warnings generated.
Use the proper enums from dma_data_direction to satisfy Clang.
DMA_MEM_TO_DEV = DMA_TO_DEVICE = 1DMA_DEV_TO_MEM = DMA_FROM_DEVICE = 2
---
 drivers/mtd/nand/raw/sh_flctl.c | 4 ++--
 1 file changed, 2 insertions(+), 2 deletions(-)
drivers/mtd/nand/raw/sh_flctl.c +2 -2
@@ -480,7 +480,7 @@ static void read_fiforeg(struct sh_flctl *flctl, int rlen, int offset)/* initiate DMA transfer */ if (flctl->chan_fifo0_rx && rlen >=32 && -flctl_dma_fifo0_transfer (flctl, buf, rlen,DMA_DEV_TO_MEM ) >0 ) +flctl_dma_fifo0_transfer (flctl, buf, rlen,DMA_FROM_DEVICE ) >0 ) goto convert;/* DMA success */ /* do polling transfer */
@@ -539,7 +539,7 @@ static void write_ec_fiforeg(struct sh_flctl *flctl, int rlen,/* initiate DMA transfer */ if (flctl->chan_fifo0_tx && rlen >=32 && -flctl_dma_fifo0_transfer (flctl, buf, rlen,DMA_MEM_TO_DEV ) >0 ) +flctl_dma_fifo0_transfer (flctl, buf, rlen,DMA_TO_DEVICE ) >0 )return ;/* DMA success */ /* do polling transfer */
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 62/209 PM / hibernate: Check the success of generating md5 digest before hibernation
In reply to Sasha LevinFrom: Chen Yu <[email protected]>
[ Upstream commit 749fa17093ff67b31dea864531a3698b6a95c26c ]
Currently if get_e820_md5() fails, then it will hibernate nevertheless. Actually the error code should be propagated to upper caller so that the hibernation could be aware of the result and terminates the process if md5 digest fails.
---
 arch/x86/power/hibernate_64.c | 11 +++++------
 1 file changed, 5 insertions(+), 6 deletions(-)
arch/x86/power/hibernate_64.c +5 -6
@@ -266,9 +266,9 @@ static int get_e820_md5(struct e820_table *table, void *buf)return ret; } -static void hibernation_e820_save (void *buf) +static int hibernation_e820_save (void *buf) { -get_e820_md5 (e820_table_firmware, buf); +return get_e820_md5 (e820_table_firmware, buf); }static bool hibernation_e820_mismatch (void *buf)
@@ -288,8 +288,9 @@ static bool hibernation_e820_mismatch(void *buf) return memcmp(result, buf, MD5_DIGEST_SIZE) ? true : false; }#else -static void hibernation_e820_save (void *buf) +static int hibernation_e820_save (void *buf) { +return 0 ; }static bool hibernation_e820_mismatch (void *buf)
@@ -334,9 +335,7 @@ int arch_hibernation_header_save(void *addr, unsigned int max_size) rdr->magic =RESTORE_MAGIC ; -hibernation_e820_save (rdr->e820_digest); - -return 0 ; +return hibernation_e820_save (rdr->e820_digest); }/**
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 65/209 clocksource/drivers/sh_cmt: Fix clocksource width for 32-bit machines
In reply to Sasha LevinFrom: Sergei Shtylyov <[email protected]>
[ Upstream commit 37e7742c55ba856eaec7e35673ee370f36eb17f3 ]
The driver seems to abuse *unsigned long* not only for the (32-bit) register values but also for the 'sh_cmt_channel::total_cycles' which needs to always be 64-bit -- as a result, the clocksource's mask is needlessly clamped down to 32-bits on the 32-bit machines...
--- drivers/clocksource/sh_cmt.c | 6 +++--- 1 file changed, 3 insertions(+), 3 deletions(-)
drivers/clocksource/sh_cmt.c +3 -3
@@ -108,7 +108,7 @@ struct sh_cmt_channel {raw_spinlock_t lock;struct clock_event_device ced;struct clocksource cs; -unsigned long total_cycles; +u64 total_cycles;bool cs_enabled; };
@@ -613,8 +613,8 @@ static u64 sh_cmt_clocksource_read(struct clocksource *cs) {struct sh_cmt_channel *ch =cs_to_sh_cmt (cs);unsigned long flags; -unsigned long value;u32 has_wrapped; +u64 value;u32 raw;raw_spin_lock_irqsave (&ch->lock, flags);
@@ -688,7 +688,7 @@ static int sh_cmt_register_clocksource(struct sh_cmt_channel *ch, cs->disable = sh_cmt_clocksource_disable; cs->suspend = sh_cmt_clocksource_suspend; cs->resume = sh_cmt_clocksource_resume; - cs->mask =CLOCKSOURCE_MASK (sizeof (unsigned long ) *8 ); + cs->mask =CLOCKSOURCE_MASK (sizeof (u64) *8 ); cs->flags =CLOCK_SOURCE_IS_CONTINUOUS ; dev_info(&ch->cmt->pdev->dev, "ch%u: used as clock source\n",
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 66/209 ice: Fix forward to queue group logic
In reply to Sasha LevinFrom: Anirudh Venkataramanan <[email protected]>
[ Upstream commit be8ff000bf83e658e63ab64cf4d2755abc5add5b ]
When adding a rule, queue region size needs to be provided as log base 2 of the number of queues in region. Fix that.
--- drivers/net/ethernet/intel/ice/ice_switch.c | 14 ++++++++++---- 1 file changed, 10 insertions(+), 4 deletions(-)
drivers/net/ethernet/intel/ice/ice_switch.c +10 -4
@@ -468,6 +468,7 @@ ice_fill_sw_rule(struct ice_hw *hw, struct ice_fltr_info *f_info,void *daddr =NULL ;u32 act =0 ;__be16 *off; +u8 q_rgn;if (opc == ice_aqc_opc_remove_sw_rules) { s_rule->pdata.lkup_tx_rx.act =0 ;
@@ -503,14 +504,19 @@ ice_fill_sw_rule(struct ice_hw *hw, struct ice_fltr_info *f_info, act |= (f_info->fwd_id.q_id <<ICE_SINGLE_ACT_Q_INDEX_S ) &ICE_SINGLE_ACT_Q_INDEX_M ;break ; +case ICE_DROP_PACKET : + act |=ICE_SINGLE_ACT_VSI_FORWARDING |ICE_SINGLE_ACT_DROP | +ICE_SINGLE_ACT_VALID_BIT ; +break ;case ICE_FWD_TO_QGRP : + q_rgn = f_info->qgrp_size >0 ? + (u8 )ilog2 (f_info->qgrp_size) :0 ; act |=ICE_SINGLE_ACT_TO_Q ; - act |= (f_info->qgrp_size <<ICE_SINGLE_ACT_Q_REGION_S ) & + act |= (f_info->fwd_id.q_id <<ICE_SINGLE_ACT_Q_INDEX_S ) & +ICE_SINGLE_ACT_Q_INDEX_M ; + act |= (q_rgn <<ICE_SINGLE_ACT_Q_REGION_S ) &ICE_SINGLE_ACT_Q_REGION_M ;break ; -case ICE_DROP_PACKET : - act |=ICE_SINGLE_ACT_VSI_FORWARDING |ICE_SINGLE_ACT_DROP ; -break ;default :return ; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 70/209 ixgbe: Fix crash with VFs and flow director on interface flap
In reply to Sasha LevinFrom: Radoslaw Tyl <[email protected]>
[ Upstream commit 5d826d209164b0752c883607be4cdbbcf7cab494 ]
This patch fix crash when we have restore flow director filters after reset adapter. In ixgbe_fdir_filter_restore() filter->action is outside of the rx_ring array, as it has a VF identifier in the upper 32 bits.
--- drivers/net/ethernet/intel/ixgbe/ixgbe_main.c | 10 ++++++++-- 1 file changed, 8 insertions(+), 2 deletions(-)
drivers/net/ethernet/intel/ixgbe/ixgbe_main.c +8 -2
@@ -5187,6 +5187,7 @@ static void ixgbe_fdir_filter_restore(struct ixgbe_adapter *adapter)struct ixgbe_hw *hw = &adapter->hw;struct hlist_node *node2;struct ixgbe_fdir_filter *filter; +u64 action;spin_lock (&adapter->fdir_perfect_lock);
@@ -5195,12 +5196,17 @@ static void ixgbe_fdir_filter_restore(struct ixgbe_adapter *adapter)hlist_for_each_entry_safe (filter, node2, &adapter->fdir_filter_list, fdir_node) { + action = filter->action; +if (action !=IXGBE_FDIR_DROP_QUEUE && action !=0 ) + action = + (action >>ETHTOOL_RX_FLOW_SPEC_RING_VF_OFF ) -1 ; +ixgbe_fdir_write_perfect_filter_82599 (hw, &filter->filter, filter->sw_idx, - (filter->action ==IXGBE_FDIR_DROP_QUEUE ) ? + (action ==IXGBE_FDIR_DROP_QUEUE ) ?IXGBE_FDIR_DROP_QUEUE : - adapter->rx_ring[filter->action]->reg_idx); + adapter->rx_ring[action]->reg_idx); }spin_unlock (&adapter->fdir_perfect_lock);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 68/209 ixgbe: Fix ixgbe TX hangs with XDP_TX beyond queue limit
In reply to Sasha LevinFrom: Radoslaw Tyl <[email protected]>
[ Upstream commit 8d7179b1e2d64b3493c0114916486fe92e6109a9 ]
We have Tx hang when number Tx and XDP queues are more than 64. In XDP always is MTQC == 0x0 (64TxQs). We need more space for Tx queues.
--- drivers/net/ethernet/intel/ixgbe/ixgbe_main.c | 14 ++++++++++---- 1 file changed, 10 insertions(+), 4 deletions(-)
drivers/net/ethernet/intel/ixgbe/ixgbe_main.c +10 -4
@@ -3582,12 +3582,18 @@ static void ixgbe_setup_mtqc(struct ixgbe_adapter *adapter)else mtqc |=IXGBE_MTQC_64VF ; }else { -if (tcs >4 ) +if (tcs >4 ) { mtqc =IXGBE_MTQC_RT_ENA |IXGBE_MTQC_8TC_8TQ ; -else if (tcs >1 ) + }else if (tcs >1 ) { mtqc =IXGBE_MTQC_RT_ENA |IXGBE_MTQC_4TC_4TQ ; -else - mtqc =IXGBE_MTQC_64Q_1PB ; + }else { +u8 max_txq = adapter->num_tx_queues + + adapter->num_xdp_queues; +if (max_txq >63 ) + mtqc =IXGBE_MTQC_RT_ENA |IXGBE_MTQC_4TC_4TQ ; +else + mtqc =IXGBE_MTQC_64Q_1PB ; + } }IXGBE_WRITE_REG (hw,IXGBE_MTQC , mtqc);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 72/209 IB/rxe: avoid srq memory leak
In reply to Sasha LevinFrom: Zhu Yanjun <[email protected]>
[ Upstream commit aae0484e15f062ad2c2502e68e15dfb8b8f84608 ]
In rxe_queue_init, q and q->buf are allocated. In do_mmap_info, q->ip is allocated. When error occurs, rxe_srq_from_init and the later error handler do not free these allocated memories. This will make memory leak.
--- drivers/infiniband/sw/rxe/rxe_srq.c | 10 ++++++++-- 1 file changed, 8 insertions(+), 2 deletions(-)
drivers/infiniband/sw/rxe/rxe_srq.c +8 -2
@@ -31,6 +31,7 @@* SOFTWARE. */ +#include <linux/vmalloc.h> #include "rxe.h" #include "rxe_loc.h" #include "rxe_queue.h"
@@ -129,13 +130,18 @@ int rxe_srq_from_init(struct rxe_dev *rxe, struct rxe_srq *srq, err =do_mmap_info (rxe, uresp ? &uresp->mi :NULL , context, q->buf, q->buf_size, &q->ip); -if (err) +if (err) { +vfree (q->buf); +kfree (q);return err; + }if (uresp) {if (copy_to_user (&uresp->srq_num, &srq->srq_num, -sizeof (uresp->srq_num))) +sizeof (uresp->srq_num))) { +rxe_queue_cleanup (q);return -EFAULT ; + } }return 0 ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 77/209 IB/mlx4: Avoid implicit enumerated type conversion
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit b56511c15713ba6c7572e77a41f7ddba9c1053ec ]
Clang warns when one enumerated type is implicitly converted to another.
drivers/infiniband/hw/mlx4/mad.c:1811:41: warning: implicit conversion from enumeration type 'enum mlx4_ib_qp_flags' to different enumeration type 'enum ib_qp_create_flags' [-Wenum-conversion]
qp_init_attr.init_attr.create_flags = MLX4_IB_SRIOV_TUNNEL_QP;
~ ^~~~~~~~~~~~~~~~~~~~~~~drivers/infiniband/hw/mlx4/mad.c:1819:41: warning: implicit conversion from enumeration type 'enum mlx4_ib_qp_flags' to different enumeration type 'enum ib_qp_create_flags' [-Wenum-conversion]
qp_init_attr.init_attr.create_flags = MLX4_IB_SRIOV_SQP;
~ ^~~~~~~~~~~~~~~~~The type mlx4_ib_qp_flags explicitly provides supplemental values to the type ib_qp_create_flags. Make that clear to Clang by changing the create_flags type to u32.
--- include/rdma/ib_verbs.h | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
include/rdma/ib_verbs.h +1 -1
@@ -1147,7 +1147,7 @@ struct ib_qp_init_attr {struct ib_qp_cap cap;enum ib_sig_type sq_sig_type;enum ib_qp_type qp_type; -enum ib_qp_create_flags create_flags; +u32 create_flags;/* * Only needed for special QP types, or when using the RW API.
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 80/209 OPP: Return error on error from dev_pm_opp_get_opp_count()
In reply to Sasha LevinFrom: Viresh Kumar <[email protected]>
[ Upstream commit 09f662f95306f3e3d47ab6842bc4b0bb868a80ad ]
Return error number instead of 0 on failures.
--- drivers/opp/core.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/opp/core.c +1 -1
@@ -313,7 +313,7 @@ int dev_pm_opp_get_opp_count(struct device *dev) count =PTR_ERR (opp_table);dev_dbg (dev,"%s: OPP table not found (%d)\n" , __func__, count); -return 0 ; +return count; } count =_get_opp_count (opp_table);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 81/209 ACPICA: Never run _REG on system_memory and system_IO
In reply to Sasha LevinFrom: Bob Moore <[email protected]>
[ Upstream commit 8b1cafdcb4b75c5027c52f1e82b47ebe727ad7ed ]
These address spaces are defined by the ACPI spec to be "always available", and thus _REG should never be run on them. Provides compatibility with other ACPI implementations.
--- drivers/acpi/acpica/acevents.h | 2 ++ drivers/acpi/acpica/aclocal.h | 2 +- drivers/acpi/acpica/evregion.c | 17 +++++++++++++++-- drivers/acpi/acpica/evrgnini.c | 6 +----- drivers/acpi/acpica/evxfregn.c | 1 - 5 files changed, 19 insertions(+), 9 deletions(-)
drivers/acpi/acpica/acevents.h +2 -0
@@ -230,6 +230,8 @@ acpi_ev_default_region_setup(acpi_handle handle,acpi_status acpi_ev_initialize_region (union acpi_operand_object *region_obj); +u8 acpi_ev_is_pci_root_bridge (struct acpi_namespace_node *node); +/* * evsci - SCI (System Control Interrupt) handling/dispatch */
drivers/acpi/acpica/aclocal.h +1 -1
@@ -395,9 +395,9 @@ struct acpi_simple_repair_info {/* Info for running the _REG methods */ struct acpi_reg_walk_info { -acpi_adr_space_type space_id;u32 function;u32 reg_run_count; +acpi_adr_space_type space_id; };/*****************************************************************************
drivers/acpi/acpica/evregion.c +15 -2
@@ -653,6 +653,19 @@ acpi_ev_execute_reg_methods(struct acpi_namespace_node *node,ACPI_FUNCTION_TRACE (ev_execute_reg_methods); +/* +* These address spaces do not need a call to _REG, since the ACPI +* specification defines them as: "must always be accessible". Since +* they never change state (never become unavailable), no need to ever +* call _REG on them. Also, a data_table is not a "real" address space, +* so do not call _REG. September 2018. +*/ +if ((space_id ==ACPI_ADR_SPACE_SYSTEM_MEMORY ) || + (space_id ==ACPI_ADR_SPACE_SYSTEM_IO ) || + (space_id ==ACPI_ADR_SPACE_DATA_TABLE )) { + return_VOID; + } + info.space_id = space_id; info.function = function; info.reg_run_count =0 ;
@@ -714,8 +727,8 @@ acpi_ev_reg_run(acpi_handle obj_handle, }/* -* We only care about regions.and objects that are allowed to have address -* space handlers +* We only care about regions and objects that are allowed to have +* address space handlers */ if ((node->type !=ACPI_TYPE_REGION ) && (node != acpi_gbl_root_node)) {return (AE_OK );
drivers/acpi/acpica/evrgnini.c +1 -5
@@ -16,9 +16,6 @@#define _COMPONENT ACPI_EVENTSACPI_MODULE_NAME ("evrgnini" ) -/* Local prototypes */ -static u8 acpi_ev_is_pci_root_bridge (struct acpi_namespace_node *node); -/******************************************************************************* * * FUNCTION: acpi_ev_system_memory_region_setup
@@ -33,7 +30,6 @@ static u8 acpi_ev_is_pci_root_bridge(struct acpi_namespace_node *node);* DESCRIPTION: Setup a system_memory operation region * ******************************************************************************/ - acpi_status acpi_ev_system_memory_region_setup(acpi_handle handle, u32 function,
@@ -313,7 +309,7 @@ acpi_ev_pci_config_region_setup(acpi_handle handle,* ******************************************************************************/ -static u8 acpi_ev_is_pci_root_bridge (struct acpi_namespace_node *node) +u8 acpi_ev_is_pci_root_bridge (struct acpi_namespace_node *node) {acpi_status status;struct acpi_pnp_device_id *hid;
drivers/acpi/acpica/evxfregn.c +0 -1
@@ -193,7 +193,6 @@ acpi_remove_address_space_handler(acpi_handle device,*/ region_obj = handler_obj->address_space.region_list; - }/* Remove this Handler object from the list */
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 82/209 cpuidle: menu: Fix wakeup statistics updates for polling state
In reply to Sasha LevinFrom: "Rafael J. Wysocki" <[email protected]>
[ Upstream commit 5f26bdceb9c0a5e6c696aa2899d077cd3ae93413 ]
If the CPU exits the "polling" state due to the time limit in the loop in poll_idle(), this is not a real wakeup and it just means that the "polling" state selection was not adequate. The governor mispredicted short idle duration, but had a more suitable state been selected, the CPU might have spent more time in it. In fact, there is no reason to expect that there would have been a wakeup event earlier than the next timer in that case.
Handling such cases as regular wakeups in menu_update() may cause the menu governor to make suboptimal decisions going forward, but ignoring them altogether would not be correct either, because every time menu_select() is invoked, it makes a separate new attempt to predict the idle duration taking distinct time to the closest timer event as input and the outcomes of all those attempts should be recorded.
For this reason, make menu_update() always assume that if the "polling" state was exited due to the time limit, the next proper wakeup event for the CPU would be the next timer event (not including the tick).
--- drivers/cpuidle/governors/menu.c | 10 ++++++++++ drivers/cpuidle/poll_state.c | 6 +++++- include/linux/cpuidle.h | 1 + 3 files changed, 16 insertions(+), 1 deletion(-)
drivers/cpuidle/governors/menu.c +10 -0
@@ -512,6 +512,16 @@ static void menu_update(struct cpuidle_driver *drv, struct cpuidle_device *dev)* duration predictor do a better job next time. */ measured_us =9 *MAX_INTERESTING /10 ; + }else if ((drv->states[last_idx].flags &CPUIDLE_FLAG_POLLING ) && + dev->poll_time_limit) { +/* +* The CPU exited the "polling" state due to a time limit, so +* the idle duration prediction leading to the selection of that +* state was inaccurate. If a better prediction had been made, +* the CPU might have been woken up from idle by the next timer. +* Assume that to be the case. +*/ + measured_us = data->next_timer_us; }else {/* measured value */ measured_us =cpuidle_get_last_residency (dev);
drivers/cpuidle/poll_state.c +5 -1
@@ -17,6 +17,8 @@ static int __cpuidle poll_idle(struct cpuidle_device *dev, {u64 time_start =local_clock (); + dev->poll_time_limit = false; +local_irq_enable ();if (!current_set_polling_and_test ()) {unsigned int loop_count =0 ;
@@ -27,8 +29,10 @@ static int __cpuidle poll_idle(struct cpuidle_device *dev,continue ; loop_count =0 ; -if (local_clock () - time_start >POLL_IDLE_TIME_LIMIT ) +if (local_clock () - time_start >POLL_IDLE_TIME_LIMIT ) { + dev->poll_time_limit = true;break ; + } } }current_clr_polling ();
include/linux/cpuidle.h +1 -0
@@ -81,6 +81,7 @@ struct cpuidle_device { unsigned int registered:1; unsigned int enabled:1; unsigned int use_deepest_state:1; + unsigned int poll_time_limit:1;unsigned int cpu;int last_residency;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 83/209 ASoC: qdsp6: q6asm-dai: checking NULL vs IS_ERR()
In reply to Sasha LevinFrom: Dan Carpenter <[email protected]>
[ Upstream commit 8e9f7265eda9f3a662ca1ca47a69042a7840735b ]
The q6asm_audio_client_alloc() doesn't return NULL, it returns error pointers.
--- sound/soc/qcom/qdsp6/q6asm-dai.c | 5 +++-- 1 file changed, 3 insertions(+), 2 deletions(-)
sound/soc/qcom/qdsp6/q6asm-dai.c +3 -2
@@ -319,10 +319,11 @@ static int q6asm_dai_open(struct snd_pcm_substream *substream) prtd->audio_client =q6asm_audio_client_alloc (dev, (q6asm_cb )event_handler, prtd, stream_id,LEGACY_PCM_MODE ); -if (!prtd->audio_client) { +if (IS_ERR (prtd->audio_client)) {pr_info ("%s: Could not allocate memory\n" , __func__); + ret =PTR_ERR (prtd->audio_client);kfree (prtd); -return -ENOMEM ; +return ret; }if (substream->stream ==SNDRV_PCM_STREAM_PLAYBACK )
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 86/209 ata: ep93xx: Use proper enums for directions
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit 6adde4a36f1b6a562a1057fbb1065007851050e7 ]
Clang warns when one enumerated type is implicitly converted to another.
drivers/ata/pata_ep93xx.c:662:36: warning: implicit conversion from enumeration type 'enum dma_data_direction' to different enumeration type 'enum dma_transfer_direction' [-Wenum-conversion]
drv_data->dma_rx_data.direction = DMA_FROM_DEVICE;
~ ^~~~~~~~~~~~~~~
drivers/ata/pata_ep93xx.c:670:36: warning: implicit conversion from
enumeration type 'enum dma_data_direction' to different enumeration type
'enum dma_transfer_direction' [-Wenum-conversion]
drv_data->dma_tx_data.direction = DMA_TO_DEVICE;
~ ^~~~~~~~~~~~~
drivers/ata/pata_ep93xx.c:681:19: warning: implicit conversion from
enumeration type 'enum dma_data_direction' to different enumeration type
'enum dma_transfer_direction' [-Wenum-conversion]
conf.direction = DMA_FROM_DEVICE;
~ ^~~~~~~~~~~~~~~
drivers/ata/pata_ep93xx.c:692:19: warning: implicit conversion from
enumeration type 'enum dma_data_direction' to different enumeration type
'enum dma_transfer_direction' [-Wenum-conversion]
conf.direction = DMA_TO_DEVICE;
~ ^~~~~~~~~~~~~Use the equivalent valued enums from the expected type so that Clang no longer warns about a conversion.
DMA_TO_DEVICE = DMA_MEM_TO_DEV = 1DMA_FROM_DEVICE = DMA_DEV_TO_MEM = 2
--- drivers/ata/pata_ep93xx.c | 8 ++++---- 1 file changed, 4 insertions(+), 4 deletions(-)
drivers/ata/pata_ep93xx.c +4 -4
@@ -659,7 +659,7 @@ static void ep93xx_pata_dma_init(struct ep93xx_pata_data *drv_data)* start of new transfer. */ drv_data->dma_rx_data.port =EP93XX_DMA_IDE ; - drv_data->dma_rx_data.direction =DMA_FROM_DEVICE ; + drv_data->dma_rx_data.direction =DMA_DEV_TO_MEM ; drv_data->dma_rx_data.name ="ep93xx-pata-rx" ; drv_data->dma_rx_channel =dma_request_channel (mask, ep93xx_pata_dma_filter, &drv_data->dma_rx_data);
@@ -667,7 +667,7 @@ static void ep93xx_pata_dma_init(struct ep93xx_pata_data *drv_data)return ; drv_data->dma_tx_data.port =EP93XX_DMA_IDE ; - drv_data->dma_tx_data.direction =DMA_TO_DEVICE ; + drv_data->dma_tx_data.direction =DMA_MEM_TO_DEV ; drv_data->dma_tx_data.name ="ep93xx-pata-tx" ; drv_data->dma_tx_channel =dma_request_channel (mask, ep93xx_pata_dma_filter, &drv_data->dma_tx_data);
@@ -678,7 +678,7 @@ static void ep93xx_pata_dma_init(struct ep93xx_pata_data *drv_data)/* Configure receive channel direction and source address */ memset (&conf,0 ,sizeof (conf)); - conf.direction =DMA_FROM_DEVICE ; + conf.direction =DMA_DEV_TO_MEM ; conf.src_addr = drv_data->udma_in_phys; conf.src_addr_width =DMA_SLAVE_BUSWIDTH_4_BYTES ;if (dmaengine_slave_config (drv_data->dma_rx_channel, &conf)) {
@@ -689,7 +689,7 @@ static void ep93xx_pata_dma_init(struct ep93xx_pata_data *drv_data)/* Configure transmit channel direction and destination address */ memset (&conf,0 ,sizeof (conf)); - conf.direction =DMA_TO_DEVICE ; + conf.direction =DMA_MEM_TO_DEV ; conf.dst_addr = drv_data->udma_out_phys; conf.dst_addr_width =DMA_SLAVE_BUSWIDTH_4_BYTES ;if (dmaengine_slave_config (drv_data->dma_tx_channel, &conf)) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 84/209 powerpc/time: Use clockevents_register_device(), fixing an issue with large decrementer
In reply to Sasha LevinFrom: Anton Blanchard <[email protected]>
[ Upstream commit 8b78fdb045de60a4eb35460092bbd3cffa925353 ]
We currently cap the decrementer clockevent at 4 seconds, even on systems with large decrementer support. Fix this by converting the code to use clockevents_register_device() which calculates the upper bound based on the max_delta passed in.
--- arch/powerpc/kernel/time.c | 17 +++-------------- 1 file changed, 3 insertions(+), 14 deletions(-)
arch/powerpc/kernel/time.c +3 -14
@@ -984,10 +984,10 @@ static void register_decrementer_clockevent(int cpu) *dec = decrementer_clockevent; dec->cpumask =cpumask_of (cpu); +clockevents_config_and_register (dec, ppc_tb_freq,2 , decrementer_max); +printk_once (KERN_DEBUG "clockevent: %s mult[%x] shift[%d] cpu[%d]\n" , dec->name, dec->mult, dec->shift, cpu); - -clockevents_register_device (dec); }static void enable_large_decrementer (void )
@@ -1035,18 +1035,7 @@ static void __init set_decrementer_max(void)static void __init init_decrementer_clockevent (void ) { -int cpu =smp_processor_id (); - -clockevents_calc_mult_shift (&decrementer_clockevent, ppc_tb_freq,4 ); - - decrementer_clockevent.max_delta_ns = -clockevent_delta2ns (decrementer_max, &decrementer_clockevent); - decrementer_clockevent.max_delta_ticks = decrementer_max; - decrementer_clockevent.min_delta_ns = -clockevent_delta2ns (2 , &decrementer_clockevent); - decrementer_clockevent.min_delta_ticks =2 ; - -register_decrementer_clockevent (cpu); +register_decrementer_clockevent (smp_processor_id ()); }void secondary_cpu_time_init (void )
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 88/209 qed: Avoid implicit enum conversion in qed_ooo_submit_tx_buffers
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit 8fa74e3c49204bdf788d99ef71840490cccc210d ]
Clang warns when one enumerated type is implicitly converted to another.
drivers/net/ethernet/qlogic/qed/qed_ll2.c:799:32: warning: implicit conversion from enumeration type 'enum core_tx_dest' to different enumeration type 'enum qed_ll2_tx_dest' [-Wenum-conversion]
tx_pkt.tx_dest = p_ll2_conn->tx_dest;
~ ~~~~~~~~~~~~^~~~~~~1 warning generated.
Fix this by using a switch statement to convert between the enumerated values since they are not 1 to 1, which matches how the rest of the driver handles this conversion.
--- drivers/net/ethernet/qlogic/qed/qed_ll2.c | 13 ++++++++++++- 1 file changed, 12 insertions(+), 1 deletion(-)
drivers/net/ethernet/qlogic/qed/qed_ll2.c +12 -1
@@ -796,7 +796,18 @@ qed_ooo_submit_tx_buffers(struct qed_hwfn *p_hwfn, tx_pkt.vlan = p_buffer->vlan; tx_pkt.bd_flags = bd_flags; tx_pkt.l4_hdr_offset_w = l4_hdr_offset_w; - tx_pkt.tx_dest = p_ll2_conn->tx_dest; +switch (p_ll2_conn->tx_dest) { +case CORE_TX_DEST_NW : + tx_pkt.tx_dest =QED_LL2_TX_DEST_NW ; +break ; +case CORE_TX_DEST_LB : + tx_pkt.tx_dest =QED_LL2_TX_DEST_LB ; +break ; +case CORE_TX_DEST_DROP : +default : + tx_pkt.tx_dest =QED_LL2_TX_DEST_DROP ; +break ; + } tx_pkt.first_frag = first_frag; tx_pkt.first_frag_len = p_buffer->packet_length; tx_pkt.cookie = p_buffer;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 85/209 powerpc/64s/radix: Explicitly flush ERAT with local LPID invalidation
In reply to Sasha LevinFrom: Nicholas Piggin <[email protected]>
[ Upstream commit 053c5a753e951c5dd1729af2cf4d8107f2e6e09b ]
Local radix TLB flush operations that operate on congruence classes have explicit ERAT flushes for POWER9. The process scoped LPID flush did not have a flush, so add it.
--- arch/powerpc/mm/tlb-radix.c | 1 + 1 file changed, 1 insertion(+)
arch/powerpc/mm/tlb-radix.c +1 -0
@@ -366,6 +366,7 @@ static inline void _tlbiel_lpid_guest(unsigned long lpid, unsigned long ric)__tlbiel_lpid_guest (lpid, set,RIC_FLUSH_TLB ); asmvolatile ("ptesync" : : :"memory" ); + asm volatile(PPC_INVALIDATE_ERAT : : :"memory"); }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 90/209 media: pxa_camera: Fix check for pdev->dev.of_node
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit 44d7f1a77d8c84f8e42789b5475b74ae0e6d4758 ]
Clang warns that the address of a pointer will always evaluated as true in a boolean context.
drivers/media/platform/pxa_camera.c:2400:17: warning: address of 'pdev->dev.of_node' will always evaluate to 'true' [-Wpointer-bool-conversion]
if (&pdev->dev.of_node && !pcdev->pdata) {
~~~~~~~~~~^~~~~~~ ~~1 warning generated.
Judging from the rest of the kernel, it seems like this was an error and just the value of of_node should be checked rather than the address.
--- drivers/media/platform/pxa_camera.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/media/platform/pxa_camera.c +1 -1
@@ -2397,7 +2397,7 @@ static int pxa_camera_probe(struct platform_device *pdev) pcdev->res = res; pcdev->pdata = pdev->dev.platform_data; -if (&pdev->dev.of_node && !pcdev->pdata) { +if (pdev->dev.of_node && !pcdev->pdata) { err =pxa_camera_pdata_from_dt (&pdev->dev, pcdev, &pcdev->asd); }else { pcdev->platform_flags = pcdev->pdata->flags;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 87/209 ARM: dts: da850-lego-ev3: slow down A/DC as much as possible
In reply to Sasha LevinFrom: David Lechner <[email protected]>
[ Upstream commit aea4762fb46e048c059ff49565ee33da07c8aeb3 ]
Due to the electrical design of the A/DC circuits on LEGO MINDSTORMS EV3, if we are reading analog values as fast as possible (i.e. using DMA to service the SPI) the A/DC chip will read incorrect values - as much as 0.1V off when the SPI is running at 10MHz. (This has to do with the capacitor charge time when channels are muxed in the A/DC.)
This patch slows down the SPI as much as possible (if CPU is at 456MHz, SPI runs at 1/2 of that, so 228MHz and has a max prescalar of 256, so we could get ~891kHz, but we're just rounding it to 1MHz). We also use the max allowable value for WDELAY to slow things down even more.
These changes reduce the error of the analog values to about 5mV, which is tolerable.
Commits a3762b13a596 ("spi: spi-davinci: Add support for SPI_CS_WORD") and e2540da86ef8 ("iio: adc: ti-ads7950: use SPI_CS_WORD to reduce CPU usage") introduce changes that allow DMA transfers to be used, so this slow down is needed now.
--- arch/arm/boot/dts/da850-lego-ev3.dts | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)
arch/arm/boot/dts/da850-lego-ev3.dts +2 -1
@@ -352,7 +352,8 @@ compatible = "ti,ads7957"; reg = <3>; #io-channel-cells = <1>; - spi-max-frequency = <10000000>; + spi-max-frequency = <1000000>; + ti,spi-wdelay = <63>; vref-supply = <&adc_ref>; }; };
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 96/209 USB: serial: cypress_m8: fix interrupt-out transfer length
In reply to Sasha LevinFrom: Johan Hovold <[email protected]>
[ Upstream commit 56445eef55cb5904096fed7a73cf87b755dfffc7 ]
Fix interrupt-out transfer length which was being set to the transfer-buffer length rather than the size of the outgoing packet.
Note that no slab data was leaked as the whole transfer buffer is always cleared before each transfer.
--- drivers/usb/serial/cypress_m8.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/usb/serial/cypress_m8.c +1 -1
@@ -769,7 +769,7 @@ static void cypress_send(struct usb_serial_port *port)usb_fill_int_urb (port->interrupt_out_urb, port->serial->dev,usb_sndintpipe (port->serial->dev, port->interrupt_out_endpointAddress), - port->interrupt_out_buffer, port->interrupt_out_size, + port->interrupt_out_buffer, actual_size, cypress_write_int_callback, port, priv->write_urb_interval); result =usb_submit_urb (port->interrupt_out_urb,GFP_ATOMIC );if (result) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 98/209 mtd: physmap_of: Release resources on error
In reply to Sasha LevinFrom: Ricardo Ribalda Delgado <[email protected]>
[ Upstream commit ef0de747f7ad179c7698a5b0e28db05f18ecbf57 ]
During probe, if there was an error the memory region and the memory map were not properly released.This can lead a system unusable if deferred probe is in use.
Replace mem_request and map with devm_ioremap_resource
--- drivers/mtd/maps/physmap_of_core.c | 27 +++++---------------------- 1 file changed, 5 insertions(+), 22 deletions(-)
drivers/mtd/maps/physmap_of_core.c +5 -22
@@ -31,7 +31,6 @@struct of_flash_list {struct mtd_info *mtd;struct map_info map; -struct resource *res; };struct of_flash {
@@ -56,18 +55,10 @@ static int of_flash_remove(struct platform_device *dev)mtd_concat_destroy (info->cmtd); } -for (i =0 ; i < info->list_size; i++) { +for (i =0 ; i < info->list_size; i++)if (info->list[i].mtd)map_destroy (info->list[i].mtd); -if (info->list[i].map.virt) -iounmap (info->list[i].map.virt); - -if (info->list[i].res) { -release_resource (info->list[i].res); -kfree (info->list[i].res); - } - }return 0 ; }
@@ -215,10 +206,11 @@ static int of_flash_probe(struct platform_device *dev) err = -EBUSY ; res_size =resource_size (&res); - info->list[i].res =request_mem_region (res.start, res_size, -dev_name (&dev->dev)); -if (!info->list[i].res) + info->list[i].map.virt =devm_ioremap_resource (&dev->dev, &res); +if (IS_ERR (info->list[i].map.virt)) { + err =PTR_ERR (info->list[i].map.virt); goto err_out; + } err = -ENXIO ; width =of_get_property (dp,"bank-width" ,NULL );
@@ -246,15 +238,6 @@ static int of_flash_probe(struct platform_device *dev)if (err) goto err_out; - err = -ENOMEM ; - info->list[i].map.virt =ioremap (info->list[i].map.phys, - info->list[i].map.size); -if (!info->list[i].map.virt) { -dev_err (&dev->dev,"Failed to ioremap() flash" -" region\n" ); - goto err_out; - } -simple_map_init (&info->list[i].map);/*
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 93/209 ALSA: hda/sigmatel - Disable automute for Elo VuPoint
In reply to Sasha LevinFrom: Michael Pobega <[email protected]>
[ Upstream commit d153135e93a50cdb6f1b52e238909e9965b56056 ]
The Elo VuPoint 15MX has two headphone jacks of which neither work by default. Disabling automute allows ALSA to work normally with the speakers & left headphone jack.
Future pin configuration changes may be required in the future to get the right headphone jack working in tandem.
--- sound/pci/hda/patch_sigmatel.c | 20 ++++++++++++++++++++ 1 file changed, 20 insertions(+)
sound/pci/hda/patch_sigmatel.c +20 -0
@@ -77,6 +77,7 @@ enum {STAC_DELL_M6_BOTH ,STAC_DELL_EQ ,STAC_ALIENWARE_M17X , +STAC_ELO_VUPOINT_15MX ,STAC_92HD89XX_HP_FRONT_JACK ,STAC_92HD89XX_HP_Z1_G2_RIGHT_MIC_JACK , STAC_92HD73XX_ASUS_MOBO,
@@ -1879,6 +1880,18 @@ static void stac92hd73xx_fixup_no_jd(struct hda_codec *codec, codec->no_jack_detect =1 ; } + +static void stac92hd73xx_disable_automute (struct hda_codec *codec, +const struct hda_fixup *fix,int action) +{ +struct sigmatel_spec *spec = codec->spec; + +if (action !=HDA_FIXUP_ACT_PRE_PROBE ) +return ; + + spec->gen.suppress_auto_mute =1 ; +} +static const struct hda_fixup stac92hd73xx_fixups[] = { [STAC_92HD73XX_REF ] = { .type =HDA_FIXUP_FUNC ,
@@ -1904,6 +1917,10 @@ static const struct hda_fixup stac92hd73xx_fixups[] = { .type = HDA_FIXUP_FUNC, .v.func = stac92hd73xx_fixup_alienware_m17x, }, + [STAC_ELO_VUPOINT_15MX] = { + .type = HDA_FIXUP_FUNC, + .v.func = stac92hd73xx_disable_automute, + }, [STAC_92HD73XX_INTEL] = { .type = HDA_FIXUP_PINS, .v.pins = intel_dg45id_pin_configs,
@@ -1942,6 +1959,7 @@ static const struct hda_model_fixup stac92hd73xx_models[] = { { .id = STAC_DELL_M6_BOTH, .name = "dell-m6" }, { .id = STAC_DELL_EQ, .name = "dell-eq" }, { .id = STAC_ALIENWARE_M17X, .name = "alienware" }, + { .id = STAC_ELO_VUPOINT_15MX, .name = "elo-vupoint-15mx" }, { .id = STAC_92HD73XX_ASUS_MOBO, .name = "asus-mobo" }, {} };
@@ -1991,6 +2009,8 @@ static const struct snd_pci_quirk stac92hd73xx_fixup_tbl[] = { "Alienware M17x", STAC_ALIENWARE_M17X),SND_PCI_QUIRK (PCI_VENDOR_ID_DELL ,0x0490 ,"Alienware M17x R3" ,STAC_DELL_EQ ), +SND_PCI_QUIRK (0x1059 ,0x1011 , +"ELO VuPoint 15MX" ,STAC_ELO_VUPOINT_15MX ),SND_PCI_QUIRK (PCI_VENDOR_ID_HP ,0x1927 ,"HP Z1 G2" ,STAC_92HD89XX_HP_Z1_G2_RIGHT_MIC_JACK ), SND_PCI_QUIRK(PCI_VENDOR_ID_HP, 0x2b17,
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 94/209 bnxt_en: return proper error when FW returns HWRM_ERR_CODE_RESOURCE_ACCESS_DENIED
In reply to Sasha LevinFrom: Vasundhara Volam <[email protected]>
[ Upstream commit 3a1d52a54a6a4030b294e5f5732f0bfbae0e3815 ]
Return proper error code when Firmware returns HWRM_ERR_CODE_RESOURCE_ACCESS_DENIED for HWRM_NVM_GET/SET_VARIABLE commands.
--- drivers/net/ethernet/broadcom/bnxt/bnxt_devlink.c | 6 +++++- 1 file changed, 5 insertions(+), 1 deletion(-)
drivers/net/ethernet/broadcom/bnxt/bnxt_devlink.c +5 -1
@@ -78,8 +78,12 @@ static int bnxt_hwrm_nvm_req(struct bnxt *bp, u32 param_id, void *msg,memcpy (buf, data_addr, bytesize);dma_free_coherent (&bp->pdev->dev, bytesize, data_addr, data_dma_addr); -if (rc) +if (rc ==HWRM_ERR_CODE_RESOURCE_ACCESS_DENIED ) { +netdev_err (bp->dev,"PF does not have admin privileges to modify NVM config\n" ); +return -EACCES ; + }else if (rc) {return -EIO ; + }return 0 ; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 101/209 brcmfmac: fix full timeout waiting for action frame on-channel tx
In reply to Sasha LevinFrom: Chung-Hsien Hsu <[email protected]>
[ Upstream commit fbf07000960d9c8a13fdc17c6de0230d681c7543 ]
The driver sends an action frame down and waits for a completion signal triggered by the received BRCMF_E_ACTION_FRAME_OFF_CHAN_COMPLETE event to continue the process. However, the action frame could be transmitted either on the current channel or on an off channel. For the on-channel case, only BRCMF_E_ACTION_FRAME_COMPLETE event will be received when the frame is transmitted, which make the driver always wait a full timeout duration. This patch has the completion signal be triggered by receiving the BRCMF_E_ACTION_FRAME_COMPLETE event for the on-channel case.
This change fixes WFA p2p certification 5.1.19 failure.
--- .../wireless/broadcom/brcm80211/brcmfmac/p2p.c | 17 +++++++++++++++-- .../wireless/broadcom/brcm80211/brcmfmac/p2p.h | 2 ++ 2 files changed, 17 insertions(+), 2 deletions(-)
drivers/net/wireless/broadcom/brcm80211/brcmfmac/p2p.c +15 -2
@@ -1457,10 +1457,12 @@ int brcmf_p2p_notify_action_tx_complete(struct brcmf_if *ifp,return 0 ;if (e->event_code ==BRCMF_E_ACTION_FRAME_COMPLETE ) { -if (e->status ==BRCMF_E_STATUS_SUCCESS ) +if (e->status ==BRCMF_E_STATUS_SUCCESS ) {set_bit (BRCMF_P2P_STATUS_ACTION_TX_COMPLETED , &p2p->status); -else { +if (!p2p->wait_for_offchan_complete) +complete (&p2p->send_af_done); + }else {set_bit (BRCMF_P2P_STATUS_ACTION_TX_NOACK , &p2p->status);/* If there is no ack, we don't need to wait for * WLC_E_ACTION_FRAME_OFFCHAN_COMPLETE event
@@ -1511,6 +1513,17 @@ static s32 brcmf_p2p_tx_action_frame(struct brcmf_p2p_info *p2p, p2p->af_sent_channel =le32_to_cpu (af_params->channel); p2p->af_tx_sent_jiffies = jiffies; +if (test_bit (BRCMF_P2P_STATUS_DISCOVER_LISTEN , &p2p->status) && + p2p->af_sent_channel == +ieee80211_frequency_to_channel (p2p->remain_on_channel.center_freq)) + p2p->wait_for_offchan_complete = false; +else + p2p->wait_for_offchan_complete = true; + +brcmf_dbg (TRACE ,"Waiting for %s tx completion event\n" , + (p2p->wait_for_offchan_complete) ? +"off-channel" :"on-channel" ); + timeout =wait_for_completion_timeout (&p2p->send_af_done,P2P_AF_MAX_WAIT_TIME );
drivers/net/wireless/broadcom/brcm80211/brcmfmac/p2p.h +2 -0
@@ -124,6 +124,7 @@ struct afx_hdl {* @gon_req_action: about to send go negotiation requets frame. * @block_gon_req_tx: drop tx go negotiation requets frame. * @p2pdev_dynamically: is p2p device if created by module param or supplicant. +* @wait_for_offchan_complete: wait for off-channel tx completion event. */ struct brcmf_p2p_info {struct brcmf_cfg80211_info *cfg;
@@ -144,6 +145,7 @@ struct brcmf_p2p_info {bool gon_req_action;bool block_gon_req_tx;bool p2pdev_dynamically; +bool wait_for_offchan_complete; };s32 brcmf_p2p_attach (struct brcmf_cfg80211_info *cfg,bool p2pdev_forced);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 102/209 qtnfmac: request userspace to do OBSS scanning if FW can not
In reply to Sasha LevinFrom: Igor Mitsyanko <[email protected]>
[ Upstream commit 92246b126ebf66ab1fec9d631df78d7c675b66db ]
In case firmware reports that it can not do OBSS scanning for 40MHz 2.4GHz channels itself, tell userpsace to do that instead by setting NL80211_FEATURE_NEED_OBSS_SCAN flag.
--- drivers/net/wireless/quantenna/qtnfmac/cfg80211.c | 3 +++ drivers/net/wireless/quantenna/qtnfmac/qlink.h | 2 ++ 2 files changed, 5 insertions(+)
drivers/net/wireless/quantenna/qtnfmac/cfg80211.c +3 -0
@@ -1109,6 +1109,9 @@ int qtnf_wiphy_register(struct qtnf_hw_info *hw_info, struct qtnf_wmac *mac)if (hw_info->hw_capab &QLINK_HW_CAPAB_SCAN_RANDOM_MAC_ADDR ) wiphy->features |=NL80211_FEATURE_SCAN_RANDOM_MAC_ADDR ; +if (!(hw_info->hw_capab &QLINK_HW_CAPAB_OBSS_SCAN )) + wiphy->features |=NL80211_FEATURE_NEED_OBSS_SCAN ; +#ifdef CONFIG_PM if (macinfo->wowlan) wiphy->wowlan = macinfo->wowlan;
drivers/net/wireless/quantenna/qtnfmac/qlink.h +2 -0
@@ -71,6 +71,7 @@ struct qlink_msg_header {* @QLINK_HW_CAPAB_DFS_OFFLOAD: device implements DFS offload functionality * @QLINK_HW_CAPAB_SCAN_RANDOM_MAC_ADDR: device supports MAC Address * Randomization in probe requests. +* @QLINK_HW_CAPAB_OBSS_SCAN: device can perform OBSS scanning. */ enum qlink_hw_capab {QLINK_HW_CAPAB_REG_UPDATE =BIT (0 ),
@@ -78,6 +79,7 @@ enum qlink_hw_capab {QLINK_HW_CAPAB_DFS_OFFLOAD =BIT (2 ),QLINK_HW_CAPAB_SCAN_RANDOM_MAC_ADDR =BIT (3 ),QLINK_HW_CAPAB_PWR_MGMT =BIT (4 ), + QLINK_HW_CAPAB_OBSS_SCAN = BIT(5), }; enum qlink_iface_type {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 99/209 cpu/SMT: State SMT is disabled even with nosmt and without "=force"
In reply to Sasha LevinFrom: Borislav Petkov <[email protected]>
[ Upstream commit d0e7d14455d41163126afecd0fcce935463cc512 ]
When booting with "nosmt=force" a message is issued into dmesg to confirm that SMT has been force-disabled but such a message is not issued when only "nosmt" is on the kernel command line.
Fix that.
--- kernel/cpu.c | 1 + 1 file changed, 1 insertion(+)
kernel/cpu.c +1 -0
@@ -375,6 +375,7 @@ void __init cpu_smt_disable(bool force)pr_info ("SMT: Force disabled\n" ); cpu_smt_control =CPU_SMT_FORCE_DISABLED ; }else { +pr_info ("SMT: disabled\n" ); cpu_smt_control =CPU_SMT_DISABLED ; } }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 103/209 qtnfmac: pass sgi rate info flag to wireless core
In reply to Sasha LevinFrom: Sergey Matyukevich <[email protected]>
[ Upstream commit d5657b709e2a92a0e581109010765d1d485580df ]
SGI should be passed to wireless core as a part of rate structure. Otherwise wireless core performs incorrect rate calculation when SGI is enabled in hardware but not reported to host.
--- drivers/net/wireless/quantenna/qtnfmac/commands.c | 3 +++ 1 file changed, 3 insertions(+)
drivers/net/wireless/quantenna/qtnfmac/commands.c +3 -0
@@ -544,6 +544,9 @@ qtnf_sta_info_parse_rate(struct rate_info *rate_dst, rate_dst->flags |=RATE_INFO_FLAGS_MCS ; else if (rate_src->flags & QLINK_STA_INFO_RATE_FLAG_VHT_MCS) rate_dst->flags |= RATE_INFO_FLAGS_VHT_MCS; + +if (rate_src->flags &QLINK_STA_INFO_RATE_FLAG_SHORT_GI ) + rate_dst->flags |=RATE_INFO_FLAGS_SHORT_GI ; } static void
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 106/209 clk: samsung: Use NOIRQ stage for Exynos5433 clocks suspend/resume
In reply to Sasha LevinFrom: Marek Szyprowski <[email protected]>
[ Upstream commit 70da9ee80228e6d98fd68e3c1db124c4461d283c ]
SoC clock drivers should suspend after every other drivers in the system, which are using clocks and resume before them. The last stage for calling suspend device callbacks is NOIRQ stage and there exists driver, which use that state (dwmmc-exynos), so Exynos5433 clocks driver should also use it. During the same stage, clocks driver will be always suspended after its clients as a direct result of proper device probe order (deferred probe reorders the suspend call sequence).
--- drivers/clk/samsung/clk-exynos5433.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/clk/samsung/clk-exynos5433.c +1 -1
@@ -5630,7 +5630,7 @@ static const struct of_device_id exynos5433_cmu_of_match[] = {static const struct dev_pm_ops exynos5433_cmu_pm_ops = { SET_RUNTIME_PM_OPS(exynos5433_cmu_suspend, exynos5433_cmu_resume, NULL) -SET_LATE_SYSTEM_SLEEP_PM_OPS (pm_runtime_force_suspend, +SET_NOIRQ_SYSTEM_SLEEP_PM_OPS (pm_runtime_force_suspend, pm_runtime_force_resume) };
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 105/209 qtnfmac: drop error reports for out-of-bounds key indexes
In reply to Sasha LevinFrom: Sergey Matyukevich <[email protected]>
[ Upstream commit 35da3fe63b8647ce3cc52fccdf186a60710815fb ]
On disconnect wireless core attempts to remove all the supported keys. Following cfg80211_ops conventions, firmware returns -ENOENT code for the out-of-bound key indexes. This is a normal behavior, so no need to report errors for this case.
--- drivers/net/wireless/quantenna/qtnfmac/cfg80211.c | 13 ++++++++++--- 1 file changed, 10 insertions(+), 3 deletions(-)
drivers/net/wireless/quantenna/qtnfmac/cfg80211.c +10 -3
@@ -521,9 +521,16 @@ static int qtnf_del_key(struct wiphy *wiphy, struct net_device *dev,int ret; ret =qtnf_cmd_send_del_key (vif, key_index, pairwise, mac_addr); -if (ret) -pr_err ("VIF%u.%u: failed to delete key: idx=%u pw=%u\n" , - vif->mac->macid, vif->vifid, key_index, pairwise); +if (ret) { +if (ret == -ENOENT ) { +pr_debug ("VIF%u.%u: key index %d out of bounds\n" , + vif->mac->macid, vif->vifid, key_index); + }else { +pr_err ("VIF%u.%u: failed to delete key: idx=%u pw=%u\n" , + vif->mac->macid, vif->vifid, + key_index, pairwise); + } + }return ret; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 107/209 clk: samsung: exynos5420: Define CLK_SECKEY gate clock only or Exynos5420
In reply to Sasha LevinFrom: Joonyoung Shim <[email protected]>
[ Upstream commit d32dd2a1a0f80edad158c9a1ba5f47650d9504a0 ]
The bit of GATE_BUS_PERIS1 for CLK_SECKEY is just reserved on exynos5422/5800, not exynos5420. Define gate clk for exynos5420 to handle the bit only on exynos5420.
--- drivers/clk/samsung/clk-exynos5420.c | 3 +-- 1 file changed, 1 insertion(+), 2 deletions(-)
drivers/clk/samsung/clk-exynos5420.c +1 -2
@@ -634,6 +634,7 @@ static const struct samsung_div_clock exynos5420_div_clks[] __initconst = { };static const struct samsung_gate_clock exynos5420_gate_clks[]__initconst = { +GATE (CLK_SECKEY ,"seckey" ,"aclk66_psgen" ,GATE_BUS_PERIS1 ,1 ,0 ,0 ),GATE (CLK_MAU_EPLL ,"mau_epll" ,"mout_mau_epll_clk" ,SRC_MASK_TOP7 ,20 ,CLK_SET_RATE_PARENT ,0 ), };
@@ -1163,8 +1164,6 @@ static const struct samsung_gate_clock exynos5x_gate_clks[] __initconst = {GATE (CLK_TMU ,"tmu" ,"aclk66_psgen" ,GATE_IP_PERIS ,21 ,0 ,0 ),GATE (CLK_TMU_GPU ,"tmu_gpu" ,"aclk66_psgen" ,GATE_IP_PERIS ,22 ,0 ,0 ), -GATE (CLK_SECKEY ,"seckey" ,"aclk66_psgen" ,GATE_BUS_PERIS1 ,1 ,0 ,0 ), -/* GEN Block */ GATE (CLK_ROTATOR ,"rotator" ,"mout_user_aclk266" ,GATE_IP_GEN ,1 ,0 ,0 ), GATE(CLK_JPEG, "jpeg", "aclk300_jpeg", GATE_IP_GEN, 2, 0, 0),
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 111/209 NFSv4.x: fix lock recovery during delegation recall
In reply to Sasha LevinFrom: Olga Kornievskaia <[email protected]>
[ Upstream commit 44f411c353bf6d98d5a34f8f1b8605d43b2e50b8 ]
Running "./nfstest_delegation --runtest recall26" uncovers that client doesn't recover the lock when we have an appending open, where the initial open got a write delegation.
Instead of checking for the passed in open context against the file lock's open context. Check that the state is the same.
--- fs/nfs/delegation.c | 6 +++--- 1 file changed, 3 insertions(+), 3 deletions(-)
fs/nfs/delegation.c +3 -3
@@ -93,7 +93,7 @@ int nfs4_check_delegation(struct inode *inode, fmode_t flags)return nfs4_do_check_delegation (inode, flags, false); } -static int nfs_delegation_claim_locks (struct nfs_open_context *ctx,struct nfs4_state *state,const nfs4_stateid *stateid) +static int nfs_delegation_claim_locks (struct nfs4_state *state,const nfs4_stateid *stateid) {struct inode *inode = state->inode;struct file_lock *fl;
@@ -108,7 +108,7 @@ static int nfs_delegation_claim_locks(struct nfs_open_context *ctx, struct nfs4_spin_lock (&flctx->flc_lock); restart:list_for_each_entry (fl, list, fl_list) { -if (nfs_file_open_context (fl->fl_file) != ctx) +if (nfs_file_open_context (fl->fl_file)->state != state)continue ;spin_unlock (&flctx->flc_lock); status =nfs4_lock_delegation_recall (fl, state, stateid);
@@ -155,7 +155,7 @@ static int nfs_delegation_claim_opens(struct inode *inode, seq =raw_seqcount_begin (&sp->so_reclaim_seqcount); err =nfs4_open_delegation_recall (ctx, state, stateid);if (!err) - err =nfs_delegation_claim_locks (ctx, state, stateid); + err =nfs_delegation_claim_locks (state, stateid);if (!err &&read_seqcount_retry (&sp->so_reclaim_seqcount, seq)) err = -EAGAIN ;mutex_unlock (&sp->so_delegreturn_mutex);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 108/209 clk: samsung: Use clk_hw API for calling clk framework from clk notifiers
In reply to Sasha LevinFrom: Marek Szyprowski <[email protected]>
[ Upstream commit 1da220e3a5d22fccda0bc8542997abc1d1741268 ]
clk_notifier_register() documentation states, that the provided notifier callbacks associated with the notifier must not re-enter into the clk framework by calling any top-level clk APIs. Fix this by replacing clk_get_rate() calls with clk_hw_get_rate(), which is safe in this context.
--- drivers/clk/samsung/clk-cpu.c | 6 +++--- drivers/clk/samsung/clk-cpu.h | 2 +- 2 files changed, 4 insertions(+), 4 deletions(-)
drivers/clk/samsung/clk-cpu.c +3 -3
@@ -152,7 +152,7 @@ static int exynos_cpuclk_pre_rate_change(struct clk_notifier_data *ndata, struct exynos_cpuclk *cpuclk, void __iomem *base) { const struct exynos_cpuclk_cfg_data *cfg_data = cpuclk->cfg; -unsigned long alt_prate =clk_get_rate (cpuclk->alt_parent); +unsigned long alt_prate =clk_hw_get_rate (cpuclk->alt_parent);unsigned long alt_div =0 , alt_div_mask =DIV_MASK ;unsigned long div0, div1 =0 , mux_reg;unsigned long flags;
@@ -280,7 +280,7 @@ static int exynos5433_cpuclk_pre_rate_change(struct clk_notifier_data *ndata, struct exynos_cpuclk *cpuclk, void __iomem *base) { const struct exynos_cpuclk_cfg_data *cfg_data = cpuclk->cfg; -unsigned long alt_prate =clk_get_rate (cpuclk->alt_parent); +unsigned long alt_prate =clk_hw_get_rate (cpuclk->alt_parent);unsigned long alt_div =0 , alt_div_mask =DIV_MASK ;unsigned long div0, div1 =0 , mux_reg;unsigned long flags;
@@ -432,7 +432,7 @@ int __init exynos_register_cpu_clock(struct samsung_clk_provider *ctx,else cpuclk->clk_nb.notifier_call = exynos_cpuclk_notifier_cb; - cpuclk->alt_parent =__clk_lookup (alt_parent); + cpuclk->alt_parent =__clk_get_hw (__clk_lookup (alt_parent));if (!cpuclk->alt_parent) {pr_err ("%s: could not lookup alternate parent %s\n" , __func__, alt_parent);
drivers/clk/samsung/clk-cpu.h +1 -1
@@ -49,7 +49,7 @@ struct exynos_cpuclk_cfg_data {*/ struct exynos_cpuclk {struct clk_hw hw; -struct clk *alt_parent; +struct clk_hw *alt_parent;void __iomem *ctrl_base;spinlock_t *lock;const struct exynos_cpuclk_cfg_data *cfg;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 113/209 media: ov5640: fix framerate update
In reply to Sasha LevinFrom: Hugues Fruchet <[email protected]>
[ Upstream commit 0929983e49c81c1d413702cd9b83bb06c4a2555c ]
Changing framerate right before streamon had no effect, the new framerate value was taken into account only at next streamon, fix this.
--- drivers/media/i2c/ov5640.c | 7 ++++--- 1 file changed, 4 insertions(+), 3 deletions(-)
drivers/media/i2c/ov5640.c +4 -3
@@ -2572,8 +2572,6 @@ static int ov5640_s_frame_interval(struct v4l2_subdev *sd,if (frame_rate <0 ) frame_rate =OV5640_15_FPS ; - sensor->current_fr = frame_rate; - sensor->frame_interval = fi->interval; mode =ov5640_find_mode (sensor, frame_rate, mode->hact, mode->vact, true);if (!mode) {
@@ -2581,7 +2579,10 @@ static int ov5640_s_frame_interval(struct v4l2_subdev *sd, goto out; } -if (mode != sensor->current_mode) { +if (mode != sensor->current_mode || + frame_rate != sensor->current_fr) { + sensor->current_fr = frame_rate; + sensor->frame_interval = fi->interval; sensor->current_mode = mode; sensor->pending_mode_change = true; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 112/209 dmaengine: ioat: fix prototype of ioat_enumerate_channels
In reply to Sasha LevinFrom: Rami Rosen <[email protected]>
[ Upstream commit f4d34aa8c887a8a2d23ef546da0efa10e3f77241 ]
--- drivers/dma/ioat/init.c | 7 +++---- 1 file changed, 3 insertions(+), 4 deletions(-)
drivers/dma/ioat/init.c +3 -4
@@ -129,7 +129,7 @@ static void ioat_init_channel(struct ioatdma_device *ioat_dma, struct ioatdma_chan *ioat_chan, int idx);static void ioat_intr_quirk (struct ioatdma_device *ioat_dma); -static int ioat_enumerate_channels (struct ioatdma_device *ioat_dma); +static void ioat_enumerate_channels (struct ioatdma_device *ioat_dma);static int ioat3_dma_self_test (struct ioatdma_device *ioat_dma);static int ioat_dca_enabled =1 ;
@@ -575,7 +575,7 @@ static void ioat_dma_remove(struct ioatdma_device *ioat_dma)* ioat_enumerate_channels - find and initialize the device's channels * @ioat_dma: the ioat dma device to be enumerated */ -static int ioat_enumerate_channels (struct ioatdma_device *ioat_dma) +static void ioat_enumerate_channels (struct ioatdma_device *ioat_dma) {struct ioatdma_chan *ioat_chan;struct device *dev = &ioat_dma->pdev->dev;
@@ -594,7 +594,7 @@ static int ioat_enumerate_channels(struct ioatdma_device *ioat_dma) xfercap_log =readb (ioat_dma->reg_base +IOAT_XFERCAP_OFFSET ); xfercap_log &=0x1f ;/* bits [4:0] valid */ if (xfercap_log ==0 ) -return 0 ; +return ;dev_dbg (dev,"%s: xfercap = %d\n" , __func__,1 << xfercap_log);for (i =0 ; i < dma->chancnt; i++) {
@@ -611,7 +611,6 @@ static int ioat_enumerate_channels(struct ioatdma_device *ioat_dma) } } dma->chancnt = i; -return i; }/**
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 120/209 Input: st1232 - set INPUT_PROP_DIRECT property
In reply to Sasha LevinFrom: Martin Kepplinger <[email protected]>
[ Upstream commit 20bbb312079494a406c10c90932e3c80837c9d94 ]
This is how userspace checks for touchscreen devices most reliably.
--- drivers/input/touchscreen/st1232.c | 1 + 1 file changed, 1 insertion(+)
drivers/input/touchscreen/st1232.c +1 -0
@@ -195,6 +195,7 @@ static int st1232_ts_probe(struct i2c_client *client, input_dev->id.bustype =BUS_I2C ; input_dev->dev.parent = &client->dev; +__set_bit (INPUT_PROP_DIRECT , input_dev->propbit);__set_bit (EV_SYN , input_dev->evbit);__set_bit (EV_KEY , input_dev->evbit);__set_bit (EV_ABS , input_dev->evbit);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 123/209 net: hns3: Fix for rx vlan id handle to support Rev 0x21 hardware
In reply to Sasha LevinFrom: Jian Shen <[email protected]>
[ Upstream commit 701a6d6ac78c76083ddb7c6581fdbedd95093e11 ]
In revision 0x20, we use vlan id != 0 to check whether a vlan tag has been offloaded, so vlan id 0 is not supported.
In revision 0x21, rx buffer descriptor adds two bits to indicate whether one or more vlan tags have been offloaded, so vlan id 0 is valid now.
This patch seperates the handle for vlan id 0, add vlan id 0 support for revision 0x21.
--- .../net/ethernet/hisilicon/hns3/hns3_enet.c | 30 ++++++++----------- 1 file changed, 13 insertions(+), 17 deletions(-)
drivers/net/ethernet/hisilicon/hns3/hns3_enet.c +13 -17
@@ -2124,18 +2124,18 @@ static void hns3_rx_skb(struct hns3_enet_ring *ring, struct sk_buff *skb)napi_gro_receive (&ring->tqp_vector->napi, skb); } -static u16 hns3_parse_vlan_tag (struct hns3_enet_ring *ring, -struct hns3_desc *desc,u32 l234info) +static bool hns3_parse_vlan_tag (struct hns3_enet_ring *ring, +struct hns3_desc *desc,u32 l234info, +u16 *vlan_tag) {struct pci_dev *pdev = ring->tqp->handle->pdev; -u16 vlan_tag;if (pdev->revision ==0x20 ) { - vlan_tag =le16_to_cpu (desc->rx.ot_vlan_tag); -if (!(vlan_tag &VLAN_VID_MASK )) - vlan_tag =le16_to_cpu (desc->rx.vlan_tag); + *vlan_tag =le16_to_cpu (desc->rx.ot_vlan_tag); +if (!(*vlan_tag &VLAN_VID_MASK )) + *vlan_tag =le16_to_cpu (desc->rx.vlan_tag); -return vlan_tag; +return (*vlan_tag !=0 ); }#define HNS3_STRP_OUTER_VLAN 0x1
@@ -2144,17 +2144,14 @@ static u16 hns3_parse_vlan_tag(struct hns3_enet_ring *ring,switch (hnae3_get_field (l234info,HNS3_RXD_STRP_TAGP_M ,HNS3_RXD_STRP_TAGP_S )) {case HNS3_STRP_OUTER_VLAN : - vlan_tag =le16_to_cpu (desc->rx.ot_vlan_tag); -break ; + *vlan_tag =le16_to_cpu (desc->rx.ot_vlan_tag); +return true;case HNS3_STRP_INNER_VLAN : - vlan_tag =le16_to_cpu (desc->rx.vlan_tag); -break ; + *vlan_tag =le16_to_cpu (desc->rx.vlan_tag); +return true;default : - vlan_tag =0 ; -break ; +return false; } - -return vlan_tag; } static int hns3_handle_rx_bd(struct hns3_enet_ring *ring,
@@ -2256,8 +2253,7 @@ static int hns3_handle_rx_bd(struct hns3_enet_ring *ring,if (netdev->features &NETIF_F_HW_VLAN_CTAG_RX ) {u16 vlan_tag; - vlan_tag =hns3_parse_vlan_tag (ring, desc, l234info); -if (vlan_tag &VLAN_VID_MASK ) +if (hns3_parse_vlan_tag (ring, desc, l234info, &vlan_tag))__vlan_hwaccel_put_tag (skb,htons (ETH_P_8021Q ), vlan_tag);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 122/209 soc: fsl: bman_portals: defer probe after bman's probe
In reply to Sasha LevinFrom: Laurentiu Tudor <[email protected]>
[ Upstream commit e0940b34c40e95d1879691d2474d182c57aae0de ]
A crash in bman portal probing could not be triggered (as is the case with qman portals) but it does make calls [1] into the bman driver so lets make sure the bman portal probing happens after bman's.
[1] bman_p_irqsource_add() (in bman) called by:
init_pcfg() called by:
bman_portal_probe()
--- drivers/soc/fsl/qbman/bman_portal.c | 10 +++++++++- 1 file changed, 9 insertions(+), 1 deletion(-)
drivers/soc/fsl/qbman/bman_portal.c +9 -1
@@ -91,7 +91,15 @@ static int bman_portal_probe(struct platform_device *pdev)struct device_node *node = dev->of_node;struct bm_portal_config *pcfg;struct resource *addr_phys[2 ]; -int irq, cpu; +int irq, cpu, err; + + err =bman_is_probed (); +if (!err) +return -EPROBE_DEFER ; +if (err <0 ) { +dev_err (&pdev->dev,"failing probe due to bman probe error\n" ); +return -ENODEV ; + } pcfg =devm_kmalloc (dev,sizeof (*pcfg),GFP_KERNEL );if (!pcfg)
Signature · 7 lines
2.20.1 _______________________________________________ linux-arm-kernel mailing list [email protected] http://lists.infradead.org/mailman/listinfo/linux-arm-kernel
Sasha Levin
maintainerPATCH 127/209 kexec: Allocate decrypted control pages for kdump if SME is enabled
In reply to Sasha LevinFrom: Lianbo Jiang <[email protected]>
[ Upstream commit 9cf38d5559e813cccdba8b44c82cc46ba48d0896 ]
When SME is enabled in the first kernel, it needs to allocate decrypted pages for kdump because when the kdump kernel boots, these pages need to be accessed decrypted in the initial boot stage, before SME is enabled.
[ bp: clean up text. ]
--- kernel/kexec_core.c | 6 ++++++ 1 file changed, 6 insertions(+)
kernel/kexec_core.c +6 -0
@@ -473,6 +473,10 @@ static struct page *kimage_alloc_crash_control_pages(struct kimage *image, } } +/* Ensure that these pages are decrypted if SME is enabled. */ +if (pages) +arch_kexec_post_alloc_pages (page_address (pages),1 << order,0 ); +return pages; }
@@ -869,6 +873,7 @@ static int kimage_load_crash_segment(struct kimage *image, result = -ENOMEM ; goto out; } +arch_kexec_post_alloc_pages (page_address (page),1 ,0 ); ptr =kmap (page); ptr += maddr & ~PAGE_MASK ; mchunk = min_t(size_t, mbytes,
@@ -886,6 +891,7 @@ static int kimage_load_crash_segment(struct kimage *image, result =copy_from_user (ptr, buf, uchunk);kexec_flush_icache_page (page);kunmap (page); +arch_kexec_pre_free_pages (page_address (page),1 );if (result) { result = -EFAULT ; goto out;
Signature · 7 lines
2.20.1 _______________________________________________ kexec mailing list [email protected] http://lists.infradead.org/mailman/listinfo/kexec
Sasha Levin
maintainerPATCH 124/209 tc-testing: fix build of eBPF programs
In reply to Sasha LevinFrom: Davide Caratti <[email protected]>
[ Upstream commit cf5eafbfa586d030f9321cee516b91d089e38280 ]
rely on uAPI headers in the current kernel tree, rather than requiring the correct version installed on the test system. While at it, group all sections in a single binary and test the 'section' parameter.
--- .../testing/selftests/tc-testing/bpf/Makefile | 29 +++++++++++++++++++ .../testing/selftests/tc-testing/bpf/action.c | 23 +++++++++++++++ .../tc-testing/tc-tests/actions/bpf.json | 16 +++++----- .../selftests/tc-testing/tdc_config.py | 4 ++- 4 files changed, 63 insertions(+), 9 deletions(-) create mode 100644 tools/testing/selftests/tc-testing/bpf/Makefile create mode 100644 tools/testing/selftests/tc-testing/bpf/action.c
tools/testing/selftests/tc-testing/bpf/Makefile new file +29 -0
@@ -0,0 +1,29 @@ +# SPDX-License-Identifier: GPL-2.0 + +APIDIR := ../../../../include/uapi +TEST_GEN_FILES = action.o + +top_srcdir = ../../../../.. +include ../../lib.mk + +CLANG ?= clang +LLC ?= llc +PROBE := $(shell $(LLC) -march=bpf -mcpu=probe -filetype=null /dev/null 2>&1) + +ifeq ($(PROBE),) + CPU ?= probe +else + CPU ?= generic +endif + +CLANG_SYS_INCLUDES := $(shell $(CLANG) -v -E - </dev/null 2>&1 \ + | sed -n '/<...> search starts here:/,/End of search list./{ s| \(/.*\)|-idirafter \1|p }') + +CLANG_FLAGS = -I. -I$(APIDIR) \ + $(CLANG_SYS_INCLUDES) \ + -Wno-compare-distinct-pointer-types + +$(OUTPUT)/%.o: %.c + $(CLANG) $(CLANG_FLAGS) \ + -O2 -target bpf -emit-llvm -c $< -o - | \ + $(LLC) -march=bpf -mcpu=$(CPU) $(LLC_FLAGS) -filetype=obj -o $@
tools/testing/selftests/tc-testing/bpf/action.c new file +23 -0
@@ -0,0 +1,23 @@ +/* SPDX-License-Identifier: GPL-2.0 +* Copyright (c) 2018 Davide Caratti, Red Hat inc. +* +* This program is free software; you can redistribute it and/or +* modify it under the terms of version 2 of the GNU General Public +* License as published by the Free Software Foundation. +*/ + +#include <linux/bpf.h> +#include <linux/pkt_cls.h> + +__attribute__((section ("action-ok" ),used))int action_ok (struct __sk_buff *s) +{ +return TC_ACT_OK ; +} + +__attribute__((section ("action-ko" ),used))int action_ko (struct __sk_buff *s) +{ + s->data =0x0 ; +return TC_ACT_OK ; +} + +char _license[] __attribute__((section("license"),used)) = "GPL";
tools/testing/selftests/tc-testing/tc-tests/actions/bpf.json +8 -8
@@ -55,7 +55,7 @@ "bpf" ], "setup": [ - "printf '#include <linux/bpf.h>\nchar l[] __attribute__((section(\"license\"),used))=\"GPL\"; __attribute__((section(\"action\"),used)) int m(struct __sk_buff *s) { return 2; }' | clang -O2 -x c -c - -target bpf -o _b.o", + "make -C bpf", [ "$TC action flush action bpf", 0,
@@ -63,14 +63,14 @@ 255 ] ], - "cmdUnderTest": "$TC action add action bpf object-file _b.o index 667", + "cmdUnderTest": "$TC action add action bpf object-file $EBPFDIR/action.o section action-ok index 667", "expExitCode": "0", "verifyCmd": "$TC action get action bpf index 667", - "matchPattern": "action order [0-9]*: bpf _b.o:\\[action\\] id [0-9]* tag 3b185187f1855c4c( jited)? default-action pipe.*index 667 ref", + "matchPattern": "action order [0-9]*: bpf action.o:\\[action-ok\\] id [0-9]* tag [0-9a-f]{16}( jited)? default-action pipe.*index 667 ref", "matchCount": "1", "teardown": [ "$TC action flush action bpf", - "rm -f _b.o" + "make -C bpf clean" ] }, {
@@ -81,7 +81,7 @@ "bpf" ], "setup": [ - "printf '#include <linux/bpf.h>\nchar l[] __attribute__((section(\"license\"),used))=\"GPL\"; __attribute__((section(\"action\"),used)) int m(struct __sk_buff *s) { s->data = 0x0; return 2; }' | clang -O2 -x c -c - -target bpf -o _c.o", + "make -C bpf", [ "$TC action flush action bpf", 0,
@@ -89,10 +89,10 @@ 255 ] ], - "cmdUnderTest": "$TC action add action bpf object-file _c.o index 667", + "cmdUnderTest": "$TC action add action bpf object-file $EBPFDIR/action.o section action-ko index 667", "expExitCode": "255", "verifyCmd": "$TC action get action bpf index 667", - "matchPattern": "action order [0-9]*: bpf _c.o:\\[action\\] id [0-9].*index 667 ref", + "matchPattern": "action order [0-9]*: bpf action.o:\\[action-ko\\] id [0-9].*index 667 ref", "matchCount": "0", "teardown": [ [
@@ -101,7 +101,7 @@ 1, 255 ], - "rm -f _c.o" + "make -C bpf clean" ] }, {
tools/testing/selftests/tc-testing/tdc_config.py +3 -1
@@ -16,7 +16,9 @@ NAMES = { 'DEV2': '', 'BATCH_FILE': './batch.txt', # Name of the namespace to use - 'NS': 'tcut' + 'NS': 'tcut', + # Directory containing eBPF test programs + 'EBPFDIR': './bpf' }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 130/209 crypto: mxs-dcp - Fix SHA null hashes and output length
In reply to Sasha LevinFrom: Radu Solea <[email protected]>
[ Upstream commit c709eebaf5c5faa8a0f140355f9cfe67e8f7afb1 ]
DCP writes at least 32 bytes in the output buffer instead of hash length as documented. Add intermediate buffer to prevent write out of bounds.
When requested to produce null hashes DCP fails to produce valid output. Add software workaround to bypass hardware and return valid output.
--- drivers/crypto/mxs-dcp.c | 47 +++++++++++++++++++++++++++++++--------- 1 file changed, 37 insertions(+), 10 deletions(-)
drivers/crypto/mxs-dcp.c +37 -10
@@ -28,9 +28,24 @@#define DCP_MAX_CHANS 4#define DCP_BUF_SZ PAGE_SIZE +#define DCP_SHA_PAY_SZ 64#define DCP_ALIGNMENT 64 +/* +* Null hashes to align with hw behavior on imx6sl and ull +* these are flipped for consistency with hw output +*/ +const uint8_t sha1_null_hash[] = +"\x09\x07\xd8\xaf\x90\x18\x60\x95\xef\xbf" +"\x55\x32\x0d\x4b\x6b\x5e\xee\xa3\x39\xda" ; + +const uint8_t sha256_null_hash[] = +"\x55\xb8\x52\x78\x1b\x99\x95\xa4" +"\x4c\x93\x9b\x64\xe4\x41\xae\x27" +"\x24\xb9\x6f\x99\xc8\xf4\xfb\x9a" +"\x14\x1c\xfc\x98\x42\xc4\xb0\xe3" ; +/* DCP DMA descriptor. */ struct dcp_dma_desc {uint32_t next_cmd_addr;
@@ -48,6 +63,7 @@ struct dcp_coherent_block {uint8_t aes_in_buf[DCP_BUF_SZ ];uint8_t aes_out_buf[DCP_BUF_SZ ];uint8_t sha_in_buf[DCP_BUF_SZ ]; +uint8_t sha_out_buf[DCP_SHA_PAY_SZ ];uint8_t aes_key[2 *AES_KEYSIZE_128 ];
@@ -513,8 +529,6 @@ static int mxs_dcp_run_sha(struct ahash_request *req)struct crypto_ahash *tfm =crypto_ahash_reqtfm (req);struct dcp_async_ctx *actx =crypto_ahash_ctx (tfm);struct dcp_sha_req_ctx *rctx =ahash_request_ctx (req); -struct hash_alg_common *halg =crypto_hash_alg_common (tfm); -struct dcp_dma_desc *desc = &sdcp->coh->desc[actx->chan];dma_addr_t digest_phys =0 ;
@@ -536,10 +550,23 @@ static int mxs_dcp_run_sha(struct ahash_request *req) desc->payload =0 ; desc->status =0 ; +/* +* Align driver with hw behavior when generating null hashes +*/ +if (rctx->init && rctx->fini && desc->size ==0 ) { +struct hash_alg_common *halg =crypto_hash_alg_common (tfm); +const uint8_t *sha_buf = + (actx->alg ==MXS_DCP_CONTROL1_HASH_SELECT_SHA1 ) ? + sha1_null_hash : sha256_null_hash; +memcpy (sdcp->coh->sha_out_buf, sha_buf, halg->digestsize); + ret =0 ; + goto done_run; + } +/* Set HASH_TERM bit for last transfer block. */ if (rctx->fini) { - digest_phys =dma_map_single (sdcp->dev, req->result, - halg->digestsize,DMA_FROM_DEVICE ); + digest_phys =dma_map_single (sdcp->dev, sdcp->coh->sha_out_buf, +DCP_SHA_PAY_SZ ,DMA_FROM_DEVICE ); desc->control0 |=MXS_DCP_CONTROL0_HASH_TERM ; desc->payload = digest_phys; }
@@ -547,9 +574,10 @@ static int mxs_dcp_run_sha(struct ahash_request *req) ret =mxs_dcp_start_dma (actx);if (rctx->fini) -dma_unmap_single (sdcp->dev, digest_phys, halg->digestsize, +dma_unmap_single (sdcp->dev, digest_phys,DCP_SHA_PAY_SZ ,DMA_FROM_DEVICE ); +done_run:dma_unmap_single (sdcp->dev, buf_phys,DCP_BUF_SZ ,DMA_TO_DEVICE );return ret;
@@ -567,6 +595,7 @@ static int dcp_sha_req_to_buf(struct crypto_async_request *arq)const int nents =sg_nents (req->src);uint8_t *in_buf = sdcp->coh->sha_in_buf; +uint8_t *out_buf = sdcp->coh->sha_out_buf;uint8_t *src_buf;
@@ -621,11 +650,9 @@ static int dcp_sha_req_to_buf(struct crypto_async_request *arq) actx->fill =0 ; -/* For some reason, the result is flipped. */ -for (i =0 ; i < halg->digestsize /2 ; i++) { -swap (req->result[i], - req->result[halg->digestsize - i -1 ]); - } +/* For some reason the result is flipped */ +for (i =0 ; i < halg->digestsize; i++) + req->result[i] = out_buf[halg->digestsize - i -1 ]; }return 0 ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 129/209 dmaengine: rcar-dmac: set scatter/gather max segment size
In reply to Sasha LevinFrom: Wolfram Sang <[email protected]>
[ Upstream commit 97d49c59e219acac576e16293a6b8cb99302f62f ]
Fix warning when running with CONFIG_DMA_API_DEBUG_SG=y by allocating a device_dma_parameters structure and filling in the max segment size.
--- drivers/dma/sh/rcar-dmac.c | 3 +++ 1 file changed, 3 insertions(+)
drivers/dma/sh/rcar-dmac.c +3 -0
@@ -198,6 +198,7 @@ struct rcar_dmac {struct dma_device engine;struct device *dev;void __iomem *iomem; +struct device_dma_parameters parms;unsigned int n_channels;struct rcar_dmac_chan *channels;
@@ -1814,6 +1815,8 @@ static int rcar_dmac_probe(struct platform_device *pdev) dmac->dev = &pdev->dev;platform_set_drvdata (pdev, dmac); + dmac->dev->dma_parms = &dmac->parms; +dma_set_max_seg_size (dmac->dev,RCAR_DMATCR_MASK );dma_set_mask_and_coherent (dmac->dev,DMA_BIT_MASK (40 )); ret =rcar_dmac_parse_of (&pdev->dev, dmac);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 133/209 ACPI / SBS: Fix rare oops when removing modules
In reply to Sasha LevinFrom: Ronald Tschalär <[email protected]>
[ Upstream commit 757c968c442397f1249bb775a7c8c03842e3e0c7 ]
There was a small race when removing the sbshc module where smbus_alarm() had queued acpi_smbus_callback() for deferred execution but it hadn't been run yet, so that when it did run hc had been freed and the module unloaded, resulting in an invalid paging request.
A similar race existed when removing the sbs module with regards to acpi_sbs_callback() (which is called from acpi_smbus_callback()).
We therefore need to ensure no callbacks are pending or executing before the cleanups are done and the modules are removed.
--- drivers/acpi/osl.c | 1 + drivers/acpi/sbshc.c | 2 ++ 2 files changed, 3 insertions(+)
drivers/acpi/osl.c +1 -0
@@ -1132,6 +1132,7 @@ void acpi_os_wait_events_complete(void)flush_workqueue (kacpid_wq);flush_workqueue (kacpi_notify_wq); } +EXPORT_SYMBOL (acpi_os_wait_events_complete);struct acpi_hp_work {struct work_struct work;
drivers/acpi/sbshc.c +2 -0
@@ -196,6 +196,7 @@ int acpi_smbus_unregister_callback(struct acpi_smb_hc *hc) hc->callback =NULL ; hc->context =NULL ;mutex_unlock (&hc->lock); +acpi_os_wait_events_complete ();return 0 ; }
@@ -292,6 +293,7 @@ static int acpi_smbus_hc_remove(struct acpi_device *device) hc =acpi_driver_data (device);acpi_ec_remove_query_handler (hc->ec, hc->query_bit); +acpi_os_wait_events_complete ();kfree (hc); device->driver_data =NULL ;return 0 ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 134/209 iwlwifi: mvm: don't send keys when entering D3
In reply to Sasha LevinFrom: Sara Sharon <[email protected]>
[ Upstream commit 8c7fd6a365eb5b2647b2c01918730d0a485b9f85 ]
In the past, we needed to program the keys when entering D3. This was since we replaced the image. However, now that there is a single image, this is no longer needed. Note that RSC is sent separately in a new command. This solves issues with newer devices that support PN offload. Since driver re-sent the keys, the PN got zeroed and the receiver dropped the next packets, until PN caught up again.
--- drivers/net/wireless/intel/iwlwifi/mvm/d3.c | 4 +++- 1 file changed, 3 insertions(+), 1 deletion(-)
drivers/net/wireless/intel/iwlwifi/mvm/d3.c +3 -1
@@ -731,8 +731,10 @@ int iwl_mvm_wowlan_config_key_params(struct iwl_mvm *mvm, {struct iwl_wowlan_kek_kck_material_cmd kek_kck_cmd = {};struct iwl_wowlan_tkip_params_cmd tkip_cmd = {}; +bool unified =fw_has_capa (&mvm->fw->ucode_capa, +IWL_UCODE_TLV_CAPA_CNSLDTD_D3_D0_IMG );struct wowlan_key_data key_data = { - .configure_keys = !d0i3, + .configure_keys = !d0i3 && !unified, .use_rsc_tsc = false, .tkip = &tkip_cmd, .use_tkip = false,
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 136/209 x86/fsgsbase/64: Fix ptrace() to read the FS/GS base accurately
In reply to Sasha LevinFrom: Andy Lutomirski <[email protected]>
[ Upstream commit 07e1d88adaaeab247b300926f78cc3f950dbeda3 ]
On 64-bit kernels ptrace can read the FS/GS base using the register access APIs (PTRACE_PEEKUSER, etc.) or PTRACE_ARCH_PRCTL.
Make both of these mechanisms return the actual FS/GS base.
This will improve debuggability by providing the correct information to ptracer such as GDB.
[ chang: Rebased and revised patch description. ]
[ mingo: Revised the changelog some more. ]
--- arch/x86/kernel/ptrace.c | 62 +++++++++++++++++++++++++++++++++------- 1 file changed, 52 insertions(+), 10 deletions(-)
arch/x86/kernel/ptrace.c +52 -10
@@ -40,6 +40,7 @@#include <asm/hw_breakpoint.h> #include <asm/traps.h> #include <asm/syscall.h> +#include <asm/mmu_context.h> #include "tls.h"
@@ -343,6 +344,49 @@ static int set_segment_reg(struct task_struct *task,return 0 ; } +static unsigned long task_seg_base (struct task_struct *task, +unsigned short selector) +{ +unsigned short idx = selector >>3 ; +unsigned long base; + +if (likely ((selector &SEGMENT_TI_MASK ) ==0 )) { +if (unlikely (idx >=GDT_ENTRIES )) +return 0 ; + +/* +* There are no user segments in the GDT with nonzero bases +* other than the TLS segments. +*/ +if (idx <GDT_ENTRY_TLS_MIN || idx >GDT_ENTRY_TLS_MAX ) +return 0 ; + + idx -=GDT_ENTRY_TLS_MIN ; + base =get_desc_base (&task->thread.tls_array[idx]); + }else { +#ifdef CONFIG_MODIFY_LDT_SYSCALL +struct ldt_struct *ldt; + +/* +* If performance here mattered, we could protect the LDT +* with RCU. This is a slow path, though, so we can just +* take the mutex. +*/ +mutex_lock (&task->mm->context.lock); + ldt = task->mm->context.ldt; +if (unlikely (idx >= ldt->nr_entries)) + base =0 ; +else + base =get_desc_base (ldt->entries + idx); +mutex_unlock (&task->mm->context.lock); +#else + base =0 ; +#endif + } + +return base; +} +#endif /* CONFIG_X86_32 */ static unsigned long get_flags (struct task_struct *task)
@@ -436,18 +480,16 @@ static unsigned long getreg(struct task_struct *task, unsigned long offset)#ifdef CONFIG_X86_64 case offsetof(struct user_regs_struct , fs_base): { -/* -* XXX: This will not behave as expected if called on -* current or if fsindex != 0. -*/ -return task->thread.fsbase; +if (task->thread.fsindex ==0 ) +return task->thread.fsbase; +else +return task_seg_base (task, task->thread.fsindex); }case offsetof(struct user_regs_struct , gs_base): { -/* -* XXX: This will not behave as expected if called on -* current or if fsindex != 0. -*/ -return task->thread.gsbase; +if (task->thread.gsindex ==0 ) +return task->thread.gsbase; +else +return task_seg_base (task, task->thread.gsindex); }#endif }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 144/209 reset: Fix potential use-after-free in __of_reset_control_get()
In reply to Sasha LevinFrom: Geert Uytterhoeven <[email protected]>
[ Upstream commit b790c8ea5593d6dc3580adfad8e117eeb56af874 ]
Calling of_node_put() decreases the reference count of a device tree object, and may free some data.
However, the of_phandle_args structure embedding it is passed to reset_controller_dev.of_xlate() after that, so it may still be accessed.
Move the call to of_node_put() down to fix this.
--- drivers/reset/core.c | 15 ++++++++------- 1 file changed, 8 insertions(+), 7 deletions(-)
drivers/reset/core.c +8 -7
@@ -496,28 +496,29 @@ struct reset_control *__of_reset_control_get(struct device_node *node,break ; } } -of_node_put (args.np);if (!rcdev) { -mutex_unlock (&reset_list_mutex); -return ERR_PTR (-EPROBE_DEFER ); + rstc =ERR_PTR (-EPROBE_DEFER ); + goto out; }if (WARN_ON (args.args_count != rcdev->of_reset_n_cells)) { -mutex_unlock (&reset_list_mutex); -return ERR_PTR (-EINVAL ); + rstc =ERR_PTR (-EINVAL ); + goto out; } rstc_id = rcdev->of_xlate (rcdev, &args);if (rstc_id <0 ) { -mutex_unlock (&reset_list_mutex); -return ERR_PTR (rstc_id); + rstc =ERR_PTR (rstc_id); + goto out; }/* reset_list_mutex also protects the rcdev's reset_control list */ rstc =__reset_control_get_internal (rcdev, rstc_id, shared); +out:mutex_unlock (&reset_list_mutex); +of_node_put (args.np);return rstc; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 149/209 media: dw9807-vcm: Fix probe error handling
In reply to Sasha LevinFrom: Sakari Ailus <[email protected]>
[ Upstream commit 9e5b5081fa117ae34eca94b63b1cb6d43dc28f10 ]
v4l2_async_unregister_subdev() may not be called without v4l2_async_register_subdev() being called first. Fix this.
--- drivers/media/i2c/dw9807-vcm.c | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)
drivers/media/i2c/dw9807-vcm.c +2 -1
@@ -218,7 +218,8 @@ static int dw9807_probe(struct i2c_client *client)return 0 ; err_cleanup: -dw9807_subdev_cleanup (dw9807_dev); +v4l2_ctrl_handler_free (&dw9807_dev->ctrls_vcm); +media_entity_cleanup (&dw9807_dev->sd.entity);return rval; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 153/209 x86/intel_rdt: Introduce utility to obtain CDP peer
In reply to Sasha LevinFrom: Reinette Chatre <[email protected]>
[ Upstream commit 521348b011d64cf3febb10b64ba5b472681bef94 ]
Introduce a utility that, when provided with a RDT resource and an instance of this RDT resource (a RDT domain), would return pointers to the RDT resource and RDT domain that share the same hardware. This is specific to the CDP resources that share the same hardware.
For example, if a pointer to the RDT_RESOURCE_L2DATA resource (struct rdt_resource) and a pointer to an instance of this resource (struct rdt_domain) is provided, then it will return a pointer to the RDT_RESOURCE_L2CODE resource as well as the specific instance that shares the same hardware as the provided rdt_domain.
This utility is created in support of the "exclusive" resource group mode where overlap of resource allocation between resource groups need to be avoided. The overlap test need to consider not just the matching resources, but also the resources that share the same hardware.
Temporarily mark it as unused in support of patch testing to avoid compile warnings until it is used.
--- arch/x86/kernel/cpu/intel_rdt_rdtgroup.c | 72 ++++++++++++++++++++++++ 1 file changed, 72 insertions(+)
arch/x86/kernel/cpu/intel_rdt_rdtgroup.c +72 -0
@@ -964,6 +964,78 @@ static int rdtgroup_mode_show(struct kernfs_open_file *of,return 0 ; } +/** +* rdt_cdp_peer_get - Retrieve CDP peer if it exists +* @r: RDT resource to which RDT domain @d belongs +* @d: Cache instance for which a CDP peer is requested +* @r_cdp: RDT resource that shares hardware with @r (RDT resource peer) +* Used to return the result. +* @d_cdp: RDT domain that shares hardware with @d (RDT domain peer) +* Used to return the result. +* +* RDT resources are managed independently and by extension the RDT domains +* (RDT resource instances) are managed independently also. The Code and +* Data Prioritization (CDP) RDT resources, while managed independently, +* could refer to the same underlying hardware. For example, +* RDT_RESOURCE_L2CODE and RDT_RESOURCE_L2DATA both refer to the L2 cache. +* +* When provided with an RDT resource @r and an instance of that RDT +* resource @d rdt_cdp_peer_get() will return if there is a peer RDT +* resource and the exact instance that shares the same hardware. +* +* Return: 0 if a CDP peer was found, <0 on error or if no CDP peer exists. +* If a CDP peer was found, @r_cdp will point to the peer RDT resource +* and @d_cdp will point to the peer RDT domain. +*/ +static int __attribute__((unused))rdt_cdp_peer_get (struct rdt_resource *r, +struct rdt_domain *d, +struct rdt_resource **r_cdp, +struct rdt_domain **d_cdp) +{ +struct rdt_resource *_r_cdp =NULL ; +struct rdt_domain *_d_cdp =NULL ; +int ret =0 ; + +switch (r->rid) { +case RDT_RESOURCE_L3DATA : + _r_cdp = &rdt_resources_all[RDT_RESOURCE_L3CODE ]; +break ; +case RDT_RESOURCE_L3CODE : + _r_cdp = &rdt_resources_all[RDT_RESOURCE_L3DATA ]; +break ; +case RDT_RESOURCE_L2DATA : + _r_cdp = &rdt_resources_all[RDT_RESOURCE_L2CODE ]; +break ; +case RDT_RESOURCE_L2CODE : + _r_cdp = &rdt_resources_all[RDT_RESOURCE_L2DATA ]; +break ; +default : + ret = -ENOENT ; + goto out; + } + +/* +* When a new CPU comes online and CDP is enabled then the new +* RDT domains (if any) associated with both CDP RDT resources +* are added in the same CPU online routine while the +* rdtgroup_mutex is held. It should thus not happen for one +* RDT domain to exist and be associated with its RDT CDP +* resource but there is no RDT domain associated with the +* peer RDT CDP resource. Hence the WARN. +*/ + _d_cdp =rdt_find_domain (_r_cdp, d->id,NULL ); +if (WARN_ON (!_d_cdp)) { + _r_cdp =NULL ; + ret = -EINVAL ; + } + +out: + *r_cdp = _r_cdp; + *d_cdp = _d_cdp; + +return ret; +} +/** * rdtgroup_cbm_overlaps - Does CBM for intended closid overlap with other * @r: Resource to which domain instance @d belongs.
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 154/209 x86/intel_rdt: CBM overlap should also check for overlap with CDP peer
In reply to Sasha LevinFrom: Reinette Chatre <[email protected]>
[ Upstream commit e5f3530c391105fdd6174852e3ea6136d073b45a ]
The CBM overlap test is used to manage the allocations of RDT resources where overlap is possible between resource groups. When a resource group is in exclusive mode then there should be no overlap between resource groups.
The current overlap test only considers overlap between the same resources, for example, that usage of a RDT_RESOURCE_L2DATA resource in one resource group does not overlap with usage of a RDT_RESOURCE_L2DATA resource in another resource group. The problem with this is that it allows overlap between a RDT_RESOURCE_L2DATA resource in one resource group with a RDT_RESOURCE_L2CODE resource in another resource group - even if both resource groups are in exclusive mode. This is a problem because even though these appear to be different resources they end up sharing the same underlying hardware and thus does not fulfill the user's request for exclusive use of hardware resources.
Fix this by including the CDP peer (if there is one) in every CBM overlap test. This does not impact the overlap between resources within the same exclusive resource group that is allowed.
--- arch/x86/kernel/cpu/intel_rdt_rdtgroup.c | 48 ++++++++++++++++++++---- 1 file changed, 41 insertions(+), 7 deletions(-)
arch/x86/kernel/cpu/intel_rdt_rdtgroup.c +41 -7
@@ -987,10 +987,9 @@ static int rdtgroup_mode_show(struct kernfs_open_file *of,* If a CDP peer was found, @r_cdp will point to the peer RDT resource * and @d_cdp will point to the peer RDT domain. */ -static int __attribute__((unused))rdt_cdp_peer_get (struct rdt_resource *r, -struct rdt_domain *d, -struct rdt_resource **r_cdp, -struct rdt_domain **d_cdp) +static int rdt_cdp_peer_get (struct rdt_resource *r,struct rdt_domain *d, +struct rdt_resource **r_cdp, +struct rdt_domain **d_cdp) {struct rdt_resource *_r_cdp =NULL ;struct rdt_domain *_d_cdp =NULL ;
@@ -1037,7 +1036,7 @@ static int __attribute__((unused)) rdt_cdp_peer_get(struct rdt_resource *r, }/** -* rdtgroup_cbm_overlaps - Does CBM for intended closid overlap with other +* __rdtgroup_cbm_overlaps - Does CBM for intended closid overlap with other * @r: Resource to which domain instance @d belongs. * @d: The domain instance for which @closid is being tested. * @cbm: Capacity bitmask being tested.
@@ -1056,8 +1055,8 @@ static int __attribute__((unused)) rdt_cdp_peer_get(struct rdt_resource *r,* * Return: false if CBM does not overlap, true if it does. */ -bool rdtgroup_cbm_overlaps (struct rdt_resource *r,struct rdt_domain *d, -unsigned long cbm,int closid,bool exclusive) +static bool __rdtgroup_cbm_overlaps (struct rdt_resource *r,struct rdt_domain *d, +unsigned long cbm,int closid,bool exclusive) {enum rdtgrp_mode mode;unsigned long ctrl_b;
@@ -1092,6 +1091,41 @@ bool rdtgroup_cbm_overlaps(struct rdt_resource *r, struct rdt_domain *d,return false; } +/** +* rdtgroup_cbm_overlaps - Does CBM overlap with other use of hardware +* @r: Resource to which domain instance @d belongs. +* @d: The domain instance for which @closid is being tested. +* @cbm: Capacity bitmask being tested. +* @closid: Intended closid for @cbm. +* @exclusive: Only check if overlaps with exclusive resource groups +* +* Resources that can be allocated using a CBM can use the CBM to control +* the overlap of these allocations. rdtgroup_cmb_overlaps() is the test +* for overlap. Overlap test is not limited to the specific resource for +* which the CBM is intended though - when dealing with CDP resources that +* share the underlying hardware the overlap check should be performed on +* the CDP resource sharing the hardware also. +* +* Refer to description of __rdtgroup_cbm_overlaps() for the details of the +* overlap test. +* +* Return: true if CBM overlap detected, false if there is no overlap +*/ +bool rdtgroup_cbm_overlaps (struct rdt_resource *r,struct rdt_domain *d, +unsigned long cbm,int closid,bool exclusive) +{ +struct rdt_resource *r_cdp; +struct rdt_domain *d_cdp; + +if (__rdtgroup_cbm_overlaps (r, d, cbm, closid, exclusive)) +return true; + +if (rdt_cdp_peer_get (r, d, &r_cdp, &d_cdp) <0 ) +return false; + +return __rdtgroup_cbm_overlaps (r_cdp, d_cdp, cbm, closid, exclusive); +} +/** * rdtgroup_mode_test_exclusive - Test if this resource group can be exclusive *
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 151/209 mtd: spi-nor: cadence-quadspi: Use proper enum for dma_[un]map_single
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit 900f5e0d8c9edc5dacc57873d22aee2ae699a8e1 ]
Clang warns when one enumerated type is converted implicitly to another.
drivers/mtd/spi-nor/cadence-quadspi.c:962:47: warning: implicit conversion from enumeration type 'enum dma_transfer_direction' to different enumeration type 'enum dma_data_direction' [-Wenum-conversion]
dma_dst = dma_map_single(nor->dev, buf, len, DMA_DEV_TO_MEM);
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~^~~~~~~~~~~~~~~
./include/linux/dma-mapping.h:428:66: note: expanded from macro
'dma_map_single'
~~~~~~~~~~~~~~~~~~~~ ^
drivers/mtd/spi-nor/cadence-quadspi.c:997:43: warning: implicit
conversion from enumeration type 'enum dma_transfer_direction' to
different enumeration type 'enum dma_data_direction' [-Wenum-conversion]
dma_unmap_single(nor->dev, dma_dst, len, DMA_DEV_TO_MEM);
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~^~~~~~~~~~~~~~~
./include/linux/dma-mapping.h:429:70: note: expanded from macro
'dma_unmap_single'
~~~~~~~~~~~~~~~~~~~~~~ ^2 warnings generated.
Use the proper enums from dma_data_direction to satisfy Clang.
DMA_FROM_DEVICE = DMA_DEV_TO_MEM = 2
--- drivers/mtd/spi-nor/cadence-quadspi.c | 4 ++-- 1 file changed, 2 insertions(+), 2 deletions(-)
drivers/mtd/spi-nor/cadence-quadspi.c +2 -2
@@ -972,7 +972,7 @@ static int cqspi_direct_read_execute(struct spi_nor *nor, u_char *buf,return 0 ; } - dma_dst =dma_map_single (nor->dev, buf, len,DMA_DEV_TO_MEM ); + dma_dst =dma_map_single (nor->dev, buf, len,DMA_FROM_DEVICE );if (dma_mapping_error (nor->dev, dma_dst)) {dev_err (nor->dev,"dma mapping failed\n" );return -ENOMEM ;
@@ -1007,7 +1007,7 @@ static int cqspi_direct_read_execute(struct spi_nor *nor, u_char *buf, } err_unmap: -dma_unmap_single (nor->dev, dma_dst, len,DMA_DEV_TO_MEM ); +dma_unmap_single (nor->dev, dma_dst, len,DMA_FROM_DEVICE );return ret; }
Signature · 6 lines
2.20.1 ______________________________________________________ Linux MTD discussion mailing list http://lists.infradead.org/mailman/listinfo/linux-mtd/
Sasha Levin
maintainerPATCH 156/209 s390/kasan: avoid vdso instrumentation
In reply to Sasha LevinFrom: Vasily Gorbik <[email protected]>
[ Upstream commit 348498458505e202df41b6b9a78da448d39298b7 ]
vdso is mapped into user space processes, which won't have kasan shodow mapped.
--- arch/s390/kernel/vdso32/Makefile | 3 ++- arch/s390/kernel/vdso64/Makefile | 3 ++- 2 files changed, 4 insertions(+), 2 deletions(-)
arch/s390/kernel/vdso32/Makefile +2 -1
@@ -28,9 +28,10 @@ obj-y += vdso32_wrapper.o extra-y += vdso32.lds CPPFLAGS_vdso32.lds += -P -C -U$(ARCH) -# Disable gcov profiling and ubsan for VDSO code +# Disable gcov profiling, ubsan and kasan for VDSO code GCOV_PROFILE := n UBSAN_SANITIZE := n +KASAN_SANITIZE := n # Force dependency (incbin is bad) $(obj)/vdso32_wrapper.o : $(obj)/vdso32.so
arch/s390/kernel/vdso64/Makefile +2 -1
@@ -28,9 +28,10 @@ obj-y += vdso64_wrapper.o extra-y += vdso64.lds CPPFLAGS_vdso64.lds += -P -C -U$(ARCH) -# Disable gcov profiling and ubsan for VDSO code +# Disable gcov profiling, ubsan and kasan for VDSO code GCOV_PROFILE := n UBSAN_SANITIZE := n +KASAN_SANITIZE := n # Force dependency (incbin is bad) $(obj)/vdso64_wrapper.o : $(obj)/vdso64.so
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 157/209 s390/kasan: avoid instrumentation of early C code
In reply to Sasha LevinFrom: Vasily Gorbik <[email protected]>
[ Upstream commit 0a9b40911baffac6fc9cc2d88e893585870a97f7 ]
Instrumented C code cannot run without the kasan shadow area. Exempt source code files from kasan which are running before / used during kasan initialization.
--- arch/s390/boot/Makefile | 1 + arch/s390/boot/compressed/Makefile | 1 + arch/s390/kernel/Makefile | 2 ++ drivers/s390/char/Makefile | 1 + 4 files changed, 5 insertions(+)
arch/s390/boot/Makefile +1 -0
@@ -6,6 +6,7 @@ KCOV_INSTRUMENT := n GCOV_PROFILE := n UBSAN_SANITIZE := n +KASAN_SANITIZE := n KBUILD_AFLAGS := $(KBUILD_AFLAGS_DECOMPRESSOR) KBUILD_CFLAGS := $(KBUILD_CFLAGS_DECOMPRESSOR)
arch/s390/boot/compressed/Makefile +1 -0
@@ -8,6 +8,7 @@ KCOV_INSTRUMENT := n GCOV_PROFILE := n UBSAN_SANITIZE := n +KASAN_SANITIZE := n obj-y := $(if $(CONFIG_KERNEL_UNCOMPRESSED),,head.o misc.o) piggy.o targets := vmlinux.lds vmlinux vmlinux.bin vmlinux.bin.gz vmlinux.bin.bz2
arch/s390/kernel/Makefile +2 -0
@@ -23,6 +23,8 @@ KCOV_INSTRUMENT_early_nobss.o := n UBSAN_SANITIZE_early.o := n UBSAN_SANITIZE_early_nobss.o := n +KASAN_SANITIZE_early_nobss.o := n + # # Passing null pointers is ok for smp code, since we access the lowcore here. #
drivers/s390/char/Makefile +1 -0
@@ -11,6 +11,7 @@ endif GCOV_PROFILE_sclp_early_core.o := n KCOV_INSTRUMENT_sclp_early_core.o := n UBSAN_SANITIZE_sclp_early_core.o := n +KASAN_SANITIZE_sclp_early_core.o := n CFLAGS_sclp_early_core.o += -D__NO_FORTIFY
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 158/209 s390/kasan: avoid user access code instrumentation
In reply to Sasha LevinFrom: Vasily Gorbik <[email protected]>
[ Upstream commit b6cbe3e8bdff6f21f1b58b08a55f479cdcf98282 ]
Kasan instrumentation adds "store" check for variables marked as modified by inline assembly. With user pointers containing addresses from another address space this produces false positives.
static inline unsigned long clear_user_xc(void __user *to, ...)
{
asm volatile(
...
: "+a" (to) ...User space access functions are wrapped by manually instrumented functions in kasan common code, which should be sufficient to catch errors. So, we just disable uaccess.o instrumentation altogether.
--- arch/s390/lib/Makefile | 4 ++++ 1 file changed, 4 insertions(+)
arch/s390/lib/Makefile +4 -0
@@ -9,5 +9,9 @@ lib-$(CONFIG_SMP) += spinlock.o lib-$(CONFIG_KPROBES) += probes.o lib-$(CONFIG_UPROBES) += probes.o +# Instrumenting memory accesses to __user data (in different address space) +# produce false positives +KASAN_SANITIZE_uaccess.o := n + chkbss := mem.o include $(srctree)/arch/s390/scripts/Makefile.chkbss
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 159/209 proc/vmcore: Fix i386 build error of missing copy_oldmem_page_encrypted()
In reply to Sasha LevinFrom: Borislav Petkov <[email protected]>
[ Upstream commit cf089611f4c446285046fcd426d90c18f37d2905 ]
Lianbo reported a build error with a particular 32-bit config, see Link below for details.
Provide a weak copy_oldmem_page_encrypted() function which architectures can override, in the same manner other functionality in that file is supplied.
--- fs/proc/vmcore.c | 10 ++++++++++ 1 file changed, 10 insertions(+)
fs/proc/vmcore.c +10 -0
@@ -176,6 +176,16 @@ int __weak remap_oldmem_pfn_range(struct vm_area_struct *vma,return remap_pfn_range (vma, from, pfn, size, prot); } +/* +* Architectures which support memory encryption override this. +*/ +ssize_t __weak +copy_oldmem_page_encrypted (unsigned long pfn,char *buf,size_t csize, +unsigned long offset,int userbuf) +{ +return copy_oldmem_page (pfn, buf, csize, offset, userbuf); +} +/* * Copy to either kernel or user space */
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 152/209 mtd: devices: m25p80: Make sure WRITE_EN is issued before each write
In reply to Sasha LevinFrom: Yogesh Gaur <[email protected]>
[ Upstream commit 3baa8ec88c2feb902328e59a4dcf0f0aaab7d2ff ]
Some SPI controllers can't write nor->page_size bytes in a single step because their TX FIFO is too small, but when that happens we should make sure a WRITE_EN command before each write access and READ_SR command after each write access is issued.
The core is already taking care of that, so all we have to do here is return the actual number of bytes that were written during the spi_mem_exec_op() operation.
--- drivers/mtd/devices/m25p80.c | 23 ++++++++--------------- 1 file changed, 8 insertions(+), 15 deletions(-)
drivers/mtd/devices/m25p80.c +8 -15
@@ -90,7 +90,6 @@ static ssize_t m25p80_write(struct spi_nor *nor, loff_t to, size_t len,SPI_MEM_OP_ADDR (nor->addr_width, to,1 ),SPI_MEM_OP_NO_DUMMY , SPI_MEM_OP_DATA_OUT(len, buf, 1)); -size_t remaining = len;int ret;/* get transfer protocols. */
@@ -101,22 +100,16 @@ static ssize_t m25p80_write(struct spi_nor *nor, loff_t to, size_t len,if (nor->program_opcode ==SPINOR_OP_AAI_WP && nor->sst_write_second) op.addr.nbytes =0 ; -while (remaining) { - op.data.nbytes = remaining <UINT_MAX ? remaining :UINT_MAX ; - ret =spi_mem_adjust_op_size (flash->spimem, &op); -if (ret) -return ret; - - ret =spi_mem_exec_op (flash->spimem, &op); -if (ret) -return ret; + ret =spi_mem_adjust_op_size (flash->spimem, &op); +if (ret) +return ret; + op.data.nbytes = len < op.data.nbytes ? len : op.data.nbytes; - op.addr.val += op.data.nbytes; - remaining -= op.data.nbytes; - op.data.buf.out += op.data.nbytes; - } + ret =spi_mem_exec_op (flash->spimem, &op); +if (ret) +return ret; -return len; +return op.data.nbytes; }/*
Signature · 6 lines
2.20.1 ______________________________________________________ Linux MTD discussion mailing list http://lists.infradead.org/mailman/listinfo/linux-mtd/
Sasha Levin
maintainerPATCH 165/209 media: cx231xx: fix potential sign-extension overflow on large shift
In reply to Sasha LevinFrom: Colin Ian King <[email protected]>
[ Upstream commit 32ae592036d7aeaabcccb2b1715373a68639a768 ]
Shifting the u8 value[3] by an int can lead to sign-extension overflow. For example, if value[3] is 0xff and the shift is 24 then it is promoted to int and then the top bit is sign-extended so that all upper 32 bits are set. Fix this by casting value[3] to a u32 before the shift.
Detected by CoverityScan, CID#1016522 ("Unintended sign extension")
--- drivers/media/usb/cx231xx/cx231xx-video.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/media/usb/cx231xx/cx231xx-video.c +1 -1
@@ -1389,7 +1389,7 @@ int cx231xx_g_register(struct file *file, void *priv, ret =cx231xx_read_ctrl_reg (dev,VRT_GET_REGISTER , (u16 )reg->reg, value,4 ); reg->val = value[0 ] | value[1 ] <<8 | - value[2 ] <<16 | value[3 ] <<24 ; + value[2 ] <<16 | (u32 )value[3 ] <<24 ; reg->size =4 ;break ;case 1 :/* AFE - read byte */
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 166/209 media: venus: vdec: fix decoded data size
In reply to Sasha LevinFrom: Vikash Garodia <[email protected]>
[ Upstream commit ce32c0a530bd955206fe45c2eff77e581202d699 ]
Existing code returns the max of the decoded size and buffer size. It turns out that buffer size is always greater due to hardware alignment requirement. As a result, payload size given to client is incorrect. This change ensures that the bytesused is assigned to actual payload size, when available.
--- drivers/media/platform/qcom/venus/vdec.c | 3 +-- 1 file changed, 1 insertion(+), 2 deletions(-)
drivers/media/platform/qcom/venus/vdec.c +1 -2
@@ -888,8 +888,7 @@ static void vdec_buf_done(struct venus_inst *inst, unsigned int buf_type,unsigned int opb_sz =venus_helper_get_opb_size (inst); vb = &vbuf->vb2_buf; - vb->planes[0 ].bytesused = - max_t(unsigned int, opb_sz, bytesused); +vb2_set_plane_payload (vb,0 , bytesused ? : opb_sz); vb->planes[0 ].data_offset = data_offset; vb->timestamp = timestamp_us *NSEC_PER_USEC ; vbuf->sequence = inst->sequence_cap++;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 167/209 ALSA: hda/ca0132 - Fix input effect controls for desktop cards
In reply to Sasha LevinFrom: Connor McAdams <[email protected]>
[ Upstream commit 7a2dc84fc480aec4f8f96e152327423014edf668 ]
This patch removes the echo cancellation control for desktop cards, and makes use of the special 0x47 SCP command for noise reduction.
--- sound/pci/hda/patch_ca0132.c | 8 ++++---- 1 file changed, 4 insertions(+), 4 deletions(-)
sound/pci/hda/patch_ca0132.c +4 -4
@@ -4520,7 +4520,7 @@ static int ca0132_effects_set(struct hda_codec *codec, hda_nid_t nid, long val) val =0 ;/* If Voice Focus on SBZ, set to two channel. */ -if ((nid ==VOICE_FOCUS ) && (spec->quirk ==QUIRK_SBZ ) +if ((nid ==VOICE_FOCUS ) && (spec->use_pci_mmio) && (spec->cur_mic_type !=REAR_LINE_IN )) {if (spec->effects_switch[CRYSTAL_VOICE -EFFECT_START_NID ]) {
@@ -4539,7 +4539,7 @@ static int ca0132_effects_set(struct hda_codec *codec, hda_nid_t nid, long val)* For SBZ noise reduction, there's an extra command * to module ID 0x47. No clue why. */ -if ((nid ==NOISE_REDUCTION ) && (spec->quirk ==QUIRK_SBZ ) +if ((nid ==NOISE_REDUCTION ) && (spec->use_pci_mmio) && (spec->cur_mic_type !=REAR_LINE_IN )) {if (spec->effects_switch[CRYSTAL_VOICE -EFFECT_START_NID ]) {
@@ -5855,8 +5855,8 @@ static int ca0132_build_controls(struct hda_codec *codec)*/ num_fx =OUT_EFFECTS_COUNT +IN_EFFECTS_COUNT ;for (i =0 ; i < num_fx; i++) { -/* SBZ and R3D break if Echo Cancellation is used. */ -if (spec->quirk ==QUIRK_SBZ || spec->quirk ==QUIRK_R3D ) { +/* Desktop cards break if Echo Cancellation is used. */ +if (spec->use_pci_mmio) {if (i == (ECHO_CANCELLATION -IN_EFFECT_START_NID +OUT_EFFECTS_COUNT ))continue ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 168/209 lightnvm: pblk: fix rqd.error return value in pblk_blk_erase_sync
In reply to Sasha LevinFrom: Matias Bjørling <[email protected]>
[ Upstream commit 4b5d56edb8fc565c5db029aecaea598eadfba7f6 ]
rqd.error is masked by the return value of pblk_submit_io_sync. The rqd structure is then passed on to the end_io function, which assumes that any error should lead to a chunk being marked offline/bad. Since the pblk_submit_io_sync can fail before the command is issued to the device, the error value maybe not correspond to a media failure, leading to chunks being immaturely retired.
Also, the pblk_blk_erase_sync function prints an error message in case the erase fails. Since the caller prints an error message by itself, remove the error message in this function.
--- drivers/lightnvm/pblk-core.c | 19 ++----------------- 1 file changed, 2 insertions(+), 17 deletions(-)
drivers/lightnvm/pblk-core.c +2 -17
@@ -893,10 +893,8 @@ static void pblk_setup_e_rq(struct pblk *pblk, struct nvm_rq *rqd,static int pblk_blk_erase_sync (struct pblk *pblk,struct ppa_addr ppa) { -struct nvm_rq rqd; -int ret =0 ; - -memset (&rqd,0 ,sizeof (struct nvm_rq )); +struct nvm_rq rqd = {NULL }; +int ret;pblk_setup_e_rq (pblk, &rqd, ppa);
@@ -904,19 +902,6 @@ static int pblk_blk_erase_sync(struct pblk *pblk, struct ppa_addr ppa)* with writes. Thus, there is no need to take the LUN semaphore. */ ret =pblk_submit_io_sync (pblk, &rqd); -if (ret) { -struct nvm_tgt_dev *dev = pblk->dev; -struct nvm_geo *geo = &dev->geo; - -pblk_err (pblk,"could not sync erase line:%d,blk:%d\n" , -pblk_ppa_to_line (ppa), -pblk_ppa_to_pos (geo, ppa)); - - rqd.error = ret; - goto out; - } - -out: rqd.private = pblk;__pblk_end_io_erase (pblk, &rqd);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 175/209 lightnvm: pblk: consider max hw sectors supported for max_write_pgs
In reply to Sasha LevinFrom: Zhoujie Wu <[email protected]>
[ Upstream commit 8a57fc3823d08edb1661a06d9e0a8c2365ac561e ]
When do GC, the number of read/write sectors are determined by max_write_pgs(see gc_rq preparation in pblk_gc_line_prepare_ws).
Due to max_write_pgs doesn't consider max hw sectors supported by nvme controller(128K), which leads to GC tries to read 64 * 4K in one command, and see below error caused by pblk_bio_map_addr in function pblk_submit_read_gc.
[ 2923.005376] pblk: could not add page to bio [ 2923.005377] pblk: could not allocate GC bio (18446744073709551604)
--- drivers/lightnvm/pblk-init.c | 2 ++ 1 file changed, 2 insertions(+)
drivers/lightnvm/pblk-init.c +2 -0
@@ -375,6 +375,8 @@ static int pblk_core_init(struct pblk *pblk) pblk->min_write_pgs = geo->ws_opt; max_write_ppas = pblk->min_write_pgs * geo->all_luns; pblk->max_write_pgs =min_t (int, max_write_ppas,NVM_MAX_VLBA ); + pblk->max_write_pgs =min_t (int, pblk->max_write_pgs, +queue_max_hw_sectors (dev->q) / (geo->csecs >>SECTOR_SHIFT ));pblk_set_sec_per_write (pblk, pblk->min_write_pgs);if (pblk->max_write_pgs >PBLK_MAX_REQ_ADDRS ) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 170/209 lightnvm: pblk: guarantee emeta on line close
In reply to Sasha LevinFrom: Javier González <[email protected]>
[ Upstream commit 9cc85bc761f83da41935cdd6edcdb7c122bc90bf ]
If a line is recovered from open chunks, the memory structures for emeta have not necessarily been properly set on line initialization. When closing a line, make sure that emeta is consistent so that the line can be recovered on the fast path on next reboot.
Also, remove a couple of empty lines at the end of the function.
--- drivers/lightnvm/pblk-core.c | 13 +++++++++++-- 1 file changed, 11 insertions(+), 2 deletions(-)
drivers/lightnvm/pblk-core.c +11 -2
@@ -1773,6 +1773,17 @@ void pblk_line_close_meta(struct pblk *pblk, struct pblk_line *line) wa->pad =cpu_to_le64 (atomic64_read (&pblk->pad_wa)); wa->gc =cpu_to_le64 (atomic64_read (&pblk->gc_wa)); +if (le32_to_cpu (emeta_buf->header.identifier) !=PBLK_MAGIC ) { + emeta_buf->header.identifier =cpu_to_le32 (PBLK_MAGIC ); +memcpy (emeta_buf->header.uuid, pblk->instance_uuid,16 ); + emeta_buf->header.id =cpu_to_le32 (line->id); + emeta_buf->header.type =cpu_to_le16 (line->type); + emeta_buf->header.version_major =EMETA_VERSION_MAJOR ; + emeta_buf->header.version_minor =EMETA_VERSION_MINOR ; + emeta_buf->header.crc =cpu_to_le32 ( +pblk_calc_meta_header_crc (pblk, &emeta_buf->header)); + } + emeta_buf->nr_valid_lbas =cpu_to_le64 (line->nr_valid_lbas); emeta_buf->crc =cpu_to_le32 (pblk_calc_emeta_crc (pblk, emeta_buf));
@@ -1790,8 +1801,6 @@ void pblk_line_close_meta(struct pblk *pblk, struct pblk_line *line)spin_unlock (&l_mg->close_lock);pblk_line_should_sync_meta (pblk); - - }static void pblk_save_lba_list (struct pblk *pblk,struct pblk_line *line)
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 173/209 lightnvm: do no update csecs and sos on 1.2
In reply to Sasha LevinFrom: Javier González <[email protected]>
[ Upstream commit 6fd05cad5ee1290b276dd8ed90a1e019b1fa577a ]
1.2 devices exposes their data and metadata size through the separate identify command. Make sure that the NVMe LBA format does not override these values.
--- drivers/nvme/host/lightnvm.c | 3 +++ 1 file changed, 3 insertions(+)
drivers/nvme/host/lightnvm.c +3 -0
@@ -968,6 +968,9 @@ void nvme_nvm_update_nvm_info(struct nvme_ns *ns)struct nvm_dev *ndev = ns->ndev;struct nvm_geo *geo = &ndev->geo; +if (geo->version ==NVM_OCSSD_SPEC_12 ) +return ; + geo->csecs =1 << ns->lba_shift; geo->sos = ns->ms; }
Signature · 7 lines
2.20.1 _______________________________________________ Linux-nvme mailing list [email protected] http://lists.infradead.org/mailman/listinfo/linux-nvme
Sasha Levin
maintainerPATCH 172/209 lightnvm: pblk: guarantee mw_cunits on read buffer
In reply to Sasha LevinFrom: Javier González <[email protected]>
[ Upstream commit d672d92d9c433c365fd6cdb4da1c02562b5f1178 ]
OCSSD 2.0 defines the amount of data that the host must buffer per chunk to guarantee reads through the geometry field mw_cunits. This value is the base that pblk uses to determine the size of its read buffer. Currently, this size is set to be the closes power-of-2 to mw_cunits times the number of parallel units available to the pblk instance for each open line (currently one). When an entry (4KB) is put in the buffer, the L2P table points to it. As the buffer wraps up, the L2P is updated to point to addresses on the device, thus guaranteeing mw_cunits at a chunk level.
However, given that pblk cannot write to the device under ws_min (normally ws_opt), there might be a window in which the buffer starts wrapping up and updating L2P entries before the mw_cunits value in a chunk has been surpassed.
In order not to violate the mw_cunits constrain in this case, account for ws_opt on the read buffer creation.
--- drivers/lightnvm/pblk-init.c | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)
drivers/lightnvm/pblk-init.c +2 -1
@@ -181,7 +181,8 @@ static int pblk_rwb_init(struct pblk *pblk)unsigned int power_size, power_seg_sz;int pgs_in_buffer; - pgs_in_buffer =max (geo->mw_cunits, geo->ws_opt) * geo->all_luns; + pgs_in_buffer = (max (geo->mw_cunits, geo->ws_opt) + geo->ws_opt) + * geo->all_luns;if (write_buffer_size && (write_buffer_size > pgs_in_buffer)) buffer_size = write_buffer_size;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 176/209 x86/kexec: Correct KEXEC_BACKUP_SRC_END off-by-one error
In reply to Sasha LevinFrom: Bjorn Helgaas <[email protected]>
[ Upstream commit 51fbf14f2528a8c6401290e37f1c893a2412f1d3 ]
The only use of KEXEC_BACKUP_SRC_END is as an argument to walk_system_ram_res():
int crash_load_segments(struct kimage *image)
{
...
walk_system_ram_res(KEXEC_BACKUP_SRC_START, KEXEC_BACKUP_SRC_END,
image, determine_backup_region);walk_system_ram_res() expects "start, end" arguments that are inclusive, i.e., the range to be walked includes both the start and end addresses.
KEXEC_BACKUP_SRC_END was previously defined as (640 * 1024UL), which is the first address *past* the desired 0-640KB range.
Define KEXEC_BACKUP_SRC_END as (640 * 1024UL - 1) so the KEXEC_BACKUP_SRC region is [0-0x9ffff], not [0-0xa0000].
--- arch/x86/include/asm/kexec.h | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
arch/x86/include/asm/kexec.h +1 -1
@@ -67,7 +67,7 @@ struct kimage;/* Memory to backup during crash kdump */ #define KEXEC_BACKUP_SRC_START (0UL) -#define KEXEC_BACKUP_SRC_END (640 * 1024UL)/* 640K */ +#define KEXEC_BACKUP_SRC_END (640 * 1024UL - 1)/* 640K */ /* * CPU does not save ss and sp on stack if execution is already
Signature · 7 lines
2.20.1 _______________________________________________ kexec mailing list [email protected] http://lists.infradead.org/mailman/listinfo/kexec
Sasha Levin
maintainerPATCH 177/209 bpf: btf: Fix a missing check bug
In reply to Sasha LevinFrom: Wenwen Wang <[email protected]>
[ Upstream commit 8af03d1ae2e154a8be3631e8694b87007e1bdbc2 ]
In btf_parse_hdr(), the length of the btf data header is firstly copied from the user space to 'hdr_len' and checked to see whether it is larger than 'btf_data_size'. If yes, an error code EINVAL is returned. Otherwise, the whole header is copied again from the user space to 'btf->hdr'. However, after the second copy, there is no check between 'btf->hdr->hdr_len' and 'hdr_len' to confirm that the two copies get the same value. Given that the btf data is in the user space, a malicious user can race to change the data between the two copies. By doing so, the user can provide malicious data to the kernel and cause undefined behavior.
This patch adds a necessary check after the second copy, to make sure 'btf->hdr->hdr_len' has the same value as 'hdr_len'. Otherwise, an error code EINVAL will be returned.
--- kernel/bpf/btf.c | 3 +++ 1 file changed, 3 insertions(+)
kernel/bpf/btf.c +3 -0
@@ -2114,6 +2114,9 @@ static int btf_parse_hdr(struct btf_verifier_env *env, void __user *btf_data, hdr = &btf->hdr; +if (hdr->hdr_len != hdr_len) +return -EINVAL ; +btf_verifier_log_hdr (env, btf_data_size);if (hdr->magic !=BTF_MAGIC ) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 181/209 pinctrl: gemini: Mask and set properly
In reply to Sasha LevinFrom: Linus Walleij <[email protected]>
[ Upstream commit d17f477c5bc6b4a5dd9f51ae263870da132a8e89 ]
The code was written under the assumption that the regmap_update_bits() would mask the bits in the mask and set the bits in the value.
It missed the points that it will not set bits in the value unless these are also masked in the mask. Set value bits that are not in the mask will simply be ignored.
--- drivers/pinctrl/pinctrl-gemini.c | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)
drivers/pinctrl/pinctrl-gemini.c +2 -1
@@ -2184,7 +2184,8 @@ static int gemini_pmx_set_mux(struct pinctrl_dev *pctldev, func->name, grp->name);regmap_read (pmx->map,GLOBAL_MISC_CTRL , &before); -regmap_update_bits (pmx->map,GLOBAL_MISC_CTRL , grp->mask, +regmap_update_bits (pmx->map,GLOBAL_MISC_CTRL , + grp->mask | grp->value, grp->value);regmap_read (pmx->map,GLOBAL_MISC_CTRL , &after);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 183/209 ARM: 8802/1: Call syscall_trace_exit even when system call skipped
In reply to Sasha LevinFrom: Timothy E Baldwin <[email protected]>
[ Upstream commit f18aef742c8fbd68e280dff0a63ba0ca6ee8ad85 ]
On at least x86 and ARM64, and as documented in the ptrace man page a skipped system call will still cause a syscall exit ptrace stop.
Previous to this commit 32-bit ARM did not, resulting in strace being confused when seccomp skips system calls.
This change also impacts programs that use ptrace to skip system calls.
--- arch/arm/kernel/entry-common.S | 9 ++++----- 1 file changed, 4 insertions(+), 5 deletions(-)
arch/arm/kernel/entry-common.S +4 -5
@@ -296,16 +296,15 @@ __sys_trace: cmp scno, #-1 @ skip the syscall? bne 2b add sp, sp, #S_OFF @ restore stack - b ret_slow_syscall -__sys_trace_return: - str r0, [sp, #S_R0 + S_OFF]! @ save returned r0 +__sys_trace_return_nosave: + enable_irq_notrace mov r0, sp bl syscall_trace_exit b ret_slow_syscall -__sys_trace_return_nosave: - enable_irq_notrace +__sys_trace_return: + str r0, [sp, #S_R0 + S_OFF]! @ save returned r0 mov r0, sp bl syscall_trace_exit b ret_slow_syscall
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 184/209 x86/mm: Do not warn about PCI BIOS W+X mappings
In reply to Sasha LevinFrom: Thomas Gleixner <[email protected]>
[ Upstream commit c200dac78fec66d87ef262cac38cfe4feabdf737 ]
PCI BIOS requires the BIOS area 0x0A0000-0x0FFFFFF to be mapped W+X for various legacy reasons. When CONFIG_DEBUG_WX is enabled, this triggers the WX warning, but this is misleading because the mapping is required and is not a result of an accidental oversight.
Prevent the full warning when PCI BIOS is enabled and the detected WX mapping is in the BIOS area. Just emit a pr_warn() which denotes the fact. This is partially duplicating the info which the PCI BIOS code emits when it maps the area as executable, but that info is not in the context of the WX checking output.
Remove the extra %p printout in the WARN_ONCE() while at it. %pS is enough.
--- arch/x86/mm/dump_pagetables.c | 35 +++++++++++++++++++++++++++-------- 1 file changed, 27 insertions(+), 8 deletions(-)
arch/x86/mm/dump_pagetables.c +27 -8
@@ -19,7 +19,9 @@#include <linux/sched.h> #include <linux/seq_file.h> #include <linux/highmem.h> +#include <linux/pci.h> +#include <asm/e820/types.h> #include <asm/pgtable.h> /*
@@ -238,6 +240,29 @@ static unsigned long normalize_addr(unsigned long u)return (signed long )(u << shift) >> shift; } +static void note_wx (struct pg_state *st) +{ +unsigned long npages; + + npages = (st->current_address - st->start_address) /PAGE_SIZE ; + +#ifdef CONFIG_PCI_BIOS +/* +* If PCI BIOS is enabled, the PCI BIOS area is forced to WX. +* Inform about it, but avoid the warning. +*/ +if (pcibios_enabled && st->start_address >=PAGE_OFFSET +BIOS_BEGIN && + st->current_address <=PAGE_OFFSET +BIOS_END ) { +pr_warn_once ("x86/mm: PCI BIOS W+X mapping %lu pages\n" , npages); +return ; + } +#endif +/* Account the WX pages */ + st->wx_pages += npages; +WARN_ONCE (1 ,"x86/mm: Found insecure W+X mapping at address %pS\n" , + (void *)st->start_address); +} +/* * This function gets called on a break in a continuous series * of PTE entries; the next one is different so we need to
@@ -273,14 +298,8 @@ static void note_page(struct seq_file *m, struct pg_state *st,unsigned long delta;int width =sizeof (unsigned long ) *2 ; -if (st->check_wx && (eff & _PAGE_RW) && !(eff & _PAGE_NX)) { -WARN_ONCE (1 , -"x86/mm: Found insecure W+X mapping at address %p/%pS\n" , - (void *)st->start_address, - (void *)st->start_address); - st->wx_pages += (st->current_address - - st->start_address) /PAGE_SIZE ; - } +if (st->check_wx && (eff & _PAGE_RW) && !(eff & _PAGE_NX)) +note_wx (st);/* * Now print the actual finished series
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 187/209 scsi: arcmsr: clean up clang warning on extraneous parentheses
In reply to Sasha LevinFrom: Colin Ian King <[email protected]>
[ Upstream commit ca2ade24157693b4e533ccec69df00ef719d4aad ]
There are extraneous parantheses that are causing clang to produce a warning so remove these.
Clean up 3 clang warnings:
equality comparison with extraneous parentheses [-Wparentheses-equality]
--- drivers/scsi/arcmsr/arcmsr_hba.c | 6 +++--- 1 file changed, 3 insertions(+), 3 deletions(-)
drivers/scsi/arcmsr/arcmsr_hba.c +3 -3
@@ -4135,9 +4135,9 @@ static void arcmsr_hardware_reset(struct AdapterControlBlock *acb)pci_read_config_byte (acb->pdev, i, &value[i]); }/* hardware reset signal */ -if ((acb->dev_id ==0x1680 )) { +if (acb->dev_id ==0x1680 ) {writel (ARCMSR_ARC1680_BUS_RESET , &pmuA->reserved1[0 ]); - }else if ((acb->dev_id ==0x1880 )) { + }else if (acb->dev_id ==0x1880 ) { do { count++; writel(0xF, &pmuC->write_sequence);
@@ -4161,7 +4161,7 @@ static void arcmsr_hardware_reset(struct AdapterControlBlock *acb) }while (((readl (&pmuE->host_diagnostic_3xxx) & ARCMSR_ARC1884_DiagWrite_ENABLE) ==0 ) && (count <5 ));writel (ARCMSR_ARC188X_RESET_ADAPTER , &pmuE->host_diagnostic_3xxx); - }else if ((acb->dev_id ==0x1214 )) { + }else if (acb->dev_id ==0x1214 ) {writel (0x20 , pmuD->reset_request); }else {pci_write_config_byte (acb->pdev,0x84 ,0x20 );
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 190/209 hwmon: (pwm-fan) Silence error on probe deferral
In reply to Sasha LevinFrom: Thierry Reding <[email protected]>
[ Upstream commit 9f67f7583e77fe5dc57aab3a6159c2642544eaad ]
Probe deferrals aren't actual errors, so silence the error message in case the PWM cannot yet be acquired.
--- drivers/hwmon/pwm-fan.c | 8 ++++++-- 1 file changed, 6 insertions(+), 2 deletions(-)
drivers/hwmon/pwm-fan.c +6 -2
@@ -221,8 +221,12 @@ static int pwm_fan_probe(struct platform_device *pdev) ctx->pwm =devm_of_pwm_get (&pdev->dev, pdev->dev.of_node,NULL );if (IS_ERR (ctx->pwm)) { -dev_err (&pdev->dev,"Could not get PWM\n" ); -return PTR_ERR (ctx->pwm); + ret =PTR_ERR (ctx->pwm); + +if (ret != -EPROBE_DEFER ) +dev_err (&pdev->dev,"Could not get PWM: %d\n" , ret); + +return ret; }platform_set_drvdata (pdev, ctx);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 192/209 hwmon: (npcm-750-pwm-fan) Change initial pwm target to 255
In reply to Sasha LevinFrom: Kun Yi <[email protected]>
[ Upstream commit f21c8e753b1dcb8f9e5b096db1f7f4e6fdfa7258 ]
Change initial PWM target to 255 to prevent overheating, for example when BMC hangs in userspace or when userspace fan control application is not implemented yet.
--- drivers/hwmon/npcm750-pwm-fan.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/hwmon/npcm750-pwm-fan.c +1 -1
@@ -52,7 +52,7 @@/* Define the Counter Register, value = 100 for match 100% */ #define NPCM7XX_PWM_COUNTER_DEFAULT_NUM 255 -#define NPCM7XX_PWM_CMR_DEFAULT_NUM 127 +#define NPCM7XX_PWM_CMR_DEFAULT_NUM 255#define NPCM7XX_PWM_CMR_MAX 255/* default all PWM channels PRESCALE2 = 1 */
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 189/209 hwmon: (nct6775) Fix names of DIMM temperature sources
In reply to Sasha LevinFrom: Guenter Roeck <[email protected]>
[ Upstream commit 3be8c9d103534fadc72b3e174613f37aa19fa423 ]
For NCT6795D and NCT6796D, the DIMM temperature sources are named "Agent[01] Dimm [01]" per datasheet. Match names in datasheets to avoid confusion.
--- drivers/hwmon/nct6775.c | 16 ++++++++-------- 1 file changed, 8 insertions(+), 8 deletions(-)
drivers/hwmon/nct6775.c +8 -8
@@ -704,10 +704,10 @@ static const char *const nct6795_temp_label[] = {"PCH_CHIP_TEMP" ,"PCH_CPU_TEMP" ,"PCH_MCH_TEMP" , -"PCH_DIM0_TEMP" , -"PCH_DIM1_TEMP" , -"PCH_DIM2_TEMP" , -"PCH_DIM3_TEMP" , +"Agent0 Dimm0" , +"Agent0 Dimm1" , +"Agent1 Dimm0" , +"Agent1 Dimm1" ,"BYTE_TEMP0" ,"BYTE_TEMP1" , "PECI Agent 0 Calibration",
@@ -742,10 +742,10 @@ static const char *const nct6796_temp_label[] = {"PCH_CHIP_TEMP" ,"PCH_CPU_TEMP" ,"PCH_MCH_TEMP" , -"PCH_DIM0_TEMP" , -"PCH_DIM1_TEMP" , -"PCH_DIM2_TEMP" , -"PCH_DIM3_TEMP" , +"Agent0 Dimm0" , +"Agent0 Dimm1" , +"Agent1 Dimm0" , +"Agent1 Dimm1" ,"BYTE_TEMP0" ,"BYTE_TEMP1" , "PECI Agent 0 Calibration",
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 197/209 mac80211: minstrel: fix using short preamble CCK rates on HT clients
In reply to Sasha LevinFrom: Felix Fietkau <[email protected]>
[ Upstream commit 37439f2d6e43ae79e22be9be159f0af157468f82 ]
mi->supported[MINSTREL_CCK_GROUP] needs to be updated
short preamble rates need to be marked as supported regardless of whether it's currently enabled. Its state can change at any time without a rate_update call.
--- net/mac80211/rc80211_minstrel_ht.c | 4 +--- 1 file changed, 1 insertion(+), 3 deletions(-)
net/mac80211/rc80211_minstrel_ht.c +1 -3
@@ -1132,7 +1132,6 @@ minstrel_ht_update_caps(void *priv, struct ieee80211_supported_band *sband,struct ieee80211_mcs_info *mcs = &sta->ht_cap.mcs;u16 sta_cap = sta->ht_cap.cap;struct ieee80211_sta_vht_cap *vht_cap = &sta->vht_cap; - struct sta_info *sinfo = container_of(sta, struct sta_info, sta);int use_vht;int n_supported =0 ;int ack_dur;
@@ -1258,8 +1257,7 @@ minstrel_ht_update_caps(void *priv, struct ieee80211_supported_band *sband,if (!n_supported) goto use_legacy; -if (test_sta_flag (sinfo,WLAN_STA_SHORT_PREAMBLE )) - mi->cck_supported_short |= mi->cck_supported_short <<4 ; + mi->supported[MINSTREL_CCK_GROUP ] |= mi->cck_supported_short <<4 ;/* create an initial rate table with the lowest supported rates */ minstrel_ht_update_stats (mp, mi);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 199/209 mac80211: minstrel: fix sampling/reporting of CCK rates in HT mode
In reply to Sasha LevinFrom: Felix Fietkau <[email protected]>
[ Upstream commit 972b66b86f85f4e8201db454f4c3e9d990cf9836 ]
Long/short preamble selection cannot be sampled separately, since it depends on the BSS state. Because of that, sampling attempts to currently not used preamble modes are not counted in the statistics, which leads to CCK rates being sampled too often.
Fix statistics accounting for long/short preamble by increasing the index where necessary.
Fix excessive CCK rate sampling by dropping unsupported sample attempts.
This improves throughput on 2.4 GHz channels
--- net/mac80211/rc80211_minstrel_ht.c | 14 ++++++++++---- 1 file changed, 10 insertions(+), 4 deletions(-)
net/mac80211/rc80211_minstrel_ht.c +10 -4
@@ -282,7 +282,8 @@ minstrel_ht_get_stats(struct minstrel_priv *mp, struct minstrel_ht_sta *mi,break ;/* short preamble */ -if (!(mi->supported[group] &BIT (idx))) +if ((mi->supported[group] &BIT (idx +4 )) && + (rate->flags &IEEE80211_TX_RC_USE_SHORT_PREAMBLE )) idx +=4 ; }return &mi->groups[group].rates[idx];
@@ -1077,18 +1078,23 @@ minstrel_ht_get_rate(void *priv, struct ieee80211_sta *sta, void *priv_sta,return ; sample_group = &minstrel_mcs_groups[sample_idx /MCS_GROUP_RATES ]; + sample_idx %=MCS_GROUP_RATES ; + +if (sample_group == &minstrel_mcs_groups[MINSTREL_CCK_GROUP ] && + (sample_idx >=4 ) != txrc->short_preamble) +return ; + info->flags |=IEEE80211_TX_CTL_RATE_CTRL_PROBE ; rate->count =1 ; -if (sample_idx /MCS_GROUP_RATES ==MINSTREL_CCK_GROUP ) { +if (sample_group == &minstrel_mcs_groups[MINSTREL_CCK_GROUP ]) {int idx = sample_idx %ARRAY_SIZE (mp->cck_rates); rate->idx = mp->cck_rates[idx]; }else if (sample_group->flags &IEEE80211_TX_RC_VHT_MCS ) {ieee80211_rate_set_vht (rate, sample_idx %MCS_GROUP_RATES , sample_group->streams); }else { - rate->idx = sample_idx %MCS_GROUP_RATES + - (sample_group->streams -1 ) *8 ; + rate->idx = sample_idx + (sample_group->streams -1 ) *8 ; } rate->flags = sample_group->flags;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 191/209 hwmon: (ina3221) Fix INA3221_CONFIG_MODE macros
In reply to Sasha LevinFrom: Nicolin Chen <[email protected]>
[ Upstream commit 791ebc9d34e9d212fc03742c31654b017d385926 ]
The three INA3221_CONFIG_MODE macros are not correctly defined here. The MODE3-1 bits are located at BIT 2-0 according to the datasheet.
So this patch just fixes them by shifting all of them with a correct offset. However, this isn't a crital bug fix as the driver does not use any of them at this point.
--- drivers/hwmon/ina3221.c | 6 +++--- 1 file changed, 3 insertions(+), 3 deletions(-)
drivers/hwmon/ina3221.c +3 -3
@@ -38,9 +38,9 @@#define INA3221_WARN3 0x0c#define INA3221_MASK_ENABLE 0x0f -#define INA3221_CONFIG_MODE_SHUNT BIT(1) -#define INA3221_CONFIG_MODE_BUS BIT(2) -#define INA3221_CONFIG_MODE_CONTINUOUS BIT(3) +#define INA3221_CONFIG_MODE_SHUNT BIT(0) +#define INA3221_CONFIG_MODE_BUS BIT(1) +#define INA3221_CONFIG_MODE_CONTINUOUS BIT(2)#define INA3221_RSHUNT_DEFAULT 10000
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 201/209 mlxsw: spectrum_switchdev: Check notification relevance based on upper device
In reply to Sasha LevinFrom: Ido Schimmel <[email protected]>
[ Upstream commit 5050f6ae253ad1307af3486c26fc4f94287078b7 ]
VxLAN FDB updates are sent with the VxLAN device which is not our upper and will therefore be ignored by current code.
Solve this by checking whether the upper device (bridge) is our upper.
--- drivers/net/ethernet/mellanox/mlxsw/spectrum_switchdev.c | 9 ++++++++- 1 file changed, 8 insertions(+), 1 deletion(-)
drivers/net/ethernet/mellanox/mlxsw/spectrum_switchdev.c +8 -1
@@ -2324,8 +2324,15 @@ static int mlxsw_sp_switchdev_event(struct notifier_block *unused,struct net_device *dev =switchdev_notifier_info_to_dev (ptr);struct mlxsw_sp_switchdev_event_work *switchdev_work;struct switchdev_notifier_fdb_info *fdb_info = ptr; +struct net_device *br_dev; -if (!mlxsw_sp_port_dev_lower_find_rcu (dev)) +/* Tunnel devices are not our uppers, so check their master instead */ + br_dev =netdev_master_upper_dev_get_rcu (dev); +if (!br_dev) +return NOTIFY_DONE ; +if (!netif_is_bridge_master (br_dev)) +return NOTIFY_DONE ; +if (!mlxsw_sp_port_dev_lower_find_rcu (br_dev))return NOTIFY_DONE ; switchdev_work =kzalloc (sizeof (*switchdev_work),GFP_ATOMIC );
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 203/209 tcp: start receiver buffer autotuning sooner
In reply to Sasha LevinFrom: Yuchung Cheng <[email protected]>
[ Upstream commit 041a14d2671573611ffd6412bc16e2f64469f7fb ]
Previously receiver buffer auto-tuning starts after receiving one advertised window amount of data. After the initial receiver buffer was raised by patch a337531b942b ("tcp: up initial rmem to 128KB and SYN rwin to around 64KB"), the reciver buffer may take too long to start raising. To address this issue, this patch lowers the initial bytes expected to receive roughly the expected sender's initial window.
--- net/ipv4/tcp_input.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
net/ipv4/tcp_input.c +1 -1
@@ -438,7 +438,7 @@ void tcp_init_buffer_space(struct sock *sk)if (!(sk->sk_userlocks &SOCK_SNDBUF_LOCK ))tcp_sndbuf_expand (sk); - tp->rcvq_space.space = tp->rcv_wnd; + tp->rcvq_space.space =min_t (u32, tp->rcv_wnd,TCP_INIT_CWND * tp->advmss);tcp_mstamp_refresh (tp); tp->rcvq_space.time = tp->tcp_mstamp; tp->rcvq_space.seq = tp->copied_seq;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 195/209 netfilter: nft_compat: do not dump private area
In reply to Sasha LevinFrom: Pablo Neira Ayuso <[email protected]>
[ Upstream commit d701d8117200399d85e63a737d2e4e897932f3b6 ]
Zero pad private area, otherwise we expose private kernel pointer to userspace. This patch also zeroes the tail area after the ->matchsize and ->targetsize that results from XT_ALIGN().
--- net/netfilter/nft_compat.c | 24 ++++++++++++++++++++++-- 1 file changed, 22 insertions(+), 2 deletions(-)
net/netfilter/nft_compat.c +22 -2
@@ -269,6 +269,24 @@ nft_target_destroy(const struct nft_ctx *ctx, const struct nft_expr *expr)kfree (expr->ops); } +static int nft_extension_dump_info (struct sk_buff *skb,int attr, +const void *info, +unsigned int size,unsigned int user_size) +{ +unsigned int info_size, aligned_size =XT_ALIGN (size); +struct nlattr *nla; + + nla =nla_reserve (skb, attr, aligned_size); +if (!nla) +return -1 ; + + info_size = user_size ? : size; +memcpy (nla_data (nla), info, info_size); +memset (nla_data (nla) + info_size,0 , aligned_size - info_size); + +return 0 ; +} +static int nft_target_dump (struct sk_buff *skb,const struct nft_expr *expr) {const struct xt_target *target = expr->ops->data;
@@ -276,7 +294,8 @@ static int nft_target_dump(struct sk_buff *skb, const struct nft_expr *expr)if (nla_put_string (skb,NFTA_TARGET_NAME , target->name) ||nla_put_be32 (skb,NFTA_TARGET_REV ,htonl (target->revision)) || -nla_put (skb,NFTA_TARGET_INFO ,XT_ALIGN (target->targetsize), info)) +nft_extension_dump_info (skb,NFTA_TARGET_INFO , info, + target->targetsize, target->usersize)) goto nla_put_failure;return 0 ;
@@ -504,7 +523,8 @@ static int __nft_match_dump(struct sk_buff *skb, const struct nft_expr *expr,if (nla_put_string (skb,NFTA_MATCH_NAME , match->name) ||nla_put_be32 (skb,NFTA_MATCH_REV ,htonl (match->revision)) || -nla_put (skb,NFTA_MATCH_INFO ,XT_ALIGN (match->matchsize), info)) +nft_extension_dump_info (skb,NFTA_MATCH_INFO , info, + match->matchsize, match->usersize)) goto nla_put_failure;return 0 ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 196/209 misc: cxl: Fix possible null pointer dereference
In reply to Sasha LevinFrom: zhong jiang <[email protected]>
[ Upstream commit 3dac3583bf1a61db6aaf31dfd752c677a4400afd ]
It is not safe to dereference an object before a null test. It is not needed and just remove them. Ftrace can be used instead.
--- drivers/misc/cxl/guest.c | 2 -- 1 file changed, 2 deletions(-)
drivers/misc/cxl/guest.c +0 -2
@@ -1020,8 +1020,6 @@ int cxl_guest_init_afu(struct cxl *adapter, int slice, struct device_node *afu_nvoid cxl_guest_remove_afu (struct cxl_afu *afu) { -pr_devel ("in %s - AFU(%d)\n" , __func__, afu->slice); -if (!afu)return ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 206/209 tools: PCI: Fix broken pcitest compilation
In reply to Sasha LevinFrom: Alan Mikhak <[email protected]>
[ Upstream commit 8a5e0af240e07dd3d4897eb8ff52aab757da7fab ]
pcitest is currently broken due to the following compiler error and related warning. Fix by changing the run_test() function signature to return an integer result.
pcitest.c: In function run_test:
pcitest.c:143:9: warning: return with a value, in function returning void
return (ret < 0) ? ret : 1 - ret; /* return 0 if test succeeded */
pcitest.c: In function main:
pcitest.c:232:9: error: void value not ignored as it ought to be
return run_test(test);
--- tools/pci/pcitest.c | 6 +++--- 1 file changed, 3 insertions(+), 3 deletions(-)
tools/pci/pcitest.c +3 -3
@@ -47,15 +47,15 @@ struct pci_test {unsigned long size; }; -static void run_test (struct pci_test *test) +static int run_test (struct pci_test *test) { -long ret; +int ret = -EINVAL ;int fd; fd =open (test->device,O_RDWR );if (fd <0 ) {perror ("can't open PCI Endpoint Test device" ); -return ; +return -ENODEV ; }if (test->barnum >=0 && test->barnum <=5 ) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 57/209 powerpc/xive: Move a dereference below a NULL test
In reply to Sasha LevinFrom: zhong jiang <[email protected]>
[ Upstream commit cd5ff94577e004e0a4457e70d0ef3a030f4010b8 ]
Move the dereference of xc below the NULL test.
--- arch/powerpc/sysdev/xive/common.c | 7 ++++--- 1 file changed, 4 insertions(+), 3 deletions(-)
arch/powerpc/sysdev/xive/common.c +4 -3
@@ -1009,12 +1009,13 @@ static void xive_ipi_eoi(struct irq_data *d) {struct xive_cpu *xc =__this_cpu_read (xive_cpu); -DBG_VERBOSE ("IPI eoi: irq=%d [0x%lx] (HW IRQ 0x%x) pending=%02x\n" , - d->irq,irqd_to_hwirq (d), xc->hw_ipi, xc->pending_prio); -/* Handle possible race with unplug and drop stale IPIs */ if (!xc)return ; + +DBG_VERBOSE ("IPI eoi: irq=%d [0x%lx] (HW IRQ 0x%x) pending=%02x\n" , + d->irq,irqd_to_hwirq (d), xc->hw_ipi, xc->pending_prio); +xive_do_source_eoi (xc->hw_ipi, &xc->ipi_data);xive_do_queue_eoi (xc); }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 204/209 ACPI / LPSS: Use acpi_lpss_* instead of acpi_subsys_* functions for hibernate
In reply to Sasha LevinFrom: Hans de Goede <[email protected]>
[ Upstream commit c8afd03486c26accdda4846e5561aa3f8e862a9d ]
Commit 48402cee6889 ("ACPI / LPSS: Resume BYT/CHT I2C controllers from resume_noirq") makes acpi_lpss_{suspend_late,resume_early}() bail early on BYT/CHT as resume_from_noirq is set.
This means that on resume from hibernate dw_i2c_plat_resume() doesn't get called by the restore_early callback, acpi_lpss_resume_early(). Instead it should be called by the restore_noirq callback matching how things are done when resume_from_noirq is set and we are doing a regular resume.
Change the restore_noirq callback to acpi_lpss_resume_noirq so that dw_i2c_plat_resume() gets properly called when resume_from_noirq is set and we are resuming from hibernate.
Likewise also change the poweroff_noirq callback so that dw_i2c_plat_suspend gets called properly.
Bugzilla: https://bugzilla.kernel.org/show_bug.cgi?id=202139
--- drivers/acpi/acpi_lpss.c | 4 ++-- 1 file changed, 2 insertions(+), 2 deletions(-)
drivers/acpi/acpi_lpss.c +2 -2
@@ -1121,8 +1121,8 @@ static struct dev_pm_domain acpi_lpss_pm_domain = { .thaw_noirq = acpi_subsys_thaw_noirq, .poweroff = acpi_subsys_suspend, .poweroff_late = acpi_lpss_suspend_late, - .poweroff_noirq = acpi_subsys_suspend_noirq, - .restore_noirq = acpi_subsys_resume_noirq, + .poweroff_noirq = acpi_lpss_suspend_noirq, + .restore_noirq = acpi_lpss_resume_noirq, .restore_early = acpi_lpss_resume_early, #endif .runtime_suspend = acpi_lpss_runtime_suspend,
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 209/209 x86/resctrl: Fix rdt_find_domain() return value and checks
In reply to Sasha LevinFrom: Reinette Chatre <[email protected]>
[ Upstream commit 52eb74339a6233c69f4e3794b69ea7c98eeeae1b ]
rdt_find_domain() returns an ERR_PTR() that is generated from a provided domain id when the value is negative.
Care needs to be taken when creating an ERR_PTR() from this value because a subsequent check using IS_ERR() expects the error to be within the MAX_ERRNO range. Using an invalid domain id as an ERR_PTR() does work at this time since this is currently always -1. Using this undocumented assumption is fragile since future users of rdt_find_domain() may not be aware of thus assumption.
Two related issues are addressed:
- Ensure that rdt_find_domain() always returns a valid error value by forcing the error to be -ENODEV when a negative domain id is provided.
- In a few instances the return value of rdt_find_domain() is just checked for NULL - fix these to include a check of ERR_PTR.
--- arch/x86/kernel/cpu/intel_rdt.c | 2 +- arch/x86/kernel/cpu/intel_rdt_ctrlmondata.c | 2 +- arch/x86/kernel/cpu/intel_rdt_rdtgroup.c | 2 +- 3 files changed, 3 insertions(+), 3 deletions(-)
arch/x86/kernel/cpu/intel_rdt.c +1 -1
@@ -421,7 +421,7 @@ struct rdt_domain *rdt_find_domain(struct rdt_resource *r, int id,struct list_head *l;if (id <0 ) -return ERR_PTR (id); +return ERR_PTR (-ENODEV );list_for_each (l, &r->domains) { d = list_entry(l, struct rdt_domain, list);
arch/x86/kernel/cpu/intel_rdt_ctrlmondata.c +1 -1
@@ -459,7 +459,7 @@ int rdtgroup_mondata_show(struct seq_file *m, void *arg) r = &rdt_resources_all[resid]; d =rdt_find_domain (r, domid,NULL ); -if (!d) { +if (IS_ERR_OR_NULL (d)) { ret = -ENOENT ; goto out; }
arch/x86/kernel/cpu/intel_rdt_rdtgroup.c +1 -1
@@ -1023,7 +1023,7 @@ static int rdt_cdp_peer_get(struct rdt_resource *r, struct rdt_domain *d,* peer RDT CDP resource. Hence the WARN. */ _d_cdp =rdt_find_domain (_r_cdp, d->id,NULL ); -if (WARN_ON (!_d_cdp)) { +if (WARN_ON (IS_ERR_OR_NULL (_d_cdp))) { _r_cdp =NULL ; ret = -EINVAL ; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 207/209 powerpc/time: Fix clockevent_decrementer initalisation for PR KVM
In reply to Sasha LevinFrom: Michael Ellerman <[email protected]>
[ Upstream commit b4d16ab58c41ff0125822464bdff074cebd0fe47 ]
In the recent commit 8b78fdb045de ("powerpc/time: Use clockevents_register_device(), fixing an issue with large decrementer") we changed the way we initialise the decrementer clockevent(s).
We no longer initialise the mult & shift values of decrementer_clockevent itself.
This has the effect of breaking PR KVM, because it uses those values in kvmppc_emulate_dec(). The symptom is guest kernels spin forever mid-way through boot.
For now fix it by assigning back to decrementer_clockevent the mult and shift values.
--- arch/powerpc/kernel/time.c | 4 ++++ 1 file changed, 4 insertions(+)
arch/powerpc/kernel/time.c +4 -0
@@ -988,6 +988,10 @@ static void register_decrementer_clockevent(int cpu)printk_once (KERN_DEBUG "clockevent: %s mult[%x] shift[%d] cpu[%d]\n" , dec->name, dec->mult, dec->shift, cpu); + +/* Set values for KVM, see kvm_emulate_dec() */ + decrementer_clockevent.mult = dec->mult; + decrementer_clockevent.shift = dec->shift; }static void enable_large_decrementer (void )
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 193/209 selftests: forwarding: Have lldpad_app_wait_set() wait for unknown, too
In reply to Sasha LevinFrom: Petr Machata <[email protected]>
[ Upstream commit 372809055f6c830ff978564e09f58bcb9e9b937c ]
Immediately after mlxsw module is probed and lldpad started, added APP entries are briefly in "unknown" state before becoming "pending". That's the state that lldpad_app_wait_set() typically sees, and since there are no pending entries at that time, it bails out. However the entries have not been pushed to the kernel yet at that point, and thus the test case fails.
Fix by waiting for both unknown and pending entries to disappear before proceeding.
--- tools/testing/selftests/net/forwarding/lib.sh | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
tools/testing/selftests/net/forwarding/lib.sh +1 -1
@@ -251,7 +251,7 @@ lldpad_app_wait_set() { local dev=$1; shift - while lldptool -t -i $dev -V APP -c app | grep -q pending; do + while lldptool -t -i $dev -V APP -c app | grep -Eq "pending|unknown"; do echo "$dev: waiting for lldpad to push pending APP updates" sleep 5 done
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 205/209 PM / devfreq: Fix static checker warning in try_then_request_governor
In reply to Sasha LevinFrom: Enric Balletbo i Serra <[email protected]>
[ Upstream commit b53b0128052ffd687797d5f4deeb76327e7b5711 ]
The patch 23c7b54ca1cd: "PM / devfreq: Fix devfreq_add_device() when drivers are built as modules." leads to the following static checker warning:
drivers/devfreq/devfreq.c:1043 governor_store()
warn: 'governor' can also be NULL
The reason is that the try_then_request_governor() function returns both error pointers and NULL. It should just return error pointers, so fix this by returning a ERR_PTR to the error intead of returning NULL.
--- drivers/devfreq/devfreq.c | 4 ++-- 1 file changed, 2 insertions(+), 2 deletions(-)
drivers/devfreq/devfreq.c +2 -2
@@ -231,7 +231,7 @@ static struct devfreq_governor *find_devfreq_governor(const char *name)* if is not found. This can happen when both drivers (the governor driver * and the driver that call devfreq_add_device) are built as modules. * devfreq_list_lock should be held by the caller. Returns the matched -* governor's pointer. +* governor's pointer or an error pointer. */ static struct devfreq_governor *try_then_request_governor (const char *name) {
@@ -257,7 +257,7 @@ static struct devfreq_governor *try_then_request_governor(const char *name)/* Restore previous state before return */ mutex_lock (&devfreq_list_lock);if (err) -return NULL ; +return ERR_PTR (err); governor =find_devfreq_governor (name); }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 198/209 mac80211: minstrel: fix CCK rate group streams value
In reply to Sasha LevinFrom: Felix Fietkau <[email protected]>
[ Upstream commit 80df9be67c44cb636bbc92caeddad8caf334c53c ]
Fixes a harmless underflow issue when CCK rates are actively being used
--- net/mac80211/rc80211_minstrel_ht.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
net/mac80211/rc80211_minstrel_ht.c +1 -1
@@ -129,7 +129,7 @@#define CCK_GROUP \ [MINSTREL_CCK_GROUP] = { \ - .streams = 0, \ + .streams = 1, \ .flags = 0, \ .duration = { \ CCK_DURATION_LIST(false), \
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 194/209 net: sched: avoid writing on noop_qdisc
In reply to Sasha LevinFrom: Eric Dumazet <[email protected]>
[ Upstream commit f98ebd47fd0da1717267ce1583a105d8cc29a16a ]
While noop_qdisc.gso_skb and noop_qdisc.skb_bad_txq are not used in other places, it seems not correct to overwrite their fields in dev_init_scheduler_queue().
noop_qdisc is essentially a shared and read-only object, even if it is not marked as const because of some implementation detail.
--- net/sched/sch_generic.c | 14 ++++++++++++-- 1 file changed, 12 insertions(+), 2 deletions(-)
net/sched/sch_generic.c +12 -2
@@ -577,6 +577,18 @@ struct Qdisc noop_qdisc = { .dev_queue = &noop_netdev_queue, .running = SEQCNT_ZERO(noop_qdisc.running), .busylock = __SPIN_LOCK_UNLOCKED(noop_qdisc.busylock), + .gso_skb = { + .next = (struct sk_buff *)&noop_qdisc.gso_skb, + .prev = (struct sk_buff *)&noop_qdisc.gso_skb, + .qlen = 0, + .lock = __SPIN_LOCK_UNLOCKED(noop_qdisc.gso_skb.lock), + }, + .skb_bad_txq = { + .next = (struct sk_buff *)&noop_qdisc.skb_bad_txq, + .prev = (struct sk_buff *)&noop_qdisc.skb_bad_txq, + .qlen = 0, + .lock =__SPIN_LOCK_UNLOCKED (noop_qdisc.skb_bad_txq.lock), + }, };EXPORT_SYMBOL (noop_qdisc);
@@ -1253,8 +1265,6 @@ static void dev_init_scheduler_queue(struct net_device *dev,rcu_assign_pointer (dev_queue->qdisc, qdisc); dev_queue->qdisc_sleeping = qdisc; -__skb_queue_head_init (&qdisc->gso_skb); -__skb_queue_head_init (&qdisc->skb_bad_txq); }void dev_init_scheduler (struct net_device *dev)
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 188/209 hwmon: (k10temp) Support all Family 15h Model 6xh and Model 7xh processors
In reply to Sasha LevinFrom: Guenter Roeck <[email protected]>
[ Upstream commit 53dfa0088edd2e2793afa21488532b12eb2dae48 ]
BIOS developer guides refer to Family 15h Models 60h-6fh and Family 15h Models 70h-7fh. So far the driver only checked for Models 60h and 70h. However, there are now processors with other model numbers in the same families. Example is A10-9620P family 15h model 65h. Follow the developer guides and mask the lower 4 bit of the model number to determine the registers to use for reading temperatures and temperature limits.
--- drivers/hwmon/k10temp.c | 5 +++-- 1 file changed, 3 insertions(+), 2 deletions(-)
drivers/hwmon/k10temp.c +3 -2
@@ -325,8 +325,9 @@ static int k10temp_probe(struct pci_dev *pdev, data->pdev = pdev; -if (boot_cpu_data.x86 ==0x15 && (boot_cpu_data.x86_model ==0x60 || - boot_cpu_data.x86_model ==0x70 )) { +if (boot_cpu_data.x86 ==0x15 && + ((boot_cpu_data.x86_model &0xf0 ) ==0x60 || + (boot_cpu_data.x86_model &0xf0 ) ==0x70 )) { data->read_htcreg = read_htcreg_nb_f15; data->read_tempreg = read_tempreg_nb_f15; }else if (boot_cpu_data.x86 ==0x17 ) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 186/209 pinctrl: gemini: Fix up TVC clock group
In reply to Sasha LevinFrom: Linus Walleij <[email protected]>
[ Upstream commit a85c928f6a7856a09e47d9b37faa3407c7ac6a8e ]
The previous fix made the TVC clock get muxed in on the D-Link DIR-685 instead of giving nagging warnings of this not working. Not good. We didn't want that, as it breaks video.
Create a specific group for the TVC CLK, and break out a specific GPIO group for it on the SL3516 so we can use that line as GPIO if we don't need the TVC CLK.
--- drivers/pinctrl/pinctrl-gemini.c | 44 ++++++++++++++++++++++++++------ 1 file changed, 36 insertions(+), 8 deletions(-)
drivers/pinctrl/pinctrl-gemini.c +36 -8
@@ -591,13 +591,16 @@ static const unsigned int tvc_3512_pins[] = {319 ,/* TVC_DATA[1] */ 301 ,/* TVC_DATA[2] */ 283 ,/* TVC_DATA[3] */ -265 ,/* TVC_CLK */ 320 ,/* TVC_DATA[4] */ 302 ,/* TVC_DATA[5] */ 284 ,/* TVC_DATA[6] */ 266, /* TVC_DATA[7] */ }; +static const unsigned int tvc_clk_3512_pins[] = { +265 ,/* TVC_CLK */ +}; +/* NAND flash pins */ static const unsigned int nflash_3512_pins[] = { 199, 200, 201, 202, 216, 217, 218, 219, 220, 234, 235, 236, 237, 252,
@@ -629,7 +632,7 @@ static const unsigned int pflash_3512_pins_extended[] = {/* Serial flash pins CE0, CE1, DI, DO, CK */ static const unsigned int sflash_3512_pins[] = {230 ,231 ,232 ,233 ,211 }; -/* The GPIO0A (0) pin overlap with TVC and extended parallel flash */ +/* The GPIO0A (0) pin overlap with TVC CLK and extended parallel flash */ static const unsigned int gpio0a_3512_pins[] = {265 };/* The GPIO0B (1-4) pins overlap with TVC and ICE */
@@ -823,7 +826,13 @@ static const struct gemini_pin_group gemini_3512_pin_groups[] = { .num_pins = ARRAY_SIZE(tvc_3512_pins), /* Conflict with character LCD and ICE */ .mask = LCD_PADS_ENABLE, - .value = TVC_PADS_ENABLE | TVC_CLK_PAD_ENABLE, + .value = TVC_PADS_ENABLE, + }, + { + .name = "tvcclkgrp", + .pins = tvc_clk_3512_pins, + .num_pins = ARRAY_SIZE(tvc_clk_3512_pins), + .value = TVC_CLK_PAD_ENABLE, },/* * The construction is done such that it is possible to use a serial
@@ -860,8 +869,8 @@ static const struct gemini_pin_group gemini_3512_pin_groups[] = { .name = "gpio0agrp", .pins = gpio0a_3512_pins, .num_pins = ARRAY_SIZE(gpio0a_3512_pins), - /* Conflict with TVC */ - .mask = TVC_PADS_ENABLE, + /* Conflict with TVC CLK */ + .mask = TVC_CLK_PAD_ENABLE, }, { .name = "gpio0bgrp",
@@ -1531,13 +1540,16 @@ static const unsigned int tvc_3516_pins[] = {311 ,/* TVC_DATA[1] */ 394 ,/* TVC_DATA[2] */ 374 ,/* TVC_DATA[3] */ -333 ,/* TVC_CLK */ 354 ,/* TVC_DATA[4] */ 395 ,/* TVC_DATA[5] */ 312 ,/* TVC_DATA[6] */ 334, /* TVC_DATA[7] */ }; +static const unsigned int tvc_clk_3516_pins[] = { +333 ,/* TVC_CLK */ +}; +/* NAND flash pins */ static const unsigned int nflash_3516_pins[] = { 243, 260, 261, 224, 280, 262, 281, 264, 300, 263, 282, 301, 320, 283,
@@ -1570,7 +1582,7 @@ static const unsigned int pflash_3516_pins_extended[] = {static const unsigned int sflash_3516_pins[] = {296 ,338 ,295 ,359 ,339 };/* The GPIO0A (0-4) pins overlap with TVC and extended parallel flash */ -static const unsigned int gpio0a_3516_pins[] = {333 ,354 ,395 ,312 ,334 }; +static const unsigned int gpio0a_3516_pins[] = {354 ,395 ,312 ,334 };/* The GPIO0B (5-7) pins overlap with ICE */ static const unsigned int gpio0b_3516_pins[] = {375 ,396 ,376 };
@@ -1602,6 +1614,9 @@ static const unsigned int gpio0j_3516_pins[] = { 359, 339 };/* The GPIO0K (30,31) pins overlap with NAND flash */ static const unsigned int gpio0k_3516_pins[] = {275 ,298 }; +/* The GPIO0L (0) pins overlap with TVC_CLK */ +static const unsigned int gpio0l_3516_pins[] = {333 }; +/* The GPIO1A (0-4) pins that overlap with IDE and parallel flash */ static const unsigned int gpio1a_3516_pins[] = {221 ,200 ,222 ,201 ,220 };
@@ -1761,7 +1776,13 @@ static const struct gemini_pin_group gemini_3516_pin_groups[] = { .num_pins = ARRAY_SIZE(tvc_3516_pins), /* Conflict with character LCD */ .mask = LCD_PADS_ENABLE, - .value = TVC_PADS_ENABLE | TVC_CLK_PAD_ENABLE, + .value = TVC_PADS_ENABLE, + }, + { + .name = "tvcclkgrp", + .pins = tvc_clk_3516_pins, + .num_pins = ARRAY_SIZE(tvc_clk_3516_pins), + .value = TVC_CLK_PAD_ENABLE, },/* * The construction is done such that it is possible to use a serial
@@ -1872,6 +1893,13 @@ static const struct gemini_pin_group gemini_3516_pin_groups[] = {/* Conflict with parallel and NAND flash */ .value = PFLASH_PADS_DISABLE | NAND_PADS_DISABLE, }, + { + .name = "gpio0lgrp", + .pins = gpio0l_3516_pins, + .num_pins = ARRAY_SIZE(gpio0l_3516_pins), + /* Conflict with TVE CLK */ + .mask = TVC_CLK_PAD_ENABLE, + }, { .name = "gpio1agrp", .pins = gpio1a_3516_pins,
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 185/209 orangefs: rate limit the client not running info message
In reply to Sasha LevinFrom: Colin Ian King <[email protected]>
[ Upstream commit 2978d873471005577e7b68a528b4f256a529b030 ]
Currently accessing various /sys/fs/orangefs files will spam the kernel log with the following info message when the client is not running:
[ 491.489284] sysfs_service_op_show: Client not running :-5:
Rate limit this info message to make it less spammy.
--- fs/orangefs/orangefs-sysfs.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
fs/orangefs/orangefs-sysfs.c +1 -1
@@ -323,7 +323,7 @@ static ssize_t sysfs_service_op_show(struct kobject *kobj,/* Can't do a service_operation if the client is not running... */ rc =is_daemon_in_service ();if (rc) { -pr_info ("%s: Client not running :%d:\n" , +pr_info_ratelimited ("%s: Client not running :%d:\n" , __func__,is_daemon_in_service ()); goto out;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 179/209 gpio: syscon: Fix possible NULL ptr usage
In reply to Sasha LevinFrom: Marek Vasut <[email protected]>
[ Upstream commit 70728c29465bc4bfa7a8c14304771eab77e923c7 ]
The priv->data->set can be NULL while flags contains GPIO_SYSCON_FEAT_OUT and chip->set is valid pointer. This happens in case the controller uses the default GPIO setter. Always use chip->set to access the setter to avoid possible NULL pointer dereferencing.
--- drivers/gpio/gpio-syscon.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/gpio/gpio-syscon.c +1 -1
@@ -122,7 +122,7 @@ static int syscon_gpio_dir_out(struct gpio_chip *chip, unsigned offset, int val) BIT(offs % SYSCON_REG_BITS)); } - priv->data->set (chip, offset, val); + chip->set (chip, offset, val);return 0 ; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 178/209 net: fix generic XDP to handle if eth header was mangled
In reply to Sasha LevinFrom: Jesper Dangaard Brouer <[email protected]>
[ Upstream commit 2972495699320229b55b8e5065a310be5c81485b ]
XDP can modify (and resize) the Ethernet header in the packet.
There is a bug in generic-XDP, because skb->protocol and skb->pkt_type are setup before reaching (netif_receive_)generic_xdp.
This bug was hit when XDP were popping VLAN headers (changing eth->h_proto), as skb->protocol still contains VLAN-indication (ETH_P_8021Q) causing invocation of skb_vlan_untag(skb), which corrupt the packet (basically popping the VLAN again).
This patch catch if XDP changed eth header in such a way, that SKB fields needs to be updated.
V2: on request from Song Liu, use ETH_HLEN instead of mac_len,
in __skb_push() as eth_type_trans() use ETH_HLEN in paired skb_pull_inline().
--- net/core/dev.c | 14 ++++++++++++++ 1 file changed, 14 insertions(+)
net/core/dev.c +14 -0
@@ -4296,6 +4296,9 @@ static u32 netif_receive_generic_xdp(struct sk_buff *skb,struct netdev_rx_queue *rxqueue;void *orig_data, *orig_data_end;u32 metalen, act =XDP_DROP ; +__be16 orig_eth_type; +struct ethhdr *eth; +bool orig_bcast;int hlen, off;u32 mac_len;
@@ -4336,6 +4339,9 @@ static u32 netif_receive_generic_xdp(struct sk_buff *skb, xdp->data_hard_start = skb->data -skb_headroom (skb); orig_data_end = xdp->data_end; orig_data = xdp->data; + eth = (struct ethhdr *)xdp->data; + orig_bcast =is_multicast_ether_addr_64bits (eth->h_dest); + orig_eth_type = eth->h_proto; rxqueue =netif_get_rxqueue (skb); xdp->rxq = &rxqueue->xdp_rxq;
@@ -4359,6 +4365,14 @@ static u32 netif_receive_generic_xdp(struct sk_buff *skb, } +/* check if XDP changed eth hdr such SKB needs update */ + eth = (struct ethhdr *)xdp->data; +if ((orig_eth_type != eth->h_proto) || + (orig_bcast !=is_multicast_ether_addr_64bits (eth->h_dest))) { +__skb_push (skb,ETH_HLEN ); + skb->protocol =eth_type_trans (skb, skb->dev); + } +switch (act) {case XDP_REDIRECT :case XDP_TX :
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 174/209 lightnvm: pblk: fix error handling of pblk_lines_init()
In reply to Sasha LevinFrom: Wei Yongjun <[email protected]>
[ Upstream commit a70985f83c625a5eaf618be81621e5e4521a66c6 ]
In the too many bad blocks error handling case, we should release all the allocated resources, otherwise it will cause memory leak.
--- drivers/lightnvm/pblk-init.c | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)
drivers/lightnvm/pblk-init.c +2 -1
@@ -1084,7 +1084,8 @@ static int pblk_lines_init(struct pblk *pblk)if (!nr_free_chks) {pblk_err (pblk,"too many bad blocks prevent for sane instance\n" ); -return -EINTR ; + ret = -EINTR ; + goto fail_free_lines; }pblk_set_provision (pblk, nr_free_chks);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 169/209 lightnvm: pblk: fix incorrect min_write_pgs
In reply to Sasha LevinFrom: Matias Bjørling <[email protected]>
[ Upstream commit 8bbd45d02a118cbefdf4e1a6274bd965a6aa3c59 ]
The calculation of pblk->min_write_pgs should only use the optimal write size attribute provided by the drive, it does not correlate to the memory page size of the system, which can be smaller or larger than the LBA size reported.
--- drivers/lightnvm/pblk-init.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/lightnvm/pblk-init.c +1 -1
@@ -371,7 +371,7 @@ static int pblk_core_init(struct pblk *pblk)atomic64_set (&pblk->nr_flush,0 ); pblk->nr_flush_rst =0 ; - pblk->min_write_pgs = geo->ws_opt * (geo->csecs /PAGE_SIZE ); + pblk->min_write_pgs = geo->ws_opt; max_write_ppas = pblk->min_write_pgs * geo->all_luns; pblk->max_write_pgs =min_t (int, max_write_ppas,NVM_MAX_VLBA );pblk_set_sec_per_write (pblk, pblk->min_write_pgs);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 171/209 lightnvm: pblk: fix write amplificiation calculation
In reply to Sasha LevinFrom: Hans Holmberg <[email protected]>
[ Upstream commit 765462fa4c4d0fd3eb718f2ba14cb04c35219854 ]
When the user data counter exceeds 32 bits, the write amplification calculation does not provide the right value. Fix this by using div64_u64 in stead of div64.
--- drivers/lightnvm/pblk-sysfs.c | 3 +-- 1 file changed, 1 insertion(+), 2 deletions(-)
drivers/lightnvm/pblk-sysfs.c +1 -2
@@ -343,7 +343,6 @@ static ssize_t pblk_get_write_amp(u64 user, u64 gc, u64 pad, {int sz; - sz =snprintf (page,PAGE_SIZE ,"user:%lld gc:%lld pad:%lld WA:" , user, gc, pad);
@@ -355,7 +354,7 @@ static ssize_t pblk_get_write_amp(u64 user, u64 gc, u64 pad,u32 wa_frac; wa_int = (user + gc + pad) *100000 ; - wa_int =div_u64 (wa_int, user); + wa_int =div64_u64 (wa_int, user); wa_int =div_u64_rem (wa_int,100000 , &wa_frac); sz += snprintf(page + sz, PAGE_SIZE - sz, "%llu.%05u\n",
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 161/209 mfd: ti_am335x_tscadc: Keep ADC interface on if child is wakeup capable
In reply to Sasha LevinFrom: Vignesh R <[email protected]>
[ Upstream commit c974ac771479327b5424f60d58845e31daddadea ]
If a child device like touchscreen is wakeup capable, then keep ADC interface on, so that a touching resistive screen will generate wakeup event to the system.
--- drivers/mfd/ti_am335x_tscadc.c | 13 +++++++++++++ 1 file changed, 13 insertions(+)
drivers/mfd/ti_am335x_tscadc.c +13 -0
@@ -295,11 +295,24 @@ static int ti_tscadc_remove(struct platform_device *pdev)return 0 ; } +static int __maybe_unused ti_tscadc_can_wakeup (struct device *dev,void *data) +{ +return device_may_wakeup (dev); +} +static int __maybe_unused tscadc_suspend (struct device *dev) {struct ti_tscadc_dev *tscadc =dev_get_drvdata (dev);regmap_write (tscadc->regmap,REG_SE ,0x00 ); +if (device_for_each_child (dev,NULL , ti_tscadc_can_wakeup)) { +u32 ctrl; + +regmap_read (tscadc->regmap,REG_CTRL , &ctrl); + ctrl &= ~(CNTRLREG_POWERDOWN ); + ctrl |=CNTRLREG_TSCSSENB ; +regmap_write (tscadc->regmap,REG_CTRL , ctrl); + }pm_runtime_put_sync (dev);return 0 ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 164/209 GFS2: Flush the GFS2 delete workqueue before stopping the kernel threads
In reply to Sasha LevinFrom: Tim Smith <[email protected]>
[ Upstream commit 1eb8d7387908022951792a46fa040ad3942b3b08 ]
Flushing the workqueue can cause operations to happen which might call gfs2_log_reserve(), or get stuck waiting for locks taken by such operations. gfs2_log_reserve() can io_schedule(). If this happens, it will never wake because the only thing which can wake it is gfs2_logd() which was already stopped.
This causes umount of a gfs2 filesystem to wedge permanently if, for example, the umount immediately follows a large delete operation.
When this occured, the following stack trace was obtained from the umount command
[<ffffffff81087968>] flush_workqueue+0x1c8/0x520 [<ffffffffa0666e29>] gfs2_make_fs_ro+0x69/0x160 [gfs2] [<ffffffffa0667279>] gfs2_put_super+0xa9/0x1c0 [gfs2] [<ffffffff811b7edf>] generic_shutdown_super+0x6f/0x100 [<ffffffff811b7ff7>] kill_block_super+0x27/0x70 [<ffffffffa0656a71>] gfs2_kill_sb+0x71/0x80 [gfs2] [<ffffffff811b792b>] deactivate_locked_super+0x3b/0x70 [<ffffffff811b79b9>] deactivate_super+0x59/0x60 [<ffffffff811d2998>] cleanup_mnt+0x58/0x80 [<ffffffff811d2a12>] __cleanup_mnt+0x12/0x20 [<ffffffff8108c87d>] task_work_run+0x7d/0xa0 [<ffffffff8106d7d9>] exit_to_usermode_loop+0x73/0x98 [<ffffffff81003961>] syscall_return_slowpath+0x41/0x50 [<ffffffff815a594c>] int_ret_from_sys_call+0x25/0x8f
[<ffffffffffffffff>] 0xffffffffffffffff
--- fs/gfs2/super.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
fs/gfs2/super.c +1 -1
@@ -854,10 +854,10 @@ static int gfs2_make_fs_ro(struct gfs2_sbd *sdp)if (error && !test_bit (SDF_SHUTDOWN , &sdp->sd_flags))return error; +flush_workqueue (gfs2_delete_workqueue);kthread_stop (sdp->sd_quotad_process);kthread_stop (sdp->sd_logd_process); -flush_workqueue (gfs2_delete_workqueue);gfs2_quota_sync (sdp->sd_vfs,0 );gfs2_statfs_sync (sdp->sd_vfs,0 );
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 163/209 media: isif: fix a NULL pointer dereference bug
In reply to Sasha LevinFrom: Wenwen Wang <[email protected]>
[ Upstream commit a26ac6c1bed951b2066cc4b2257facd919e35c0b ]
In isif_probe(), there is a while loop to get the ISIF base address and linearization table0 and table1 address. In the loop body, the function platform_get_resource() is called to get the resource. If platform_get_resource() returns NULL, the loop is terminated and the execution goes to 'fail_nobase_res'. Suppose the loop is terminated at the first iteration because platform_get_resource() returns NULL and the execution goes to 'fail_nobase_res'. Given that there is another while loop at 'fail_nobase_res' and i equals to 0, one iteration of the second while loop will be executed. However, the second while loop does not check the return value of platform_get_resource(). This can cause a NULL pointer dereference bug if the return value is a NULL pointer.
This patch avoids the above issue by adding a check in the second while loop after the call to platform_get_resource().
--- drivers/media/platform/davinci/isif.c | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)
drivers/media/platform/davinci/isif.c +2 -1
@@ -1100,7 +1100,8 @@ static int isif_probe(struct platform_device *pdev)while (i >=0 ) { res =platform_get_resource (pdev,IORESOURCE_MEM , i); -release_mem_region (res->start,resource_size (res)); +if (res) +release_mem_region (res->start,resource_size (res)); i--; }vpfe_unregister_ccdc_device (&isif_hw_dev);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 162/209 printk: Give error on attempt to set log buffer length to over 2G
In reply to Sasha LevinFrom: He Zhe <[email protected]>
[ Upstream commit e6fe3e5b7d16e8f146a4ae7fe481bc6e97acde1e ]
The current printk() is ready to handle log buffer size up to 2G. Give an explicit error for users who want to use larger log buffer.
Also fix printk formatting to show the 2G as a positive number.
--- kernel/printk/printk.c | 18 ++++++++++++------ 1 file changed, 12 insertions(+), 6 deletions(-)
kernel/printk/printk.c +12 -6
@@ -438,6 +438,7 @@ static u32 clear_idx;/* record buffer */ #define LOG_ALIGN __alignof__(struct printk_log)#define __LOG_BUF_LEN (1 << CONFIG_LOG_BUF_SHIFT) +#define LOG_BUF_LEN_MAX (u32)(1 << 31)static char __log_buf[__LOG_BUF_LEN]__aligned(LOG_ALIGN) ;static char *log_buf = __log_buf;static u32 log_buf_len = __LOG_BUF_LEN;
@@ -1038,18 +1039,23 @@ void log_buf_vmcoreinfo_setup(void)static unsigned long __initdata new_log_buf_len;/* we practice scaling the ring buffer by powers of 2 */ -static void __init log_buf_len_update (unsigned size) +static void __init log_buf_len_update (u64 size) { +if (size > (u64 )LOG_BUF_LEN_MAX ) { + size = (u64 )LOG_BUF_LEN_MAX ; +pr_err ("log_buf over 2G is not supported.\n" ); + } +if (size) size =roundup_pow_of_two (size);if (size > log_buf_len) - new_log_buf_len = size; + new_log_buf_len = (unsigned long )size; }/* save requested log_buf_len since it's too early to process it */ static int __init log_buf_len_setup (char *str) { -unsigned int size; +u64 size;if (!str)return -EINVAL ;
@@ -1119,7 +1125,7 @@ void __init setup_log_buf(int early) }if (unlikely (!new_log_buf)) { -pr_err ("log_buf_len: %ld bytes not available\n" , +pr_err ("log_buf_len: %lu bytes not available\n" , new_log_buf_len);return ; }
@@ -1132,8 +1138,8 @@ void __init setup_log_buf(int early)memcpy (log_buf, __log_buf, __LOG_BUF_LEN);logbuf_unlock_irqrestore (flags); -pr_info ("log_buf_len: %d bytes\n" , log_buf_len); -pr_info ("early log buf free: %d(%d%%)\n" , +pr_info ("log_buf_len: %u bytes\n" , log_buf_len); +pr_info ("early log buf free: %u(%u%%)\n" , free, (free *100 ) / __LOG_BUF_LEN); }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 150/209 media: cx18: Don't check for address of video_dev
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit eb1ca9a428fdc3f98be4898f6cd8bcb803878619 ]
Clang warns that the address of a pointer will always evaluated as true in a boolean context.
drivers/media/pci/cx18/cx18-driver.c:1255:23: warning: address of 'cx->streams[i].video_dev' will always evaluate to 'true' [-Wpointer-bool-conversion]
if (&cx->streams[i].video_dev)
~~ ~~~~~~~~~~~~~~~^~~~~~~~~1 warning generated.
Check whether v4l2_dev is null, not the address, so that the statement doesn't fire all the time. This check has been present since 2009, introduced by commit 21a278b85d3c ("V4L/DVB (11619): cx18: Simplify the work handler for outgoing mailbox commands")
--- drivers/media/pci/cx18/cx18-driver.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/media/pci/cx18/cx18-driver.c +1 -1
@@ -1252,7 +1252,7 @@ static void cx18_cancel_out_work_orders(struct cx18 *cx) {int i;for (i =0 ; i <CX18_MAX_STREAMS ; i++) -if (&cx->streams[i].video_dev) +if (cx->streams[i].video_dev.v4l2_dev)cancel_work_sync (&cx->streams[i].out_work_order); }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 148/209 media: dw9714: Fix error handling in probe function
In reply to Sasha LevinFrom: Rajmohan Mani <[email protected]>
[ Upstream commit f9a0b14240a2d0bd196d35e8aac73df6eabd6382 ]
Fixed the case where v4l2_async_unregister_subdev() is called unnecessarily in the error handling path in probe function.
--- drivers/media/i2c/dw9714.c | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)
drivers/media/i2c/dw9714.c +2 -1
@@ -169,7 +169,8 @@ static int dw9714_probe(struct i2c_client *client)return 0 ; err_cleanup: -dw9714_subdev_cleanup (dw9714_dev); +v4l2_ctrl_handler_free (&dw9714_dev->ctrls_vcm); +media_entity_cleanup (&dw9714_dev->sd.entity);dev_err (&client->dev,"Probe failed: %d\n" , rval);return rval; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 135/209 xsk: proper AF_XDP socket teardown ordering
In reply to Sasha LevinFrom: Björn Töpel <[email protected]>
[ Upstream commit 541d7fdd7694560404c502f64298a90ffe017e6b ]
The AF_XDP socket struct can exist in three different, implicit
states: setup, bound and released. Setup is prior the socket has been bound to a device. Bound is when the socket is active for receive and send. Released is when the process/userspace side of the socket is released, but the sock object is still lingering, e.g. when there is a reference to the socket in an XSKMAP after process termination.
The Rx fast-path code uses the "dev" member of struct xdp_sock to check whether a socket is bound or relased, and the Tx code uses the struct xdp_umem "xsk_list" member in conjunction with "dev" to determine the state of a socket.
However, the transition from bound to released did not tear the socket down in correct order.
On the Rx side "dev" was cleared after synchronize_net() making the synchronization useless. On the Tx side, the internal queues were destroyed prior removing them from the "xsk_list".
This commit corrects the cleanup order, and by doing so xdp_del_sk_umem() can be simplified and one synchronize_net() can be removed.
--- net/xdp/xdp_umem.c | 11 +++-------- net/xdp/xsk.c | 13 ++++++++----- 2 files changed, 11 insertions(+), 13 deletions(-)
net/xdp/xdp_umem.c +3 -8
@@ -32,14 +32,9 @@ void xdp_del_sk_umem(struct xdp_umem *umem, struct xdp_sock *xs) {unsigned long flags; -if (xs->dev) { -spin_lock_irqsave (&umem->xsk_list_lock, flags); -list_del_rcu (&xs->list); -spin_unlock_irqrestore (&umem->xsk_list_lock, flags); - -if (umem->zc) -synchronize_net (); - } +spin_lock_irqsave (&umem->xsk_list_lock, flags); +list_del_rcu (&xs->list); +spin_unlock_irqrestore (&umem->xsk_list_lock, flags); }int xdp_umem_query (struct net_device *dev,u16 queue_id)
net/xdp/xsk.c +8 -5
@@ -343,12 +343,18 @@ static int xsk_release(struct socket *sock)local_bh_enable ();if (xs->dev) { +struct net_device *dev = xs->dev; +/* Wait for driver to stop using the xdp socket. */ -synchronize_net (); -dev_put (xs->dev); +xdp_del_sk_umem (xs->umem, xs); xs->dev =NULL ; +synchronize_net (); +dev_put (dev); } +xskq_destroy (xs->rx); +xskq_destroy (xs->tx); +sock_orphan (sk); sock->sk =NULL ;
@@ -707,9 +713,6 @@ static void xsk_destruct(struct sock *sk)if (!sock_flag (sk,SOCK_DEAD ))return ; -xskq_destroy (xs->rx); -xskq_destroy (xs->tx); -xdp_del_sk_umem (xs->umem, xs);xdp_put_umem (xs->umem);sk_refcnt_debug_dec (sk);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 132/209 xfrm: use correct size to initialise sp->ovec
In reply to Sasha LevinFrom: Li RongQing <[email protected]>
[ Upstream commit f1193e915748291fb205a908db33bd3debece6e2 ]
This place should want to initialize array, not a element, so it should be sizeof(array) instead of sizeof(element)
but now this array only has one element, so no error in this condition that XFRM_MAX_OFFLOAD_DEPTH is 1
--- net/xfrm/xfrm_input.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
net/xfrm/xfrm_input.c +1 -1
@@ -131,7 +131,7 @@ struct sec_path *secpath_dup(struct sec_path *src) sp->len =0 ; sp->olen =0 ; -memset (sp->ovec,0 ,sizeof (sp->ovec[XFRM_MAX_OFFLOAD_DEPTH ])); +memset (sp->ovec,0 ,sizeof (sp->ovec));if (src) {int i;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 131/209 crypto: mxs-dcp - Fix AES issues
In reply to Sasha LevinFrom: Radu Solea <[email protected]>
[ Upstream commit fadd7a6e616b89c7f4f7bfa7b824f290bab32c3c ]
The DCP driver does not obey cryptlen, when doing android CTS this results in passing to hardware input stream lengths which are not multiple of block size.
Add a check to prevent future erroneous stream lengths from reaching the hardware and adjust the scatterlist walking code to obey cryptlen.
Also properly copy-out the IV for chaining.
--- drivers/crypto/mxs-dcp.c | 33 +++++++++++++++++++++++++++++++-- 1 file changed, 31 insertions(+), 2 deletions(-)
drivers/crypto/mxs-dcp.c +31 -2
@@ -225,6 +225,12 @@ static int mxs_dcp_run_aes(struct dcp_async_ctx *actx,dma_addr_t dst_phys =dma_map_single (sdcp->dev, sdcp->coh->aes_out_buf,DCP_BUF_SZ ,DMA_FROM_DEVICE ); +if (actx->fill %AES_BLOCK_SIZE ) { +dev_err (sdcp->dev,"Invalid block size!\n" ); + ret = -EINVAL ; + goto aes_done_run; + } +/* Fill in the DMA descriptor. */ desc->control0 =MXS_DCP_CONTROL0_DECR_SEMAPHORE | MXS_DCP_CONTROL0_INTERRUPT |
@@ -254,6 +260,7 @@ static int mxs_dcp_run_aes(struct dcp_async_ctx *actx, ret =mxs_dcp_start_dma (actx); +aes_done_run:dma_unmap_single (sdcp->dev, key_phys,2 *AES_KEYSIZE_128 ,DMA_TO_DEVICE );dma_unmap_single (sdcp->dev, src_phys,DCP_BUF_SZ ,DMA_TO_DEVICE );
@@ -280,13 +287,15 @@ static int mxs_dcp_aes_block_crypt(struct crypto_async_request *arq)uint8_t *out_tmp, *src_buf, *dst_buf =NULL ;uint32_t dst_off =0 ; +uint32_t last_out_len =0 ;uint8_t *key = sdcp->coh->aes_key;int ret =0 ;int split =0 ; -unsigned int i, len, clen, rem =0 ; +unsigned int i, len, clen, rem =0 , tlen =0 ;int init =0 ; +bool limit_hit = false; actx->fill =0 ;
@@ -305,6 +314,11 @@ static int mxs_dcp_aes_block_crypt(struct crypto_async_request *arq)for_each_sg (req->src, src, nents, i) { src_buf =sg_virt (src); len =sg_dma_len (src); + tlen += len; + limit_hit = tlen > req->nbytes; + +if (limit_hit) + len = req->nbytes - (tlen - len); do { if (actx->fill + len > out_off)
@@ -321,13 +335,15 @@ static int mxs_dcp_aes_block_crypt(struct crypto_async_request *arq)* If we filled the buffer or this is the last SG, * submit the buffer. */ -if (actx->fill == out_off ||sg_is_last (src)) { +if (actx->fill == out_off ||sg_is_last (src) || + limit_hit) { ret =mxs_dcp_run_aes (actx, req, init);if (ret)return ret; init =0 ; out_tmp = out_buf; + last_out_len = actx->fill;while (dst && actx->fill) {if (!split) { dst_buf =sg_virt (dst);
@@ -350,6 +366,19 @@ static int mxs_dcp_aes_block_crypt(struct crypto_async_request *arq) } } }while (len); + +if (limit_hit) +break ; + } + +/* Copy the IV for CBC for chaining */ +if (!rctx->ecb) { +if (rctx->enc) +memcpy (req->info, out_buf+(last_out_len-AES_BLOCK_SIZE ), +AES_BLOCK_SIZE ); +else +memcpy (req->info, in_buf+(last_out_len-AES_BLOCK_SIZE ), +AES_BLOCK_SIZE ); }return ret;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 128/209 x86/olpc: Fix build error with CONFIG_MFD_CS5535=m
In reply to Sasha LevinFrom: Borislav Petkov <[email protected]>
[ Upstream commit fa112cf1e8bc693d5a666b1c479a2859c8b6e0f1 ]
When building a 32-bit config which has the above MFD item as module but OLPC_XO1_PM is enabled =y - which is bool, btw - the kernel fails building with:
ld: arch/x86/platform/olpc/olpc-xo1-pm.o: in function `xo1_pm_remove':
/home/boris/kernel/linux/arch/x86/platform/olpc/olpc-xo1-pm.c:159: undefined reference to `mfd_cell_disable'
ld: arch/x86/platform/olpc/olpc-xo1-pm.o: in function `xo1_pm_probe':
/home/boris/kernel/linux/arch/x86/platform/olpc/olpc-xo1-pm.c:133: undefined reference to `mfd_cell_enable'
make: *** [Makefile:1030: vmlinux] Error 1
Force MFD_CS5535 to y if OLPC_XO1_PM is enabled.
--- arch/x86/Kconfig | 3 +-- 1 file changed, 1 insertion(+), 2 deletions(-)
arch/x86/Kconfig +1 -2
@@ -2726,8 +2726,7 @@ config OLPC config OLPC_XO1_PM bool "OLPC XO-1 Power Management" - depends on OLPC && MFD_CS5535 && PM_SLEEP - select MFD_CORE + depends on OLPC && MFD_CS5535=y && PM_SLEEP ---help--- Add support for poweroff and suspend of the OLPC XO-1 laptop.
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 125/209 remoteproc: Check for NULL firmwares in sysfs interface
In reply to Sasha LevinFrom: Suman Anna <[email protected]>
[ Upstream commit faeadbb64094757150a8c2a3175ca418dbdd472c ]
The remoteproc framework provides a sysfs file 'firmware' for modifying the firmware image name from userspace. Add an additional check to ensure NULL firmwares are errored out right away, rather than getting a delayed error while requesting a firmware during the start of a remoteproc later on.
--- drivers/remoteproc/remoteproc_sysfs.c | 5 +++++ 1 file changed, 5 insertions(+)
drivers/remoteproc/remoteproc_sysfs.c +5 -0
@@ -48,6 +48,11 @@ static ssize_t firmware_store(struct device *dev, } len =strcspn (buf,"\n" ); +if (!len) { +dev_err (dev,"can't provide a NULL firmware\n" ); + err = -EINVAL ; + goto out; + } p =kstrndup (buf, len,GFP_KERNEL );if (!p) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 126/209 remoteproc: qcom: q6v5: Fix a race condition on fatal crash
In reply to Sasha LevinFrom: Sibi Sankar <[email protected]>
[ Upstream commit d3ae96c0e6b042a883927493351b2af6ee05e92c ]
Currently with GLINK_SSR enabled each fatal crash results in servicing a crash from wdog as well. This is due to a race that occurs in setting the running flag in the shutdown path. Fix this by moving the running flag to the end of fatal interrupt handler.
Crash Logs:
qcom-q6v5-pil 4080000.remoteproc: fatal error without message remoteproc remoteproc0: crash detected in 4080000.remoteproc: type fatal
error
remoteproc remoteproc0: handling crash #1 in 4080000.remoteproc remoteproc remoteproc0: recovering 4080000.remoteproc qcom-q6v5-pil 4080000.remoteproc: watchdog without message remoteproc remoteproc0: crash detected in 4080000.remoteproc: type watchdog remoteproc:glink-edge: intent request timed outqcom_glink_ssr remoteproc:glink-edge.glink_ssr.-1.-1: failed to send
cleanup messageqcom_glink_ssr remoteproc:glink-edge.glink_ssr.-1.-1: timeout waiting
for cleanup done message
qcom-q6v5-pil 4080000.remoteproc: timed out on wait qcom-q6v5-pil 4080000.remoteproc: port failed halt
remoteproc remoteproc0: stopped remote processor 4080000.remoteproc qcom-q6v5-pil 4080000.remoteproc: MBA booted, loading mpss remoteproc remoteproc0: remote processor 4080000.remoteproc is now up remoteproc remoteproc0: handling crash #2 in 4080000.remoteproc remoteproc remoteproc0: recovering 4080000.remoteproc qcom-q6v5-pil 4080000.remoteproc: port failed halt
remoteproc remoteproc0: stopped remote processor 4080000.remoteproc qcom-q6v5-pil 4080000.remoteproc: MBA booted, loading mpss remoteproc remoteproc0: remote processor 4080000.remoteproc is now up
--- drivers/remoteproc/qcom_q6v5.c | 3 +-- 1 file changed, 1 insertion(+), 2 deletions(-)
drivers/remoteproc/qcom_q6v5.c +1 -2
@@ -84,6 +84,7 @@ static irqreturn_t q6v5_fatal_interrupt(int irq, void *data)else dev_err (q6v5->dev,"fatal error without message\n" ); + q6v5->running = false;rproc_report_crash (q6v5->rproc,RPROC_FATAL_ERROR );return IRQ_HANDLED ;
@@ -150,8 +151,6 @@ int qcom_q6v5_request_stop(struct qcom_q6v5 *q6v5) {int ret; - q6v5->running = false; -qcom_smem_state_update_bits (q6v5->state,BIT (q6v5->stop_bit),BIT (q6v5->stop_bit));
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 115/209 gfs2: slow the deluge of io error messages
In reply to Sasha LevinFrom: Bob Peterson <[email protected]>
[ Upstream commit b524abcc01483b2ac093cc6a8a2a7375558d2b64 ]
When an io error is hit, it calls gfs2_io_error_bh_i for every journal buffer it can't write. Since we changed gfs2_io_error_bh_i recently to withdraw later in the cycle, it sends a flood of errors to the console. This patch checks for the file system already being withdrawn, and if so, doesn't send more messages. It doesn't stop the flood of messages, but it slows it down and keeps it more reasonable.
--- fs/gfs2/incore.h | 1 + fs/gfs2/log.c | 7 +++++-- fs/gfs2/util.c | 13 +++++++------ 3 files changed, 13 insertions(+), 8 deletions(-)
fs/gfs2/incore.h +1 -0
@@ -623,6 +623,7 @@ enum {SDF_RORECOVERY =7 ,/* read only recovery */ SDF_SKIP_DLM_UNLOCK =8 ,SDF_FORCE_AIL_FLUSH =9 , + SDF_AIL1_IO_ERROR = 10, }; enum gfs2_freeze_state {
fs/gfs2/log.c +5 -2
@@ -108,7 +108,9 @@ __acquires(&sdp->sd_ail_lock)gfs2_assert (sdp, bd->bd_tr == tr);if (!buffer_busy (bh)) { -if (!buffer_uptodate (bh)) { +if (!buffer_uptodate (bh) && + !test_and_set_bit (SDF_AIL1_IO_ERROR , + &sdp->sd_flags)) {gfs2_io_error_bh (sdp, bh); *withdraw = true; }
@@ -206,7 +208,8 @@ static void gfs2_ail1_empty_one(struct gfs2_sbd *sdp, struct gfs2_trans *tr,gfs2_assert (sdp, bd->bd_tr == tr);if (buffer_busy (bh))continue ; -if (!buffer_uptodate (bh)) { +if (!buffer_uptodate (bh) && + !test_and_set_bit (SDF_AIL1_IO_ERROR , &sdp->sd_flags)) {gfs2_io_error_bh (sdp, bh); *withdraw = true; }
fs/gfs2/util.c +7 -6
@@ -256,12 +256,13 @@ void gfs2_io_error_bh_i(struct gfs2_sbd *sdp, struct buffer_head *bh, const char *function, char *file, unsigned int line, bool withdraw) { - fs_err(sdp, - "fatal: I/O error\n" - " block = %llu\n" -" function = %s, file = %s, line = %u\n" , - (unsigned long long )bh->b_blocknr, - function, file, line); + if (!test_bit(SDF_SHUTDOWN, &sdp->sd_flags)) + fs_err(sdp, + "fatal: I/O error\n" + " block = %llu\n" +" function = %s, file = %s, line = %u\n" , + (unsigned long long )bh->b_blocknr, + function, file, line);if (withdraw)gfs2_lm_withdraw (sdp,NULL ); }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 114/209 media: cec-gpio: select correct Signal Free Time
In reply to Sasha LevinFrom: Hans Verkuil <[email protected]>
[ Upstream commit c439d5c1e13dbf66cff53455432f21d4d0536c51 ]
If a receive is in progress or starts before the transmit has a chance, then lower the Signal Free Time of the upcoming transmit to no more than CEC_SIGNAL_FREE_TIME_NEW_INITIATOR.
This is per the specification requirements.
--- drivers/media/cec/cec-pin.c | 20 ++++++++++++++++++++ 1 file changed, 20 insertions(+)
drivers/media/cec/cec-pin.c +20 -0
@@ -936,6 +936,17 @@ static enum hrtimer_restart cec_pin_timer(struct hrtimer *timer)/* Start bit, switch to receive state */ pin->ts = ts; pin->state =CEC_ST_RX_START_BIT_LOW ; +/* +* If a transmit is pending, then that transmit should +* use a signal free time of no more than +* CEC_SIGNAL_FREE_TIME_NEW_INITIATOR since it will +* have a new initiator due to the receive that is now +* starting. +*/ +if (pin->tx_msg.len && pin->tx_signal_free_time > +CEC_SIGNAL_FREE_TIME_NEW_INITIATOR ) + pin->tx_signal_free_time = +CEC_SIGNAL_FREE_TIME_NEW_INITIATOR ;break ; }if (ktime_to_ns (pin->ts) ==0 )
@@ -1158,6 +1169,15 @@ static int cec_pin_adap_transmit(struct cec_adapter *adap, u8 attempts, {struct cec_pin *pin = adap->pin; +/* +* If a receive is in progress, then this transmit should use +* a signal free time of max CEC_SIGNAL_FREE_TIME_NEW_INITIATOR +* since when it starts transmitting it will have a new initiator. +*/ +if (pin->state !=CEC_ST_IDLE && + signal_free_time >CEC_SIGNAL_FREE_TIME_NEW_INITIATOR ) + signal_free_time =CEC_SIGNAL_FREE_TIME_NEW_INITIATOR ; + pin->tx_signal_free_time = signal_free_time; pin->tx_extra_bytes =0 ; pin->tx_msg = *msg;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 110/209 printk: Correct wrong casting
In reply to Sasha LevinFrom: He Zhe <[email protected]>
[ Upstream commit 51a72ab7372d85c96104e58036f1b49ba11e5d2b ]
log_first_seq and console_seq are 64-bit unsigned integers. Correct a wrong casting that might cut off the output.
--- kernel/printk/printk.c | 5 +++-- 1 file changed, 3 insertions(+), 2 deletions(-)
kernel/printk/printk.c +3 -2
@@ -2358,8 +2358,9 @@ void console_unlock(void)printk_safe_enter_irqsave (flags);raw_spin_lock (&logbuf_lock);if (console_seq < log_first_seq) { - len =sprintf (text,"** %u printk messages dropped **\n" , - (unsigned )(log_first_seq - console_seq)); + len =sprintf (text, +"** %llu printk messages dropped **\n" , + log_first_seq - console_seq);/* messages are gone, move to first one */ console_seq = log_first_seq;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 104/209 qtnfmac: inform wireless core about supported extended capabilities
In reply to Sasha LevinFrom: Sergey Matyukevich <[email protected]>
[ Upstream commit ab1c64a1d349cc7f1090a60ce85a53298e3d371d ]
Driver retrieves information about supported extended capabilities from wireless card. However this information is not propagated further to Linux wireless core. Fix this by setting extended capabilities fields of wiphy structure.
--- .../net/wireless/quantenna/qtnfmac/cfg80211.c | 9 +++++++++ .../net/wireless/quantenna/qtnfmac/commands.c | 3 +-- drivers/net/wireless/quantenna/qtnfmac/core.c | 16 ++++++++++++++-- drivers/net/wireless/quantenna/qtnfmac/core.h | 1 + 4 files changed, 25 insertions(+), 4 deletions(-)
drivers/net/wireless/quantenna/qtnfmac/cfg80211.c +9 -0
@@ -1126,6 +1126,15 @@ int qtnf_wiphy_register(struct qtnf_hw_info *hw_info, struct qtnf_wmac *mac) wiphy->regulatory_flags |=REGULATORY_WIPHY_SELF_MANAGED ; } +if (mac->macinfo.extended_capabilities_len) { + wiphy->extended_capabilities = + mac->macinfo.extended_capabilities; + wiphy->extended_capabilities_mask = + mac->macinfo.extended_capabilities_mask; + wiphy->extended_capabilities_len = + mac->macinfo.extended_capabilities_len; + } +strlcpy (wiphy->fw_version, hw_info->fw_version,sizeof (wiphy->fw_version)); wiphy->hw_version = hw_info->hw_version;
drivers/net/wireless/quantenna/qtnfmac/commands.c +1 -2
@@ -1356,8 +1356,7 @@ static int qtnf_parse_variable_mac_info(struct qtnf_wmac *mac, ext_capa_mask =NULL ; } -kfree (mac->macinfo.extended_capabilities); -kfree (mac->macinfo.extended_capabilities_mask); +qtnf_mac_ext_caps_free (mac); mac->macinfo.extended_capabilities = ext_capa; mac->macinfo.extended_capabilities_mask = ext_capa_mask; mac->macinfo.extended_capabilities_len = ext_capa_len;
drivers/net/wireless/quantenna/qtnfmac/core.c +14 -2
@@ -304,6 +304,19 @@ void qtnf_mac_iface_comb_free(struct qtnf_wmac *mac) } } +void qtnf_mac_ext_caps_free (struct qtnf_wmac *mac) +{ +if (mac->macinfo.extended_capabilities_len) { +kfree (mac->macinfo.extended_capabilities); + mac->macinfo.extended_capabilities =NULL ; + +kfree (mac->macinfo.extended_capabilities_mask); + mac->macinfo.extended_capabilities_mask =NULL ; + + mac->macinfo.extended_capabilities_len =0 ; + } +} +static void qtnf_vif_reset_handler (struct work_struct *work) { struct qtnf_vif *vif = container_of(work, struct qtnf_vif, reset_work);
@@ -493,8 +506,7 @@ static void qtnf_core_mac_detach(struct qtnf_bus *bus, unsigned int macid) }qtnf_mac_iface_comb_free (mac); -kfree (mac->macinfo.extended_capabilities); -kfree (mac->macinfo.extended_capabilities_mask); +qtnf_mac_ext_caps_free (mac);kfree (mac->macinfo.wowlan);wiphy_free (wiphy); bus->mac[macid] =NULL ;
drivers/net/wireless/quantenna/qtnfmac/core.h +1 -0
@@ -151,6 +151,7 @@ struct qtnf_hw_info {struct qtnf_vif *qtnf_mac_get_free_vif (struct qtnf_wmac *mac);struct qtnf_vif *qtnf_mac_get_base_vif (struct qtnf_wmac *mac);void qtnf_mac_iface_comb_free (struct qtnf_wmac *mac); +void qtnf_mac_ext_caps_free (struct qtnf_wmac *mac);struct wiphy *qtnf_wiphy_allocate (struct qtnf_bus *bus);int qtnf_core_net_attach (struct qtnf_wmac *mac,struct qtnf_vif *priv,const char *name,unsigned char name_assign_type);
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 100/209 brcmfmac: reduce timeout for action frame scan
In reply to Sasha LevinFrom: Chung-Hsien Hsu <[email protected]>
[ Upstream commit edb6d6885bef82d1eac432dbeca9fbf4ec349d7e ]
Finding a common channel to send an action frame out is required for some action types. Since a loop with several scan retry is used to find the channel, a short wait time could be considered for each attempt. This patch reduces the wait time from 1500 to 450 msec for each action frame scan.
This patch fixes the WFA p2p certification 5.1.20 failure caused by the long action frame send time.
--- drivers/net/wireless/broadcom/brcm80211/brcmfmac/p2p.c | 9 ++++----- 1 file changed, 4 insertions(+), 5 deletions(-)
drivers/net/wireless/broadcom/brcm80211/brcmfmac/p2p.c +4 -5
@@ -74,7 +74,7 @@#define P2P_AF_MAX_WAIT_TIME msecs_to_jiffies(2000)#define P2P_INVALID_CHANNEL -1#define P2P_CHANNEL_SYNC_RETRY 5 -#define P2P_AF_FRM_SCAN_MAX_WAIT msecs_to_jiffies(1500) +#define P2P_AF_FRM_SCAN_MAX_WAIT msecs_to_jiffies(450)#define P2P_DEFAULT_SLEEP_TIME_VSDB 200/* WiFi P2P Public Action Frame OUI Subtypes */
@@ -1134,7 +1134,6 @@ static s32 brcmf_p2p_af_searching_channel(struct brcmf_p2p_info *p2p) {struct afx_hdl *afx_hdl = &p2p->afx_hdl;struct brcmf_cfg80211_vif *pri_vif; -unsigned long duration;s32 retry;brcmf_dbg (TRACE ,"Enter\n" );
@@ -1150,7 +1149,6 @@ static s32 brcmf_p2p_af_searching_channel(struct brcmf_p2p_info *p2p)* pending action frame tx is cancelled. */ retry =0 ; - duration =msecs_to_jiffies (P2P_AF_FRM_SCAN_MAX_WAIT );while ((retry <P2P_CHANNEL_SYNC_RETRY ) && (afx_hdl->peer_chan ==P2P_INVALID_CHANNEL )) { afx_hdl->is_listen = false;
@@ -1158,7 +1156,8 @@ static s32 brcmf_p2p_af_searching_channel(struct brcmf_p2p_info *p2p) retry);/* search peer on peer's listen channel */ schedule_work (&afx_hdl->afx_work); -wait_for_completion_timeout (&afx_hdl->act_frm_scan, duration); +wait_for_completion_timeout (&afx_hdl->act_frm_scan, +P2P_AF_FRM_SCAN_MAX_WAIT );if ((afx_hdl->peer_chan !=P2P_INVALID_CHANNEL ) || (!test_bit (BRCMF_P2P_STATUS_FINDING_COMMON_CHANNEL , &p2p->status)))
@@ -1171,7 +1170,7 @@ static s32 brcmf_p2p_af_searching_channel(struct brcmf_p2p_info *p2p) afx_hdl->is_listen = true;schedule_work (&afx_hdl->afx_work);wait_for_completion_timeout (&afx_hdl->act_frm_scan, - duration); +P2P_AF_FRM_SCAN_MAX_WAIT ); } if ((afx_hdl->peer_chan != P2P_INVALID_CHANNEL) || (!test_bit(BRCMF_P2P_STATUS_FINDING_COMMON_CHANNEL,
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 89/209 media: rc: ir-rc6-decoder: enable toggle bit for Kathrein RCU-676 remote
In reply to Sasha LevinFrom: Matthias Reichl <[email protected]>
[ Upstream commit 85e4af0a7ae2f146769b7475ae531bf8a3f3afb4 ]
The Kathrein RCU-676 remote uses the 32-bit rc6 protocol and toggles bit 15 (0x8000) on repeated button presses, like MCE remotes.
Add it's customer code 0x80460000 to the 32-bit rc6 toggle handling code to get proper scancodes and toggle reports.
--- drivers/media/rc/ir-rc6-decoder.c | 9 +++++++-- 1 file changed, 7 insertions(+), 2 deletions(-)
drivers/media/rc/ir-rc6-decoder.c +7 -2
@@ -40,6 +40,7 @@#define RC6_6A_MCE_TOGGLE_MASK 0x8000/* for the body bits */ #define RC6_6A_LCC_MASK 0xffff0000/* RC6-6A-32 long customer code mask */ #define RC6_6A_MCE_CC 0x800f0000/* MCE customer code */ +#define RC6_6A_KATHREIN_CC 0x80460000/* Kathrein RCU-676 customer code */ #ifndef CHAR_BIT #define CHAR_BIT 8/* Normally in <limits.h> */ #endif
@@ -242,13 +243,17 @@ static int ir_rc6_decode(struct rc_dev *dev, struct ir_raw_event ev) toggle =0 ;break ;case 32 : -if ((scancode &RC6_6A_LCC_MASK ) ==RC6_6A_MCE_CC ) { +switch (scancode &RC6_6A_LCC_MASK ) { +case RC6_6A_MCE_CC : +case RC6_6A_KATHREIN_CC : protocol =RC_PROTO_RC6_MCE ; toggle = !!(scancode &RC6_6A_MCE_TOGGLE_MASK ); scancode &= ~RC6_6A_MCE_TOGGLE_MASK ; - }else { +break ; +default : protocol =RC_PROTO_RC6_6A_32 ; toggle =0 ; +break ; }break ;default :
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 97/209 usb: dwc2: disable power_down on rockchip devices
In reply to Sasha LevinFrom: SolidHal <[email protected]>
[ Upstream commit c216765d3a1defda5e7e2dabd878f99f0cd2ebf2 ]
The bug would let the usb controller enter partial power down, which was formally known as hibernate, upon boot if nothing was plugged in to the port. Partial power down couldn't be exited properly, so any usb devices plugged in after boot would not be usable.
Before the name change, params.hibernation was false by default, so _dwc2_hcd_suspend() would skip entering hibernation. With the rename, _dwc2_hcd_suspend() was changed to use params.power_down to decide whether or not to enter partial power down.
Since params.power_down is non-zero by default, it needs to be set to 0 for rockchip devices to restore functionality.
This bug was reported in the linux-usb thread:
REGRESSION: usb: dwc2: USB device not seen after boot
The commit that caused this regression is:6d23ee9caa6790aea047f9aca7f3c03cb8d96eb6
--- drivers/usb/dwc2/params.c | 1 + 1 file changed, 1 insertion(+)
drivers/usb/dwc2/params.c +1 -0
@@ -88,6 +88,7 @@ static void dwc2_set_rk_params(struct dwc2_hsotg *hsotg) p->host_perio_tx_fifo_size =256 ; p->ahbcfg =GAHBCFG_HBSTLEN_INCR16 <<GAHBCFG_HBSTLEN_SHIFT ; + p->power_down =0 ; }static void dwc2_set_ltq_params (struct dwc2_hsotg *hsotg)
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 92/209 media: i2c: adv748x: Support probing a single output
In reply to Sasha LevinFrom: Jacopo Mondi <[email protected]>
[ Upstream commit eccf442ce156ec2b4e06b1239d5fdcb0c732f63f ]
Currently the adv748x driver will fail to probe unless both of its output endpoints (TXA and TXB) are connected.
Make the driver support probing provided that there is at least one input, and one output connected and protect the clean-up function from accessing un-initialized fields.
Following patches will fix other uses of un-initialized TXs in the driver, such as power management functions.
--- drivers/media/i2c/adv748x/adv748x-core.c | 25 +++++++++++++++++++++--- drivers/media/i2c/adv748x/adv748x-csi2.c | 18 ++++++----------- drivers/media/i2c/adv748x/adv748x.h | 2 ++ 3 files changed, 30 insertions(+), 15 deletions(-)
drivers/media/i2c/adv748x/adv748x-core.c +22 -3
@@ -569,7 +569,8 @@ static int adv748x_parse_dt(struct adv748x_state *state) {struct device_node *ep_np =NULL ;struct of_endpoint ep; -bool found = false; +bool out_found = false; +bool in_found = false;for_each_endpoint_of_node (state->dev->of_node, ep_np) {of_graph_parse_endpoint (ep_np, &ep);
@@ -592,10 +593,17 @@ static int adv748x_parse_dt(struct adv748x_state *state)of_node_get (ep_np); state->endpoints[ep.port] = ep_np; - found = true; +/* +* At least one input endpoint and one output endpoint shall +* be defined. +*/ +if (ep.port <ADV748X_PORT_TXA ) + in_found = true; +else + out_found = true; } -return found ?0 : -ENODEV ; +return in_found && out_found ?0 : -ENODEV ; }static void adv748x_dt_cleanup (struct adv748x_state *state)
@@ -627,6 +635,17 @@ static int adv748x_probe(struct i2c_client *client, state->i2c_clients[ADV748X_PAGE_IO ] = client;i2c_set_clientdata (client, state); +/* +* We can not use container_of to get back to the state with two TXs; +* Initialize the TXs's fields unconditionally on the endpoint +* presence to access them later. +*/ + state->txa.state = state->txb.state = state; + state->txa.page =ADV748X_PAGE_TXA ; + state->txb.page =ADV748X_PAGE_TXB ; + state->txa.port =ADV748X_PORT_TXA ; + state->txb.port =ADV748X_PORT_TXB ; +/* Discover and process ports declared by the Device tree endpoints */ ret =adv748x_parse_dt (state);if (ret) {
drivers/media/i2c/adv748x/adv748x-csi2.c +6 -12
@@ -266,19 +266,10 @@ static int adv748x_csi2_init_controls(struct adv748x_csi2 *tx)int adv748x_csi2_init (struct adv748x_state *state,struct adv748x_csi2 *tx) { -struct device_node *ep;int ret; -/* We can not use container_of to get back to the state with two TXs */ - tx->state = state; - tx->page =is_txa (tx) ?ADV748X_PAGE_TXA :ADV748X_PAGE_TXB ; - - ep = state->endpoints[is_txa (tx) ?ADV748X_PORT_TXA :ADV748X_PORT_TXB ]; -if (!ep) { -adv_err (state,"No endpoint found for %s\n" , -is_txa (tx) ?"txa" :"txb" ); -return -ENODEV ; - } +if (!is_tx_enabled (tx)) +return 0 ;/* Initialise the virtual channel */ adv748x_csi2_set_virtual_channel (tx,0 );
@@ -288,7 +279,7 @@ int adv748x_csi2_init(struct adv748x_state *state, struct adv748x_csi2 *tx) is_txa(tx) ? "txa" : "txb");/* Ensure that matching is based upon the endpoint fwnodes */ - tx->sd.fwnode =of_fwnode_handle (ep); + tx->sd.fwnode =of_fwnode_handle (state->endpoints[tx->port]);/* Register internal ops for incremental subdev registration */ tx->sd.internal_ops = &adv748x_csi2_internal_ops;
@@ -321,6 +312,9 @@ int adv748x_csi2_init(struct adv748x_state *state, struct adv748x_csi2 *tx)void adv748x_csi2_cleanup (struct adv748x_csi2 *tx) { +if (!is_tx_enabled (tx)) +return ; +v4l2_async_unregister_subdev (&tx->sd);media_entity_cleanup (&tx->sd.entity);v4l2_ctrl_handler_free (&tx->ctrl_hdl);
drivers/media/i2c/adv748x/adv748x.h +2 -0
@@ -82,6 +82,7 @@ struct adv748x_csi2 {struct adv748x_state *state;struct v4l2_mbus_framefmt format;unsigned int page; +unsigned int port;struct media_pad pads[ADV748X_CSI2_NR_PADS ];struct v4l2_ctrl_handler ctrl_hdl;
@@ -91,6 +92,7 @@ struct adv748x_csi2 {#define notifier_to_csi2 (n) container_of(n, struct adv748x_csi2, notifier)#define adv748x_sd_to_csi2 (sd) container_of(sd, struct adv748x_csi2, sd) +#define is_tx_enabled (_tx) ((_tx)->state->endpoints[(_tx)->port] != NULL)enum adv748x_hdmi_pads {ADV748X_HDMI_SINK ,
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 91/209 media: rcar-vin: fix redeclaration of symbol
In reply to Sasha LevinFrom: Niklas Söderlund <[email protected]>
[ Upstream commit 4e673ed4e2bfac00b3c3043a84e007874c17c84d ]
When adding support for parallel subdev for Gen3 it was missed that the symbol 'i' in rvin_group_link_notify() was already declared, remove the dupe as it's only used as a loop variable this have no functional change. This fixes warning:
rcar-core.c:117:52: originally declared here rcar-core.c:173:30: warning: symbol 'i' shadows an earlier one
--- drivers/media/platform/rcar-vin/rcar-core.c | 1 - 1 file changed, 1 deletion(-)
drivers/media/platform/rcar-vin/rcar-core.c +0 -1
@@ -174,7 +174,6 @@ static int rvin_group_link_notify(struct media_link *link, u32 flags,if (csi_id == -ENODEV ) {struct v4l2_subdev *sd; -unsigned int i;/* * Make sure the source entity subdevice is registered as
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 76/209 RDMA/hns: Limit the size of extend sge of sq
In reply to Sasha LevinFrom: Lijun Ou <[email protected]>
[ Upstream commit 05ad5482a5904c416bcfd74afd7193e206e563ce ]
The hip08 split two hardware version. The version id are 0x20 and 0x21 according to the PCI revison. The max size of extend sge of sq is limited to 2M for 0x20 version and 8M for 0x21 version. It may be exceeded to 2M according to the algorithm that compute the product of wqe count and extend sge number of every wqe. But the product always less than 8M.
--- drivers/infiniband/hw/hns/hns_roce_device.h | 1 + drivers/infiniband/hw/hns/hns_roce_hw_v2.c | 1 + drivers/infiniband/hw/hns/hns_roce_hw_v2.h | 1 + drivers/infiniband/hw/hns/hns_roce_qp.c | 19 +++++++++++++++++++ 4 files changed, 22 insertions(+)
drivers/infiniband/hw/hns/hns_roce_device.h +1 -0
@@ -665,6 +665,7 @@ struct hns_roce_caps {u32 max_sq_sg;/* 2 */ u32 max_sq_inline;/* 32 */ u32 max_rq_sg;/* 2 */ +u32 max_extend_sg;int num_qps;/* 256k */ int reserved_qps;u32 max_wqes;/* 16k */
drivers/infiniband/hw/hns/hns_roce_hw_v2.c +1 -0
@@ -1194,6 +1194,7 @@ static int hns_roce_v2_profile(struct hns_roce_dev *hr_dev) caps->num_cqs =HNS_ROCE_V2_MAX_CQ_NUM ; caps->max_cqes =HNS_ROCE_V2_MAX_CQE_NUM ; caps->max_sq_sg =HNS_ROCE_V2_MAX_SQ_SGE_NUM ; + caps->max_extend_sg =HNS_ROCE_V2_MAX_EXTEND_SGE_NUM ; caps->max_rq_sg =HNS_ROCE_V2_MAX_RQ_SGE_NUM ; caps->max_sq_inline =HNS_ROCE_V2_MAX_SQ_INLINE ; caps->num_uars =HNS_ROCE_V2_UAR_NUM ;
drivers/infiniband/hw/hns/hns_roce_hw_v2.h +1 -0
@@ -50,6 +50,7 @@#define HNS_ROCE_V2_MAX_CQE_NUM 0x10000#define HNS_ROCE_V2_MAX_RQ_SGE_NUM 0x100#define HNS_ROCE_V2_MAX_SQ_SGE_NUM 0xff +#define HNS_ROCE_V2_MAX_EXTEND_SGE_NUM 0x200000#define HNS_ROCE_V2_MAX_SQ_INLINE 0x20#define HNS_ROCE_V2_UAR_NUM 256#define HNS_ROCE_V2_PHY_UAR_NUM 1
drivers/infiniband/hw/hns/hns_roce_qp.c +19 -0
@@ -31,6 +31,7 @@* SOFTWARE. */ +#include <linux/pci.h> #include <linux/platform_device.h> #include <rdma/ib_addr.h> #include <rdma/ib_umem.h>
@@ -372,6 +373,16 @@ static int hns_roce_set_user_sq_size(struct hns_roce_dev *hr_dev,if (hr_qp->sq.max_gs >2 ) hr_qp->sge.sge_cnt =roundup_pow_of_two (hr_qp->sq.wqe_cnt * (hr_qp->sq.max_gs -2 )); + +if ((hr_qp->sq.max_gs >2 ) && (hr_dev->pci_dev->revision ==0x20 )) { +if (hr_qp->sge.sge_cnt > hr_dev->caps.max_extend_sg) { +dev_err (hr_dev->dev, +"The extended sge cnt error! sge_cnt=%d\n" , + hr_qp->sge.sge_cnt); +return -EINVAL ; + } + } + hr_qp->sge.sge_shift =4 ;/* Get buf size, SQ and RQ are aligned to page_szie */
@@ -465,6 +476,14 @@ static int hns_roce_set_kernel_sq_size(struct hns_roce_dev *hr_dev, hr_qp->sge.sge_shift =4 ; } +if ((hr_qp->sq.max_gs >2 ) && hr_dev->pci_dev->revision ==0x20 ) { +if (hr_qp->sge.sge_cnt > hr_dev->caps.max_extend_sg) { +dev_err (dev,"The extended sge cnt error! sge_cnt=%d\n" , + hr_qp->sge.sge_cnt); +return -EINVAL ; + } + } +/* Get buf size, SQ and RQ are aligned to PAGE_SIZE */ page_size =1 << (hr_dev->caps.mtt_buf_pg_sz +PAGE_SHIFT ); hr_qp->sq.offset =0 ;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 75/209 RDMA/hns: Bugfix for CM test
In reply to Sasha LevinFrom: Lijun Ou <[email protected]>
[ Upstream commit 15fc056fba7b17b9abfbe80a12f188403fc949fb ]
It will print the warning when the MSB bit of SLID is not zero running cm_req_handler function that test CM. It needs to fixed zero when test RoCE device.
--- drivers/infiniband/hw/hns/hns_roce_hw_v2.c | 1 + 1 file changed, 1 insertion(+)
drivers/infiniband/hw/hns/hns_roce_hw_v2.c +1 -0
@@ -2268,6 +2268,7 @@ static int hns_roce_v2_poll_one(struct hns_roce_cq *hr_cq, wc->src_qp = (u8 )roce_get_field (cqe->byte_32,V2_CQE_BYTE_32_RMT_QPN_M ,V2_CQE_BYTE_32_RMT_QPN_S ); + wc->slid =0 ; wc->wc_flags |= (roce_get_bit (cqe->byte_32,V2_CQE_BYTE_32_GRH_S ) ?IB_WC_GRH :0 );
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 78/209 rpmsg: glink: smem: Support rx peak for size less than 4 bytes
In reply to Sasha LevinFrom: Arun Kumar Neelakantam <[email protected]>
[ Upstream commit 928002a5e9dab2ddc1a0fe3e00739e89be30dc6b ]
The current rx peak function fails to read the data if size is less than 4bytes.
Use memcpy_fromio to support data reads of size less than 4 bytes.
--- drivers/rpmsg/qcom_glink_smem.c | 12 ++++-------- 1 file changed, 4 insertions(+), 8 deletions(-)
drivers/rpmsg/qcom_glink_smem.c +4 -8
@@ -89,15 +89,11 @@ static void glink_smem_rx_peak(struct qcom_glink_pipe *np, tail -= pipe->native.length; len =min_t (size_t, count, pipe->native.length - tail); -if (len) { -__ioread32_copy (data, pipe->fifo + tail, - len /sizeof (u32)); - } +if (len) +memcpy_fromio (data, pipe->fifo + tail, len); -if (len != count) { -__ioread32_copy (data + len, pipe->fifo, - (count - len) /sizeof (u32)); - } +if (len != count) +memcpy_fromio (data + len, pipe->fifo, (count - len)); } static void glink_smem_rx_advance(struct qcom_glink_pipe *np,
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 74/209 RDMA/hns: Submit bad wr when post send wr exception
In reply to Sasha LevinFrom: Lijun Ou <[email protected]>
[ Upstream commit c80e066100b5fed722c8da67c1bd2312e7bcf129 ]
When user issues a RDMA read and enables sq inline, it needs to report a bad wr to user.
--- drivers/infiniband/hw/hns/hns_roce_hw_v2.c | 1 + 1 file changed, 1 insertion(+)
drivers/infiniband/hw/hns/hns_roce_hw_v2.c +1 -0
@@ -121,6 +121,7 @@ static int set_rwqe_data_seg(struct ib_qp *ibqp, const struct ib_send_wr *wr, }if (wr->opcode ==IB_WR_RDMA_READ ) { + *bad_wr = wr;dev_err (hr_dev->dev,"Not support inline data!\n" );return -EINVAL ; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 73/209 RDMA/hns: Bugfix for reserved qp number
In reply to Sasha LevinFrom: Lijun Ou <[email protected]>
[ Upstream commit 06ef0ee4b569101f3a07ce08335dbf29fd1404ef ]
It needs to include two special qps for every port. The hip08 have four ports and the all reserved qp numbers are eight.
--- drivers/infiniband/hw/hns/hns_roce_device.h | 1 + drivers/infiniband/hw/hns/hns_roce_hw_v2.c | 1 + drivers/infiniband/hw/hns/hns_roce_hw_v2.h | 1 + drivers/infiniband/hw/hns/hns_roce_qp.c | 10 ++++++++-- 4 files changed, 11 insertions(+), 2 deletions(-)
drivers/infiniband/hw/hns/hns_roce_device.h +1 -0
@@ -666,6 +666,7 @@ struct hns_roce_caps {u32 max_sq_inline;/* 32 */ u32 max_rq_sg;/* 2 */ int num_qps;/* 256k */ +int reserved_qps;u32 max_wqes;/* 16k */ u32 max_sq_desc_sz;/* 64 */ u32 max_rq_desc_sz;/* 64 */
drivers/infiniband/hw/hns/hns_roce_hw_v2.c +1 -0
@@ -1222,6 +1222,7 @@ static int hns_roce_v2_profile(struct hns_roce_dev *hr_dev) caps->reserved_mrws =1 ; caps->reserved_uars =0 ; caps->reserved_cqs =0 ; + caps->reserved_qps =HNS_ROCE_V2_RSV_QPS ; caps->qpc_ba_pg_sz =0 ; caps->qpc_buf_pg_sz =0 ;
drivers/infiniband/hw/hns/hns_roce_hw_v2.h +1 -0
@@ -78,6 +78,7 @@#define HNS_ROCE_INVALID_LKEY 0x100#define HNS_ROCE_CMQ_TX_TIMEOUT 30000#define HNS_ROCE_V2_UC_RC_SGE_NUM_IN_WQE 2 +#define HNS_ROCE_V2_RSV_QPS 8#define HNS_ROCE_CONTEXT_HOP_NUM 1#define HNS_ROCE_MTT_HOP_NUM 1
drivers/infiniband/hw/hns/hns_roce_qp.c +8 -2
@@ -1106,14 +1106,20 @@ int hns_roce_init_qp_table(struct hns_roce_dev *hr_dev) {struct hns_roce_qp_table *qp_table = &hr_dev->qp_table;int reserved_from_top =0 ; +int reserved_from_bot;int ret;spin_lock_init (&qp_table->lock);INIT_RADIX_TREE (&hr_dev->qp_table_tree,GFP_ATOMIC ); -/* A port include two SQP, six port total 12 */ +/* In hw v1, a port include two SQP, six ports total 12 */ +if (hr_dev->caps.max_sq_sg <=2 ) + reserved_from_bot =SQP_NUM ; +else + reserved_from_bot = hr_dev->caps.reserved_qps; + ret =hns_roce_bitmap_init (&qp_table->bitmap, hr_dev->caps.num_qps, - hr_dev->caps.num_qps -1 ,SQP_NUM , + hr_dev->caps.num_qps -1 , reserved_from_bot, reserved_from_top);if (ret) { dev_err(hr_dev->dev, "qp bitmap init failed!error=%d\n",
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 71/209 IB/mthca: Fix error return code in __mthca_init_one()
In reply to Sasha LevinFrom: Wei Yongjun <[email protected]>
[ Upstream commit 39f2495618c5e980d2873ea3f2d1877dd253e07a ]
Fix to return a negative error code from the mthca_cmd_init() error handling case instead of 0, as done elsewhere in this function.
--- drivers/infiniband/hw/mthca/mthca_main.c | 3 ++- 1 file changed, 2 insertions(+), 1 deletion(-)
drivers/infiniband/hw/mthca/mthca_main.c +2 -1
@@ -986,7 +986,8 @@ static int __mthca_init_one(struct pci_dev *pdev, int hca_type) goto err_free_dev; } -if (mthca_cmd_init (mdev)) { + err =mthca_cmd_init (mdev); +if (err) {mthca_err (mdev,"Failed to init command interface, aborting.\n" ); goto err_free_dev; }
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 69/209 i40e: Use proper enum in i40e_ndo_set_vf_link_state
In reply to Sasha LevinFrom: Nathan Chancellor <[email protected]>
[ Upstream commit 43ade6ad18416b8fd5bb3c9e9789faa666527eec ]
Clang warns when one enumerated type is converted implicitly to another.
drivers/net/ethernet/intel/i40e/i40e_virtchnl_pf.c:4214:42: warning:
implicit conversion from enumeration type 'enum i40e_aq_link_speed' to different enumeration type 'enum virtchnl_link_speed'
[-Wenum-conversion]
pfe.event_data.link_event.link_speed = I40E_LINK_SPEED_40GB;
~ ^~~~~~~~~~~~~~~~~~~~1 warning generated.
Use the proper enum from virtchnl_link_speed, which has the same value as I40E_LINK_SPEED_40GB, VIRTCHNL_LINK_SPEED_40GB. This appears to be missed by commit ff3f4cc267f6 ("virtchnl: finish conversion to virtchnl interface").
--- drivers/net/ethernet/intel/i40e/i40e_virtchnl_pf.c | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
drivers/net/ethernet/intel/i40e/i40e_virtchnl_pf.c +1 -1
@@ -4201,7 +4201,7 @@ int i40e_ndo_set_vf_link_state(struct net_device *netdev, int vf_id, int link) vf->link_forced = true; vf->link_up = true; pfe.event_data.link_event.link_status = true; - pfe.event_data.link_event.link_speed =I40E_LINK_SPEED_40GB ; + pfe.event_data.link_event.link_speed =VIRTCHNL_LINK_SPEED_40GB ;break ;case IFLA_VF_LINK_STATE_DISABLE : vf->link_forced = true;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 64/209 clocksource/drivers/sh_cmt: Fixup for 64-bit machines
In reply to Sasha LevinFrom: Sergei Shtylyov <[email protected]>
[ Upstream commit 22627c6f3ed3d9d0df13eec3c831b08f8186c38e ]
When trying to use CMT for clockevents on R-Car gen3 SoCs, I noticed that 'max_delta_ns' for the broadcast timer (CMT) was shown as 1000 in /proc/timer_list. It turned out that when calculating it, the driver did 1 << 32 (causing what I think was undefined behavior) resulting in a zero delta, later clamped to 1000 by cev_delta2ns(). The root cause turned out to be that the driver abused *unsigned long* for the CMT register values (which are 16/32-bit), so that the calculation of 'ch->max_match_value' in sh_cmt_setup_channel() used the wrong branch. Using more proper 'u32' instead fixed 'max_delta_ns' and even fixed the switching an active clocksource to CMT (which caused the system to turn non-interactive before).
--- drivers/clocksource/sh_cmt.c | 72 +++++++++++++++++------------------- 1 file changed, 33 insertions(+), 39 deletions(-)
drivers/clocksource/sh_cmt.c +33 -39
@@ -78,18 +78,17 @@ struct sh_cmt_info {unsigned int channels_mask;unsigned long width;/* 16 or 32 bit version of hardware block */ -unsigned long overflow_bit; -unsigned long clear_bits; +u32 overflow_bit; +u32 clear_bits;/* callbacks for CMSTR and CMCSR access */ -unsigned long (*read_control)(void __iomem *base,unsigned long offs); +u32 (*read_control)(void __iomem *base,unsigned long offs);void (*write_control)(void __iomem *base,unsigned long offs, -unsigned long value); +u32 value);/* callbacks for CMCNT and CMCOR access */ -unsigned long (*read_count)(void __iomem *base,unsigned long offs); -void (*write_count)(void __iomem *base,unsigned long offs, -unsigned long value); +u32 (*read_count)(void __iomem *base,unsigned long offs); +void (*write_count)(void __iomem *base,unsigned long offs,u32 value); };struct sh_cmt_channel {
@@ -103,9 +102,9 @@ struct sh_cmt_channel {unsigned int timer_bit;unsigned long flags; -unsigned long match_value; -unsigned long next_match_value; -unsigned long max_match_value; +u32 match_value; +u32 next_match_value; +u32 max_match_value;raw_spinlock_t lock;struct clock_event_device ced;struct clocksource cs;
@@ -160,24 +159,22 @@ struct sh_cmt_device {#define SH_CMT32_CMCSR_CKS_RCLK1 (7 << 0)#define SH_CMT32_CMCSR_CKS_MASK (7 << 0) -static unsigned long sh_cmt_read16 (void __iomem *base,unsigned long offs) +static u32 sh_cmt_read16 (void __iomem *base,unsigned long offs) {return ioread16 (base + (offs <<1 )); } -static unsigned long sh_cmt_read32 (void __iomem *base,unsigned long offs) +static u32 sh_cmt_read32 (void __iomem *base,unsigned long offs) {return ioread32 (base + (offs <<2 )); } -static void sh_cmt_write16 (void __iomem *base,unsigned long offs, -unsigned long value) +static void sh_cmt_write16 (void __iomem *base,unsigned long offs,u32 value) {iowrite16 (value, base + (offs <<1 )); } -static void sh_cmt_write32 (void __iomem *base,unsigned long offs, -unsigned long value) +static void sh_cmt_write32 (void __iomem *base,unsigned long offs,u32 value) {iowrite32 (value, base + (offs <<2 )); }
@@ -242,7 +239,7 @@ static const struct sh_cmt_info sh_cmt_info[] = {#define CMCNT 1/* channel register */ #define CMCOR 2/* channel register */ -static inline unsigned long sh_cmt_read_cmstr (struct sh_cmt_channel *ch) +static inline u32 sh_cmt_read_cmstr (struct sh_cmt_channel *ch) {if (ch->iostart)return ch->cmt->info->read_control (ch->iostart,0 );
@@ -250,8 +247,7 @@ static inline unsigned long sh_cmt_read_cmstr(struct sh_cmt_channel *ch)return ch->cmt->info->read_control (ch->cmt->mapbase,0 ); } -static inline void sh_cmt_write_cmstr (struct sh_cmt_channel *ch, -unsigned long value) +static inline void sh_cmt_write_cmstr (struct sh_cmt_channel *ch,u32 value) {if (ch->iostart) ch->cmt->info->write_control (ch->iostart,0 , value);
@@ -259,39 +255,35 @@ static inline void sh_cmt_write_cmstr(struct sh_cmt_channel *ch, ch->cmt->info->write_control (ch->cmt->mapbase,0 , value); } -static inline unsigned long sh_cmt_read_cmcsr (struct sh_cmt_channel *ch) +static inline u32 sh_cmt_read_cmcsr (struct sh_cmt_channel *ch) {return ch->cmt->info->read_control (ch->ioctrl,CMCSR ); } -static inline void sh_cmt_write_cmcsr (struct sh_cmt_channel *ch, -unsigned long value) +static inline void sh_cmt_write_cmcsr (struct sh_cmt_channel *ch,u32 value) { ch->cmt->info->write_control (ch->ioctrl,CMCSR , value); } -static inline unsigned long sh_cmt_read_cmcnt (struct sh_cmt_channel *ch) +static inline u32 sh_cmt_read_cmcnt (struct sh_cmt_channel *ch) {return ch->cmt->info->read_count (ch->ioctrl,CMCNT ); } -static inline void sh_cmt_write_cmcnt (struct sh_cmt_channel *ch, -unsigned long value) +static inline void sh_cmt_write_cmcnt (struct sh_cmt_channel *ch,u32 value) { ch->cmt->info->write_count (ch->ioctrl,CMCNT , value); } -static inline void sh_cmt_write_cmcor (struct sh_cmt_channel *ch, -unsigned long value) +static inline void sh_cmt_write_cmcor (struct sh_cmt_channel *ch,u32 value) { ch->cmt->info->write_count (ch->ioctrl,CMCOR , value); } -static unsigned long sh_cmt_get_counter (struct sh_cmt_channel *ch, -int *has_wrapped) +static u32 sh_cmt_get_counter (struct sh_cmt_channel *ch,u32 *has_wrapped) { -unsigned long v1, v2, v3; -int o1, o2; +u32 v1, v2, v3; +u32 o1, o2; o1 =sh_cmt_read_cmcsr (ch) & ch->cmt->info->overflow_bit;
@@ -311,7 +303,8 @@ static unsigned long sh_cmt_get_counter(struct sh_cmt_channel *ch,static void sh_cmt_start_stop_ch (struct sh_cmt_channel *ch,int start) { -unsigned long flags, value; +unsigned long flags; +u32 value;/* start stop register shared by multiple timer channels */ raw_spin_lock_irqsave (&ch->cmt->lock, flags);
@@ -418,11 +411,11 @@ static void sh_cmt_disable(struct sh_cmt_channel *ch)static void sh_cmt_clock_event_program_verify (struct sh_cmt_channel *ch,int absolute) { -unsigned long new_match; -unsigned long value = ch->next_match_value; -unsigned long delay =0 ; -unsigned long now =0 ; -int has_wrapped; +u32 value = ch->next_match_value; +u32 new_match; +u32 delay =0 ; +u32 now =0 ; +u32 has_wrapped; now =sh_cmt_get_counter (ch, &has_wrapped); ch->flags |=FLAG_REPROGRAM ;/* force reprogram */
@@ -619,9 +612,10 @@ static struct sh_cmt_channel *cs_to_sh_cmt(struct clocksource *cs)static u64 sh_cmt_clocksource_read (struct clocksource *cs) {struct sh_cmt_channel *ch =cs_to_sh_cmt (cs); -unsigned long flags, raw; +unsigned long flags;unsigned long value; -int has_wrapped; +u32 has_wrapped; +u32 raw;raw_spin_lock_irqsave (&ch->lock, flags); value = ch->total_cycles;
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 63/209 tools: PCI: Fix compilation warnings
In reply to Sasha LevinFrom: Gustavo Pimentel <[email protected]>
[ Upstream commit fef31ecaaf2c5c54db85b35e893bf8abec96b93f ]
Current compilation produces the following warnings:
tools/pci/pcitest.c: In function 'run_test':tools/pci/pcitest.c:56:9: warning: unused variable 'time' [-Wunused-variable]
double time;
^~~~
tools/pci/pcitest.c:55:25: warning: unused variable 'end'
[-Wunused-variable]
struct timespec start, end;
^~~
tools/pci/pcitest.c:55:18: warning: unused variable 'start'
[-Wunused-variable]
struct timespec start, end;
^~~~~tools/pci/pcitest.c:146:1: warning: control reaches end of non-void function [-Wreturn-type]
}
^
Fix them:
- remove unused variables
- change function return from int to void, since it's not used
--- tools/pci/pcitest.c | 7 ++----- 1 file changed, 2 insertions(+), 5 deletions(-)
tools/pci/pcitest.c +2 -5
@@ -23,7 +23,6 @@#include <stdio.h> #include <stdlib.h> #include <sys/ioctl.h> -#include <time.h> #include <unistd.h> #include <linux/pcitest.h>
@@ -48,17 +47,15 @@ struct pci_test {unsigned long size; }; -static int run_test (struct pci_test *test) +static void run_test (struct pci_test *test) {long ret;int fd; -struct timespec start, end; -double time; fd =open (test->device,O_RDWR );if (fd <0 ) {perror ("can't open PCI Endpoint Test device" ); -return fd; +return ; }if (test->barnum >=0 && test->barnum <=5 ) {
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 58/209 ARM: dts: at91: sama5d4_xplained: fix addressable nand flash size
In reply to Sasha LevinFrom: Tudor Ambarus <[email protected]>
[ Upstream commit df90fc64367ffdb6f1b5c0f0c4940d44832b0174 ]
sama5d4_xplained comes with a 4Gb NAND flash. Increase the rootfs size to match this limit.
--- arch/arm/boot/dts/at91-sama5d4_xplained.dts | 2 +- 1 file changed, 1 insertion(+), 1 deletion(-)
arch/arm/boot/dts/at91-sama5d4_xplained.dts +1 -1
@@ -252,7 +252,7 @@ rootfs@800000 { label = "rootfs"; - reg = <0x800000 0x0f800000>; + reg = <0x800000 0x1f800000>; }; }; };
Signature · 1 line
2.20.1
Sasha Levin
maintainerPATCH 60/209 ARM: dts: at91: sama5d2_ptc_ek: fix bootloader env offsets
In reply to Sasha LevinFrom: Tudor Ambarus <[email protected]>
[ Upstream commit f602b4871c5f7ac01d37d8b285ca947ba7613065 ]
The offsets for the bootloader environment and its redundant partition were inverted. Fix the addresses to match our nand flash map available at:
http://www.at91.com/linux4sam/pub/Linux4SAM/SambaSubsections//demo_nandflash_map_lnx4sam5x.png
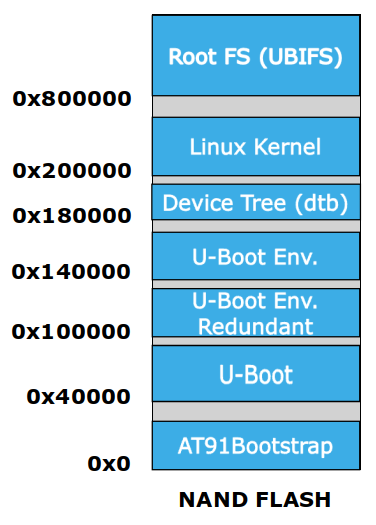
--- arch/arm/boot/dts/at91-sama5d2_ptc_ek.dts | 8 ++++---- 1 file changed, 4 insertions(+), 4 deletions(-)
arch/arm/boot/dts/at91-sama5d2_ptc_ek.dts +4 -4
@@ -92,13 +92,13 @@ reg = <0x40000 0xc0000>; }; - bootloaderenv@0x100000 { - label = "bootloader env"; + bootloaderenvred@0x100000 { + label = "bootloader env redundant"; reg = <0x100000 0x40000>; }; - bootloaderenvred@0x140000 { - label = "bootloader env redundant"; + bootloaderenv@0x140000 { + label = "bootloader env"; reg = <0x140000 0x40000>; };
Signature · 1 line
2.20.1